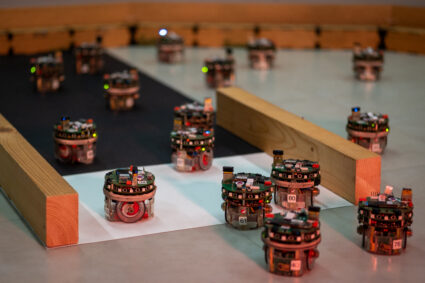
Reinforcement learning lets robots learn behaviors on their own, through trial and error, usually inside a computer simulation. Moving what they learn onto physical robots is another matter. Simulated and real robots never behave quite the same way, a mismatch known as the “reality gap,” and reinforcement learning has long been particularly sensitive to it. Researchers at IRIDIA, the artificial intelligence laboratory of the Université libre de Bruxelles (ULB), have shown how to get around it for robot swarms: swarms trained with their method in simulation keep performing reliably once they are moved onto real robots.
Teaching a swarm of robots to search for survivors after an earthquake, or to explore a hostile site, entirely inside a computer before risking a real machine sounds like the sensible way to do it. The catch is the reality gap. Friction, sensor noise and mechanical imprecision rarely behave the way they do in a simulation, and skills learned there tend to fall apart when a robot meets the real world.
Ilyes Gharbi, Mauro Birattari and colleagues at IRIDIA (Brussels School of Engineering, ULB) report their results in Science Robotics.
Reinforcement learning has become one of the most powerful tools in robotics for producing complex behaviors automatically, and it is behind some of the most striking recent advances in legged locomotion and robotic manipulation. Swarm robotics followed a different path. Its own tradition of modular design methods assembles robot behaviors from predefined building blocks. These methods transfer reliably to real robots, but they rely on slow, costly search procedures. The two lines of research had rarely been compared on solid experimental ground.
The researchers’ idea was to give the robots less freedom in exchange for more reliability. Instead of letting the learning algorithm set each wheel’s speed directly, they had it choose, moment by moment, among a handful of tried-and-tested behaviors: moving toward a light, aggregating with peers, exploring. This restriction keeps the robots from learning to exploit quirks of the simulator that don’t exist in reality. What is left to learn is the part that matters: when to switch from one behavior to another so that the group works together.
“For years we have argued that the reality gap is, at its core, a problem of overfitting: a design method that is too flexible learns the simulator rather than the task,” says Mauro Birattari, who led the research. “Reinforcement learning is very good at finding whatever works in simulation, including tricks that only work there. By limiting what the robots can learn, we leave the algorithm only the decisions that still make sense on a real robot.”
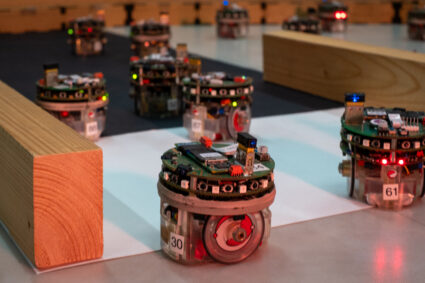
The team tested the approach on a swarm of 20 e-puck robots across five different collective missions, with 250 experiments on the physical robots in total. Swarms trained this way transferred to reality reliably. They substantially outperformed a state-of-the-art method in which the algorithm controls the robots’ motors directly, and which struggled once it left the simulator. The researchers also found that simpler, more constrained policies transferred better than larger, more flexible ones. That goes against a widespread intuition in artificial intelligence, that bigger and more flexible models are generally better.
“What excites me is that this makes reinforcement learning a practical tool for swarm robotics,” says Ilyes Gharbi, first author of the study. “Designing collective behaviors by hand takes experts a lot of time. With this approach, a swarm can be trained in simulation for a new mission and deployed on real robots with confidence that it will behave as expected. The next step is to test it on larger swarms, other robot platforms and less controlled environments.”
The study brings together two research traditions that had developed largely separately: the efficiency of reinforcement learning and the reliability of swarm robotics ’modular methods. Both will be needed before groups of autonomous robots can be trusted with tasks such as search and rescue, environmental monitoring, or exploring places too dangerous for people.
This research was partially supported by the Belgian Fonds de la Recherche Scientifique—FNRS through the PDR project “Reinforcement Learning for Robot Swarms.”
Publication
I. Gharbi, M. Kegeleirs, G. Legarda Herranz, J. Szpirer, K. Hasselmann, M. Birattari, “Structural bias enables reliable sim-to-real transfer in reinforcement learning for robot swarms,” Science Robotics (2026).