Page 1 of 4
1 2 3 4

#AAMAS2026 blue sky award winner: Foundation world models for agents in changing environments

Florent Delgrange won the Best Blue Sky Paper Award at AAMAS 2026 for his work Foundation World Models for Agents that Learn, Verify, and Adapt Reliably Beyond Static Environments. We caught up with him to find out more about his vision for agent learning.

What is the topic of your Blue Sky Ideas paper and why is it an interesting area for study?

My Blue Sky Ideas paper asks a simple but difficult question: how can an autonomous agent keep learning as its world changes without quietly losing the guarantees that made its behavior trustworthy?

Reinforcement learning and formal methods address complementary parts of this problem. Reinforcement learning allows an agent to learn by trial and error and can scale to environments for which we could never write down every rule. However, the agent is usually asked to maximize a reward. A poorly specified reward can be exploited, and a high reward does not by itself tell us that a safety or coordination requirement has been satisfied. Reactive synthesis starts from the other end: given a model of the environment and a logical description of the intended behavior, it can construct a policy that is correct by design. The difficulty is that it normally needs an explicit, fixed model, which is precisely what an agent lacks in an open and changing world.

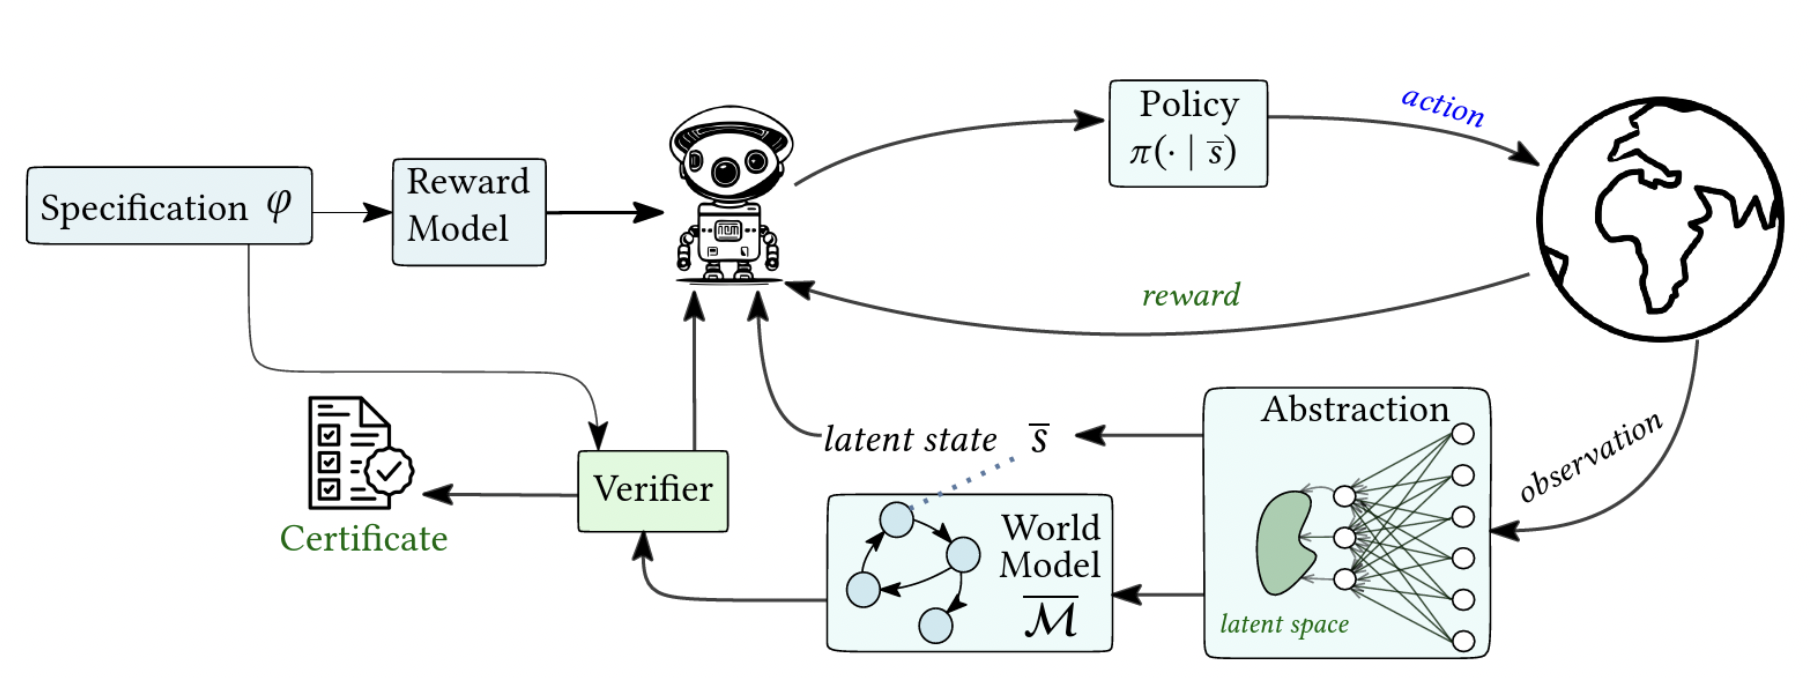
The paper proposes a research agenda that brings these traditions into one loop. A foundation world model would be learned from experience, but structured so that a verifier can reason about it. As the agent learns a policy, it would update its model, measure the reliability of its abstraction, and check whether the policy still satisfies its specification. The verifier’s feedback could reject an unsafe update, request data from an uncertain region, or trigger a revision of the model.

This matters because real environments do not politely remain as they were during training. Goals evolve, conditions change, and, in a multi-agent system, every adapting agent changes the environment perceived by the others. Reliability therefore cannot be a certificate obtained once at deployment. It has to be maintained as the agent continues to learn.

What is your vision for foundation world models?

To me, foundation refers first to reuse, not simply to size. I do not envision a larger video predictor trained on more trajectories. I envision a persistent and structured model that an agent can carry across tasks, policies, and changing populations of agents.

One way to think about it is as a map that records more than roads. It should also tell the agent which areas have been surveyed, which conclusions depend on those areas, and when a change in the world has made an old route unreliable. A useful foundation world model should do the same for decision-making: predict what may happen, expose the structure needed for reasoning, and quantify when those predictions are trustworthy enough to support a guarantee.

I’d want such a model to have three key properties. First, it should be calibrated: every learned abstraction should come with a measure of its error or coverage, so that the agent knows where formal conclusions remain valid. Second, it should be compositional: verified local dynamics, behaviors, and certificates should be reusable when a new task is assembled. Third, it should be semantically queryable: a formal requirement or high-level instruction should help the agent derive a suitable reward model, task-specific abstraction, or policy prior with little additional experience.

The durable idea is that the world model becomes a common substrate for learning, planning, and verification. It should help an agent act, but also identify the limits of its competence, gather evidence where those limits matter, and explain why a particular behavior can or cannot currently be certified.

How does this vision differ from current models?

Most current model-based approaches focus on learning for a particular task, environment, policy, or training distribution. Their main model learning objective is predictive accuracy: reconstruct an observation, forecast the next (latent) state, or generate imagined trajectories for planning. Those are important capabilities, but average predictive metric is not the same as fitness for a particular guarantee.

Consider a model for a scenario involving an agent interacting in a warehouse, where the world model predicts almost every transition correctly but misses a rare, dangerous interaction with a forklift. Its average error may be excellent while that transition is exactly the one that determines whether a collision-avoidance claim is valid. The reverse is also possible: a compact model may ignore colors and textures yet preserve everything needed to reason about routes and collisions. For verification, the relevant question is therefore not only “How accurate is the model?” but “Which conclusions does this accuracy justify, for this policy and this requirement?”

Foundation world models would make that connection an explicit design objective. Their abstractions would carry reliability information tied to the behavior being analyzed, and this information would be revised online as the data distribution changes. Previously verified components could be reused and composed, while specifications expressed in logic or language could guide which representation and policy the agent needs for a new task.

The main difference is therefore a change in role. Current models are primarily prediction tools. The model I envisage is a persistent, analyzable basis for learning, adaptation, and formal reasoning, with language models providing a complementary semantic interface. They could translate high-level instructions into candidate specifications or propose structured model updates, while the world model grounds these proposals in experience and the verifier checks their validity. Foundation world models may benefit from scale through broader task and environment coverage, but scale alone does not provide the structure or certificates required for reliability.

Could you give an example of how such a model might work?

Consider a delivery robot in a busy warehouse. Its task could be stated as: “eventually deliver the package while always avoiding collisions.” Instead of manually combining many bonuses and penalties, the system would translate that requirement into a reward model. Learning and verification would then start from the same description of the intended behavior.

As the robot receives observations, it would learn a compact representation of the warehouse and a policy that acts on that representation. A verifier would ask two related questions. Does the policy satisfy the delivery and collision-avoidance requirement in the learned world model? And is the learned abstraction accurate enough, along the routes that matter, for that conclusion to be trusted? A certificate is meaningful only when both answers are supported.

Now suppose a new forklift begins using a shortcut that was rarely visited during training, cluttering the way. Rather than treating an old prediction as a guarantee, the model should lower its confidence in that region. The verifier would detect this, withdraw the affected certificate, reject a risky policy update, direct exploration toward the shortcut, and reinstate a guarantee only after the world model has been recalibrated.

The paper also considers a more ambitious test-time loop. A language model could propose one or more small formal program describing the new dynamics. A model checker would test them, learn to compose with them, and return a counterexample or structural inconsistency when they are wrong. The language model could revise its hypothesis, the robot could collect targeted experience, and the cycle would repeat. In this division of labor, the language model proposes and the formal verifier checks.

We already have pieces of the loop, including formal reward translations, verifiable abstractions, safe policy-improvement methods, and program generation. Building an efficient end-to-end agent that keeps all of these pieces calibrated while it learns remains the research challenge.

What do you think the impact of such a framework on multi-agent systems could be?

Multi-agent systems make the problem both more urgent and more difficult. Each learning agent is a moving part of every other agent’s environment. Even when the physical world is unchanged, the effective dynamics evolve as agents update their policies, join or leave the system, share information, or pursue new objectives.

A foundation world model could retain reusable descriptions of these interaction patterns, while formal specifications state what must hold for the group. A fleet of warehouse robots, for example, may need to avoid collisions and complete deliveries while respecting shared capacity constraints. The model could connect each local policy to the assumptions on which its certificate depends. If one robot changes its route, the system could identify which assumptions and guarantees are affected, collect new data where needed, and revise only the relevant components rather than relearning and re-verifying the entire fleet.

Composition is the main source of potential leverage. Verified local dynamics or coordination behaviors could serve as building blocks for new teams and tasks, and previous agents could provide useful priors for new participants. This could support faster adaptation while making failures easier to diagnose: the system should report which interaction invalidated a certificate and provide a counterexample, rather than only revealing that the joint reward has fallen.

The central obstacle for multi-agent systems is scalability. The joint state space grows very quickly with the number of agents, and local guarantees do not automatically compose into a global one. We will need principled ways to expose dependencies, preserve soundness under composition, and run verification quickly enough to influence learning online. If we can solve those problems, the field could move from learning coordination strategies and checking them afterwards to learning new strategies while continuously tracking which global properties remain guaranteed.

About Florent
Florent Delgrange is a postdoctoral researcher in computer science at the Artificial Intelligence Lab of Vrije Universiteit Brussel (VUB). His research lies at the intersection of reinforcement learning, world models, and formal verification. He develops methods for agents that can learn and adapt while justifying and certifying the behavior they adopt. He completed a joint PhD at VUB and the University of Antwerp in 2024 on the formal verification of deep reinforcement learning policies. His paper Foundation World Models for Agents that Learn, Verify, and Adapt Reliably Beyond Static Environments received the Best Blue Sky Paper Award at AAMAS 2026.

#RoboCup2026 – humanoid league day 1

Image credit: RoboCup Federation.

RoboCup 2026 kicked off today in Incheon, South Korea, with the league competitions running until 5 July. It’s an exciting time for RoboCup, as there have been some updates to the leagues and competition format. Most prominently, the soccer leagues will have a primary focus on humanoid robots. In a series of daily updates, we’ll be bringing you the latest results, videos, and news from the humanoid soccer league.

This year, the humanoid league is split into three sizes: large division, middle division, and small division. There are 18 teams participating the small division, 16 in the middle, and an impressive 22 competing in the large division.

The first two days of competition are be devoted to the seeding round. Teams play using the Swiss-system of ranking to decide who gets through to the knockout stages.

Livestreams from the different fields of play can be found here.

At the end of the first day of competition, teams in the small and middle divisions have played two games each, with the large division ending the day part way through the second round. Early leaders in the small division, with the full six points from two games are: GeoHBots, CAU Mountain&Sea, and Hamburg Bit-Bots. There are also three teams in the middle division who have claimed the six point haul: B-Human, RoboRoos, and HTWK Robots.

You can watch a short summary of the first day, including some of the robots in action, from KBS News:

This short video from RoboCup gives a flavour of the day’s happenings, which also featured the opening ceremony.

We will be back tomorrow with further updates on competition results, some highlights from the day, and insights into how the event is progressing.

Useful links

Sony AI table tennis robot outplays elite human players

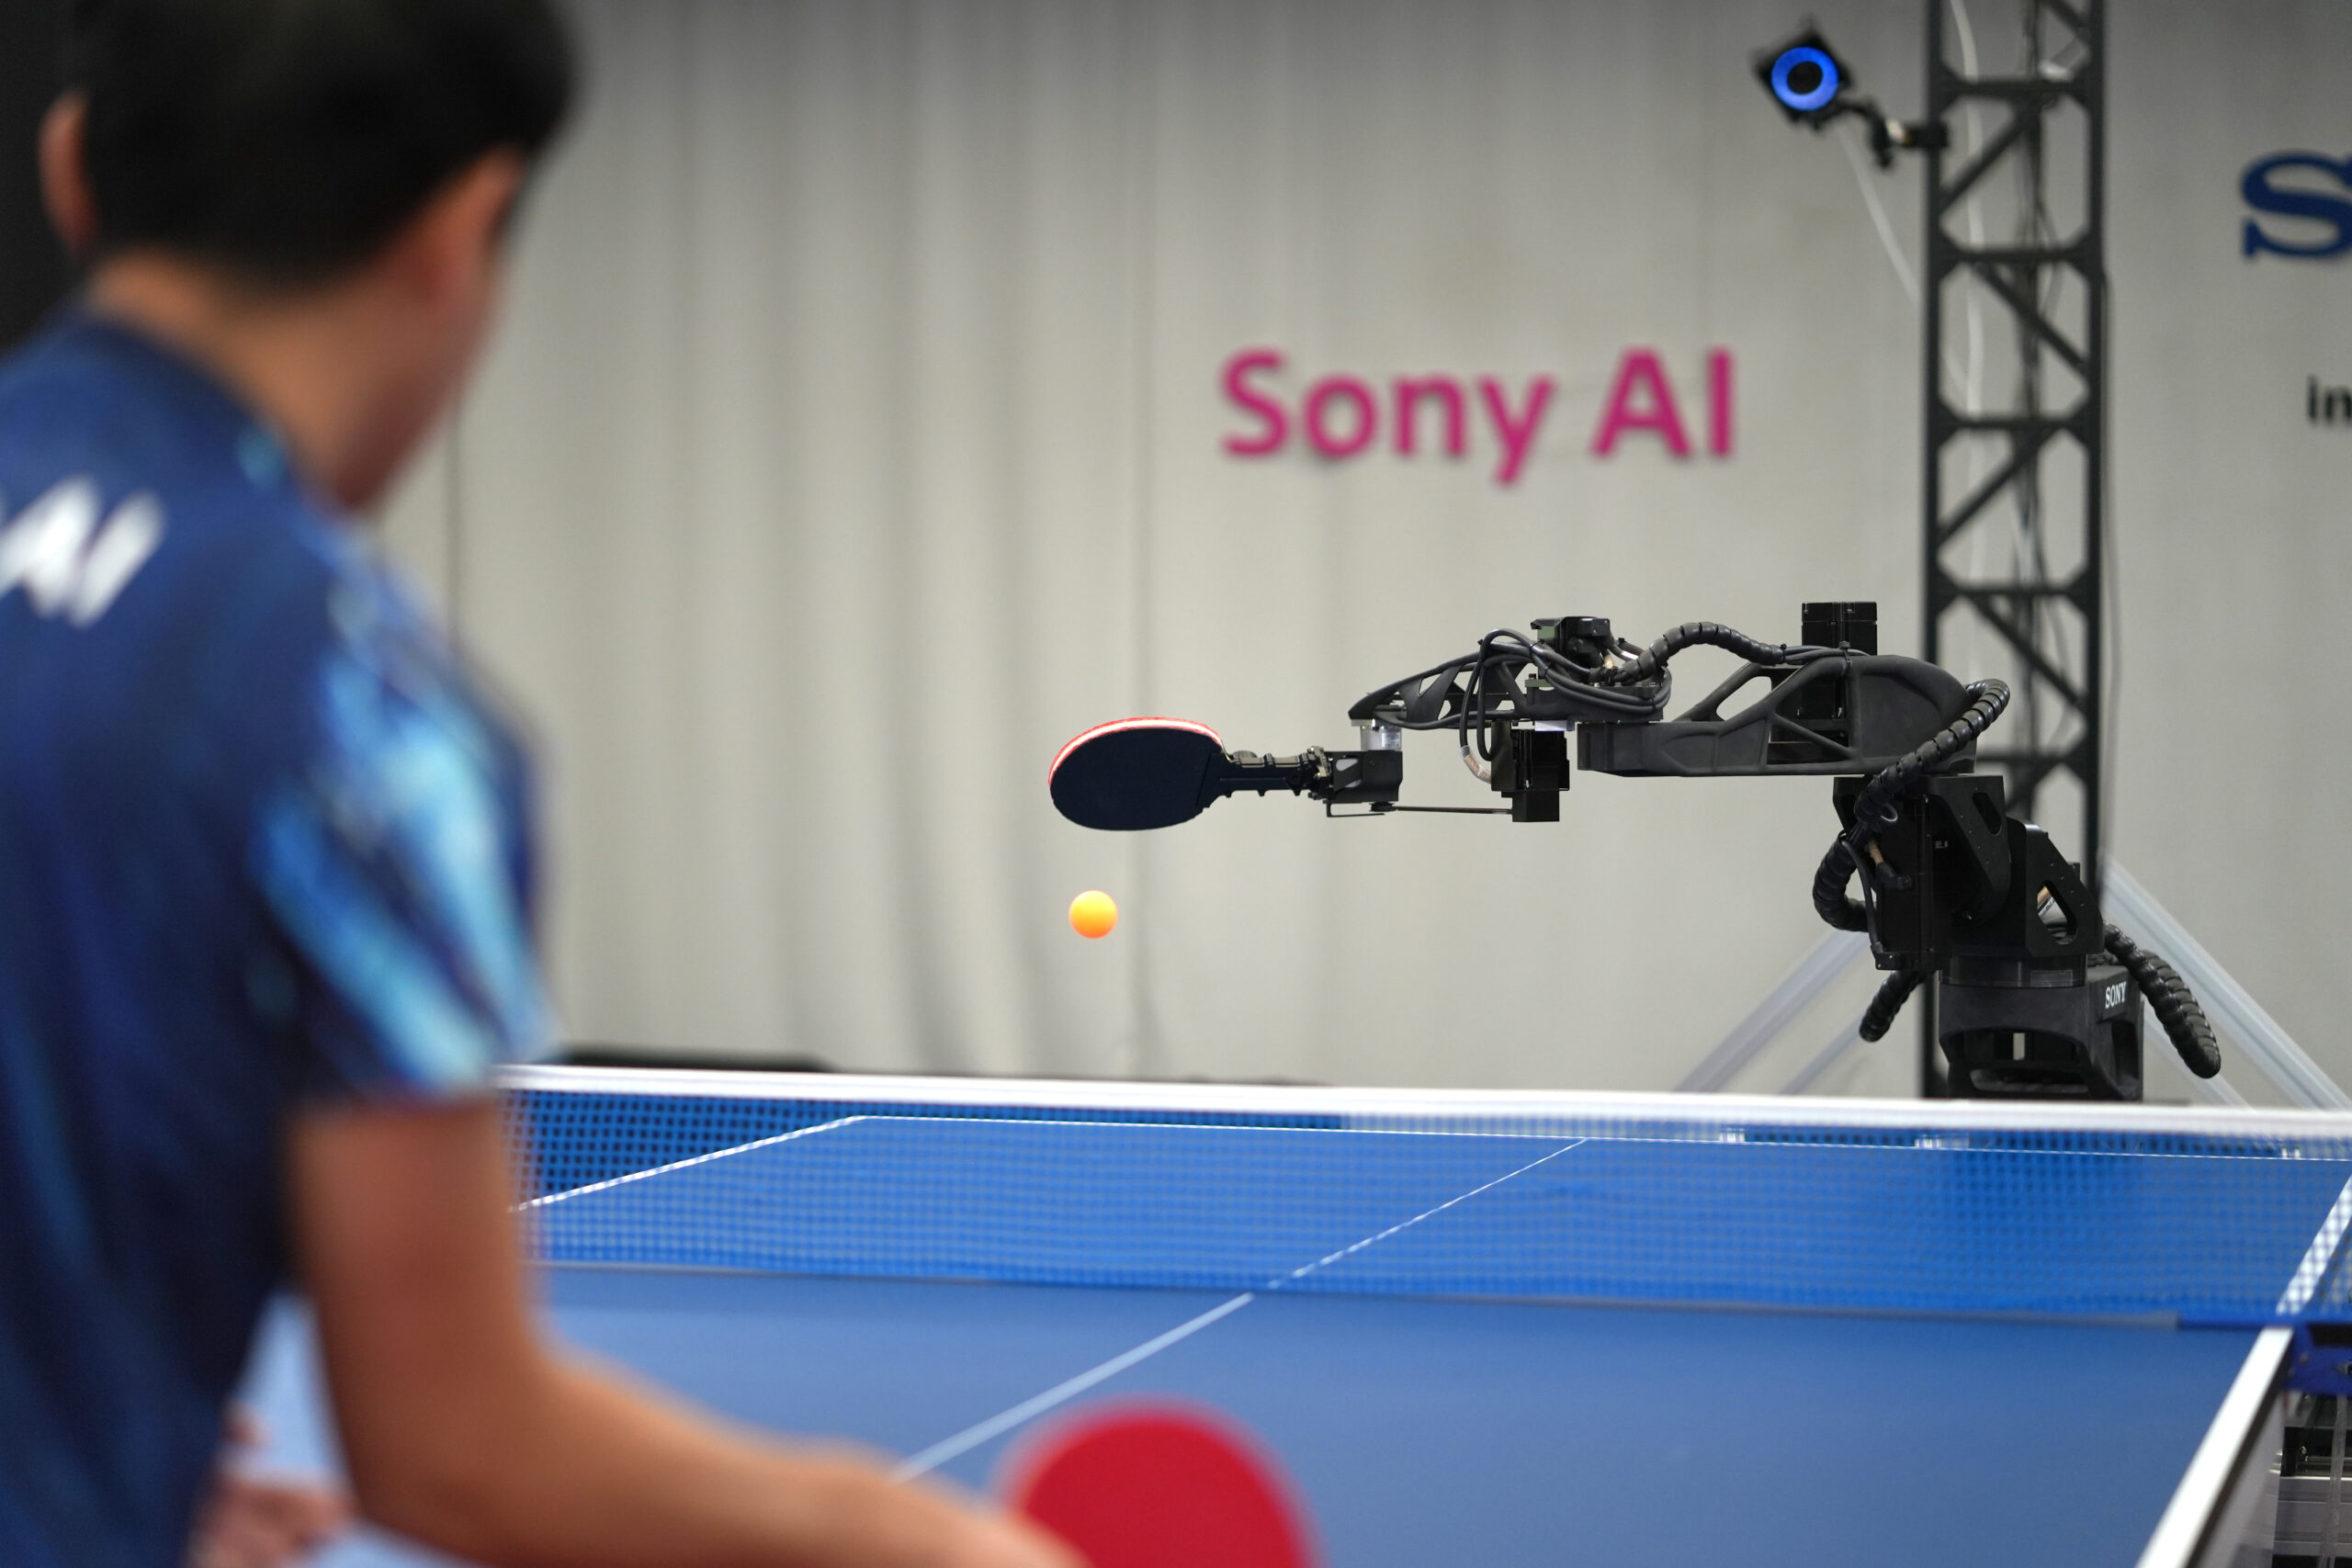
Ace rotates its paddle as it prepares to return the ball back to its human opponent, Yamato Kawamata, during a match in December 2025. Credit: Sony AI.
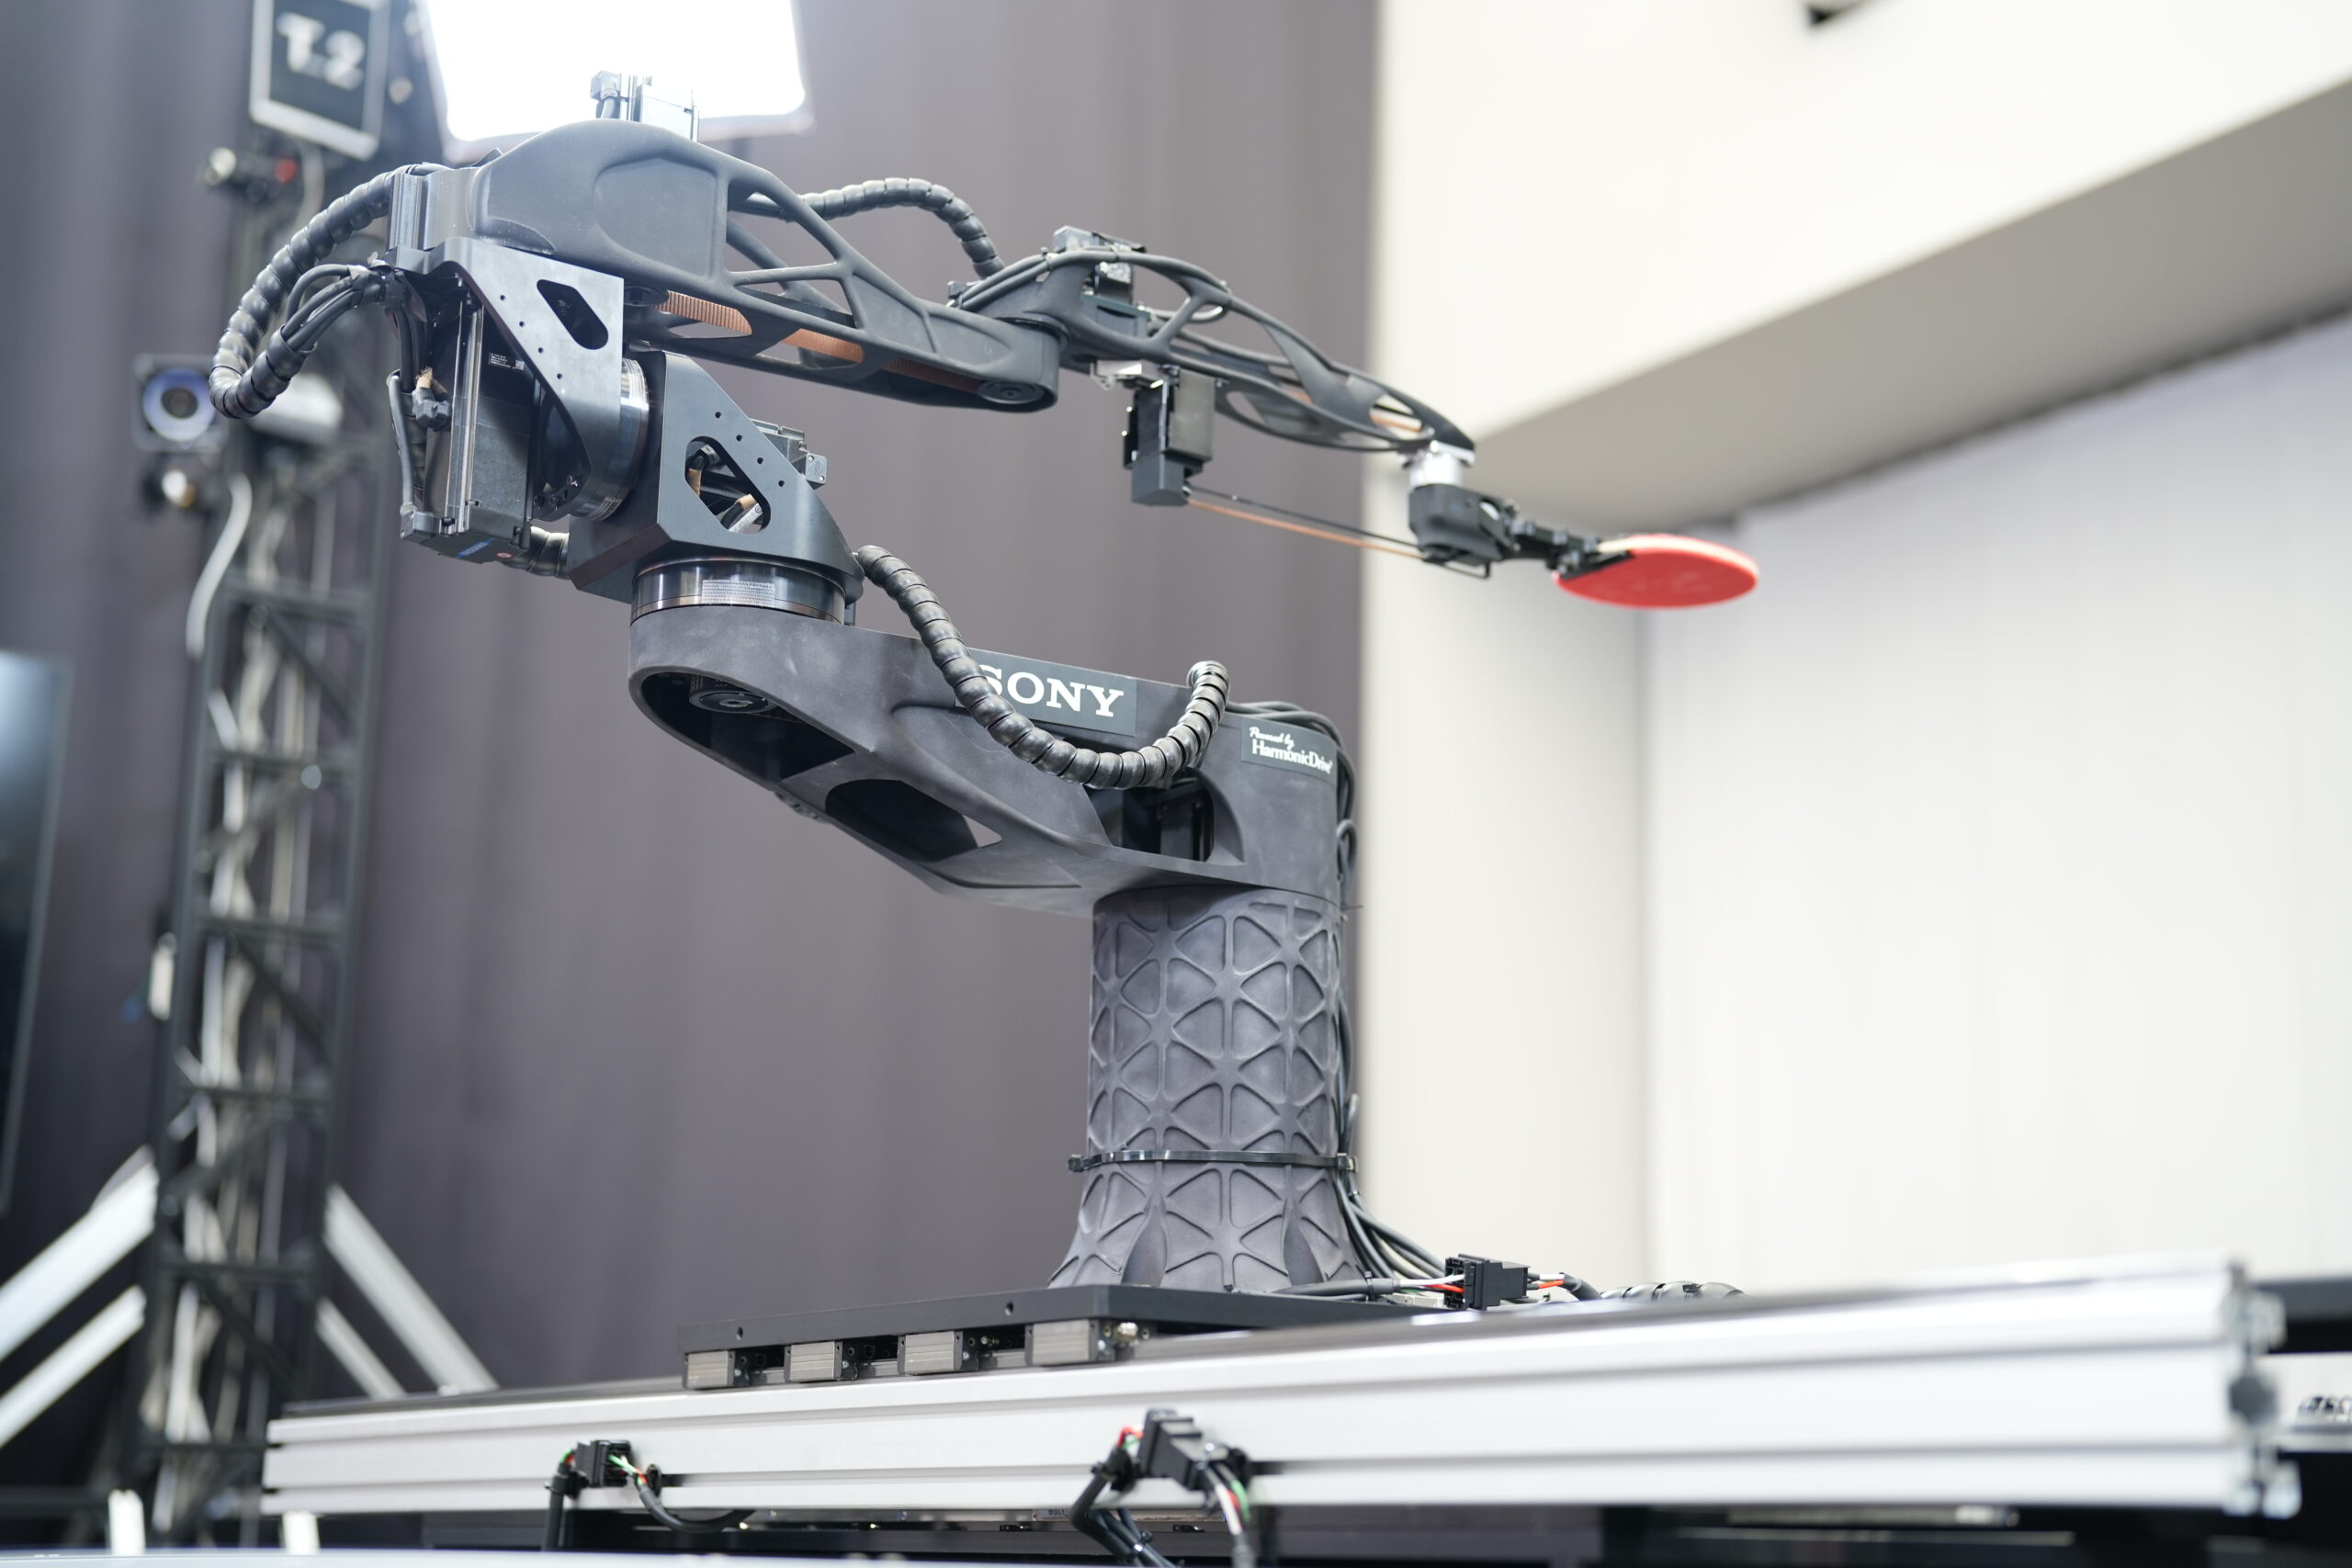
In an article published today in Nature, Sony AI introduce Ace, the first robot to beat elite human players in competitive physical sport.

Although AI systems have shown advanced performance in digital domains and board games (such as complex video games, chess and Go), translating this to physical performance has remained a significant challenge. Such a feat requires perception, planning, and control to work in a high-speed domain on the scale of milliseconds. Table tennis is a demanding and complex real-world test for robotics, requiring rapid decision-making, precise physical execution, and continuous adaptation to an unpredictable opponent. The ball’s high speed, spin, and complex trajectories are central to competitive play.

Director of Sony AI in Zürich, and project lead for Ace, Peter Dürr said “this research has shown that an autonomous robot can, in fact, win at a competitive sport, matching or exceeding the reaction time and decision making of humans in a physical space. Table tennis is a game of enormous complexity that requires split-second decisions as well as speed and power. This research breakthrough highlights the potential of physical AI agents to perform real-time interactive tasks, and represents a significant step toward creating robots with broader applications in fast, precise, and real-time human interactions.”

A complete view of table tennis robot, Ace, including arm and track. Credit: Sony AI.
What new components does Ace incorporate?

Ace combines event-based vision sensors and a control system based on model-free reinforcement learning, as well as state-of-the-art high-speed robot hardware. Ace was designed with three novel components:

  • A high speed perception system composed of nine active pixel sensor cameras to determine the ball’s precise 3D position, combined with three gaze control systems that use event-based vision sensor cameras, pan/tilt mirrors, and telephoto tunable lens to measure the ball’s angular velocity and spin in real time.
  • A novel control system based on model-free reinforcement learning to enable rapid adaptation and decision-making without reliance on pre-programmed models.
  • High-speed robotic hardware capable of executing precise, high-speed control for agile physical interaction.

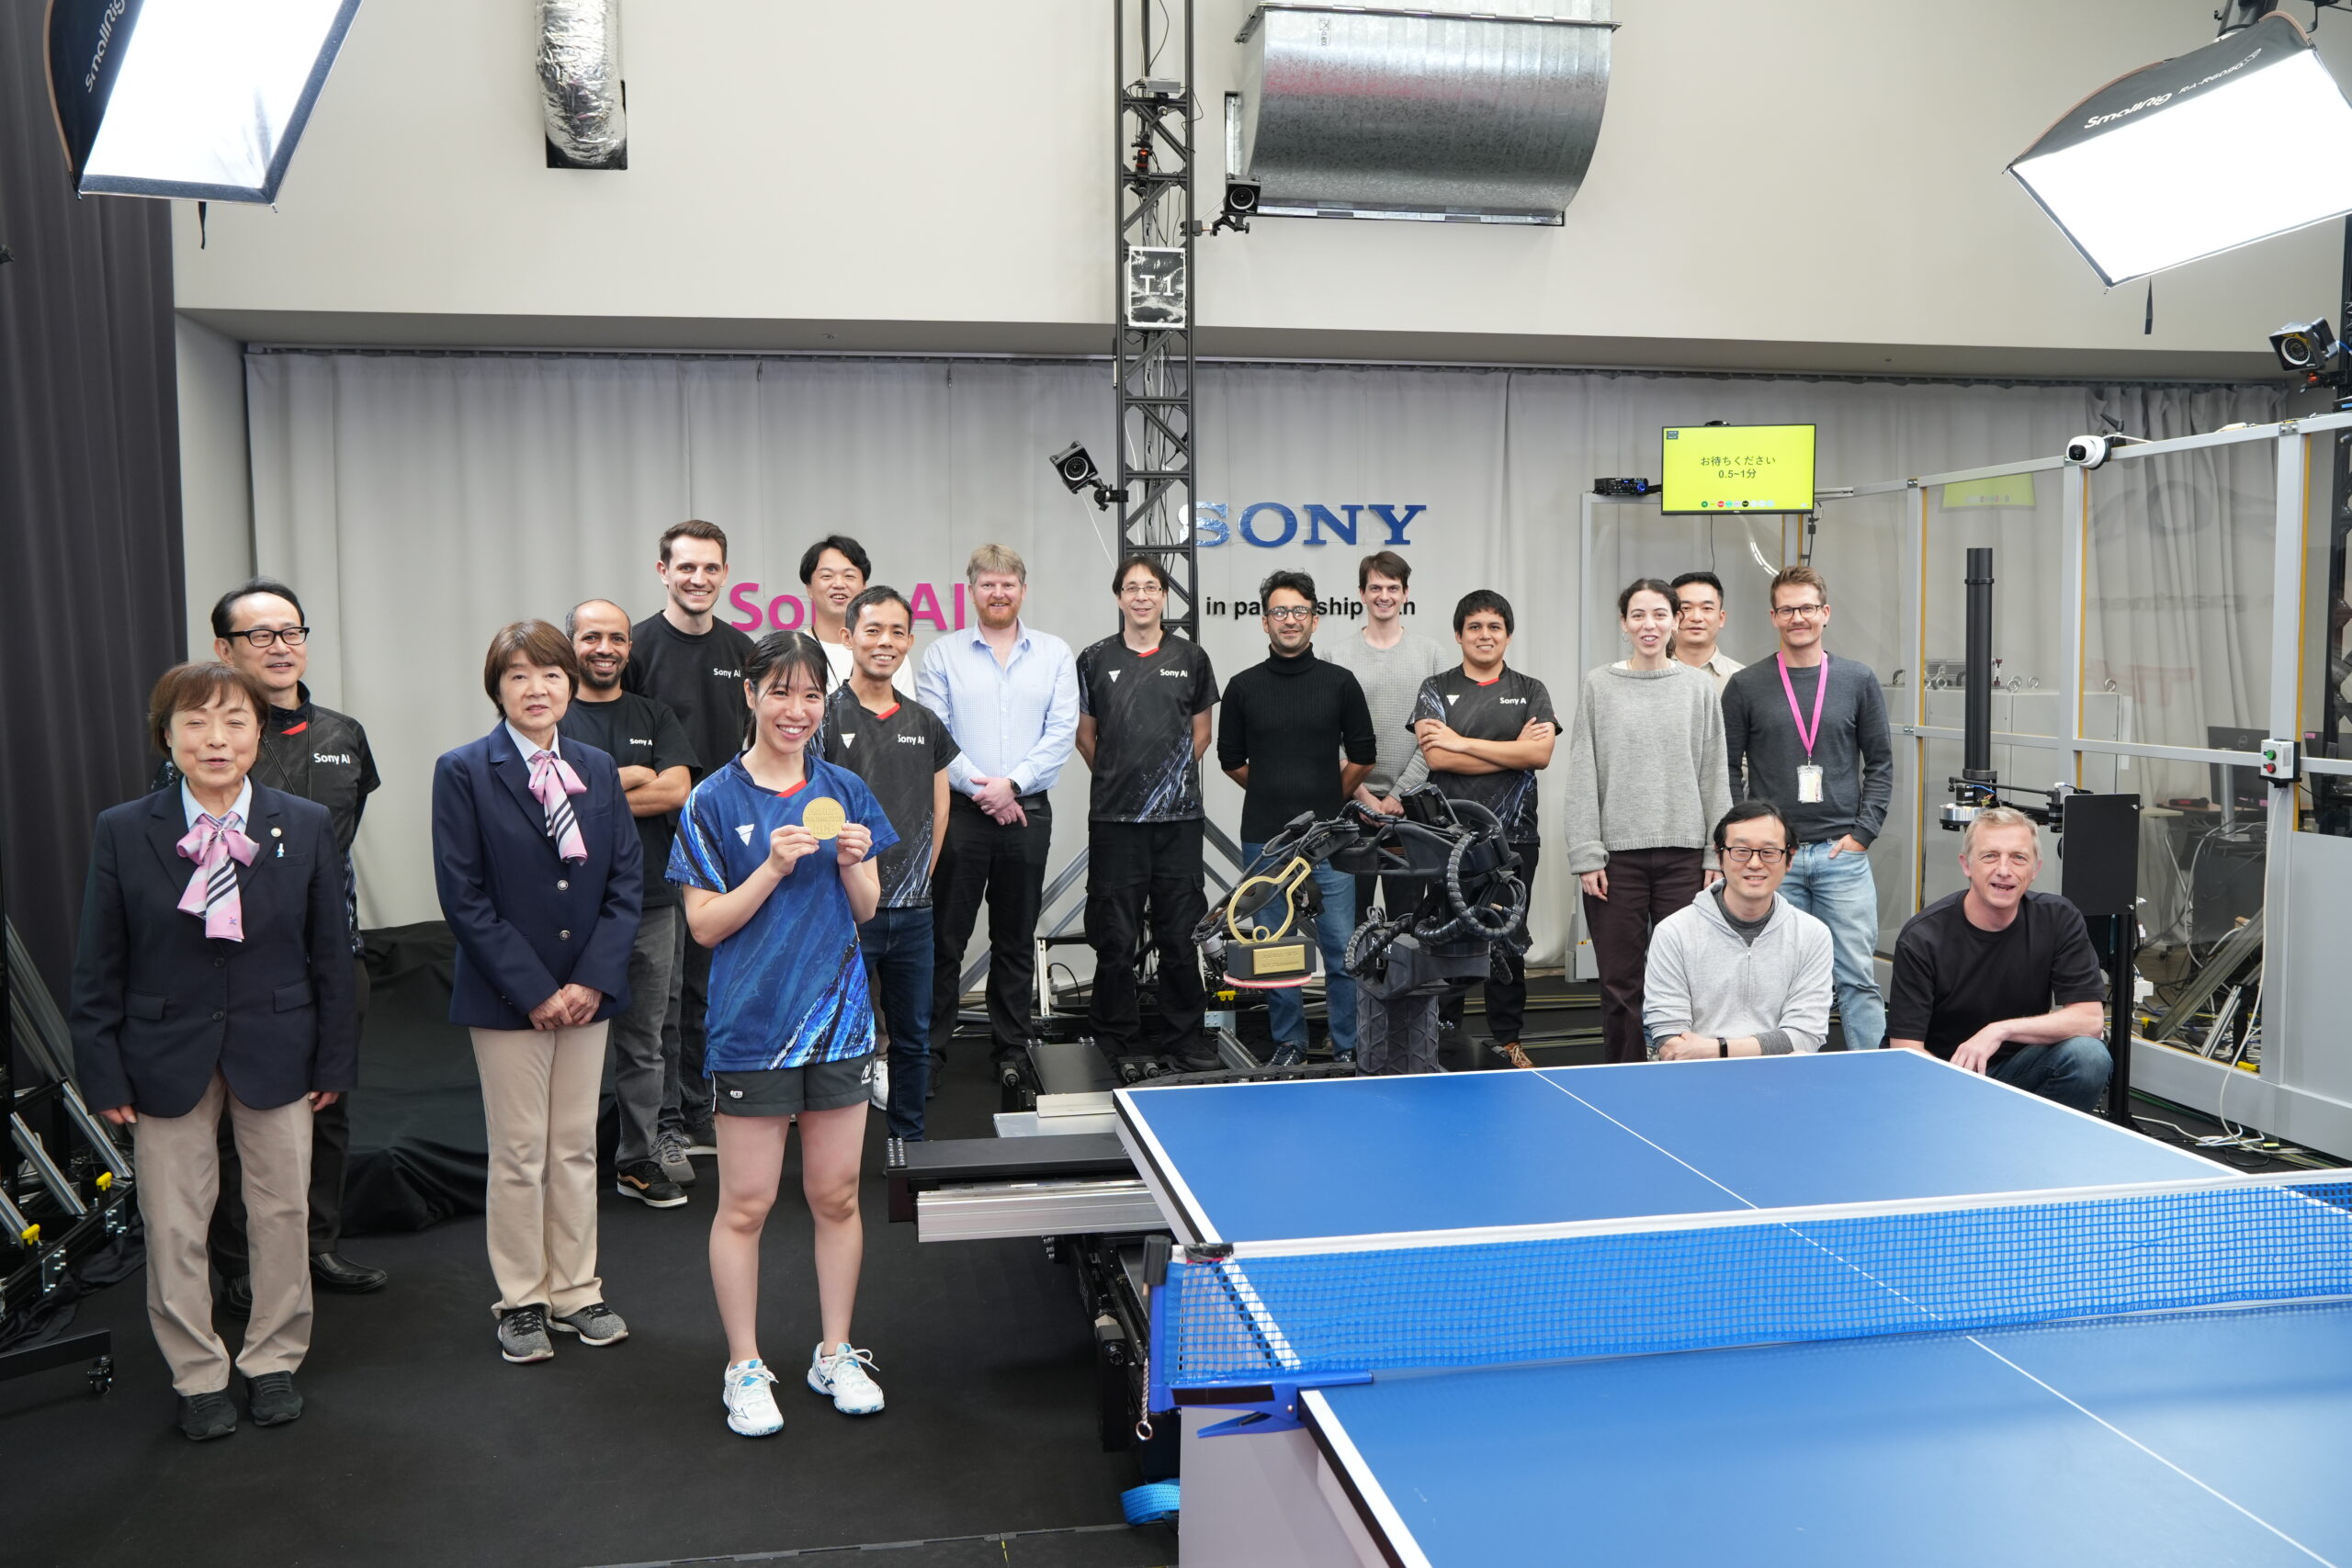
Members of the Ace research team and table tennis officials pose with the robot and its human opponent, Mayuka Taira, following an official match in December 2025.
From Figure 4 in the Nature manuscript “Outplaying elite table tennis players with an autonomous robot” this film shows the robot making a split section change to its trajectory when the ball hits the net. Credit: Sony AI and Nature.

Testing Ace against elite players

For the results reported in the Nature publication, Ace was evaluated in matches against five elite players and two professional table tennis players, under International Table Tennis Federation (ITTF) regulations. Ace achieved three victories in five matches against the elite players, along with competitive performances in the remaining matches.

There were some interesting results from the evaluations, including the fact that Ace was able to return a wide range of spins, consistently achieving over 75% return rate up to spins of 450 rad/s. The control systems behind Ace also allowed for quick reaction to unusual shots, such as balls bouncing off the net. This behavior illustrates the ability of the approach to generalize to situations that are both rare and hard to model in simulation.

Following submission of the Nature manuscript, the team conducted additional competitive matches in December 2025 and March 2026, beating professional players in the process. Compared with earlier evaluations, Ace demonstrated higher shot speeds, more aggressive placement closer to the table edge, and faster-paced rallies, reflecting continued performance gains under competitive conditions.

Find out more about the project in this video from Sony AI.

Resource-constrained image generation and visual understanding: an interview with Aniket Roy

In the latest in our series of interviews meeting the AAAI/SIGAI Doctoral Consortium participants, we caught up with Aniket Roy to find out more about his research on generative models for computer vision tasks.

Tell us a bit about your PhD – where did you study, and what was the topic of your research?

I recently completed my PhD in Computer Science at Johns Hopkins University, where I worked under the supervision of Bloomberg Distinguished Professor Rama Chellappa. My research primarily focused on developing methods for resource-constrained image generation and visual understanding. In particular, I explored how modern generative models can be adapted to operate efficiently while maintaining strong performance.

During my PhD, I worked broadly at the intersection of generative AI, multimodal learning, and few-shot learning. Much of my work involved designing techniques that enable models to learn new concepts or perform complex visual tasks with limited data or computational resources. This included research on diffusion models, personalized image generation, and multimodal representation learning. Overall, my work aims to make advanced vision and generative AI systems more adaptable, efficient, and practical for real-world applications.

Could you give us an overview of the research you carried out during your PhD?

During my PhD, my research broadly focused on improving the adaptability, efficiency, and quality of modern generative models for computer vision tasks. The rapid progress in generative AI–particularly diffusion models and vision–language models–has created new opportunities to address long-standing challenges such as data scarcity, controllable generation, and personalized image synthesis. My work aimed to develop methods that allow these large models to adapt effectively with limited data and computational resources while maintaining high visual fidelity.

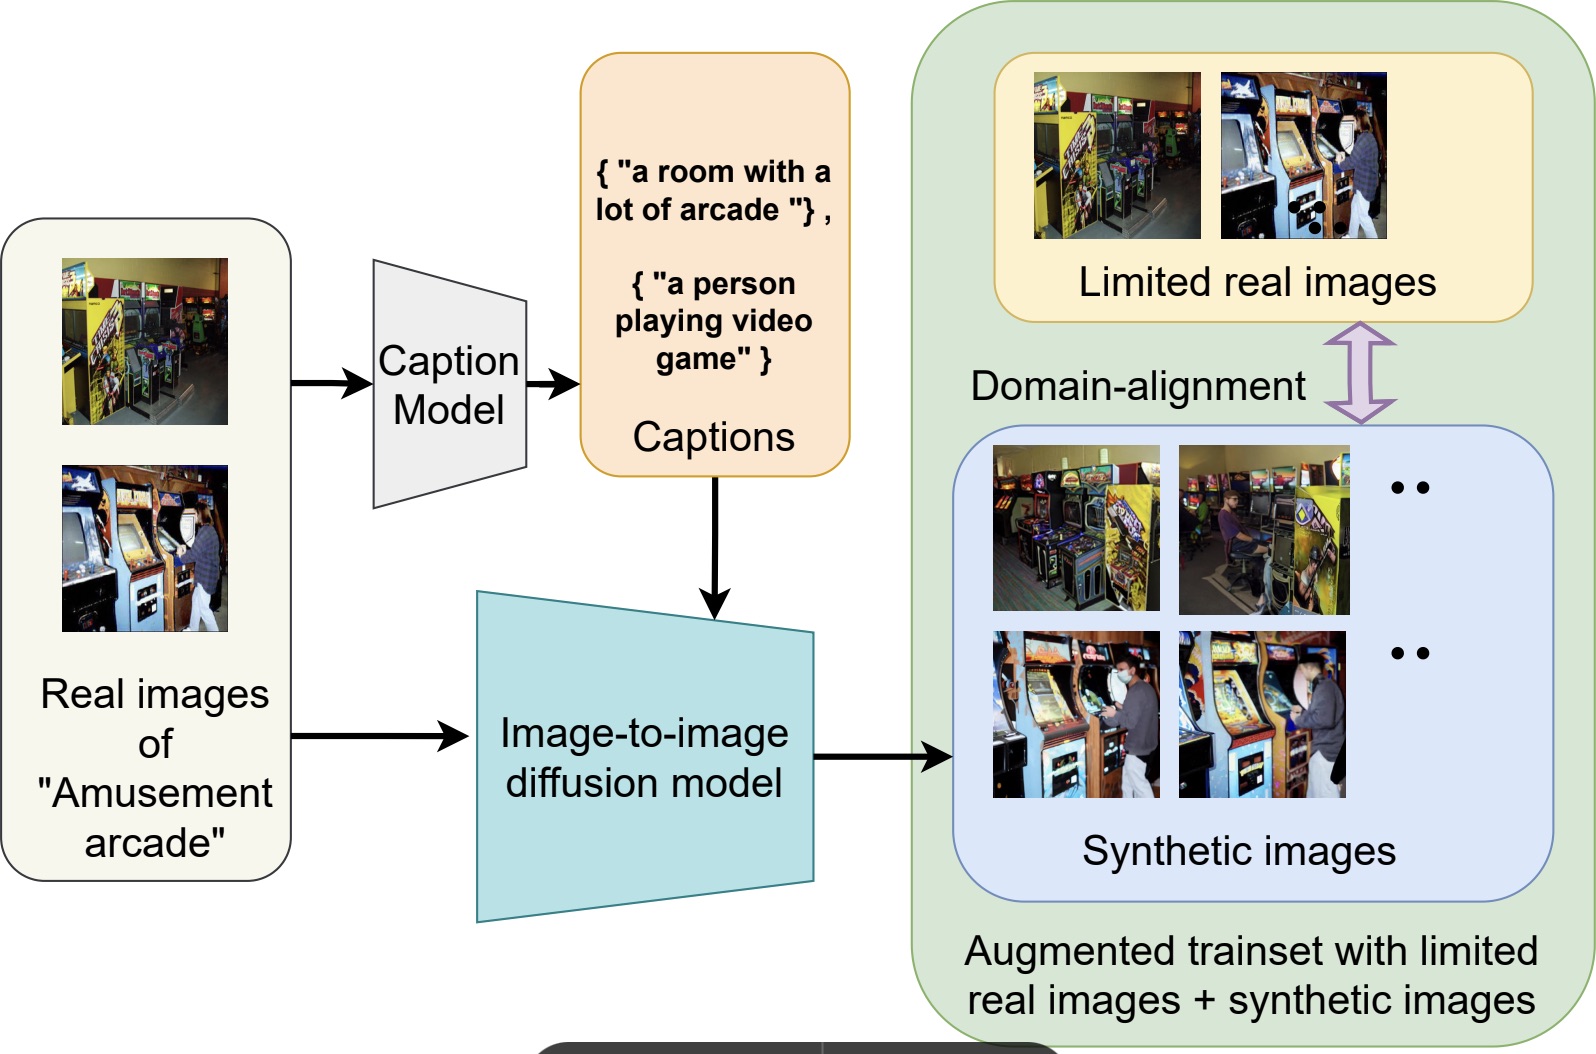
One line of my research addressed learning in data-constrained settings. For example, I proposed FeLMi, a few-shot learning framework that leverages uncertainty-guided hard mixup strategies to improve robustness and generalization when only a small number of labeled samples are available. Building on this idea of improving training data quality, I also developed Cap2Aug, which introduces caption-guided multimodal augmentation. This approach uses textual descriptions to guide synthetic image generation, improving visual diversity while reducing the domain gap between real and generated data.

Overview of Cap2Aug.

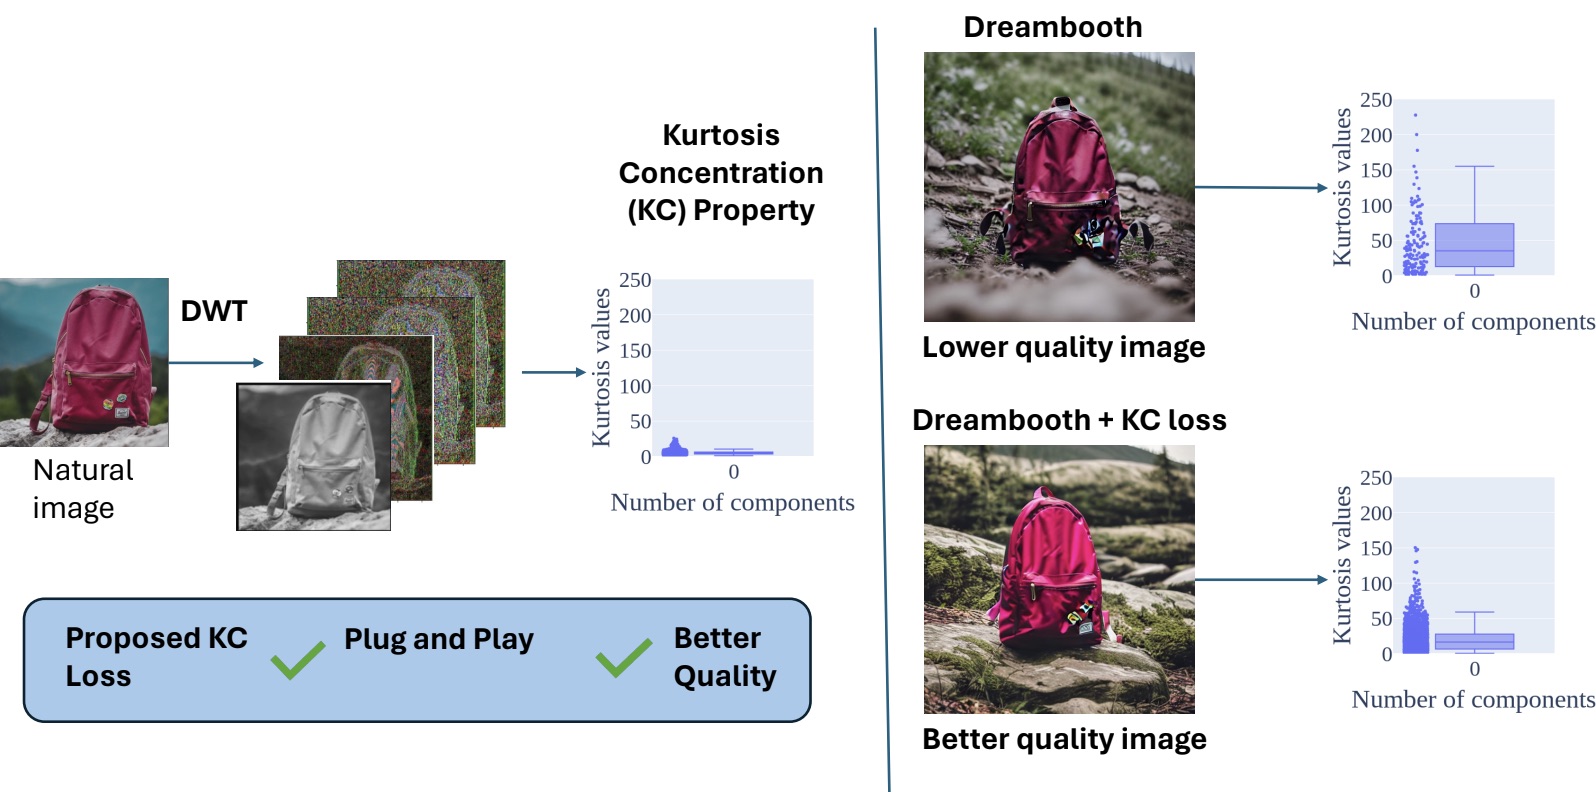
Another aspect of my research focused on improving the perceptual quality of images generated by diffusion models. In this direction, I proposed DiffNat, a plug-and-play regularization method based on the kurtosis-concentration property observed in natural images. By incorporating this principle into diffusion models through a KC loss, the generated images exhibit more natural texture statistics and improved perceptual realism, which also benefits downstream vision tasks.

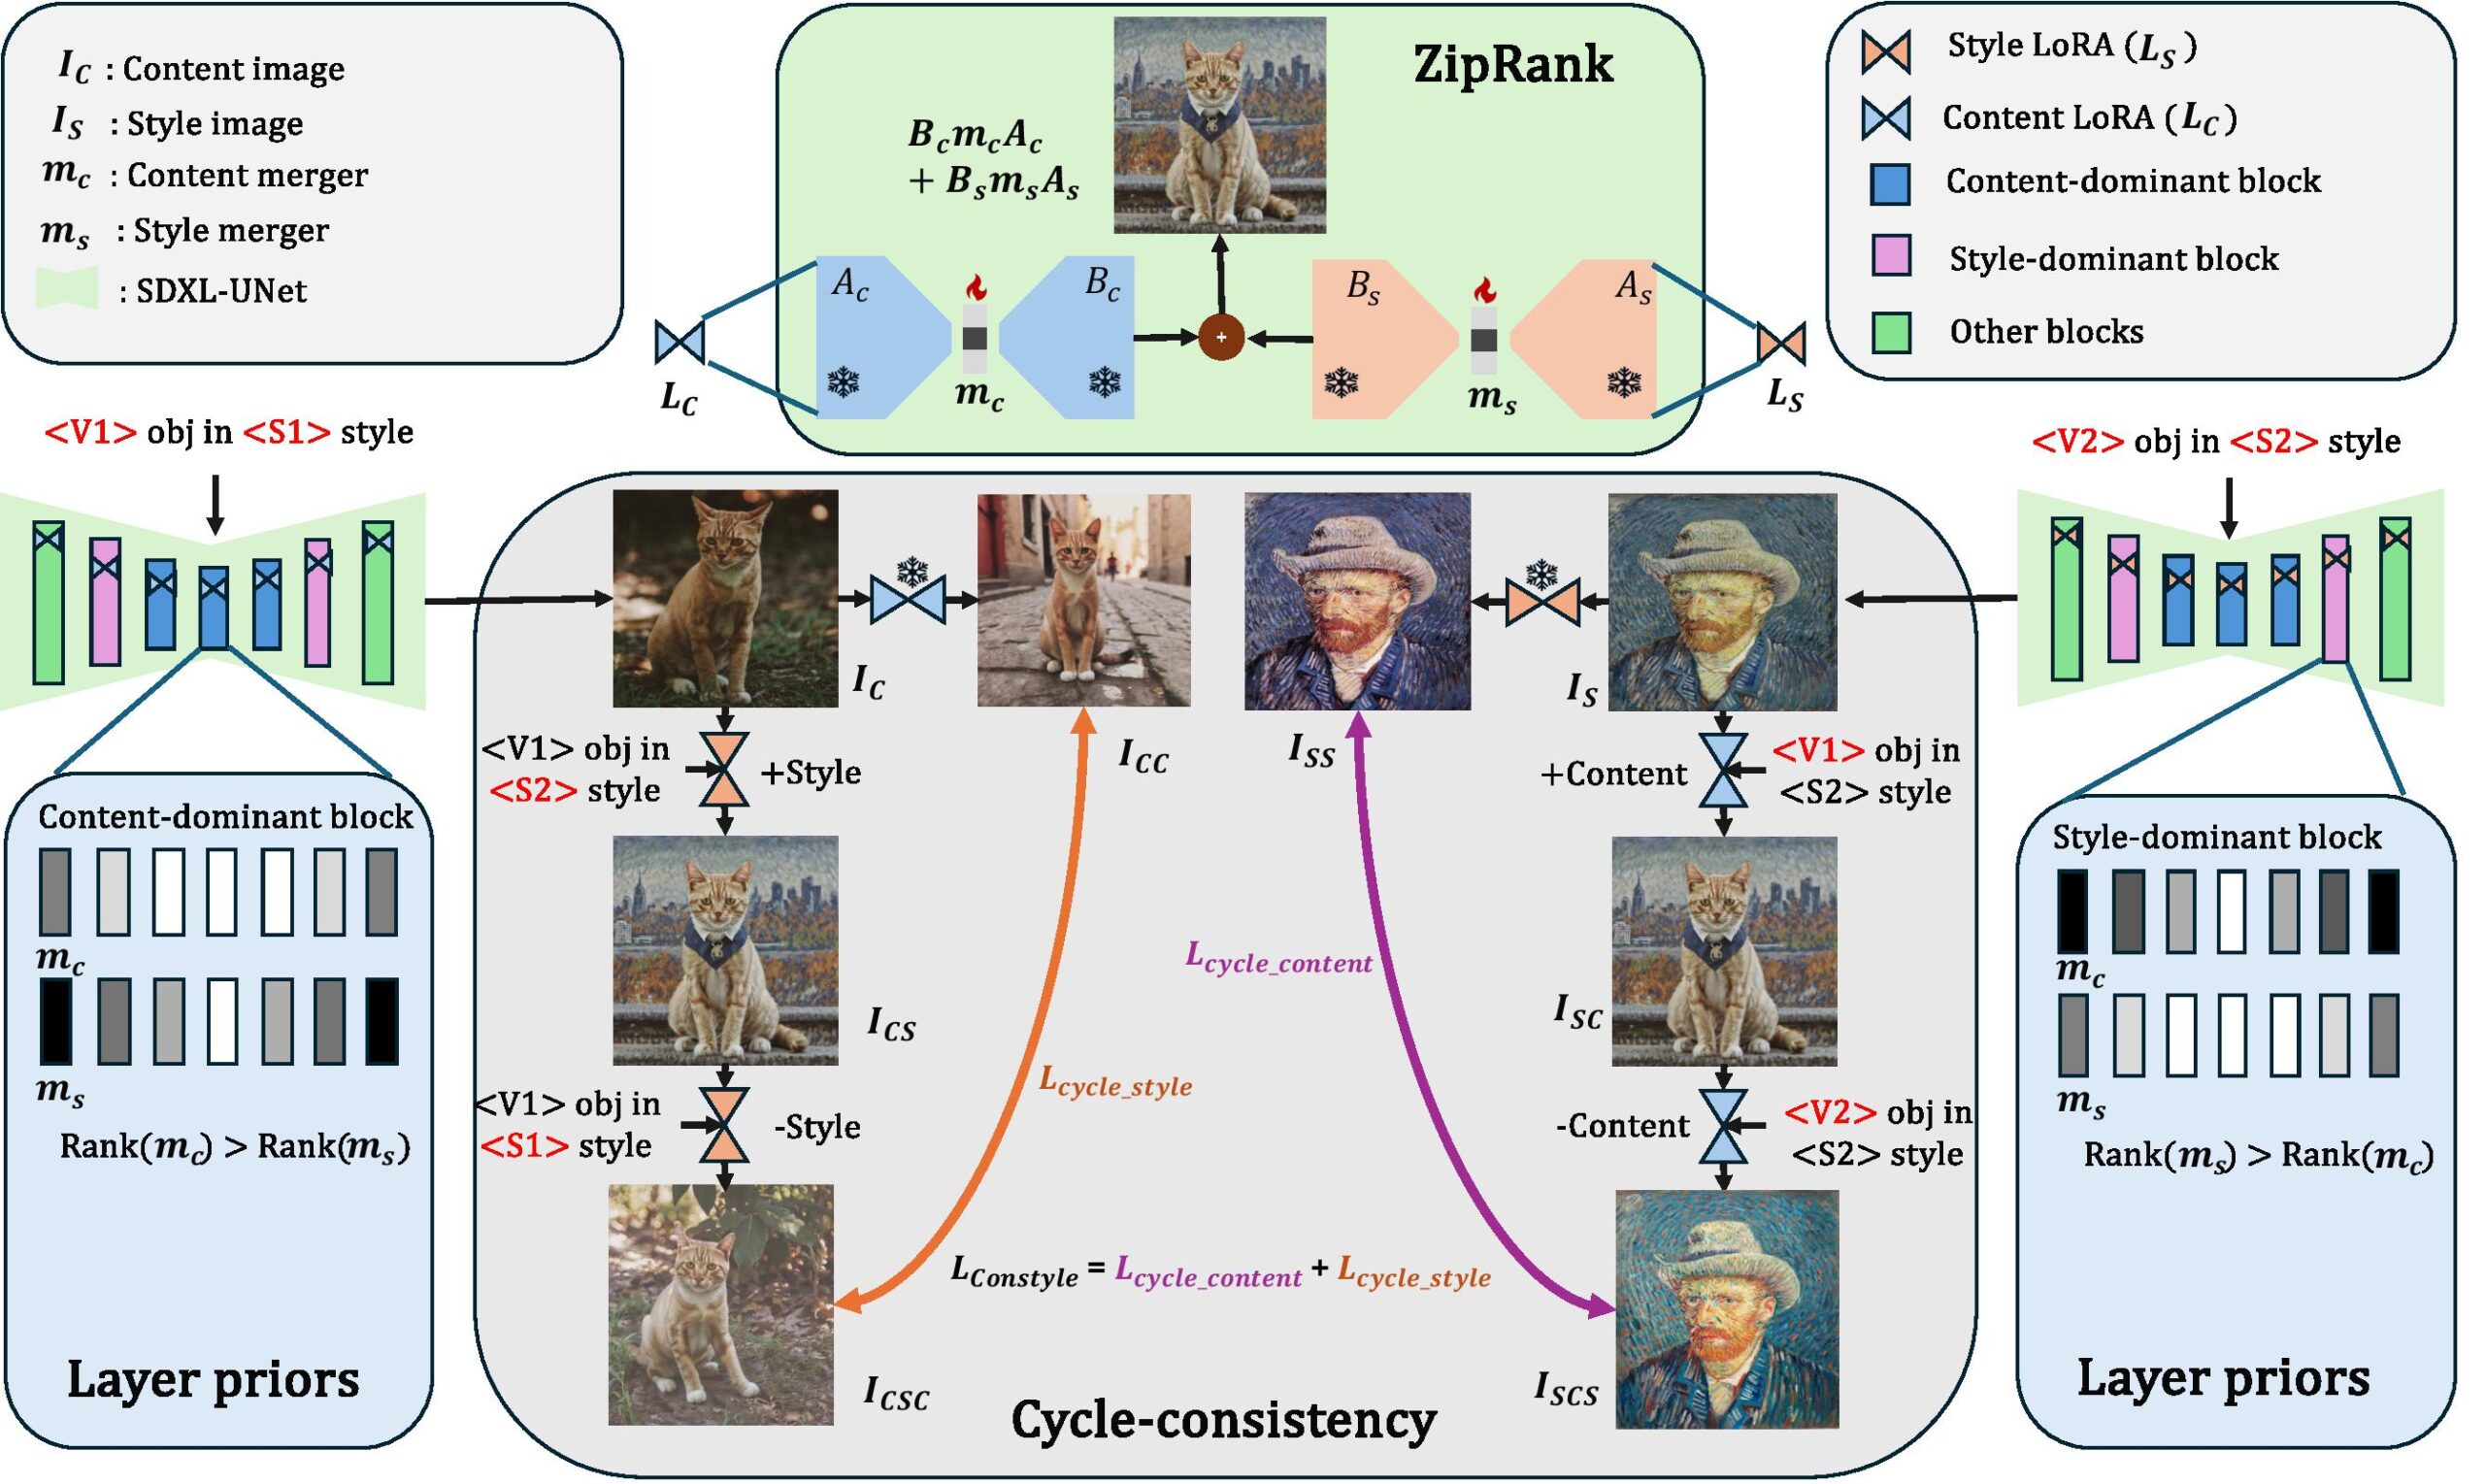
A major part of my work explored personalization and efficient adaptation of large generative models. I introduced DuoLoRA, a parameter-efficient framework for composing low-rank adapters that enables fine-grained control over content and style without requiring full retraining of the base model. I further extended personalization to zero-shot settings using a training-free textual inversion approach that allows arbitrary objects to be customized directly during generation. Finally, I proposed MultiLFG, a frequency-guided multi-LoRA composition framework that uses wavelet-domain representations and timestep-aware weighting to enable accurate and training-free fusion of multiple concepts in diffusion models.

Overview of DuoLoRA.

Overall, my research contributes toward building generative systems that are more efficient, adaptable, and controllable, enabling high-quality image generation and understanding even in data-limited or resource-constrained scenarios.

Was there a specific project or an aspect of your research that was particularly interesting?

One project that I found particularly interesting during my PhD is DiffNat, which was published in TMLR 2025. Diffusion models have become the backbone of many modern generative AI systems and have achieved impressive results in generating and editing realistic images. However, improving the perceptual quality and naturalness of generated images remains an important challenge.

Overview of DiffNat.

In this work, we introduced a simple but effective regularization technique called the kurtosis concentration (KC) loss, which can be integrated into standard diffusion model pipelines as a plug-and-play component. The idea was inspired by a statistical property of natural images: when an image is decomposed into different band-pass filtered versions–for example using the Discrete Wavelet Transform–the kurtosis values across these frequency bands tend to be relatively consistent. In contrast, generated images often show large discrepancies across these bands. Our method reduces the gap between the highest and lowest kurtosis values across the frequency components, encouraging the generated images to follow more natural image statistics.

In addition, we introduced a condition-agnostic perceptual guidance strategy during inference that further improves image fidelity without requiring additional training signals. We evaluated the approach across several diverse tasks, including personalized few-shot finetuning with text guidance, unconditional image generation, image super-resolution, and blind face restoration. Across these tasks, incorporating the KC loss and perceptual guidance consistently improved perceptual quality, measured through metrics such as FID and MUSIQ, as well as through human evaluation.

What I particularly liked about this project is that it connects classical image statistics with modern diffusion models. It shows that relatively simple statistical insights about natural images can still play a powerful role in improving large generative models.

What are your plans for building on the PhD – where are you working now and what will you be investigating next?

During my PhD, I discovered that I genuinely enjoy the process of research–especially the moment when an intuition or idea turns out to work in practice. That process of exploring new ideas and pushing the boundaries of what we know is something I find very motivating.

To continue pursuing this, I will be joining NEC Laboratories America as a Research Scientist. In this role, I hope to build on my PhD work by developing new methods for generative models and exploring how these models can interact with broader multimodal systems. In particular, I am interested in advancing research at the intersection of generative models, vision–language–action models, and embodied AI. More broadly, my goal is to contribute to the development of intelligent systems that can understand, generate, and interact with the visual world more effectively, while also continuing to push forward the scientific understanding of these models.

I’m interested in how you got into the field. What inspired you to study computer vision and machine learning?

My interest in computer vision and machine learning started during my undergraduate studies, when I took courses in signal processing and image processing. I found those subjects particularly fascinating because they allowed you to experiment with algorithms and immediately see their effects on images. That visual and intuitive aspect made the field very engaging, and it helped me appreciate how mathematical concepts can directly translate into meaningful visual results.

At the same time, I was also curious about how the human brain processes visual information—how we are able to recognize objects, understand scenes, and interpret complex visual signals so effortlessly. That curiosity led me to wonder whether we could design computational models that mimic aspects of human perception and enable machines to understand visual data in a similar way.

A major influence during this time was my professor, Dr. Kuntal Ghosh, who encouraged me to think more deeply about these problems and approach them with a scientific mindset. His mentorship played an important role in shaping my interest in research. Since then, that curiosity about visual perception and intelligent systems has continued to drive my work in computer vision and machine learning.

What was your experience of the Doctoral Consortium at AAAI?

Unfortunately, I was not able to attend the AAAI Doctoral Consortium in person due to visa-related issues. However, a colleague kindly helped present my poster on my behalf during the event. Even though I could not be there physically, I was very encouraged by the response my work received. Several researchers reached out to me after seeing the poster, and we had some very insightful discussions about the ideas and potential future directions of the research. In that sense, I still found the experience quite rewarding. The Doctoral Consortium is a great platform for sharing early-stage ideas, receiving feedback from the community, and connecting with other researchers working on related problems. I appreciated the opportunity to engage with people who were interested in the work, and those interactions helped spark new perspectives and collaborations.

Could you tell us an interesting (non-AI related) fact about you?

Outside of research, I’m a big fan of music and stand-up comedy, and I really enjoy traveling whenever I get the chance. Exploring new places, cultures, and perspectives is something I find refreshing—it’s a great way to recharge and stay curious about the world beyond work. I also enjoy writing poetic satire from time to time, and I occasionally perform it. It’s a fun creative outlet that allows me to mix humor and storytelling, which is quite different from the analytical nature of the research work I usually do.

About Aniket Roy

Aniket is currently a Research Scientist at NEC Labs America. He obtained his PhD from the Computer Science dept at Johns Hopkins University under the guidance of Bloomberg Distinguished Professor Prof. Rama Chellappa. Prior to that, he did a Master’s from Indian Institute of Technology Kharagpur. He was recognized with the Best Paper Award at IWDW 2016 and the Markose Thomas Memorial Award for the best research paper at the Master’s level. During PhD, he explored domains of few-shot learning, multimodal learning, diffusion models, LLMs, LoRA merging with publications in leading venues such as NeurIPS, ICCV, TMLR, WACV, CVPR and also 3 US patents filed. During his PhD, he also gained industrial experience through multiple internships in Amazon, Qualcomm, MERL, and SRI International. He was awarded as an Amazon Fellow (2023-24) at JHU and selected to participate in ICCV’25 and AAAI’26 doctoral consortium.

A history of RoboCup with Manuela Veloso

RoboCup is an international competition that promotes and advances robotics and AI through the challenges presented by its various leagues. We got the chance to sit down with Professor Manuela Veloso, one of RoboCup’s founders, to find out more about how it all started, how the community has grown over the years, and the vision for the future.

I think it would be very interesting to go right back to the beginning and hear how RoboCup got started. What was the initial idea, and how did it get set up?

So we are talking about the mid-90s. In terms of the research in those days, it was the beginning of the internet and many AI and computer science researchers were focused on the internet, first on sophisticated search algorithms, on natural language understanding, on information retrieval, and then on software agents and machine learning applied to digital information. From what I recall, there was a smaller group of researchers who were interested in actual, physical robots, and in particular in AI and robotics. I myself was specifically interested in the problem of creating autonomous robots with perception (get information from the world), cognition (select action to achieve goals), and then act (execute the planned actions). This combination of perception, cognition, and action is a very good framework for autonomous robots, because they have to get their information from their sensors, they have to reason about actions to achieve their goals, and then execute them. So, during the 90s, I was at Carnegie Mellon with this AI research goal of integrating perception, cognition, and action in autonomous robots.

Over in Canada there was Alan Mackworth, who jointly with his wonderful student, Michael Sahota, built a one-on-one little autonomous robot soccer set-up. Two robots ran on a small field that had a camera overhead, and aimed at scoring each in one of the two little goals. This work showed that this task of kicking a ball and defending and aiming at a goal could be done autonomously. So it was a tremendous demonstration that a robot soccer world could exist. Mostly at the same time, in Japan, Minoru Asada was showing that a big robot could learn with reinforcement learning how to push a ball into a goal. So you have these one-on-one, fully autonomous little robot cars that were pushing balls around in Canada, and then there was this effort of learning to score with a larger robot in Japan. The learning robot didn’t have a team, it was not a real game, but it was showing that reinforcement learning could learn the skill of aiming into a goal. And then there was also Hiroaki Kitano at Sony who was very interested in little humanoids.

So this is very beautiful because all these things came into play – all of us had different interests.

Alan Mackworth did not get involved with RoboCup, but he gave a demonstration of these one-on-one robots at AAAI in 1994. And in those days, I had a PhD student who had just joined – Peter Stone. And Peter was a serious and passionate soccer player. He saw this little game and he came to me and said, “this is what I want to do for my thesis research, robot soccer!” And for me, I was trying to find a research environment where autonomy was needed in the robot world. I had already a student, Karen Haigh, who was working with autonomous office robots, and learning to plan and execute. But with these soccer robots and Peter Stone’s interest everything came to play, and we started robot soccer research in my lab.

In 1996, there was also a robot soccer effort in South Korea, called MIROSOT, and that’s the first competition we participated in. So Peter Stone, myself, and the team we built at Carnegie Mellon – Sorin Achim and Kwun Han – went to South Korea to participate. From South Korea, we flew to a robot soccer workshop in Japan organized by Minoru Asada and Hiroaki Kitano. Also in attendance were Dominique Duhaut, Itsuki Noda, Silvia Coradeschi, and Enrico Pagello. And that’s where RoboCup really started – we decided to do a competition. And the good thing was that Kitano was the chair of IJCAI, which was going to happen in Osaka in the summer of 1997. So we are there in Osaka and literally we came up with this idea of having a robot soccer competition, RoboCup. It was a big moment for us as researchers. We had to come up with the rules of this competition so that people would be able to participate seven months later. We came up with the three leagues that we were interested in and had expertise in.

The small size league, building upon our Carnegie Mellon interests, would have a field with a camera overhead connected to a computer and then the computer would remotely control the robots through radio.

Then Minoru Asada had these bigger robots with wheels, and we created a league that we call the middle-size league to include the robotics research of Minoru Asada and others. And then Itsuki Noda was interested in creating a simulation environment. We thought that this would help get more people participating in this task of robot soccer.

So that’s how the three leagues started: the small size, the middle size, and the simulation. Hiroaki Kitano, Dominique Duhaut and I were in charge of the small-size league, Minoru Asada was in charge of the middle-size league, and Itsuki Noda ran the simulation league.

One of the challenges was to come up with the rules and define the robots and playing fields. I remember my own pragmatism in suggesting that we play on a ping-pong table for the small-size, as a ping-pong table is something that exists in the whole world. That meant that we would have a playing surface, with defined size and texture, anywhere in the world. We decided one ping-pong table for the small-size league, and nine ping-pong tables for the middle-size league.

In the summer of 1997, at IJCAI, when we all went to the actual first RoboCup competition, the space was gorgeous. Hiroaki Kitano had made these beautiful fields and white bleachers around the fields. It was a very beautiful space with an area with computers for the simulation league. There were 80 teams that had joined the simulation online. We were, I believe, five teams for the small size league and about eight to ten for the middle size league.

That’s how it all started. And 1997 it was in Osaka, in 1998 Dominique Duhaut organized RoboCup in Paris, at a modern Science Center, La Villette. And then in 1999, RoboCup was organized by Silvia Coradeschi, in Stockholm, again co-located with the IJCAI conference. In these three years 1997, ’98, and ’99, there were only these three leagues, small size, middle size, and simulation. It was the foundation of everything. RoboCup grew consistently every year in terms of the number of teams, the number of participants, and the number of participating countries.

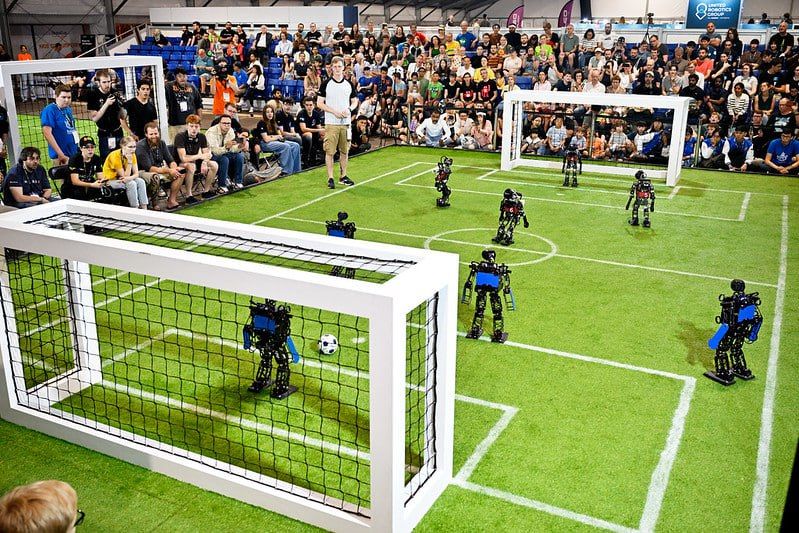
Some of the pitches in the main soccer arena at RoboCup 2024, held in Eindhoven, The Netherlands.
So how did RoboCup expand and could you talk about the decisions to add extra leagues?

Well, nothing was necessarily planned, it was more related to the research interests that people had. So when we were in Melbourne in 2000, there were two things that were added. One was RoboCupJunior. There was a professor, Elizabeth Sklar, who had a tremendous interest in robotics education for children. She proposed the RoboCupJunior competitions for children K-12. The goal of RoboCupJunior was to train all these young people to do research in robotics. It was and it still is extremely successful. In Melbourne there were probably the same number of children as there were people competing in what we now call the major leagues. As well as the soccer leagues, Elizabeth also ran a dance competition. This was very impressive – the children would dance on stage with their designed, built, and programmed mobile robots.

I believe that the rescue league was also introduced in 2000. The reason why we came up with rescue was because in those days, there was a lot of research on robots in disaster environments. So many people in our groups had an interest in developing robots that were able to handle disaster environments. So, we included that interest. And later on, @home was also introduced because people had an interest in service robots.

The logistics league came later to cover robots inside factories. The reason for introducing new leagues was always to include the community. And we didn’t want anyone to feel they could not come to RoboCup because they did different research with their robots. And so it was a very intellectually inclusive environment for AI and robotics researchers that could perform tasks autonomously – with perception, cognition, and action mostly in teams for particular tasks.

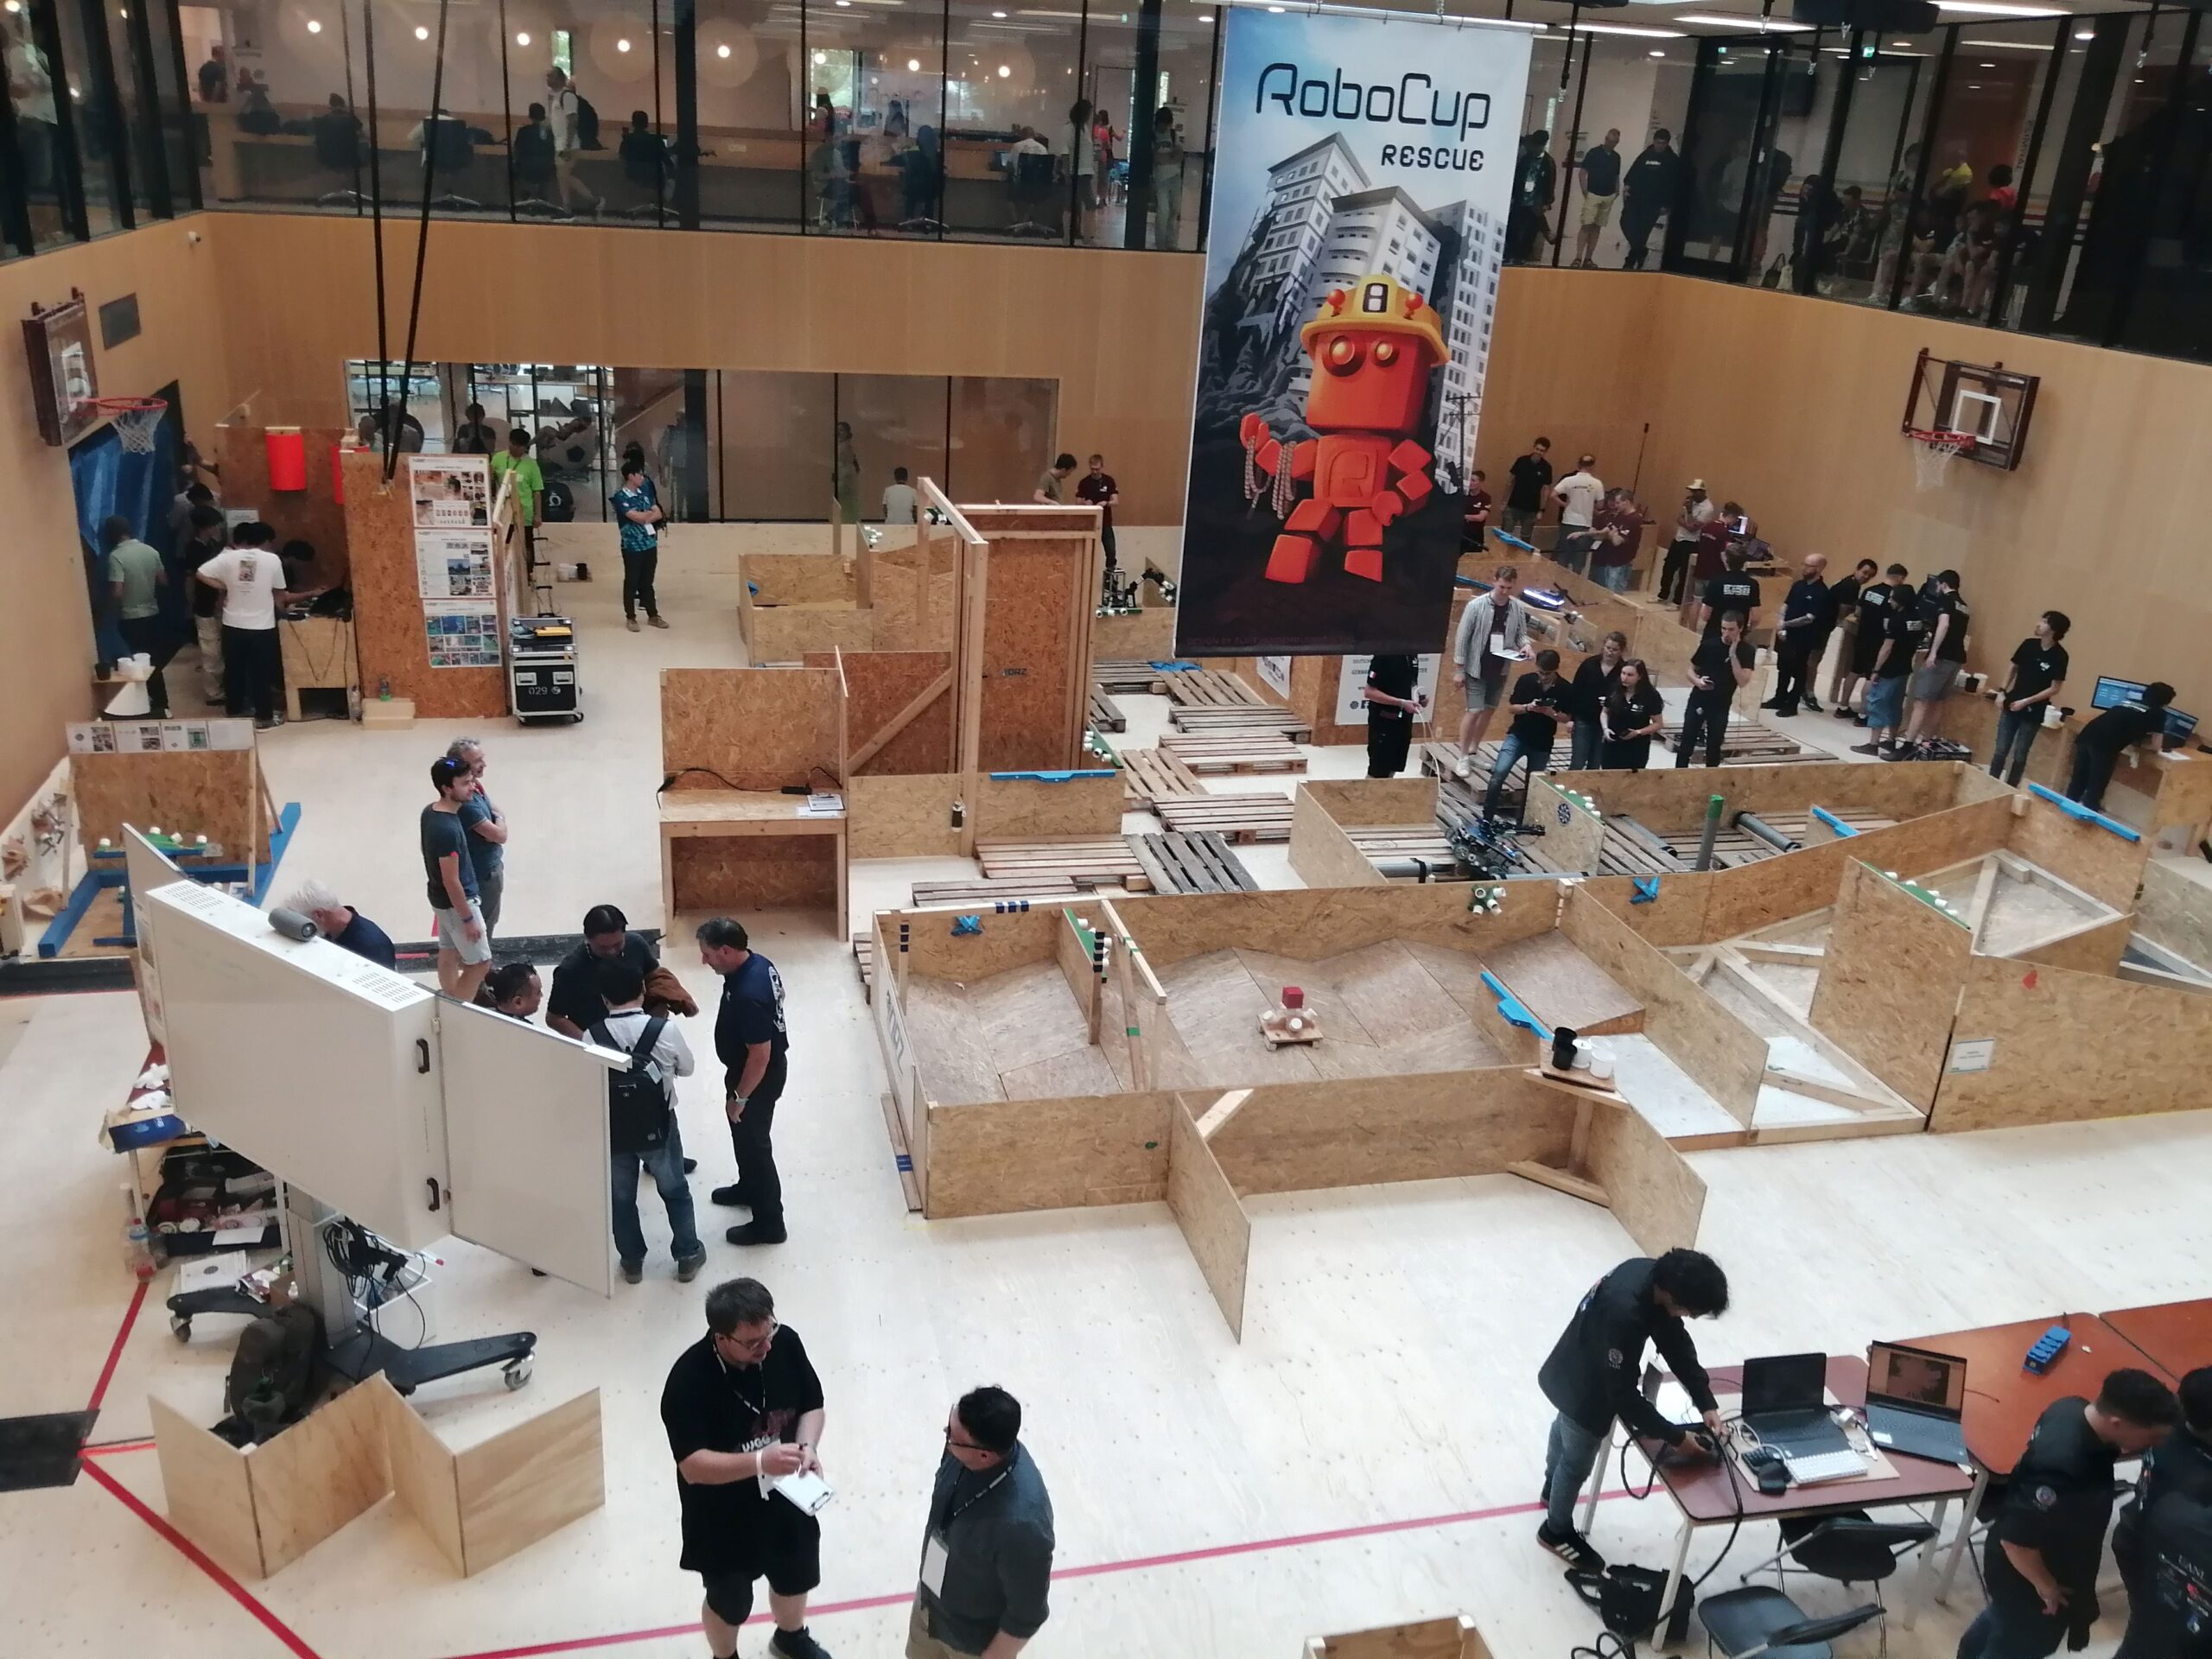
Rescue league arena at RoboCup 2024.
Could you talk about the changes that were announced last year, and the decision behind those?

Back in 1997, Hiroaki Kitano came up with this goal of a robot soccer team being able to beat the human World Cup winners by 2025. (I later tried, in the early 2000s, to rephrase that goal so that it was not about the robots beating the humans, but instead having robots playing alongside human players by 2050.) However, for this to happen, we have started the humanoid league so that the robots would have legs, not wheels. Our roadmap hence moves towards humanoid robots. It also happens that currently there are several robot companies who are producing humanoid robots that are easy to acquire, so researchers do not have the design and build their own humanoid robots, which was a difficult task that was pursued only by a limited group of researchers. In parallel, events started aiming at including humanoid robot soccer. We believed that RoboCup should be visible and a reference for humanoid robot soccer. We then proposed and changed that, in the international RoboCup competitions, robot soccer will focus solely on humanoid robots. That doesn’t mean that the other RoboCup leagues aren’t valuable. But if they continue at a regional level, there will still be venues to foster these other types of interests. The RoboCup international competitions would be solely focused on humanoid robot soccer.

Action from the humanoid soccer league at RoboCup 2025. Image courtesy of Alessandra Rossi.
RoboCup was tremendously successful in terms of including a variety of different autonomous robot research interests from the community. But I also believe that now we should move into just humanoid soccer at the international level. This will help with visibility of the competition and also for consolidation. We can now buy humanoid robots that we didn’t have before. Previously, you had to build them in your universities, and that was not a research direction for many people. But there is not that excuse anymore. You can buy humanoid robots, and increasingly, you can talk with these humanoid robots using GenAI. So it became a different challenge, a much more accessible challenge than before. The challenge will be: can these platforms play soccer in the presence of another team? I think it’s a fascinating new direction to try to focus on this challenge of the game of soccer – multiple players, two teams in a large space, eventually coordinating, collaborating, or playing with and against humans. So that’s the rationale.

When people don’t know the story, they tend to wonder why we have all these other leagues, such as rescue and logistics. It was always driven by the interests of the community and a big heart for a research approach. And we always thought that because we were organizing an event with a venue, that we could include these people that have interests outside of soccer. That has always been our drive. However, it’s true that it diluted a little bit the goal of 2050 – the humanoid soccer robots. Now I think it’s time to go back to soccer as a main focus, and still keep supporting the other interests that we have fostered, more at a regional level.

There are still a lot of details to be sorted out. And, of course, people may be upset by leagues terminating at the international level. I have always participated in the small-size league myself, 20 years of participating, and I am very attached to it. I was always the trustee representing the small-size league, and I am not sure I am happy with the small-size not being in the international event. But I need to think beyond what my personal interests are and try to understand what would have a bigger impact for AI, robotics, and RoboCup. I think that that’s demonstrating a group of humanoids playing soccer. And if we don’t do it at RoboCup, maybe someone else will.

The way I think about it is that we have made this decision and we can reevaluate it in five or ten years. But not making a change and never having the courage to deviate from what we have been pursuing is less exciting. Things have stalled a bit, with the same number of teams, the same people, the same rules, the same type of intellectual and research accomplishments. We need to excite people about something major again. So I think that the community will greatly embrace this new RoboCup international. And we are so well organized locally, that we can support other leagues at the local events.

I do think that, from a scientific and research point of view, it’s the right moment to target the soccer humanoid robots, because of their availability and our RoboCup ultimate goal. I think it would be amazing if people knew RoboCup international as the humanoid robot soccer competition. Can you imagine in 2027 having 100 teams all playing soccer with humanoids? We’ll see.

About Manuela Veloso

  • Herbert A. Simon University Professor Emerita, School of Computer Science, Carnegie Mellon University
  • 2018-2026 Founder and Head, JPMorganChase AI Research, Managing Director

For the last eight years, Manuela Veloso has been the founder and Head of JPMorganChase AI Research and Herbert A. Simon University Professor Emerita at Carnegie Mellon University, where she was faculty in the Computer Science Department and then Head of the Machine Learning Department.

At JPMorganChase, she built a team of 100 top talented members with graduate education (PhD and Masters) in AI and related disciplines. The team focused on pillar areas of AI in finance, including data-driven optimization, planning and search, document analysis, trustworthy AI, AI and mathematical reasoning, continual learning, and multiagent systems. The team published their research in academic venues and addressed and contributed to business needs and vision.

Veloso has a licenciatura degree in Electrical Engineering and an M.Sc. in Electrical and Computer Engineering from Instituto Superior Técnico, Lisbon, an M.A. in Computer Science from Boston University, and a Ph.D. in Computer Science from Carnegie Mellon University. Veloso has Doctorate Honoris Causa degrees from the Örebro University, Sweden, the Instituto Universitário de Lisboa (ISCTE), Portugal, the Université de Bordeaux, France, and the Universidade Católica of Portugal.

She served as president of the Association for the Advancement of Artificial Intelligence (AAAI), and she is co-founder and a Past President of the RoboCup Federation. She is a fellow of main professional organizations in her area, namely AAAI, IEEE, AAAS, and ACM. She is the recipient of the ACM/SIGART Autonomous Agents Research Award, the Einstein Chair of the Chinese Academy of Sciences, an NSF Career Award, and the Allen Newell Medal for Excellence in Research. Veloso is a member of the National Academy of Engineering with a citation “for contributions to artificial intelligence and its applications in robotics and the financial services industry.” She is also a member of the Academy of Sciences of Portugal.

Her research interests are in AI, including Multiagent Systems, Autonomous Robots, Continual Learning Agents, and AI in Finance. For further details, see Manuela’s webpage.

How can robots acquire skills through interactions with the physical world? An interview with Jiaheng Hu

One of the key challenges in building robots for household or industrial settings is the need to master the control of high-degree-of-freedom systems such as mobile manipulators. Reinforcement learning has been a promising avenue for acquiring robot control policies, however, scaling to complex systems has proved tricky. In their work SLAC: Simulation-Pretrained Latent Action Space for Whole-Body Real-World RL, Jiaheng Hu, Peter Stone and Roberto Martín-Martín introduce a method that renders real-world reinforcement learning feasible for complex embodiments. We caught up with Jiaheng to find out more.

What is the topic of the research in your paper and why is it an interesting area for study?

This paper is about how robots (in particular, household robots like mobile manipulators) can autonomously acquire skills via interacting with the physical world (i.e. real-world reinforcement learning). Reinforcement learning (RL) is a general learning framework for learning from trial-and-error interaction with an environment, and has huge potential in allowing robots to learn tasks without humans hand-engineering the solution. RL for robotics is a very exciting field, as it can open possibilities for robots to self-improve in a scalable way, towards the creation of general-purpose household robots that can assist people in our everyday lives.

What were some of the issues with previous methods that your paper was trying to address?

Previously, most of the successful applications of RL to robotics were done by training entirely in simulation, then deploying the policy in the real-world directly (i.e. zero-shot sim2real). However, such a method has big limitations: on one hand, it is not very scalable, as you need to create task-specific, high-fidelity simulation environments that highly match the real-world environment that you want to deploy the robot in, and this can often take days or months for each and every task. On the other hand, some tasks are actually very hard to simulate, as they involve deformable objects and contact-rich interactions (for example, pouring water, folding clothes, wiping whiteboard). For these tasks, the simulation is often quite different from the real world. This is where real-world RL comes into play: if we can allow a robot to learn by directly interacting with the physical world, we don’t need a simulator anymore. However, while several attempts have been made towards realizing real-world RL, it is actually a very hard problem since: 1. Sample-inefficiency: RL requires a lot of samples (i.e. interaction with the environment) to learn good behavior, which is often impossible to collect in large quantities in the real-world. 2. Safety Issues: RL requires exploration, and random exploration in the real-world is often very very dangerous. The robot can break itself and will never be able to recover from that.

Could you tell us about the method (SLAC) that you’ve introduced?

So, creating high-fidelity simulations is very hard, and directly learning in the real-world is also really hard. What should we do? The key idea of SLAC is that we can use a low-fidelity simulation environment to assist subsequent real-world RL. Specifically, SLAC implements this idea in a two-step process: in the first step, SLAC learns a latent action space in simulation via unsupervised reinforcement learning. Unsupervised RL is a technique that allows the robot to explore a given environment and learn task-agnostic behaviors. In SLAC, we design a special unsupervised RL objective that encourages these behaviors to be safe and structured.

In the second step, we treat these learned behaviors as the new action space of the robot, where the robot does real-world RL for downstream tasks such as wiping whiteboards by making decisions in this new action space. Importantly, this method allow us to circumvent the two biggest problem of real-world RL: we don’t have to worry about safety issues since the new action space is pretrained to be always safe; and we can learn in a sample-efficient way because our new action space is trained to be very structured.

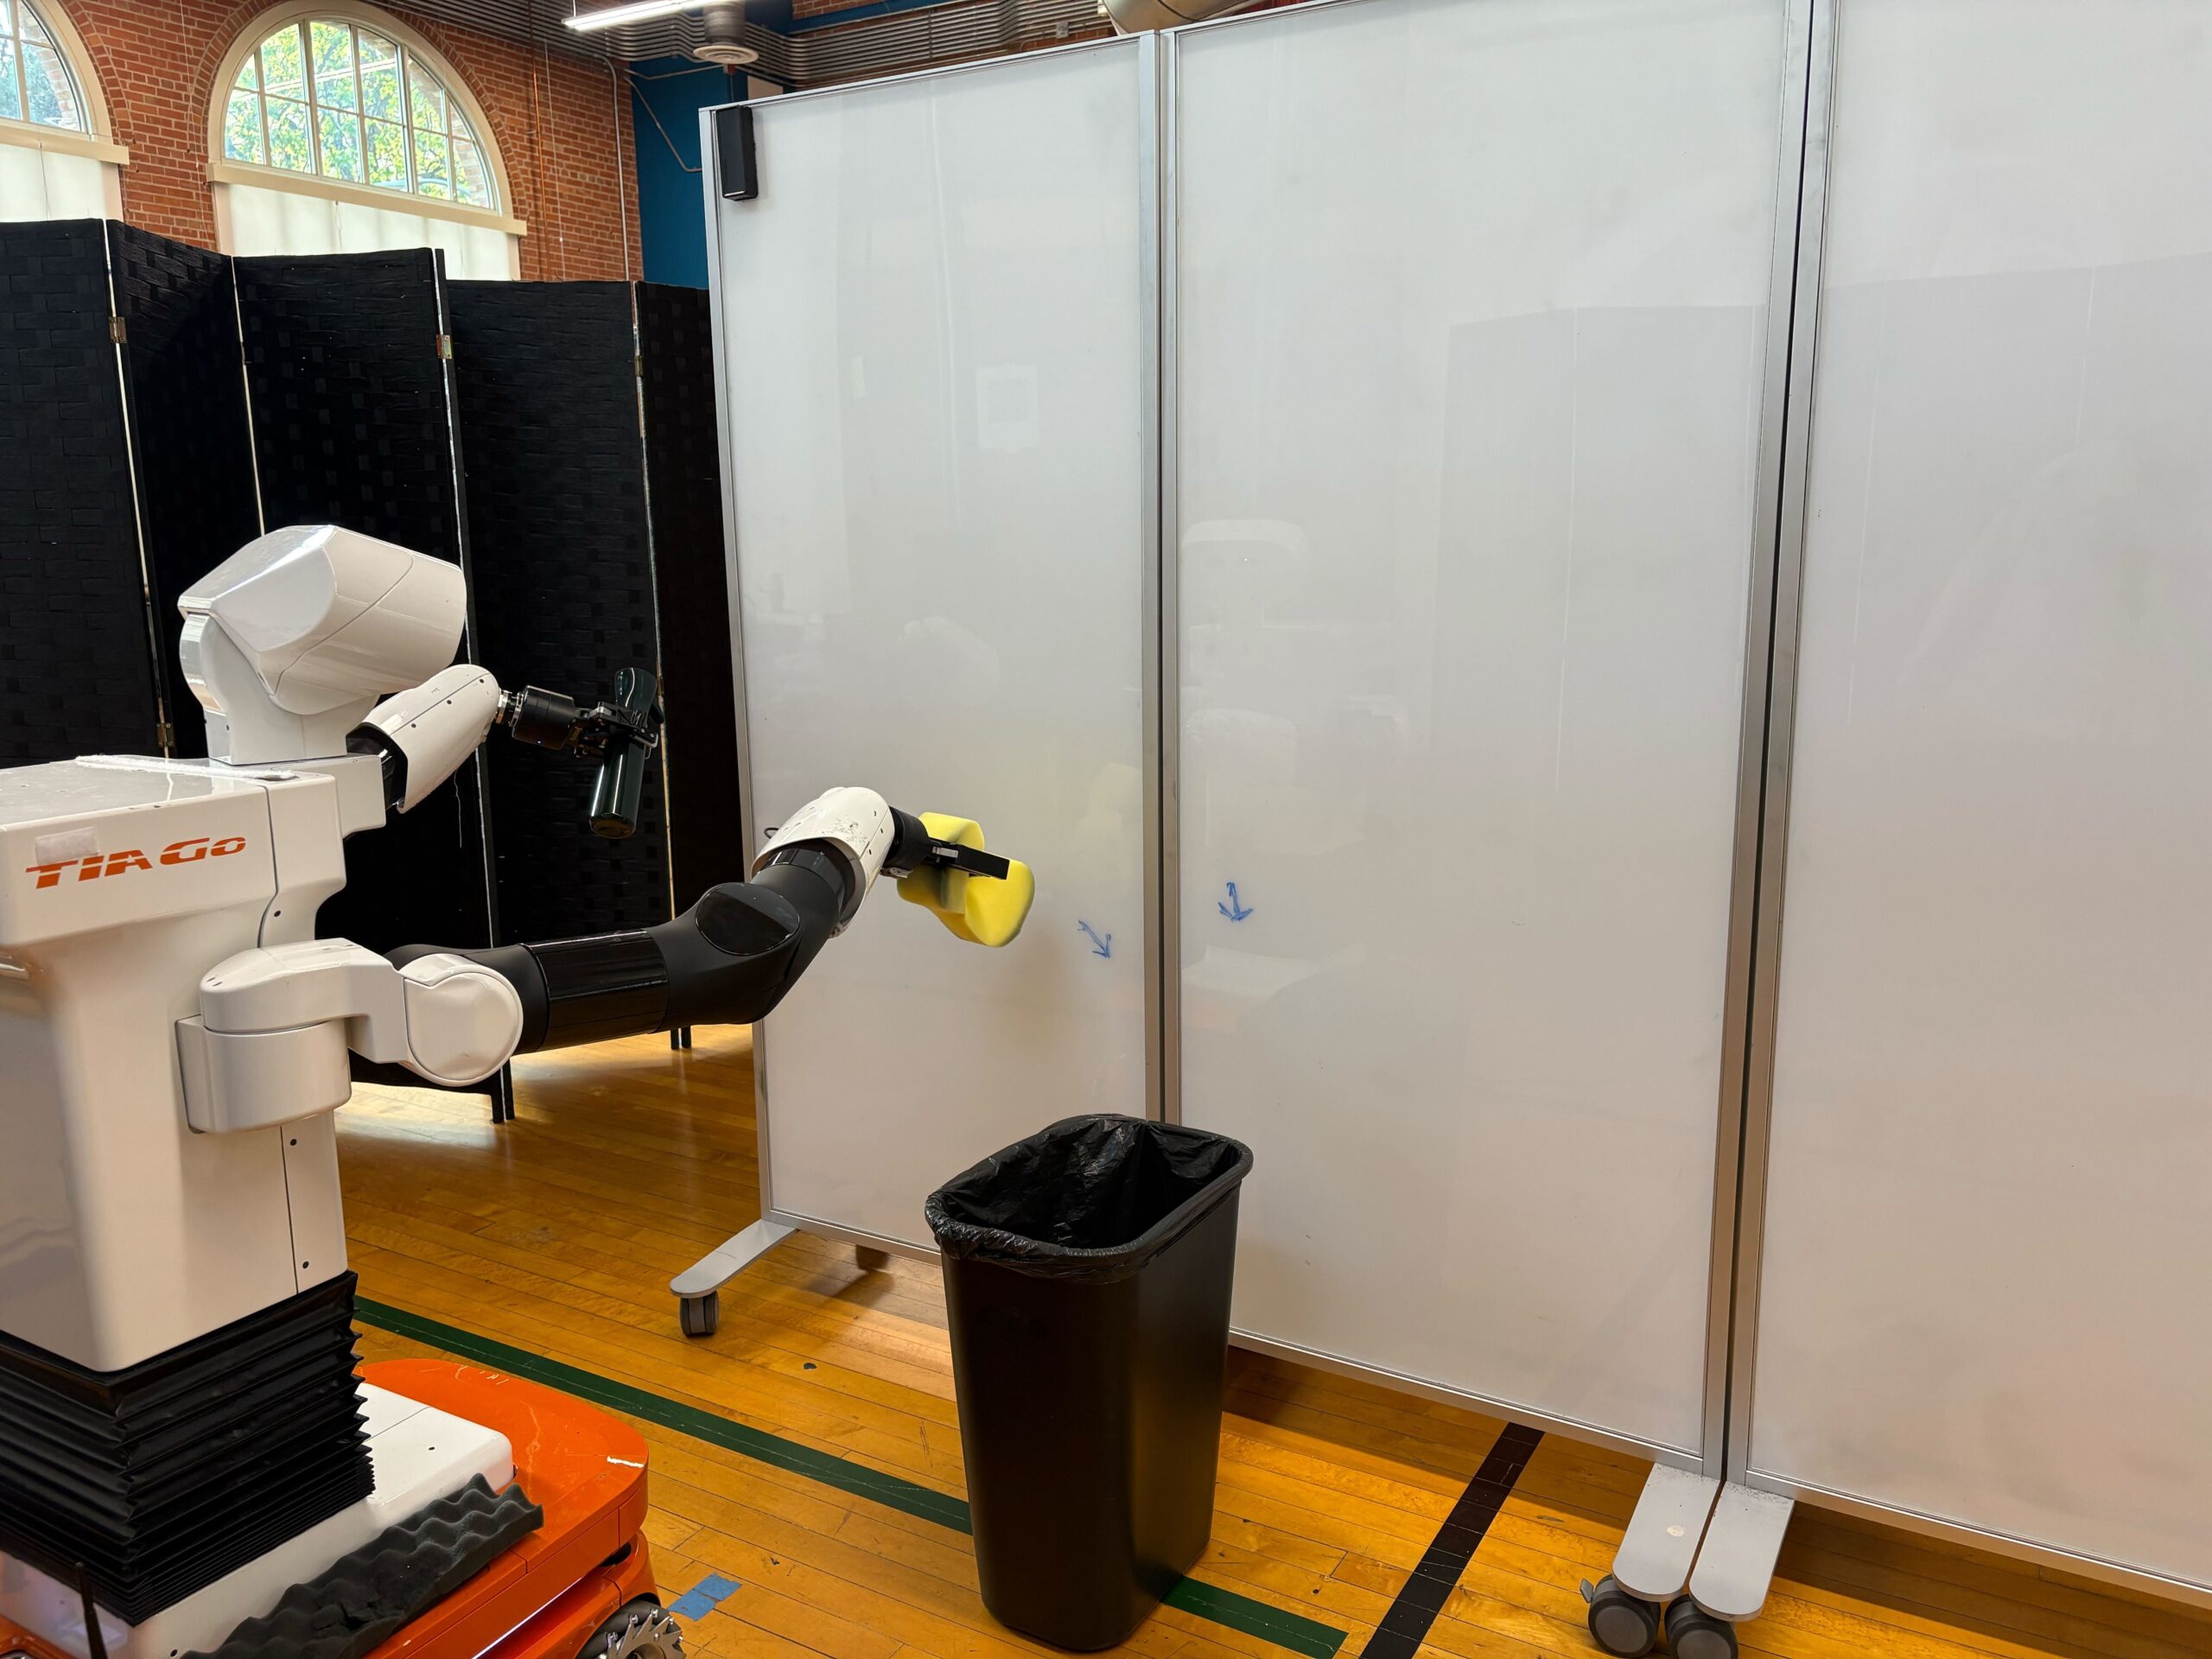
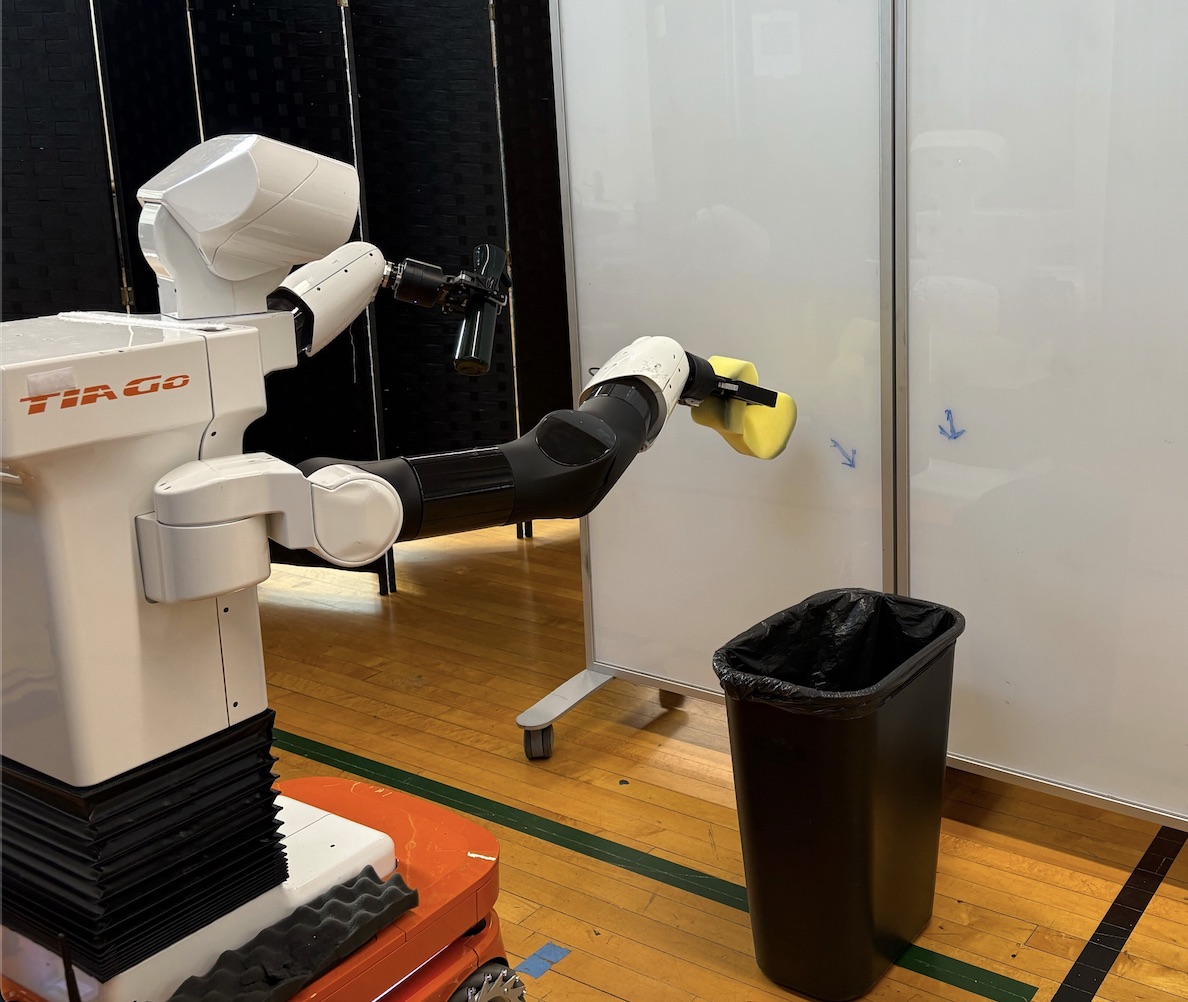
The robot carrying out the task of wiping a whiteboard.
How did you go about testing and evaluating your method, and what were some of the key results?

We test our methods on a real Tiago robot – a high degrees-of-freedom, bi-manual mobile manipulation, on a series of very challenging real-world tasks, including wiping a large whiteboard, cleaning a table, and sweeping trash into a bag. These tasks are challenging from three aspects: 1. They are visuo-motor tasks that require processing of high-dimensional image information. 2. They require the whole-body motion of the robot (i.e. controlling many degrees-of-freedom at the same time), and 3. They are contact-rich, which makes it hard to simulate accurately. On all of these tasks, our method allows us to learn high-performance policies (>80% success rate) within an hour of real-world interactions. By comparison, previous methods simply cannot solve the task, and often risk breaking the robot. So to summarize, previously it was simply not possible to solve these tasks via real-world RL, and our method has made it possible.

What are your plans for future work?

I think there is still a lot more to do at the intersection of RL and robotics. My eventual goal is to create truly self-improving robots that can learn entirely by themselves without any human involvement. More recently, I’ve been interested in how we can leverage foundation models such as vision-language models (VLMs) and vision-language-action models (VLAs) to further automate the self-improvement loop.

About Jiaheng

Jiaheng Hu is a 4th-year PhD student at UT-Austin, co-advised by Prof. Peter Stone and Prof. Roberto Martín-Martín. His research interest is in Robot Learning and Reinforcement Learning, with the long-term goal of developing self-improving robots that can learn and adapt autonomously in unstructured environments. Jiaheng’s work has been published at top-tier Robotics and ML venues, including CoRL, NeurIPS, RSS, and ICRA, and has earned multiple best paper nominations and awards. During his PhD, he interned at Google DeepMind and Ai2, and is a recipient of the Two Sigma PhD Fellowship.

Read the work in full

SLAC: Simulation-Pretrained Latent Action Space for Whole-Body Real-World RL, Jiaheng Hu, Peter Stone, Roberto Martín-Martín.

Sven Koenig wins the 2026 ACM/SIGAI Autonomous Agents Research Award

ACM SIGAI logo

Congratulations to Sven Koenig on winning the 2026 ACM/SIGAI Autonomous Agents Research Award. This prestigious award is made for excellence in research in the area of autonomous agents. It is intended to recognize researchers in autonomous agents whose current work is an important influence on the field.

Professor Sven Koenig was recognised “for his work on AI planning and search, which has shaped how intelligent agents reason and act in complex, dynamic environments. His contributions seamlessly bridge theory and practice, with a profound impact not only on AI and multi-agent systems, but also on robotics, where his algorithms have enabled robust, scalable autonomy in real-world robotic platforms”.

Sven Koenig is Chancellor’s Professor and Bren Chair at the Computer Science Department of UC Irvine. A Fellow of AAAI, AAAS, and ACM, Professor Koenig has received several best paper awards from AAAI, ICALP and SoCS, and contributed to the community in numerous service roles, most recently having served as the conference chair of AAAI 2026.
Taking humanoid soccer to the next level: An interview with RoboCup trustee Alessandra Rossi

A core objective of RoboCup is to promote and advance robotics and AI research through the challenges offered by its various leagues. The ultimate goal of the soccer competition is that, by 2050, a team of fully autonomous humanoid robots will defeat the most recent winner of the FIFA World Cup. To bring this vision closer to reality, the RoboCup Federation has announced several changes to the leagues. We spoke with Alessandra Rossi, a trustee who has been involved in the humanoid soccer league for many years, to learn more.

Could you start by introducing yourself and tell us how you’ve been involved in RoboCup throughout the years, because you’ve been involved in so many aspects of the competition!

I am Alessandra Rossi from the University of Naples “Federico II”, where I am an Assistant Professor of Computer Science. I began working with and collaborating in RoboCup in 2016, when I started my PhD at the University of Hertfordshire in the UK. I am still affiliated with the University of Hertfordshire, as I remain a member of the humanoid KidSize team Bold Hearts, the longest continuously active team in the UK. After a few years, I became the team leader of Bold Hearts.

In 2019, I became a member of both the Technical Committee and the Organizing Committee of the Humanoid League. After serving on the Technical Committee for two years, I was elected to the Executive Committee of the Humanoid League. In 2025, I was elected to the Board of Trustees for the first time.

Over the years, I have steadily increased my involvement and commitment to RoboCup. I have always sought to actively engage the RoboCup community, both during competitions and outside of competition periods. I also work to encourage engagement between the major and junior leagues and to participate in regional RoboCup events.

While working at the University of Hertfordshire as a Visiting Lecturer, we launched an online module that uses RoboCup as a benchmark for teaching robotics to undergraduate students. The module is still running. I initially served as the module leader, and this role has since been taken over by our Bold Hearts teammate, Bente Riegler.

Last year, Maike Paetzel-Prüsmann, Merel Keijsers, and I (as lead authors), in collaboration with several trustees and many members from different leagues, published a paper on the current and future challenges in humanoid robotics. The paper was published in Autonomous Robots and is, to the best of my knowledge, the first to involve such a large and diverse group of contributors from across the RoboCup leagues. It discusses research within RoboCup and the collaboration and synergies between the leagues.

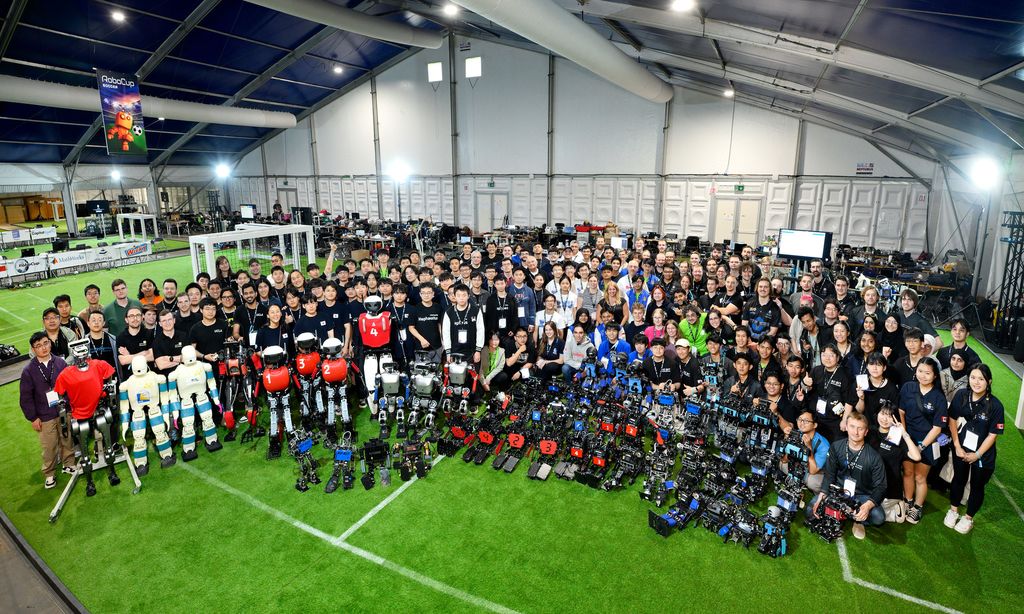
Group photo of the humanoid league teams at RoboCup 2025.
I understand that there are some changes planned for the leagues. Could say something about that, and specifically the changes that affect the soccer and the humanoid side.

The 2050 goal of the RoboCup Federation, as many people are probably aware, is for a team of humanoid robots to play against the winners of the FIFA World Cup. To achieve this, it is necessary to push further in that direction. One of the key changes, therefore, will be a stronger focus on humanoid robots.

Another major change will be the merger of the Standard Platform League (SPL) and the KidSize Humanoid League. This merged league will have the freedom to define its exact format and to develop a new roadmap that aligns the entire league toward a shared objective. While the 2050 goal itself remains unchanged, the path toward achieving it will need to be adjusted.

It is crucial to continue fostering the engagement of teams in the leagues that will be affected by these changes. At the same time, we must recognize that technology is advancing rapidly. Over the past year, in particular, we have seen significant progress in both hardware platforms and large language models. As RoboCup serves as a global benchmark for robotics research, we should continuously strive to advance technology and research—while still having fun.

Soccer is the complex task and behavior we are studying, and it is complex in many dimensions: from physical control and robot motion, to communication and strategy, and even human-like interactions. These include responding to the referee’s whistle, verbal and non-verbal communication among team members, interactions with the coach, and communication with the referee. All of these aspects will ultimately need to be incorporated into the humanoid league.

The RoboCup Federation has agreed some new partnerships with Unitree, Fourier and Booster. What impact will this have on the humanoid league? Will there be a standard platform element with teams using a specific humanoid robot?

I believe we will see a mix of different robots. With the three companies currently sponsoring RoboCup, we have already seen that their robots can achieve a wide range of behaviors, and there have been significant improvements in robot control. Some of these robots can walk very quickly—almost to the point of running.

Initially, there may be the possibility of multiple teams using the same platform. However, we must keep in mind that both hardware and software can become obsolete very quickly, so we need to remain open to multiple options. A robot that is state of the art today may no longer be so in a year or two. As a result, committing to a single standard platform could limit future progress.

For this reason, the current idea is to remain open to multiple platforms. Many teams already have excellent custom-built robots, and further improvements to these platforms should be encouraged. That said, the exact structure has not yet been decided, and these decisions will be made in consultation with the teams. It is important to give the RoboCup community the time it needs to adapt and move forward.

There have been some big advances in the humanoid adult-size league in the past couple of years. What improvements stood out to you at RoboCup2025 in Brazil?

One major change is that we have added extra robots to each team. Previously, teams played with just two robots per side, but matches are now played three versus three.

Another important improvement is the reduced presence of humans on the field. There is no longer a handler assigned to each robot. In the past, a team member had to walk behind the robots in case they fell and risked being damaged.

I have actually played in a match against the winning humanoid team. Naturally, the human team won, but it was an enjoyable and very interesting game, as the robots were surprisingly fast.


Action from the human vs humanoid match at RoboCup 2025.


Further action from the human vs humanoid match at RoboCup 2025.

What has been the general reaction from the RoboCup community to the changes? I guess it depends on which league you’re in as to how much it affects you.

Yes, it depends on which league you are part of. The reactions have been a mix of excitement and passion. Of course, everyone is keen to see improvements, and participants have always been prepared for changes to the rules and the league structures. However, there are still some open questions, and teams are waiting to see how things will evolve. Tomorrow, there will be a meeting with the President and several trustees to address questions raised by the leagues.

The overall direction of RoboCup, guided by the 2050 goal has not changed. Each league has been extremely valuable and has contributed in different ways toward achieving that goal. RoboCup has also been immensely valuable for robotics research more broadly. Beyond being fun, the challenges involved in making robots play soccer are extraordinarily complex. The research and solutions developed within RoboCup can be applied to many other fields and applications.

About Alessandra Rossi

Alessandra is Assistant Professor at the University of Naples Federico II, Italy. Her PhD thesis was part of the Marie Sklodowska-Curie Research ETN SECURE project at the University of Hertfordshire (UK). Her research interests include Human–(Multi) Robot Interaction, social robotics, trust, XAI, multi-agent systems and user profiling. She is Project Manager and co-supervisor of the MSCA PERSEO (955778), TRAIL (101072488) and SWEET (101168792). She is also co-PI of the project ERROR (FA8655-23-1-7060), and part of several national and international projects. Alessandra is also trustee member of RoboCup Federation, and member of the Humanoid League team called Bold Hearts. She is Chair of the IEEE P3108™ “Study Design”, and a member of the “Appendix” groups, she is Program Chair of IEEE RO-MAN 2027, she has been Robotic Challenge Chair at ICSR 2025, Special Session Chair of IEEE RO-MAN 2024, Publicity Chair of IEEE RO-MAN 2022 and 2023, Organising Chair of the 26th RoboCup International Symposium 2023, and she is on the program committee of several international conferences on human–robot interaction and artificial intelligence.
RoboCup Logistics League: an interview with Alexander Ferrein, Till Hofmann and Wataru Uemura

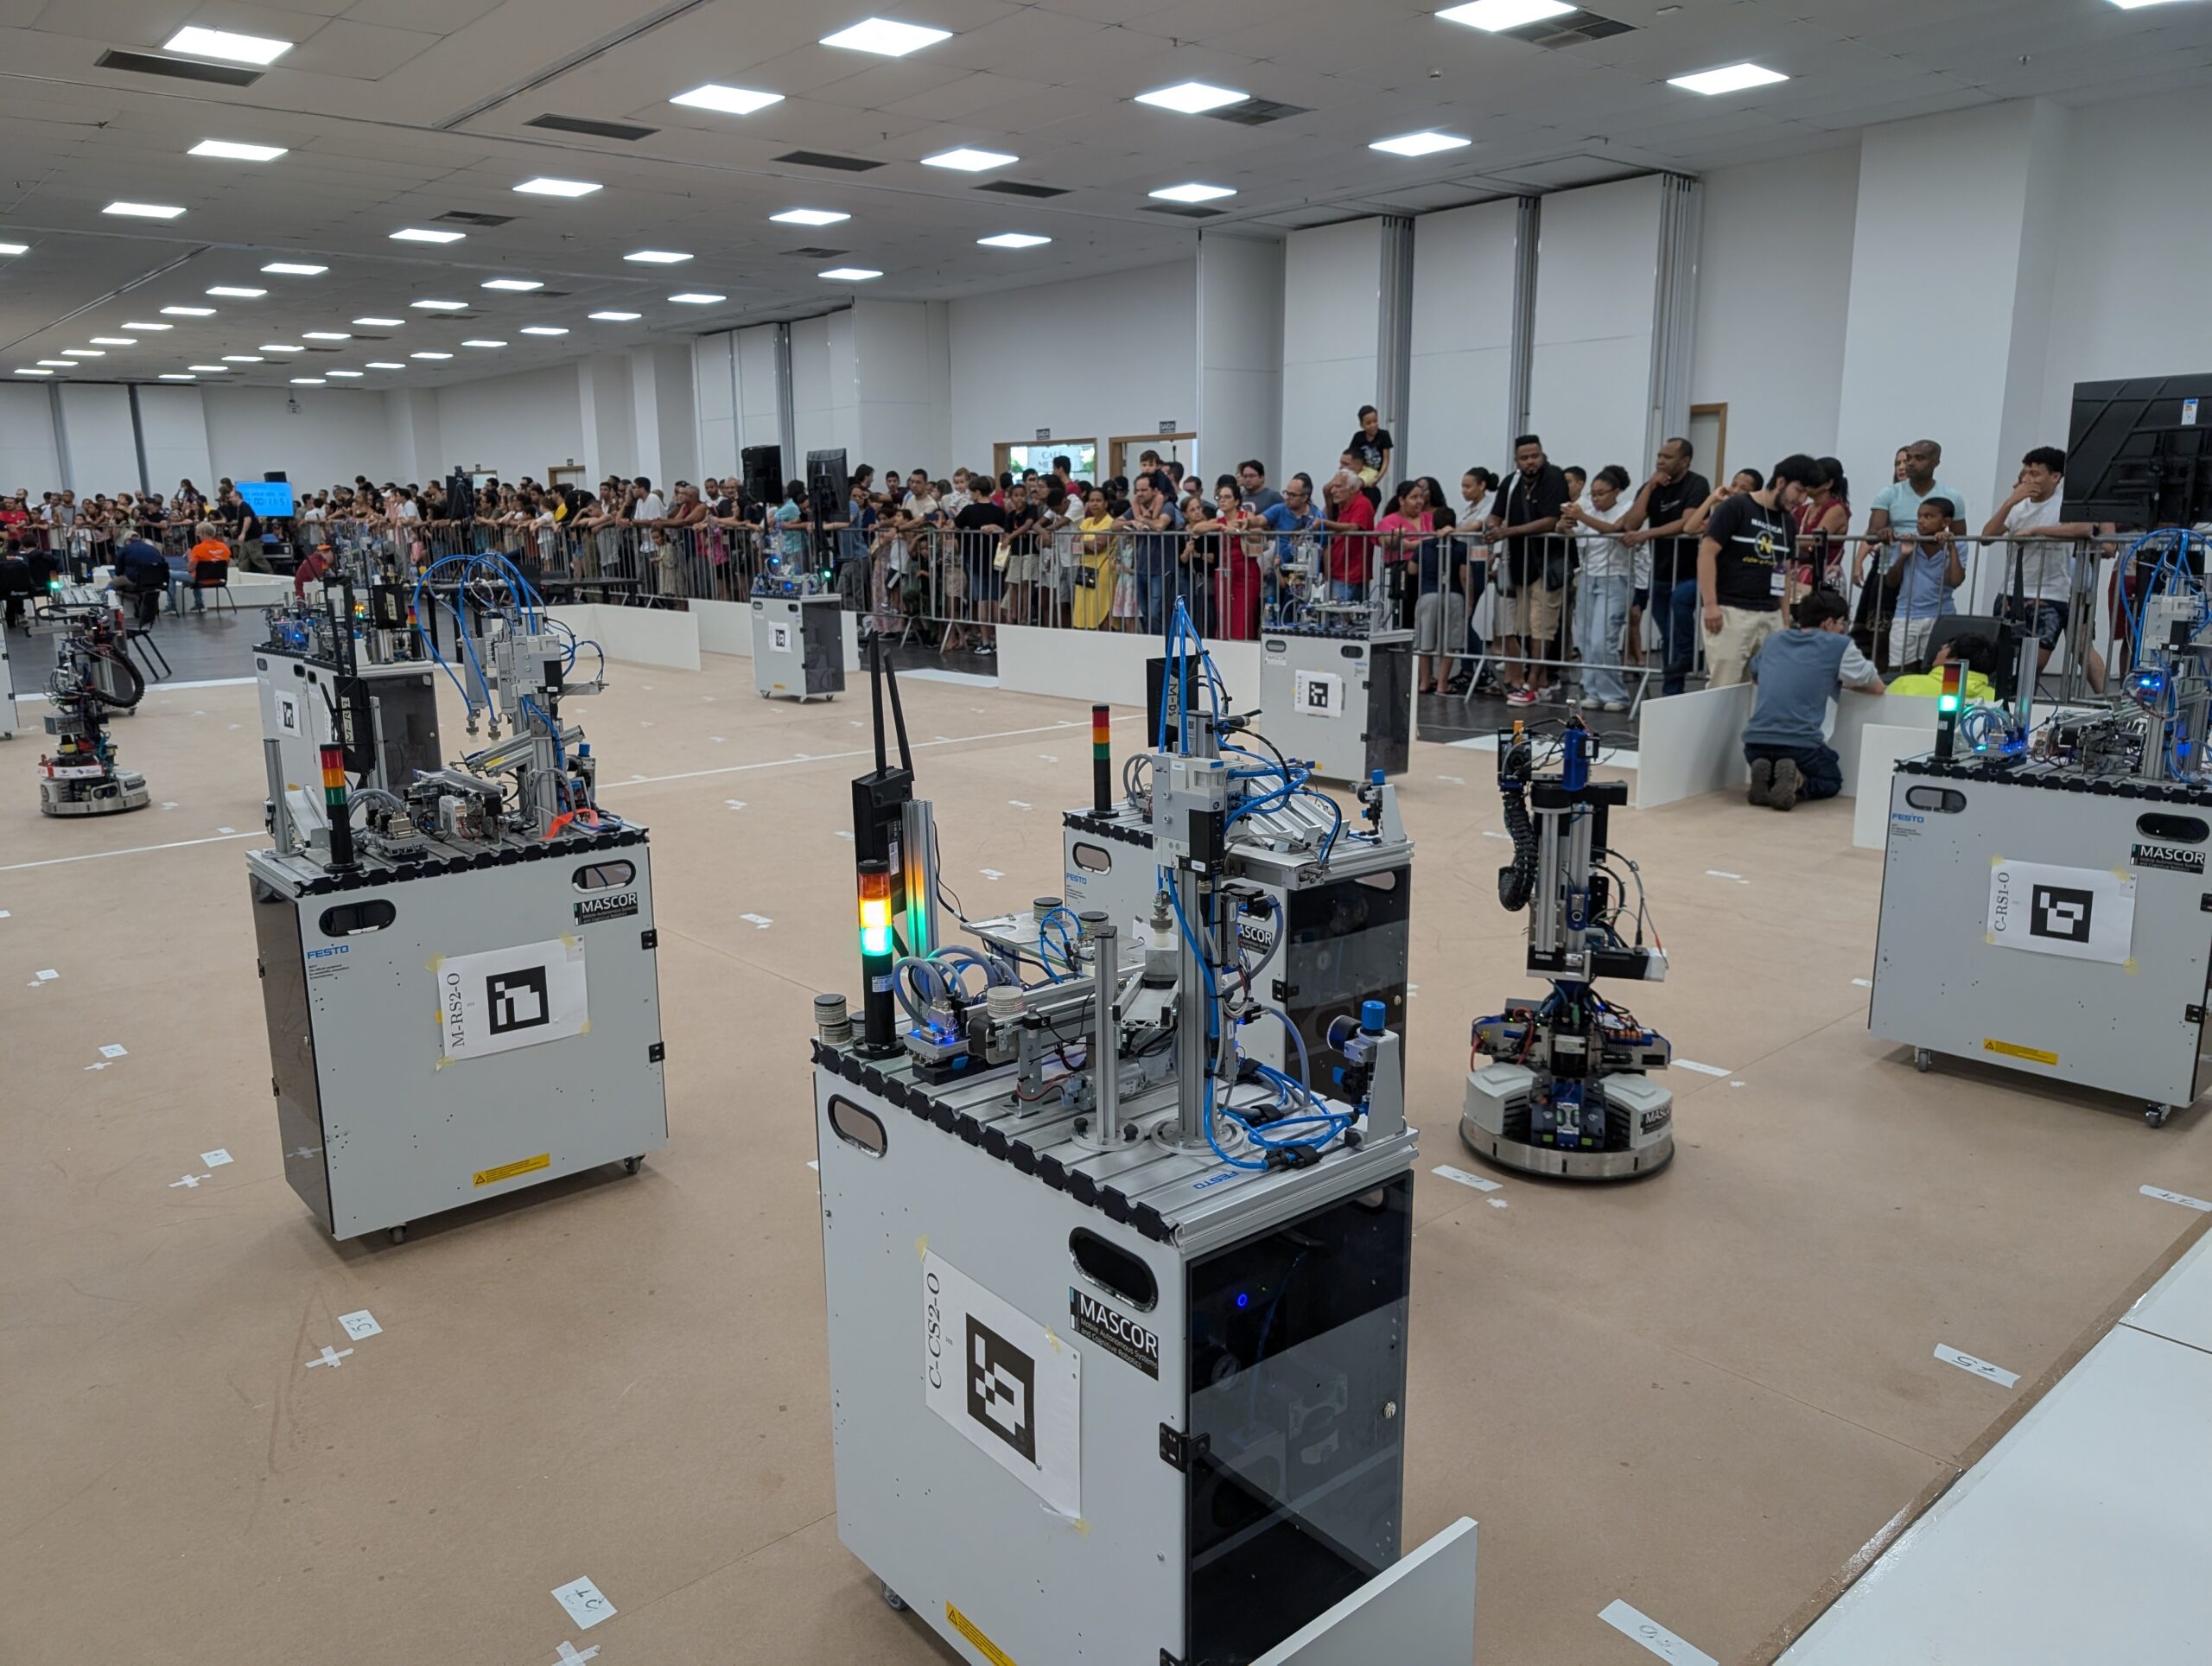
The Industrial League arena at RoboCup2025.
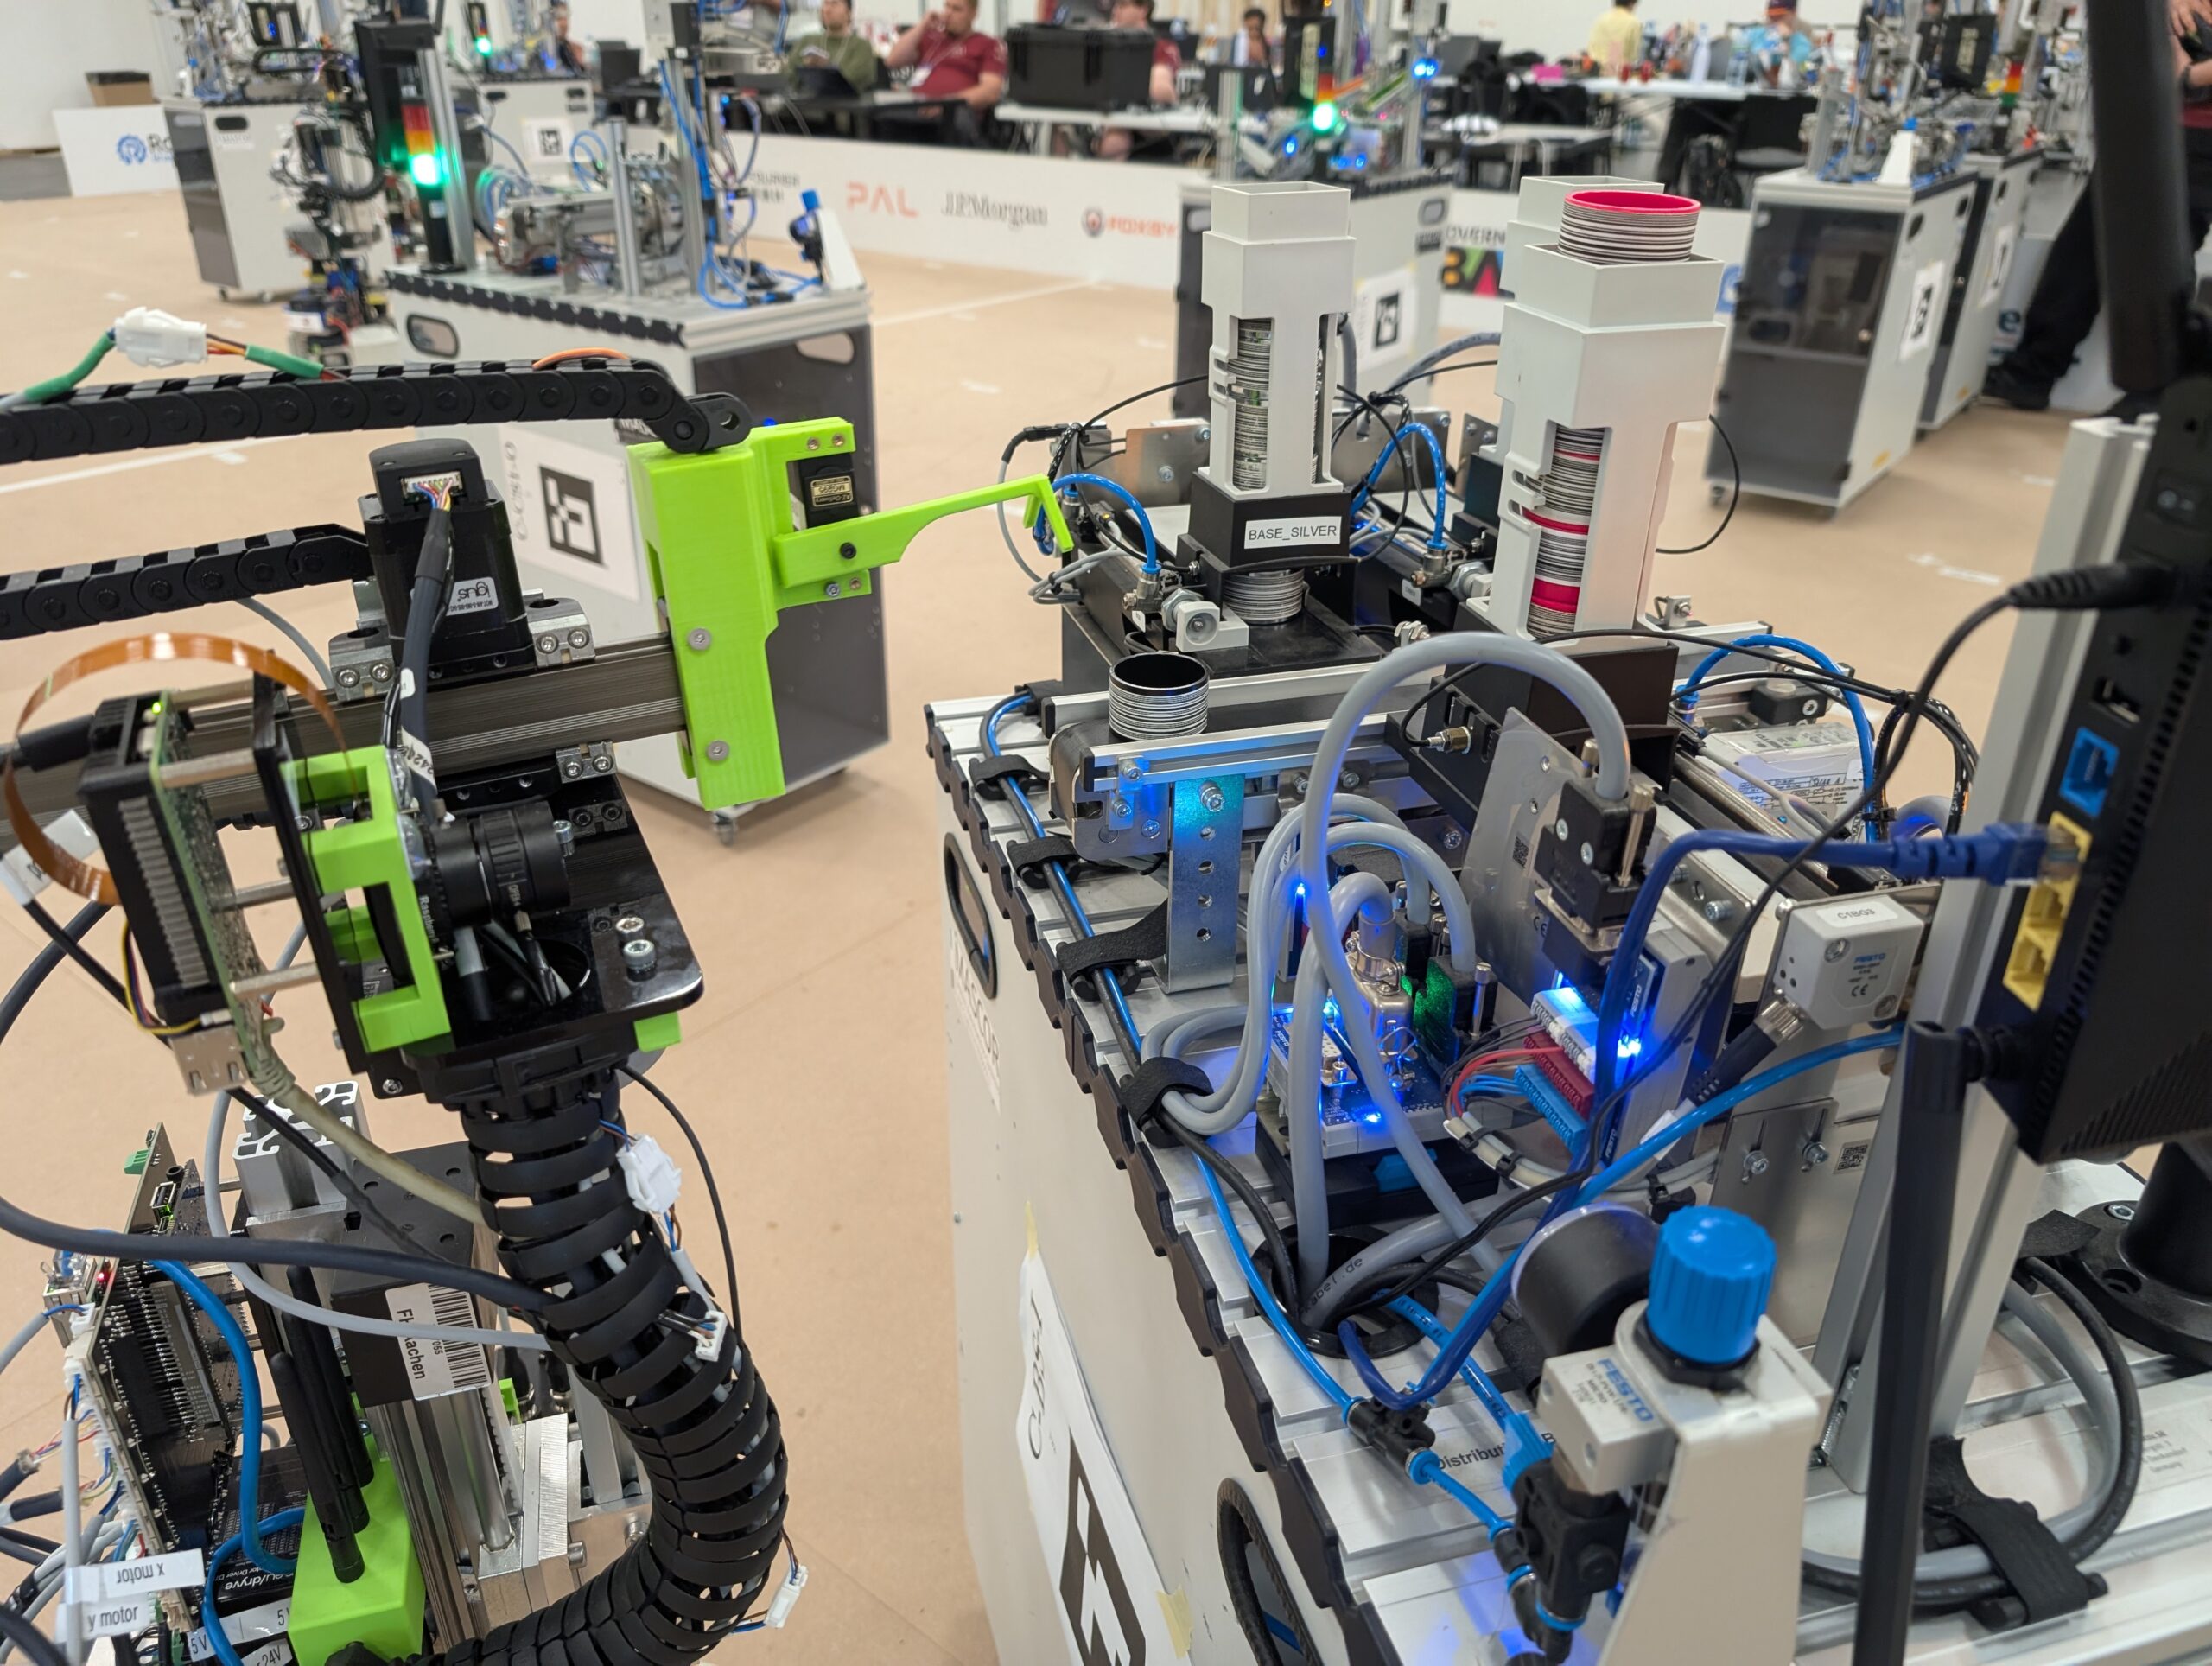
RoboCup is an international scientific initiative with the goal of advancing the state of the art of intelligent robots, AI and automation. The annual RoboCup event took place from 15-21 July in Salvador, Brazil. The Logistics League forms part of the Industrial League and is an application-driven league inspired by the industrial scenario of a smart factory. Ahead of the Brazil meeting, we spoke with three key members of the league to find out more. Alexander Ferrein is a RoboCup Trustee overseeing the Industrial League, and Till Hofmann and Wataru Uemura are Logistics League Executive Committee members.

Could you start by giving us an introduction to the Logistics League?

Alexander Ferrein: The idea of the Logistics League is to have robots helping in intra-production logistics. The playing field is set up with different machines and the robots need to bring raw materials and products to the machines and pick products up from them. There are orders coming in for different products of different complexities. The idea is that the robots deliver these products after they have been machined, at a certain handover point, and then the team will be awarded points. The setup is that we have six machines per team, and three robots operating in the smart factory.

There are two teams competing at the same time on different sides of the field. Most of the machines are on the home side of the field, but some machines are also on the opponent’s side of the field. The teams need to show basic robotics skills like navigation skills and collision avoidance. For the production of products we have little discs that have different colours and can be stacked on top of each other, and they have different caps. We have around 550 different items that can be produced. We don’t focus so much on the handling of the parts, therefore the manipulating mechanisms are quite simple and are usually custom built by the teams. They just need to grab these discs and drive them around and put them on conveyor belts on the machines.

The main focus is on the production logistics and the planning phase. The complex products need to be produced or machined by a team of robots – without this planning and team work it wouldn’t be possible to deliver the products within the allotted time in the competition.

Until now, we had been supported by Festo didactics, who supplied the machines. However, they pulled out in February and told us that they won’t support us in bringing the machines to Brazil. Our team in Aachen has a complete field set up, so we are in the (not so easy) process of packing the machines up in pallets and shipping them to Brazil.

Till Hofmann: One important detail is that all the products that need to be manufactured, the orders for those come online, and the number of possible products is very high. Therefore, you can’t do any planning in advance – you can’t just create a big database that contains one sequence that you execute for every possible product, that doesn’t really work. So the robots need to do online planning. Due to the fact that we have multiple robots in the team and then also the opponents teams’ robots on the field, many things go differently than planned, so a very big aspect of the competition is execution monitoring and online replanning. Basically you create an initial plan, but you need to constantly adapt that plan to what actually happens during execution. I just want to stress that in contrast to other RoboCup competitions, it’s really a long-horizon planning task in the sense that we usually need to do actions on a time horizon of five to ten minutes to actually get to an intermediate goal of producing one of those products.

Wataru Uemura: The focus of our league is on how to handle the production line. The three mobile robots are a very important part. At first these were autonomous guided robots, but now they are completely autonomous mobile robots. The robots need to decide on their path to make the product.

Could you talk about some of the challenges the teams face in the league, and is there a challenge or aspect of the competition that the teams have found particularly difficult?

Alexander: First of all, one needs to say that it is a really tough problem that we are facing here. So the teams that are starting new, they have to deal with all of the robotic aspects, so mobile robots, autonomous intelligence systems, they need to drive around, map, interact with the machines. As these items that we are pushing around are non-standard things, they also need to build their own manipulating devices. And then there is this massive planning aspect of the league, which is also not so easy. When we started this in 2011, 2012, we were thinking that this must be a solved problem, that one could use scheduling systems, that production is digital, and that everything would be easy. However, we found out it’s not actually easy, and there are no off-the-shelf solutions for a fleet of robots doing planning and production.

Looking at our team (which has become particularly successful over the years) and from observing the other teams as a trustee, I think that the integration aspect of all the different tasks is really a hard thing. Having a software system that is capable of so many things, communicating with the centralized referee box, and making it run within the time limit of a match, is the major challenge. Today, navigation of a robot is not the big issue, basically, but getting it integrated into your software system and building all the rest around the planning components and so on, this is, from my point of view, the major challenge.

Till: As I mentioned, I think the combination of long-horizon planning and execution monitoring is particularly difficult. We do have a lot of failures during one production run, because of hardware limitations and problems with the robots. Sometimes the machines themselves fail and they need to deal with this, without being able to solve the problem itself, because it’s not in their control. So they need to do a lot of reasoning that considers all the different cases that may happen. For example, suddenly you have a product appearing in a machine and you no longer know the configuration because this information was lost on the way. How do you deal with this? Another example is that the robot drops a piece while it is driving around and then tries to feed it into the machine. Then the machine reports a failure and the team needs to keep its world model up-to-date to know that this product is no longer where they thought it was. How do we deal with this?

Will there be any new challenges introduced for RoboCup 2025?

Alexander: Because the problem we are trying to solve is so hard, we don’t have many teams in the league. We had a new team at RoboCup2023, in Bordeaux, and they are now consistently coming to the RoboCups, which is nice. Apart from this, we have a core of three to five teams that participate in the league. As the challenge itself is hard to get into, the skills only develop slowly, so new challenges are not really introduced. There are slight changes here and there. One of the major changes in recent years was during Coronavirus times where we had to abandon the whole match aspect because we couldn’t play with two teams at the same time. We introduced aspects of the game as challenges. Now we have a challenge track as well, where teams can just focus on certain aspects of the league and do not need to play the full game.

The skills of the teams are not developing in such a way that we really need to add new challenges because it is still unsolved and hard for all the teams to get the robots running, because we have so many different aspects.

I understand that you are thinking about some changes to the league. Could you say more about this?

Alexander: Yes, we have some ideas for a new Industrial League. As Festo are pulling out we don’t see the need to stick with this particular machine type. We had a workshop earlier this year with all the teams and organising committees and we’re proposing a future challenge, or league. We will discuss this at RoboCup2025.

Till: We actually already had discussions with @work, and agreed that the long-term goal is to merge the two competitions into one big Industrial League. Next year, we will start converging by doing some kind of collaboration challenge or crossover challenge where teams from @work will collaborate with what’s now the Logistics League, but will be the Smart Manufacturing League by that time. Then hopefully, in two or three years, this will be one big league rather than separate industrial competitions. And the idea of the league that we’re currently planning to migrate to is really a broader smart manufacturing scenario where we have different aspects of smart manufacturing. So currently it’s really only the production logistics part. But in the future, we also want to include the assembly itself as part of the competition and also extend this to humanoid robots and also focus on human-robot collaboration in this manufacturing setting.

So this will be very different to the Logistics League as it is right now. How we will do the migration from what we have to that new league without losing all the teams is something that’s still in the making.

Alexander: I also don’t think we shouldn’t restrict ourselves to just one type of robot. As we see, there is something going on with respect to humanoid robots, and the Rescue League is proposing a quadruped robot. In the @Home League there are ideas to introduce the staircases where you need more agility in these settings. So for me, I wouldn’t restrict the type of robots that we’re using. We are just thinking about proposing challenges that are looking towards the future. So far we have been doing things that we thought might be relevant to industry, but industry is not very interested in what we are doing here. At least, they are not knocking at our doors and asking what our solutions are. That’s also another aspect that we will possibly discuss at Robocup 2025 – how we could increase our impact as a league for the outside world.

So that’s one of the aims, I guess, to evolve in a way such that industry will be more interested?

Alexander: Yes, be relevant, right? I mean, you see so much going on, in particular in China with the robot manufacturing OEMs [original equipment manufacturers] that build these robots in a few years that have quite impressive capabilities. And well, we stand aside and just watch. So maybe we should use those robots, and integrate them into our process. It’s very important that we are opening our minds to envision a future that’s different from today.

About the interviewees

Alexander Ferrein received his MSc in Computer Science (Dipl.-Inform.) and his PhD (Dr. rer. nat) from Aachen University in 2001 and 2007, respectively. Between 2009-2011 he joined the Robotics and Agents Research Lab, University of Cape Town, as a postdoctoral research fellow with Feodor-Lynen scholarship granted by the Alexander-von-Humboldt Foundation. He then re-joined the Knowledge-Based Systems Group at Aachen University before he became a professor for Robotics and Computer Science at FH Aachen University of Applied Sciences. He is a heading the Mobile Autonomous Systems & Cognitive Robotics Institute at Aachen Applied Science University. His research focusses on the field of Artificial Intelligence and Cognitive Robotics. Since 2015 he is member of the Advisory Committee of the African-German Network of Excellence in Science whose Vice-president he was between 2019-2023. His research concentrates on the field of cognitive robotics. In particular, he is interested in high-level control and decision making of robots and agents acting under real-time constraints.

Till Hofmann is a Postdoc at RWTH Aachen University. His research focuses on planning, plan execution, generalized planning as well as reactive synthesis, with a particular focus on planning for robotics. He was a participant in the RoboCup Logistics League from 2016 until 2019 and member of the technical committee from 2017 until 2020. Since 2024, he is on the executive committee of the RCLL.

Wataru Uemura was born in 1977, and received B.E, M.E. and D.E. degrees from Osaka City University, in 2000, 2002, and 2005. He is an associate professor in Electronics, Information and Communication Engineering Course, Faculty of Advanced Science and Technology, Ryukoku University in Shiga, Japan. He is a member of IEEE, RoboCup and others. He is a chairperson of the RoboCup Japanese National Committee. He is an executive committee member of RoboCup Logistics League. He was a member of the Industrial Robotics Competition Committee, the World Robot Summit. He was TPC Vice Chairs of GCCE 2012, Conference Chair of GCCE 2016, and Publication Chairs of GCCE (Global Conference on Consumer Electronics). He is a member of the World Skills in Japan organizing committee of Autonomous Mobile Robots.

Call for AAAI educational AI videos


The Association for the Advancement of Artificial Intelligence (AAAI) is calling for submissions to a competition for educational AI videos for general audiences. These videos must be two to three minutes in length and should aim to convey informative, accurate, and timely information about AI research and applications.

The video could highlight your own research, that of another researcher or group, introduce viewers to an AI topic, or include interviews with AI researchers. Any theme is welcome, but videos covering the following are particularly encouraged: large language models, AI and ethics, societal impact of AI, and risks of deployed AI.

The videos will be assessed in terms of their content, understandability, relevance to AI, entertainment value, and presentation quality.

To give you a flavour of what these videos could look like, click here to see the winners of the previous iteration of the competition.

The deadline for submissions is 30 November 2025. To submit, you must upload your video to a publicly accessible website, and fill in the submission form.

You can find out more here.

#ICML2025 outstanding position paper: Interview with Jaeho Kim on addressing the problems with conference reviewing

At this year’s International Conference on Machine Learning (ICML2025), Jaeho Kim, Yunseok Lee and Seulki Lee won an outstanding position paper award for their work Position: The AI Conference Peer Review Crisis Demands Author Feedback and Reviewer Rewards. We hear from Jaeho about the problems they were trying to address, and their proposed author feedback mechanism and reviewer reward system.

Could you say something about the problem that you address in your position paper?

Our position paper addresses the problems plaguing current AI conference peer review systems, while also raising questions about the future direction of peer review.

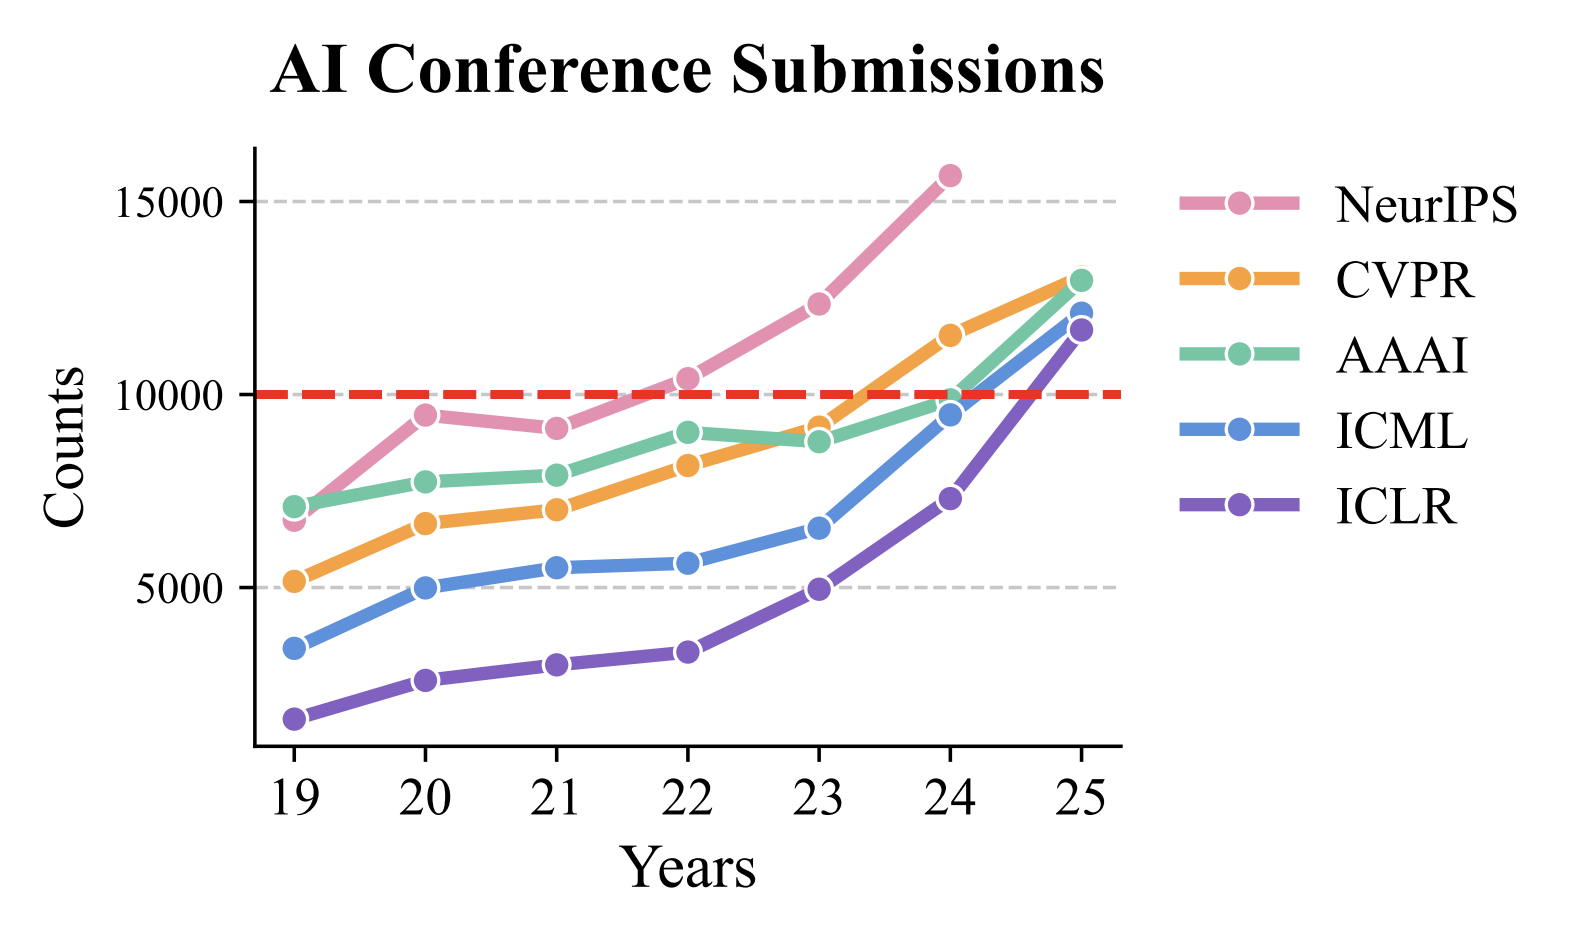
The imminent problem with the current peer review system in AI conferences is the exponential growth in paper submissions driven by increasing interest in AI. To put this with numbers, NeurIPS received over 30,000 submissions this year, while ICLR saw a 59.8% increase in submissions in just one year. This huge increase in submissions has created a fundamental mismatch: while paper submissions grow exponentially, the pool of qualified reviewers has not kept pace.

Submissions to some of the major AI conferences over the past few years.
This imbalance has severe consequences. The majority of papers are no longer receiving adequate review quality, undermining peer review’s essential function as a gatekeeper of scientific knowledge. When the review process fails, inappropriate papers and flawed research can slip through, potentially polluting the scientific record.

Considering AI’s profound societal impact, this breakdown in quality control poses risks that extend far beyond academia. Poor research that enters the scientific discourse can mislead future work, influence policy decisions, and ultimately hinder genuine knowledge advancement. Our position paper focuses on this critical question and proposes methods on how we can enhance the quality of review, thus leading to better dissemination of knowledge.

What do you argue for in the position paper?

Our position paper proposes two major changes to tackle the current peer review crisis: an author feedback mechanism and a reviewer reward system.

First, the author feedback system enables authors to formally evaluate the quality of reviews they receive. This system allows authors to assess reviewers’ comprehension of their work, identify potential signs of LLM-generated content, and establish basic safeguards against unfair, biased, or superficial reviews. Importantly, this isn’t about penalizing reviewers, but rather creating minimal accountability to protect authors from the small minority of reviewers who may not meet professional standards.

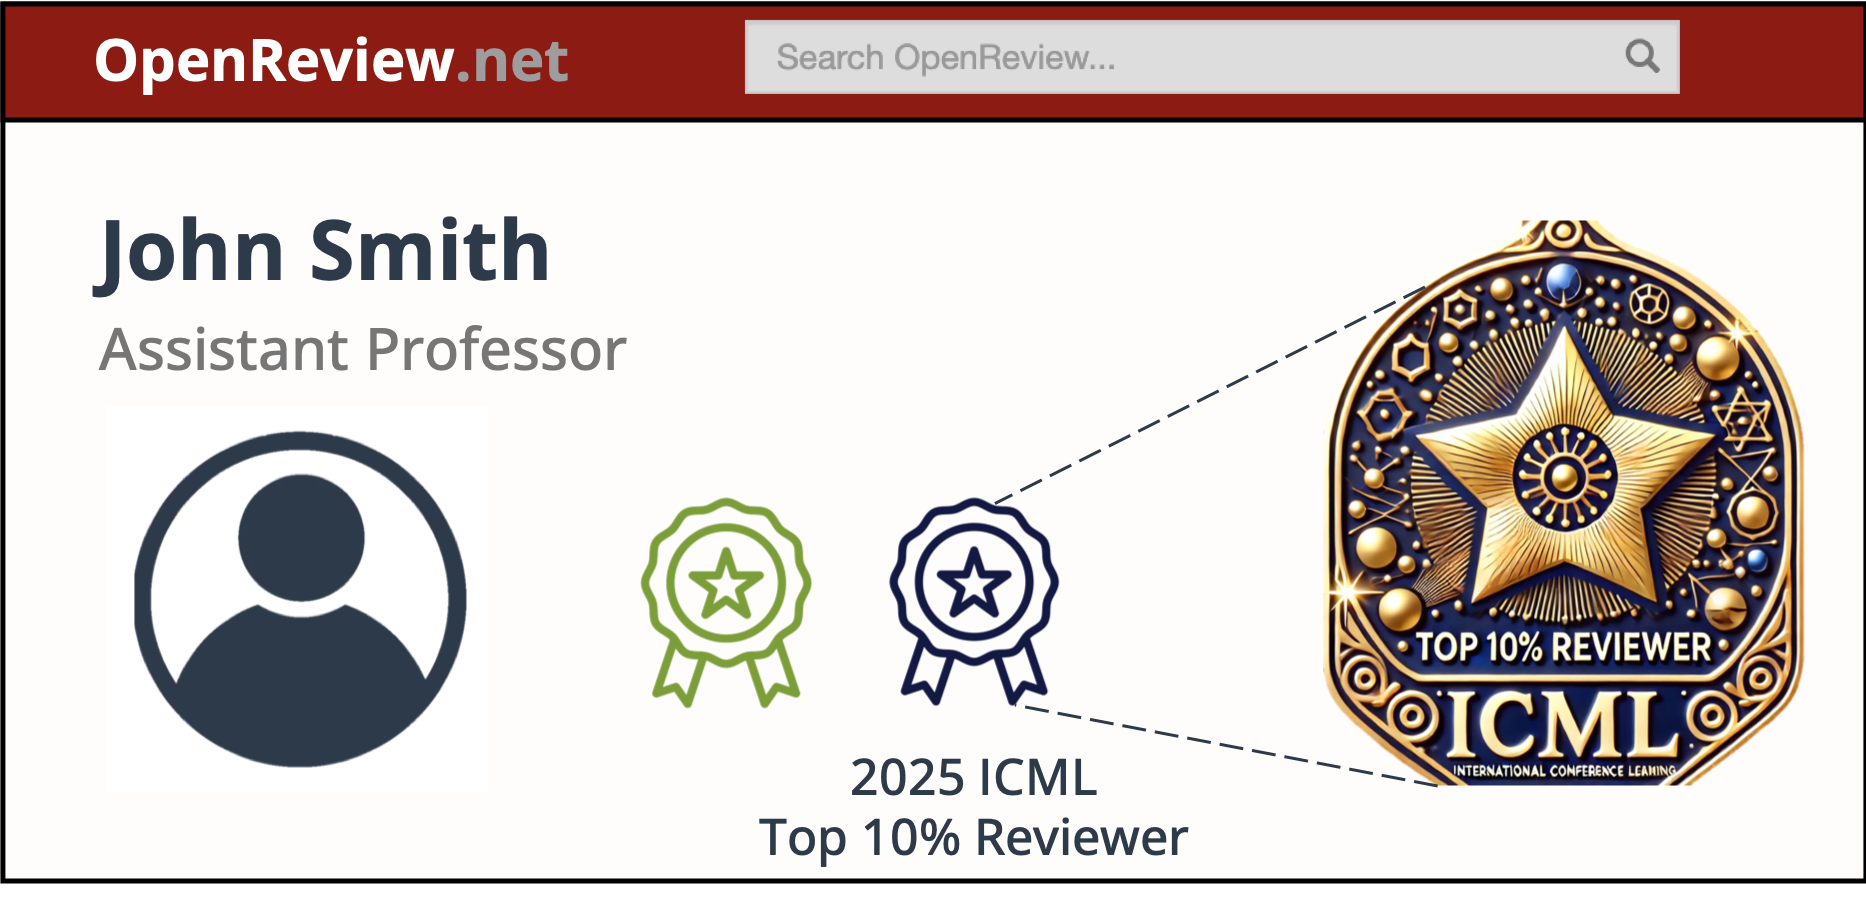
Second, our reviewer incentive system provides both immediate and long-term professional value for quality reviewing. For short-term motivation, author evaluation scores determine eligibility for digital badges (such as “Top 10% Reviewer” recognition) that can be displayed on academic profiles like OpenReview and Google Scholar. For long-term career impact, we propose novel metrics like a “reviewer impact score” – essentially an h-index calculated from the subsequent citations of papers a reviewer has evaluated. This treats reviewers as contributors to the papers they help improve and validates their role in advancing scientific knowledge.

Could you tell us more about your proposal for this new two-way peer review method?

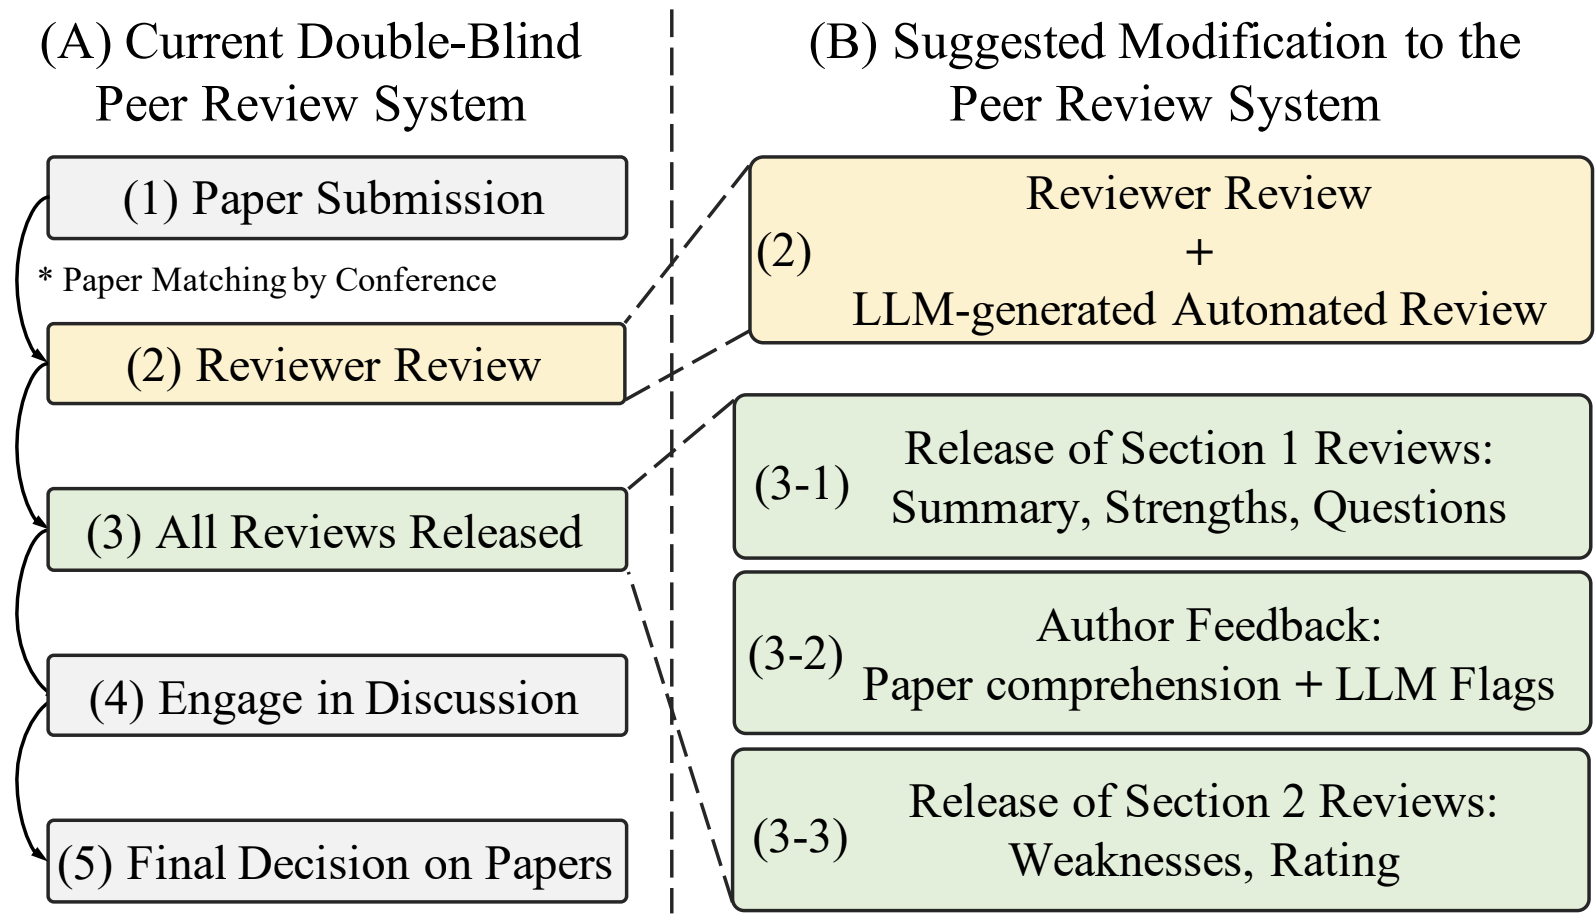
Our proposed two-way peer review system makes one key change to the current process: we split review release into two phases.

The authors’ proposed modification to the peer-review system.
Currently, authors submit papers, reviewers write complete reviews, and all reviews are released at once. In our system, authors first receive only the neutral sections – the summary, strengths, and questions about their paper. Authors then provide feedback on whether reviewers properly understood their work. Only after this feedback do we release the second part containing weaknesses and ratings.

This approach offers three main benefits. First, it’s practical – we don’t need to change existing timelines or review templates. The second phase can be released immediately after the authors give feedback. Second, it protects authors from irresponsible reviews since reviewers know their work will be evaluated. Third, since reviewers typically review multiple papers, we can track their feedback scores to help area chairs identify (ir)responsible reviewers.

The key insight is that authors know their own work best and can quickly spot when a reviewer hasn’t properly engaged with their paper.

Could you talk about the concrete reward system that you suggest in the paper?

We propose both short-term and long-term rewards to address reviewer motivation, which naturally declines over time despite starting enthusiastically.

Short-term: Digital badges displayed on reviewers’ academic profiles, awarded based on author feedback scores. The goal is making reviewer contributions more visible. While some conferences list top reviewers on their websites, these lists are hard to find. Our badges would be prominently displayed on profiles and could even be printed on conference name tags.
Example of a badge that could appear on profiles.

Long-term: Numerical metrics to quantify reviewer impact at AI conferences. We suggest tracking measures like an h-index for reviewed papers. These metrics could be included in academic portfolios, similar to how we currently track publication impact.

The core idea is creating tangible career benefits for reviewers while establishing peer review as a professional academic service that rewards both authors and reviewers.

What do you think could be some of the pros and cons of implementing this system?

The benefits of our system are threefold. First, it is a very practical solution. Our approach doesn’t change current review schedules or review burdens, making it easy to incorporate into existing systems. Second, it encourages reviewers to act more responsibly, knowing their work will be evaluated. We emphasize that most reviewers already act professionally – however, even a small number of irresponsible reviewers can seriously damage the peer review system. Third, with sufficient scale, author feedback scores will make conferences more sustainable. Area chairs will have better information about reviewer quality, enabling them to make more informed decisions about paper acceptance.

However, there is strong potential for gaming by reviewers. Reviewers might optimize for rewards by giving overly positive reviews. Measures to counteract these problems are definitely needed. We are currently exploring solutions to address this issue.

Are there any concluding thoughts you’d like to add about the potential future
of conferences and peer-review?

One emerging trend we’ve observed is the increasing discussion of LLMs in peer review. While we believe current LLMs have several weaknesses (e.g., prompt injection, shallow reviews), we also think they will eventually surpass humans. When that happens, we will face a fundamental dilemma: if LLMs provide better reviews, why should humans be reviewing? Just as the rapid rise of LLMs caught us unprepared and created chaos, we cannot afford a repeat. We should start preparing for this question as soon as possible.

About Jaeho

Jaeho Kim is a Postdoctoral Researcher at Korea University with Professor Changhee Lee. He received his Ph.D. from UNIST under the supervision of Professor Seulki Lee. His main research focuses on time series learning, particularly developing foundation models that generate synthetic and human-guided time series data to reduce computational and data costs. He also contributes to improving the peer review process at major AI conferences, with his work recognized by the ICML 2025 Outstanding Position Paper Award.

Read the work in full

Position: The AI Conference Peer Review Crisis Demands Author Feedback and Reviewer Rewards, Jaeho Kim, Yunseok Lee, Seulki Lee.

RoboCup@Work League: Interview with Christoph Steup

RoboCup@Work League teams at the event in Brazil.
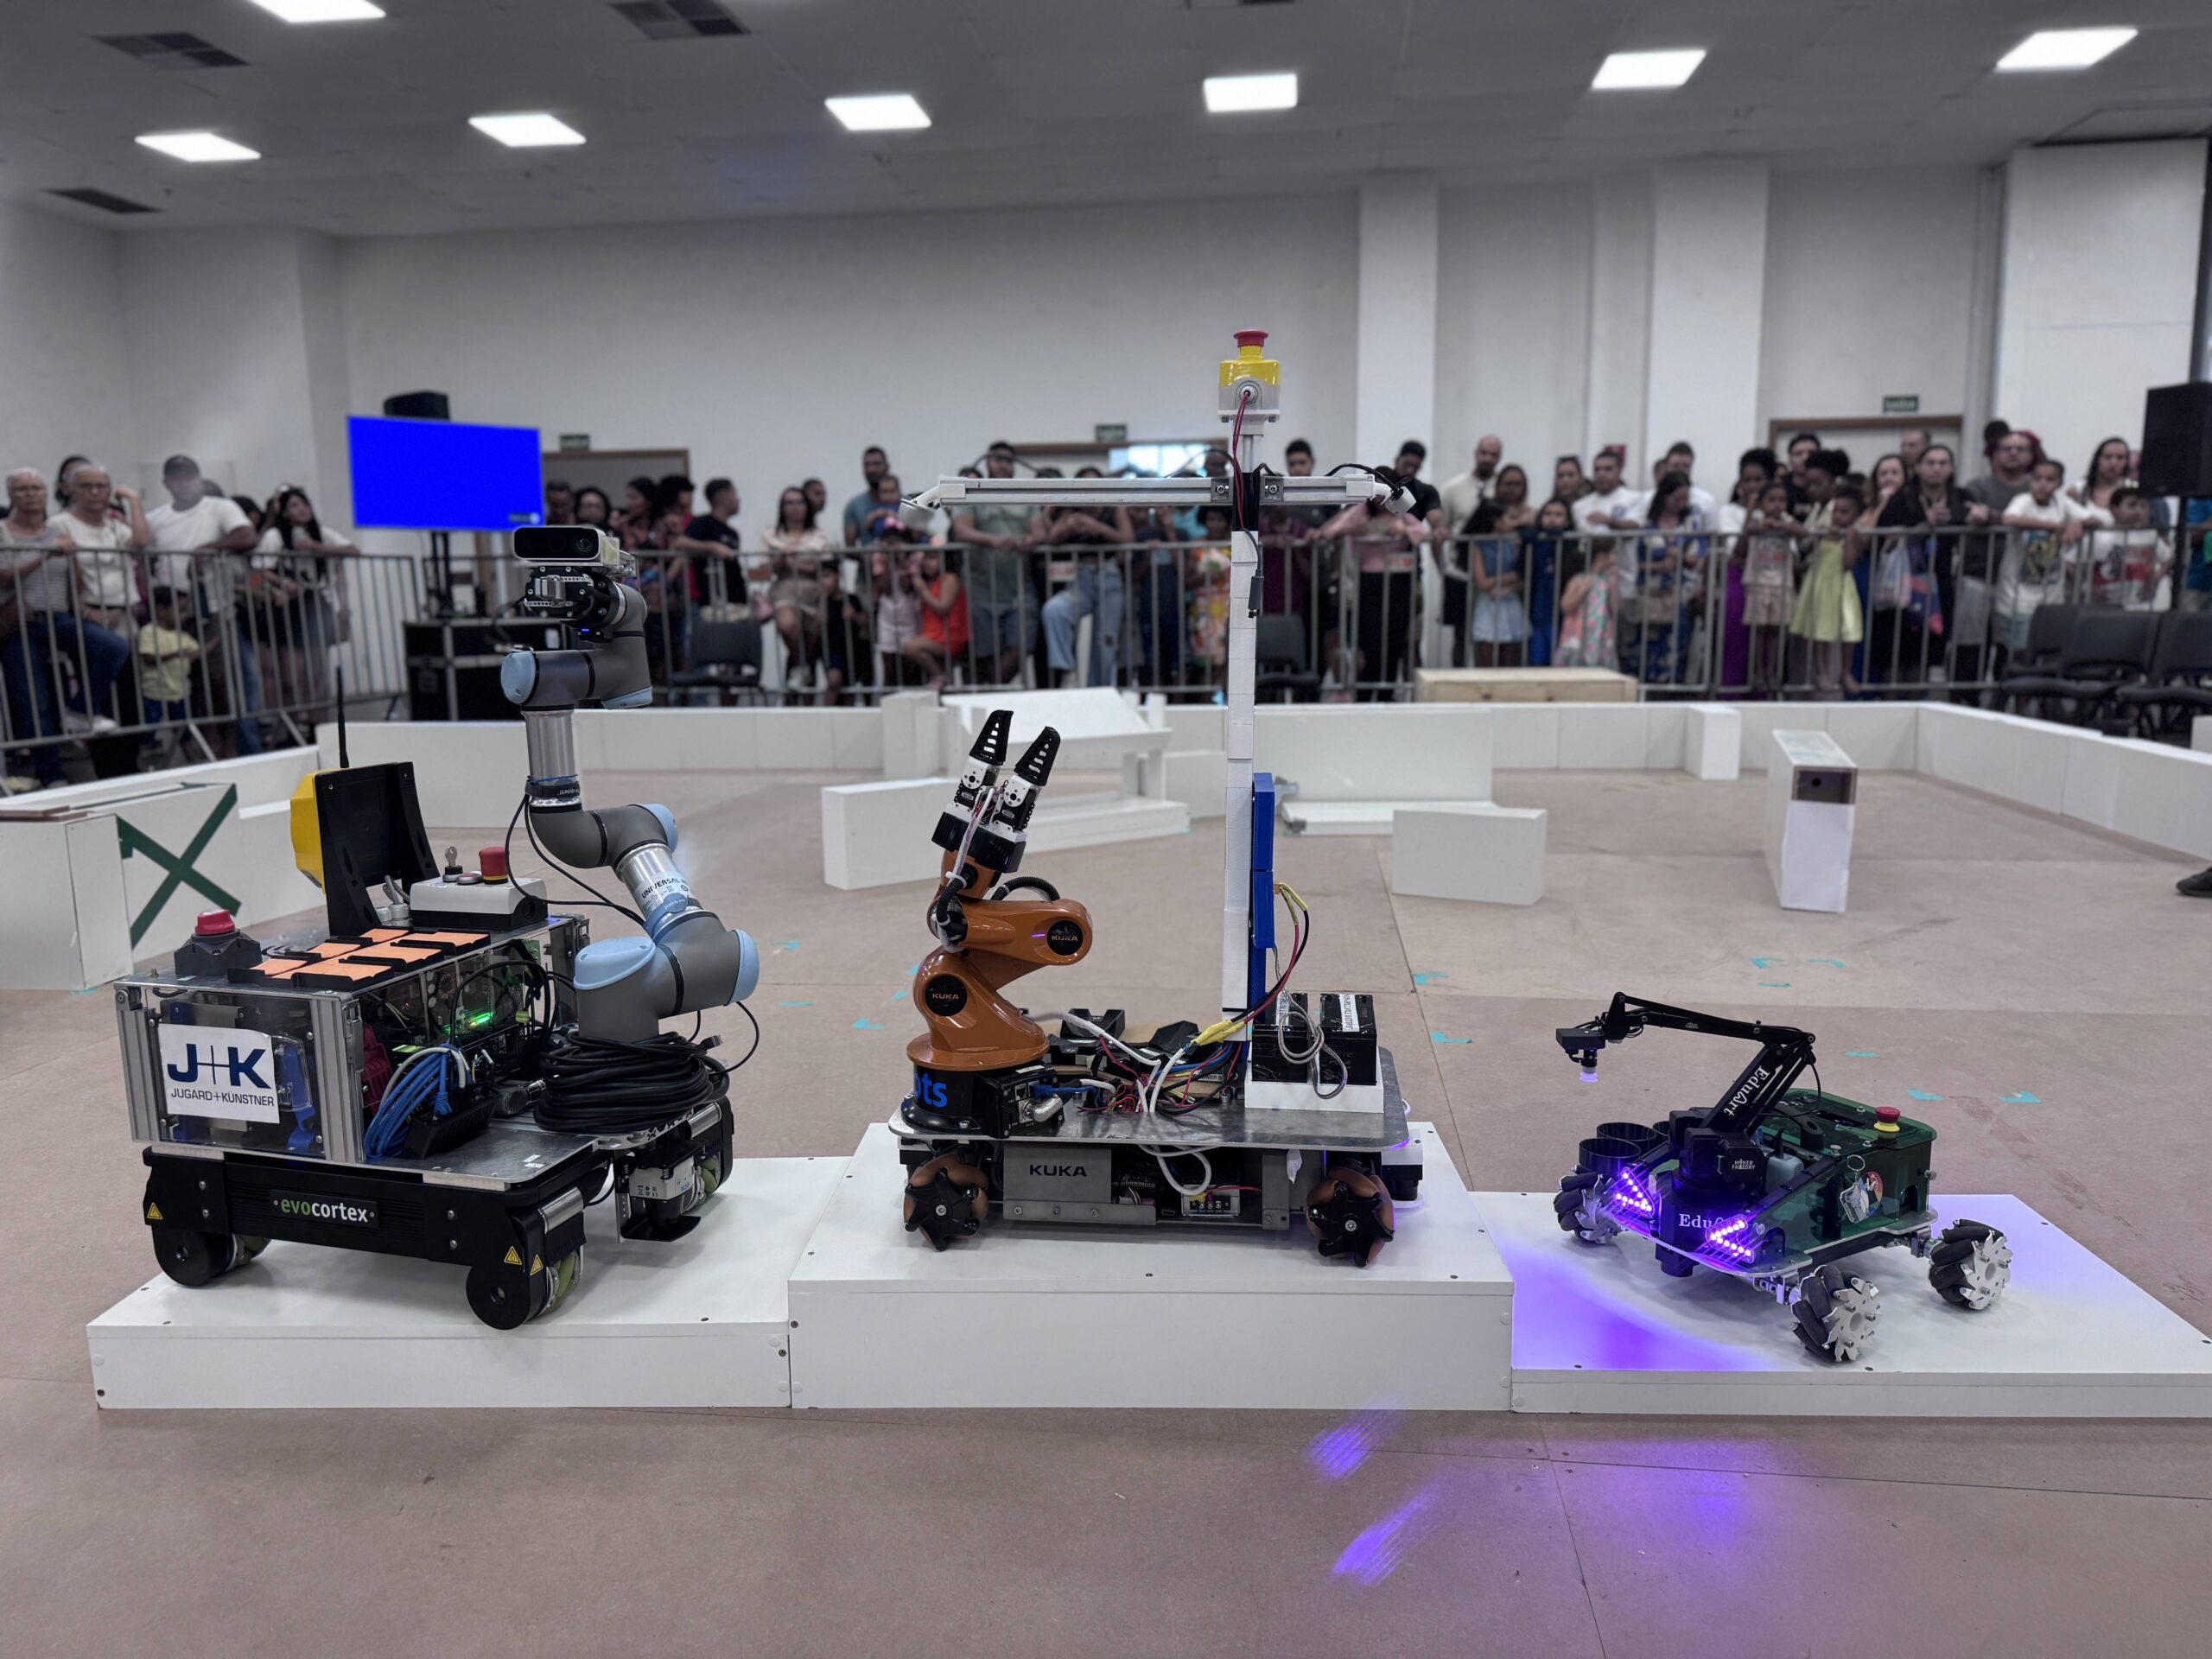
RoboCup is an international scientific initiative with the goal of advancing the state of the art of intelligent robots, AI and automation. The annual RoboCup event, where teams gather from across the globe to take part in competitions across a number of leagues, this year took place in Salvador, Brazil from 15-21 July. In a series of interviews, we’ve been meeting some of the RoboCup trustees, committee members, and participants, to find out more about their respective leagues. Christoph Steup is an Executive Committee member and oversees the @Work League. Ahead of the event in Brazil, we spoke to Christoph to find out more about the @Work League, the tasks that teams need to complete, and future plans for the League.

Could you start by giving us an introduction to the @Work league?

The @Work League, along with the Logistics League, forms the Industrial League. Our goal is to mimic some of the aspects of industrial production systems. An important aspect of this is factory automization and trying to mimic the factory of the future, where you have autonomous robots building products according to customer design. In these factories of the future, a single piece would be produced individually for each customer. Factories nowadays have big conveyor belts and a lot of automization, with the tasks mostly done in the same way, and you can only build stuff efficiently if you build millions of items. We are working on building individual pieces, where automization is still possible, and even a single piece can be built effectively. But obviously, in our RoboCup competitions, we are not interested in building on a factory scale – we are doing it on a very small scale. That means our robots are typically 80 centimeters long, the largest are around 70 centimeters wide, and some of them are also 80 centimeters high. So let’s say they fit in a one metre cubed box. Also, all our operations are done on the ground. This is just for simplification because building big tables to make it more realistic would also increase the cost for RoboCup and wouldn’t give much additional value.

What our robots need to do is transport objects from different workstations. So we have a default configuration where the arena starts, and there are workstations with objects lying on them, and some of these objects need to be transported to other workstations. The robot needs to do that completely autonomously. So this is one of the special things about the @Work League, that it’s completely autonomous and there is only a single restart allowed per team. So that means the robot really needs to be reliable. One of the big differences between medium teams and very good teams is that the very good teams perform well all the time whereas the medium teams have some good runs and some bad runs.

As well as the object transportation that you mentioned, and there other tasks that the teams need to carry out?

There are some special tasks in our league, like the precision placement task where the robot needs to fit an object into a cavity that is essentially the same shape and size as the object. It’s a little bit like the game that babies do to train their dexterity.

We also have a task that is inspired by a conveyor belt, but we are using a table that is constantly turning. The robots need to grasp stuff while the table is turning. This looks a little bit silly because no one would actually put a rotating table in a factory, however this is our way of actually mimicking a conveyor belt. The conveyor belt itself would be really, really difficult to integrate into the competition, so we just abstracted that and use this rotating table to actually have the same challenge but in a more manageable way. And it’s still a very, very hard challenge.

Then there are some special challenges that we integrate. For example, that robots need to report their state back so that we can observe what the robot is doing. We also have a challenge where humans are in the loop. For example, the robot brings pieces to a certain workstation where a human is present, the human assembles the pieces, and then the human needs to give a sign to the robot, and then the robot will take the piece away and put it somewhere else. This is designed to really mimic the automated factory flow.

In the past we also had a challenge where the robots needed to open a drawer, take something out and then close the drawer again. We’ve also had tasks where the robot has to handle fragile objects, like sweets, where the robot really needed to be careful in manipulating them. So in general, what differentiates us most from the Logistics League is that we are focusing a lot on manipulation and all the difficulties that come with manipulation and unknown objects, whereas Logistics is more tailored towards large-scale logistics processes with all their optimization and planning.

I was lucky enough to attend RoboCup last year in Eindhoven and what the teams were doing was really impressive. It was also interesting to see how varied the robots were, and how teams were approaching the tasks in distinct ways, with different grabbers and so on.

Yes, this difference in approaches is related to the history of our League, which is a little bit similar to the Logistics League. The Logistics League was originally a sponsored demonstration by Festo, which is a large company from Germany that creates tools, but they also have a didactics area where they provide tools to help people understand factory optimization. The @Work League was sponsored by Kuka, the robotics company, and, in the beginning, they required every team to compete with the Kuka youBot. So this was pretty much the default platform for our league, but at some point Kuka dropped from a sponsor to just an advisor to the league, and nowadays they are not part of the league at all. So when the Kuka youBot was going out of commission, the teams searched for alternatives and now we are presented with a wide variety of robots that are competing in the league, which I personally find really cool. Now we have all these different robots, all these different approaches, and some work better in some scenarios and worse in others. So we really have a scientific approach to the problem and we are really getting some insights into how you can tackle this problem on multiple levels.

Have you noticed that some of the challenges specifically are more difficult in general for all the teams?

In 2018 we introduced a challenge of so-called arbitrary surfaces which are surfaces unknown to the teams that are put on top of the workstations. The teams need to be able to deal with these surfaces. There are two surfaces that are really, really awful for the teams – one is grass that we pretty much stole from the soccer competitions! We just thought it would be funny to try it, and it was a really interesting problem, especially for some of the grippers of the different teams. For example, the current world champion, they have a rigid gripper so they can have force feedback when they grasp. However, the grass is really difficult for them – because of their rigidity, they always grasp the grass itself and then they pull up the grass with the object. And this led to some interesting problems, like they are transporting the actual surface around and not only the object. This isn’t a problem for teams using a flexible gripper. However, on the other hand, the flexible gripper makes it really difficult to assess if you have grasped the object because you have very bad force feedback. So there are two different approaches that have their pros and cons in different scenarios.

Three robots from the @Work competition in Brazil.
Are you introducing any new tasks for this year?

Yes and no. So actually we are introducing a completely new challenge which is different from what we’ve done before. The new challenge is the so-called smart farming challenge, which is opening our league to a whole new field of applications, because we are now looking at agriculture. We are working on this with Studica, a robotics company from Canada, whose hardware we are using. We’ve already given it a try at the German Open. This challenge comes with some new specifics and one these is that the teams only get the robot shortly before the competition. So they don’t really know the robot largely in advance, and they need to assemble, program and design the robot in a very short time. To compensate for this, we reduce the amount of optimization and robustness that is necessary. Because it’s an agriculture setting, we have different objects, like fruits, that the teams need to handle. This makes it a little bit more complicated because fruits have a more arbitrary shape and different levels of ripeness that need to be detected. We also have some grapes that are hanging on a wall, which is a completely different kind of manipulation task than before, because before the teams just needed to grasp things from surfaces, but now they really need to pluck stuff from a wall in a reliable way. So this is the new challenge. It also comes with a lot of software challenges because the computational power of this robot is very limited because it only has a Raspberry Pi. For example, there is not a lot of image processing possible, especially compared to the current robots, some of which even have GPUs embedded.

Is there a particular part of the hardware or software that you’ve seen some of the biggest developments in over the last year or so?

Yeah, I think one big change I observed over the years was a switch from custom neural networks for object detection to off-the-shelf components. So pretty much all teams nowadays use YOLO networks, which you can get pre-trained and they just deploy them on GPUs that they embedded into their robots. This is also one of the reasons why the robots really grew in size over the last few years because they needed space for the larger computational power. This actually made it possible for a lot of teams to reliably detect the objects. Object detection was a big problem in the beginning of the league and nowadays it’s not really a big issue – most teams are really good at that. Sometimes they are a little bit startled with decoy objects – these are objects in the arena that are not really part of the task, and they are unknown to the teams beforehand. Sometimes they are, let’s say, evil decoys that look like an object and there’s some mismatches that the teams do, but this is becoming very rare.

I think the second big change is a switch to larger manipulators with more degrees of freedom. So in the beginning, everyone had a very small manipulator with only five degrees of freedom, which limited the operating range, and nowadays pretty much all teams have a six degree of freedom manipulator with a large range. This means that they don’t need to move their robot when they are in front of a workstation, which makes them much faster and also much more precise.

Could you talk about the future plans for the League?

There are a few things we are thinking about.

With regards to the competition itself, we had a discussion with the teams about what they are interested in doing in the future. Two things came up that they really want to have. One is mobile obstacles, so they want other objects to move autonomously through the arena. We’re in the process of creating that, in cooperation with EduArt, which is a company from Germany that also provides small educational robots. And the second thing we want to introduce is a kind of humanoid robot that the teams can use to actually handle special manipulation tasks that cannot be done simply with a robot manipulator.

In terms of creating an entry-level League, we have been working on this and one potential idea is to use the smart-farming challenge as the entry point. Through the collaboration with Studica, we can provide teams with the robot and they get to keep it after the competition. At the German Open I spoke to the Rapidly-Manufactured Rescue League about this crossover between the Rescue and the Junior Leagues, and they are very keen to collaborate.

We’re also talking with the Logistics League. Their sponsor, Festo, has dropped out of their league and now they need to reorganize. We are wondering if it would be worthwhile to bring our leagues closer together, or even fuse them together to a single RoboCup Industrial league. The Logistics League wants to do more manipulation, and the @Work League wants to do more planning, so we are closing the gap naturally between the two. However, this is just a thought at the moment – we need to see how the teams react to that.

About Christoph

Christoph Steup is an active researcher specializing in various fields of robotics, including swarm robotics, precision farming, and weather-resilient autonomous driving. He currently works at the Fraunhofer Institute for Transportation and Infrastructure Systems (IVI), where he leads the Swarm Technology Group. Prior to this role, he headed the Computational Intelligence in Robotics group at the Otto von Guericke University Magdeburg. Christoph’s involvement with RoboCup began in 2015 when he joined the robOTTO team of Otto von Guericke University as team leader. His contributions to the RoboCup community expanded as he became a member of the Technical Committee for the @Work League in 2017. In 2019, he further advanced his participation by joining the Executive Committee of the league.

Interview with Haimin Hu: Game-theoretic integration of safety, interaction and learning for human-centered autonomy

In this interview series, we’re meeting some of the AAAI/SIGAI Doctoral Consortium participants to find out more about their research. In this latest interview, Haimin Hu tells us about his research on the algorithmic foundations of human-centered autonomy and his plans for future projects, and gives some advice for PhD students looking to take the next step in their career.

Could you give us an overview of the research you carried out during your PhD?

My PhD research, conducted under the supervision of Professor Jaime Fernández Fisac in the Princeton Safe Robotics Lab, focuses on the algorithmic foundations of human-centered autonomy. By integrating dynamic game theory with machine learning and safety-critical control, my work aims to ensure autonomous systems, from self-driving vehicles to drones and quadrupedal robots, are performant, verifiable, and trustworthy when deployed in human-populated space. The core principle of my PhD research is to plan robots’ motion in the joint space of both physical and information states, actively ensuring safety as they navigate uncertain, changing environments and interact with humans. Its key contribution is a unified algorithmic framework—backed by game theory—that allows robots to safely interact with their human peers, adapt to human preferences and goals, and even help humans refine their skills. Specifically, my PhD work contributes to the following areas in human-centered autonomy and multi-agent systems:

  • Trustworthy human–robot interaction: Planning safe and efficient robot trajectories by closing the computation loop between physical human-robot interaction and runtime learning that reduces the robot’s uncertainty about the human.
  • Verifiable neural safety analysis for complex robotic systems: Learning robust neural controllers for robots with high-dimensional dynamics; guaranteeing their training-time convergence and deployment-time safety.
  • Scalable interactive planning under uncertainty: Synthesizing game-theoretic control policies for complex and uncertain human–robot systems at scale.

Was there a project (or aspect of your research) that was particularly interesting?

Safety in human-robot interaction is especially difficult to define, because it hinges on an, I’d say, almost unanswerable question: How safe is safe enough when humans might behave in arbitrary ways? To give a concrete example: Is it sufficient if an autonomous vehicle can avoid hitting a fallen cyclist 99.9% of the time? What if this rate can only be achieved by the vehicle always stopping and waiting for the human to move out of the way?

I would argue that, for trustworthy deployment of robots in human-populated space, we need to complement standard statistical methods with clear-cut robust safety assurances under a vetted set of operation conditions as well established as those of bridges, power plants, and elevators. We need runtime learning to minimize the robot’s performance loss caused by safety-enforcing maneuvers; this calls for algorithms that can reduce the robot’s inherent uncertainty induced by its human peers, for example, their intent (does a human driver want to merge, cut behind, or stay in the lane?) or response (if the robot comes closer, how will the human react?). We need to close the loop between the robot’s learning and decision-making so that it can optimize efficiency by anticipating how its ongoing interaction with the human may affect the evolving uncertainty, and ultimately, its long-term performance.

What made you want to study AI, and the area of human-centered robotic systems in particular?

I’ve been fascinated by robotics and intelligent systems since childhood, when I’d spend entire days watching sci-fi anime like Mobile Suit Gundam, Neon Genesis Evangelion, or Future GPX Cyber Formula. What captivated me wasn’t just the futuristic technology, but the vision of AI as a true partner—augmenting human abilities rather than replacing them. Cyber Formula in particular planted the idea of human-AI co-evolution in my mind: an AI co-pilot that not only helps a human driver navigate high-speed, high-stakes environments, but also adapts to the driver’s style over time, ultimately making the human a better racer and deepening mutual trust along the way. Today, during my collaboration with Toyota Research Institute (TRI), I work on human-centered robotics systems that embody this principle: designing AI systems that collaborate with people in dynamic, safety-critical settings by rapidly aligning with human intent through multimodal inputs, from physical assistance to visual cues and language feedback, bringing to life the very ideas that once lived in my childhood imagination.

You’ve landed a faculty position at Johns Hopkins University (JHU) – congratulations! Could you talk a bit about the process of job searching, and perhaps share some advice and insights for PhD students who may be at a similar stage in their career?

The job search was definitely intense but also deeply rewarding. My advice to PhD students: start thinking early about the kind of long-term impact you want to make, and act early on your application package and job talk. Also, make sure you talk to people, especially your senior colleagues and peers on the job market. I personally benefited a lot from the following resources:

Do you have an idea of the research projects you’ll be working on at JHU?

I wish to help create a future where humans can unquestionably embrace the presence of robots around them. Towards this vision, my lab at JHU will investigate the following topics:

  • Uncertainty-aware interactive motion planning: How can robots plan safe and efficient motion by accounting for their evolving uncertainty, as well as their ability to reduce it through future interaction, sensing, communication, and learning?
  • Human–AI co-evolution and co-adaptation: How can embodied AI systems learn from human teammates while helping them refine existing skills and acquire new ones in a safe, personalized manner?
  • Safe human-compatible autonomy: How can autonomous systems ensure prescribed safety while remaining aligned with human values and attuned to human cognitive limitations?
  • Scalable and generalizable strategic decision-making: How can multi-robot systems make safe, coordinated decisions in dynamic, human-populated environments?

How was the experience attending the AAAI Doctoral Consortium?

I had the privilege of attending the 2025 AAAI Doctoral Consortium, and it was an incredibly valuable experience. I’m especially grateful to the organizers for curating such a thoughtful and supportive environment for early-career researchers. The highlight for me was the mentoring session with Dr Ming Yin (postdoc at Princeton, now faculty at Georgia Tech CSE), whose insights on navigating the uncertain and competitive job market were both encouraging and eye-opening.

Could you tell us an interesting (non-AI related) fact about you?

I am passionate about skiing. I learned to ski primarily by vision-based imitation learning from a chairlift, though I’m definitely paying the price now for poor generalization! One day, I hope to build an exoskeleton that teaches me to ski better while keeping me safe on the double black diamonds.

About Haimin

Haimin Hu is an incoming Assistant Professor of Computer Science at Johns Hopkins University, where he is also a member of the Data Science and AI Institute, the Institute for Assured Autonomy, and the Laboratory for Computational Sensing and Robotics. His research focuses on the algorithmic foundations of human-centered autonomy. He has received several awards and recognitions, including a 2025 Robotics: Science and Systems Pioneer, a 2025 Cyber-Physical Systems Rising Star, and a 2024 Human-Robot Interaction Pioneer. Additionally, he has served as an Associate Editor for IEEE Robotics and Automation Letters since his fourth year as a PhD student. He obtained a PhD in Electrical and Computer Engineering from Princeton University in 2025, an MSE in Electrical Engineering from the University of Pennsylvania in 2020, and a BE in Electronic and Information Engineering from ShanghaiTech University in 2018.

AIhub coffee corner: Agentic AI

AIhub coffee corner

The AIhub coffee corner captures the musings of AI experts over a short conversation. This month we tackle the topic of agentic AI. Joining the conversation this time are: Sanmay Das (Virginia Tech), Tom Dietterich (Oregon State University), Sabine Hauert (University of Bristol), Sarit Kraus (Bar-Ilan University), and Michael Littman (Brown University).

Sabine Hauert: Today’s topic is agentic AI. What is it? Why is it taking off? Sanmay, perhaps you could kick off with what you noticed at AAMAS [the Autonomous Agents and Multiagent Systems conference]?

Sanmay Das: It was very interesting because obviously there’s suddenly been an enormous interest in what an agent is and in the development of agentic AI. People in the AAMAS community have been thinking about what an agent is for at least three decades. Well, longer actually, but the community itself dates back about three decades in the form of these conferences. One of the very interesting questions was about why everybody is rediscovering the wheel and rewriting these papers about what it means to be an agent, and how we should think about these agents. The way in which AI has progressed, in the sense that large language models (LLMs) are now the dominant paradigm, is almost entirely different from the way in which people have thought about agents in the AAMAS community. Obviously, there’s been a lot of machine learning and reinforcement learning work, but there’s this historical tradition of thinking about reasoning and logic where you can actually have explicit world models. Even when you’re doing game theory, or MDPs, or their variants, you have an explicit world model that allows you to specify the notion of how to encode agency. Whereas I think that’s part of the disconnect now – everything is a little bit black boxy and statistical. How do you then think about what it means to be an agent? I think in terms of the underlying notion of what it means to be an agent, there’s a lot that can be learnt from what’s been done in the agents community and in philosophy.

I also think that there are some interesting ties to thinking about emergent behaviors, and multi-agent simulation. But it’s a little bit of a Wild West out there and there are all of these papers saying we need to first define what an agent is, which is definitely rediscovering the wheel. So, at AAMAS, there was a lot of discussion of stuff like that, but also questions about what this means in this particular era, because now we suddenly have these really powerful creatures that I think nobody in the AAMAS community saw coming. Fundamentally we need to adapt what we’ve been doing in the community to take into account that these are different from how we thought intelligent agents would emerge into this more general space where they can play. We need to work out how we adapt the kinds of things that we’ve learned about negotiation, agent interaction, and agent intention, to this world. Rada Mihalcea gave a really interesting keynote talk thinking about the natural language processing (NLP) side of things and the questions there.

Sabine: Do you feel like it was a new community joining the AAMAS community, or the AAMAS community that was converting?

Sanmay: Well, there were people who were coming to AAMAS and seeing that the community has been working on this for a long time. So learning something from that was definitely the vibe that I got. But my guess is, if you go to ICML or NeurIPS, that’s very much not the vibe.

Sarit Kraus: I think they’re wasting some time. I mean, forget the “what is an agent?”, but there have been many works from the agent community for many years about coordination, collaboration, etc. I heard about one recent paper where they reinvented Contract Nets. Contract Nets were introduced in 1980, and now there is a paper about it. OK, it’s LLMs that are transferring tasks from one another and signing contracts, but if they just read the past papers, it would save their time and then they could move to more interesting research questions. Currently, they say with LLM agents that you need to divide the task into sub agents. My PhD was about building a Diplomacy player, and in my design of the player there were agents that each played a different part of a Diplomacy play – one was a strategic agent, one was a Foreign Minister, etc. And now they are talking about it again.

Michael Littman: I totally agree with Sanmay and Sarit. The way I think about it is this: this notion of “let’s build agents now that we have LLMs” to me feels a little bit like we have a new programming language like Rust++, or whatever, and we can use it to write programs that we were struggling with before. It’s true that new programming languages can make some things easier, which is great, and LLMs give us a new, powerful way to create AI systems, and that’s also great. But it’s not clear that they solve the challenges that the agents community have been grappling with for so long. So, here’s a concrete example from an article that I read yesterday. Claudius is a version of Claude and it was agentified to run a small online shop. They gave it the ability to communicate with people, post slack messages, order products, set prices on things, and people were actually doing economic exchanges with the system. At the end of the day, it was terrible. Somebody talked it into buying tungsten cubes and selling them in the store. It was just nonsense. The Anthropic people viewed the experiment as a win. They said “ohh yeah, there were definitely problems, but they’re totally fixable”. And the fixes, to me, sounded like all they’d have to do is solve the problems that the agents community has been trying to solve for the last couple of decades. That’s all, and then we’ve got it perfect. And it’s not clear to me at all that just making LLMs generically better, or smarter, or better reasoners suddenly makes all these kinds of agents questions trivial because I don’t think they are. I think they’re hard for a reason and I think you have to grapple with the hard questions to actually solve these problems. But it’s true that LLMs give us a new ability to create a system that can have a conversation. But then the system’s decision-making is just really, really bad. And so I thought that was super interesting. But we agents researchers still have jobs, that’s the good news from all this.

Sabine: My bread and butter is to design agents, in our case robots, that work together to arrive at desired emergent properties and collective behaviors. From this swarm perspective, I feel that over the past 20 years we have learned a lot of the mechanisms by which you reach consensus, the mechanisms by which you automatically design agent behaviours using machine learning to enable groups to achieve a desired collective task. We know how to make agent behaviours understandable, all that good stuff you want in an engineered system. But up until now, we’ve been profoundly lacking the individual agents’ ability to interact with the world in a way that gives you richness. So in my mind, there’s a really nice interface where the agents are more capable, so they can now do those local interactions that make them useful. But we have this whole overarching way to systematically engineer collectives that I think might make the best of both worlds. I don’t know at what point that interface happens. I guess it comes partly from every community going a little bit towards the other side. So from the swarm side, we’re trying visual language models (VLMs), we’re trying to have our robots understand using LLMs their local world to communicate with humans and with each other and get a collective awareness at a very local level of what’s happening. And then we use our swarm paradigms to be able to engineer what they do as a collective using our past research expertise. I imagine for those who are just entering this discipline they need to start from the LLMs and go up. I think it’s part of the process.

Tom Dietterich: I think a lot of it just doesn’t have anything to do with agents at all, you’re writing computer programs. People found that if you try to use a single LLM to do the whole thing, the context gets all messed up and the LLM starts having trouble interpreting it. In fact, these LLMs have a relatively small short-term memory that they can effectively use before they start getting interference among the different things in the buffer. So the engineers break the system into multiple LLM calls and chain them together, and it’s not an agent, it’s just a computer program. I don’t know how many of you have seen this system called DSPy (written by Omar Khattab)? It takes an explicit sort of software engineering perspective on things. Basically, you write a type signature for each LLM module that says “here’s what it’s going to take as input, here’s what it’s going to produce as output”, you build your system, and then DSPy automatically tunes all the prompts as a sort of compiler phase to get the system to do the right thing. I want to question whether building systems with LLMs as a software engineering exercise will branch off from the building of multi-agent systems. Because virtually all the “agentic systems” are not agents in the sense that we would call them that. They don’t have autonomy any more than a regular computer program does.

Sabine: I wonder about the anthropomorphization of this, because now that you have different agents, they’re all doing a task or a job, and all of a sudden you get articles talking about how you can replace a whole team by a set of agents. So we’re no longer replacing individual jobs, we’re now replacing teams and I wonder if this terminology also doesn’t help.

Sanmay: To be clear, this idea has existed at least since the early 90s, when there were these “soft bots” that were basically running Unix commands and they were figuring out what to do themselves. It’s really no different. What people mean when they’re talking about agents is giving a piece of code the opportunity to run its own stuff and to be able to do that in service of some kind of a goal.

I think about this in terms of economic agents, because that’s what I grew up (AKA, did my PhD) thinking about. And, do I want an agent? I could think about writing an agent that manages my (non-existent) stock portfolio. If I had enough money to have a stock portfolio, I might think about writing an agent that manages that portfolio, and that’s a reasonable notion of having autonomy, right? It has some goal, which I set, and then it goes about making decisions. If you think about the sensor-actuator framework, its actuator is that it can make trades and it can take money from my bank account in order to do so. So I think that there’s something in getting back to the basic question of “how does this agent act in the world?” and then what are the percepts that it is receiving?

I completely agree with what you were saying earlier about this question of whether the LLMs enable interactions to happen in different ways. If you look at pre-LLMs, with these agents that were doing pricing, there’s this hilarious story of how some old biology textbook ended up costing $17 million on Amazon because there were these two bots that were doing the pricing of those books at two different used book stores. One of them was a slightly higher-rated store than the other, so it would take whatever price that the lower-rated store had and push it up by 10%. Then the lower-rated store was an undercutter and it would take the current highest price and go to 99% of that price. But this just led to this spiral where suddenly that book cost $17 million. This is exactly the kind of thing that’s going to happen in this world. But the thing that I’m actually somewhat worried about, and anthropomorphising, is how these agents are going to decide on their goals.There’s an opportunity for really bad errors to come out of programming that wouldn’t be as harmful in a more constrained situation.

Tom: In the reinforcement learning literature, of course, there’s all this discussion about reward hacking and so on, but now we imagine two agents interacting with each other and hacking each other’s rewards effectively, so the whole dynamics blows up – people are just not prepared.

Sabine: The breakdown of the problem that Tom mentioned, I think there’s perhaps a real benefit to having these agents that are narrower and that as a result are perhaps more verifiable at the individual level, they maybe have clearer goals, they might be more green because we might be able to constrain what area they operate with. And then in the robotics world, we’ve been looking at collaborative awareness where narrow agents that are task-specific are aware of other agents and collectively they have some awareness of what they’re meant to be doing overall. And it’s quite anti-AGI in the sense that you have lots of narrow agents again. So part of me is wondering, are we going back to heterogeneous task-specific agents and the AGI is collective, perhaps? And so this new wave, maybe it’s anti-AGI – that would be interesting!

Tom: Well, it’s almost the only way we can hope to prove the correctness of the system, to have each component narrow enough that we can actually reason about it. That’s an interesting paradox that I was missing from Stuart Russell’s “What if we succeed?” chapter in his book, which is what if we succeed in building a broad-spectrum agent, how are we going to test it?

It does seem like it would be great to have some people from the agents community speak at the machine learning conferences and try to do some diplomatic outreach. Or maybe run some workshops at those conferences.

Sarit: I was always interested in human-agent interaction and the fact that LLMs have solved the language issue for me, I’m very excited. But the other problem that has been mentioned is still here – you need to integrate strategies and decision-making. So my model is you have LLM agents that have tools that are all sorts of algorithms that we developed and implemented and there should be several of them. But the fact that somebody solved our natural language interaction, I think this is really, really great and good for the agents community as well for the computer science community generally.

Sabine: And good for the humans. It’s a good point, the humans are agents as well in those systems.

Interview with Kate Candon: Leveraging explicit and implicit feedback in human-robot interactions

In this interview series, we’re meeting some of the AAAI/SIGAI Doctoral Consortium participants to find out more about their research. Kate Candon is a PhD student at Yale University interested in understanding how we can create interactive agents that are more effectively able to help people. We spoke to Kate to find out more about how she is leveraging explicit and implicit feedback in human-robot interactions.

Could you start by giving us a quick introduction to the topic of your research?

I study human-robot interaction. Specifically I’m interested in how we can get robots to better learn from humans in the way that they naturally teach. Typically, a lot of work in robot learning is with a human teacher who is only tasked with giving explicit feedback to the robot, but they’re not necessarily engaged in the task. So, for example, you might have a button for “good job” and “bad job”. But we know that humans give a lot of other signals, things like facial expressions and reactions to what the robot’s doing, maybe gestures like scratching their head. It could even be something like moving an object to the side that a robot hands them – that’s implicitly saying that that was the wrong thing to hand them at that time, because they’re not using it right now. Those implicit cues are trickier, they need interpretation. However, they are a way to get additional information without adding any burden to the human user. In the past, I’ve looked at these two streams (implicit and explicit feedback) separately, but my current and future research is about combining them together. Right now, we have a framework, which we are working on improving, where we can combine the implicit and explicit feedback.

In terms of picking up on the implicit feedback, how are you doing that, what’s the mechanism? Because it sounds incredibly difficult.

It can be really hard to interpret implicit cues. People will respond differently, from person to person, culture to culture, etc. And so it’s hard to know exactly which facial reaction means good versus which facial reaction means bad.

So right now, the first version of our framework is just using human actions. Seeing what the human is doing in the task can give clues about what the robot should do. They have different action spaces, but we can find an abstraction so that we can know that if a human does an action, what the similar actions would be that the robot can do. That’s the implicit feedback right now. And then, this summer, we want to extend that to using visual cues and looking at facial reactions and gestures.

So what kind of scenarios have you been kind of testing it on?

For our current project, we use a pizza making setup. Personally I really like cooking as an example because it’s a setting where it’s easy to imagine why these things would matter. I also like that cooking has this element of recipes and there is a formula, but there’s also room for personal preferences. For example, somebody likes to put their cheese on top of the pizza, so it gets really crispy, whereas other people like to put it under the meat and veggies, so that maybe it is more melty instead of crispy. Or even, some people clean up as they go versus others who wait until the end to deal with all the dishes. Another thing that I’m really excited about is that cooking can be social. Right now, we’re just working in dyadic human-robot interactions where it’s one person and one robot, but another extension that we want to work on in the coming year is extending this to group interactions. So if we have multiple people, maybe the robot can learn not only from the person reacting to the robot, but also learn from a person reacting to another person and extrapolating what that might mean for them in the collaboration.

Could you say a bit about how the work that you did earlier in your PhD has led you to this point?

When I first started my PhD, I was really interested in implicit feedback. And I thought that I wanted to focus on learning only from implicit feedback. One of my current lab mates was focused on the EMPATHIC framework, and was looking into learning from implicit human feedback, and I really liked that work and thought it was the direction that I wanted to go into.

However, that first summer of my PhD it was during COVID and so we couldn’t really have people come into the lab to interact with robots. And so instead I did an online study where I had people play a game with a robot. We recorded their face while they were playing the game, and then we tried to see if we could predict based on just facial reactions, gaze, and head orientation if we could predict what behaviors they preferred for the agent that they were playing with in the game. We actually found that we could decently well predict which of the behaviors they preferred.

The thing that was really cool was we found how much context matters. And I think this is something that is really important for going from just a solely teacher-learner paradigm to a collaboration – context really matters. What we found is that sometimes people would have really big reactions but it wasn’t necessarily to what the agent was doing, it was to something that they had done in the game. For example, there’s this clip that I always use in talks about this. This person’s playing and she has this really noticeably confused, upset look. And so at first you might think that’s negative feedback, whatever the robot did, the robot shouldn’t have done that. But if you actually look at the context, we see that it was the first time that she lost a life in this game. For the game we made a multiplayer version of Space Invaders, and she got hit by one of the aliens and her spaceship disappeared. And so based on the context, when a human looks at that, we actually say she was just confused about what happened to her. We want to filter that out and not actually consider that when reasoning about the human’s behavior. I think that was really exciting. After that, we realized that using implicit feedback only was just so hard. That’s why I’ve taken this pivot, and now I’m more interested in combining the implicit and explicit feedback together.

You mentioned the explicit element would be more binary, like good feedback, bad feedback. Would the person-in-the-loop press a button or would the feedback be given through speech?

Right now we just have a button for good job, bad job. In an HRI paper we looked at explicit feedback only. We had the same space invaders game, but we had people come into the lab and we had a little Nao robot, a little humanoid robot, sitting on the table next to them playing the game. We made it so that the person could give positive or negative feedback during the game to the robot so that it would hopefully learn better helping behavior in the collaboration. But we found that people wouldn’t actually give that much feedback because they were focused on just trying to play the game.

And so in this work we looked at whether there are different ways we can remind the person to give feedback. You don’t want to be doing it all the time because it’ll annoy the person and maybe make them worse at the game if you’re distracting them. And also you don’t necessarily always want feedback, you just want it at useful points. The two conditions we looked at were: 1) should the robot remind someone to give feedback before or after they try a new behavior? 2) should they use an “I” versus “we” framing? For example, “remember to give feedback so I can be a better teammate” versus “remember to give feedback so we can be a better team”, things like that. And we found that the “we” framing didn’t actually make people give more feedback, but it made them feel better about the feedback they gave. They felt like it was more helpful, kind of a camaraderie building. And that was only explicit feedback, but we want to see now if we combine that with a reaction from someone, maybe that point would be a good time to ask for that explicit feedback.

You’ve already touched on this but could you tell us about the future steps you have planned for the project?

The big thing motivating a lot of my work is that I want to make it easier for robots to adapt to humans with these subjective preferences. I think in terms of objective things, like being able to pick something up and move it from here to here, we’ll get to a point where robots are pretty good. But it’s these subjective preferences that are exciting. For example, I love to cook, and so I want the robot to not do too much, just to maybe do my dishes whilst I’m cooking. But someone who hates to cook might want the robot to do all of the cooking. Those are things that, even if you have the perfect robot, it can’t necessarily know those things. And so it has to be able to adapt. And a lot of the current preference learning work is so data hungry that you have to interact with it tons and tons of times for it to be able to learn. And I just don’t think that that’s realistic for people to actually have a robot in the home. If after three days you’re still telling it “no, when you help me clean up the living room, the blankets go on the couch not the chair” or something, you’re going to stop using the robot. I’m hoping that this combination of explicit and implicit feedback will help it be more naturalistic. You don’t have to necessarily know exactly the right way to give explicit feedback to get the robot to do what you want it to do. Hopefully through all of these different signals, the robot will be able to hone in a little bit faster.

I think a big future step (that is not necessarily in the near future) is incorporating language. It’s very exciting with how large language models have gotten so much better, but also there’s a lot of interesting questions. Up until now, I haven’t really included natural language. Part of it is because I’m not fully sure where it fits in the implicit versus explicit delineation. On the one hand, you can say “good job robot”, but the way you say it can mean different things – the tone is very important. For example, if you say it with a sarcastic tone, it doesn’t necessarily mean that the robot actually did a good job. So, language doesn’t fit neatly into one of the buckets, and I’m interested in future work to think more about that. I think it’s a super rich space, and it’s a way for humans to be much more granular and specific in their feedback in a natural way.

What was it that inspired you to go into this area then?

Honestly, it was a little accidental. I studied math and computer science in undergrad. After that, I worked in consulting for a couple of years and then in the public healthcare sector, for the Massachusetts Medicaid office. I decided I wanted to go back to academia and to get into AI. At the time, I wanted to combine AI with healthcare, so I was initially thinking about clinical machine learning. I’m at Yale, and there was only one person at the time doing that, so I was looking at the rest of the department and then I found Scaz (Brian Scassellati) who does a lot of work with robots for people with autism and is now moving more into robots for people with behavioral health challenges, things like dementia or anxiety. I thought his work was super interesting. I didn’t even realize that that kind of work was an option. He was working with Marynel Vázquez, a professor at Yale who was also doing human-robot interaction. She didn’t have any healthcare projects, but I interviewed with her and the questions that she was thinking about were exactly what I wanted to work on. I also really wanted to work with her. So, I accidentally stumbled into it, but I feel very grateful because I think it’s a way better fit for me than the clinical machine learning would have necessarily been. It combines a lot of what I’m interested in, and I also feel it allows me to flex back and forth between the mathy, more technical work, but then there’s also the human element, which is also super interesting and exciting to me.

Have you got any advice you’d give to someone thinking of doing a PhD in the field? Your perspective will be particularly interesting because you’ve worked outside of academia and then come back to start your PhD.

One thing is that, I mean it’s kind of cliche, but it’s not too late to start. I was hesitant because I’d been out of the field for a while, but I think if you can find the right mentor, it can be a really good experience. I think the biggest thing is finding a good advisor who you think is working on interesting questions, but also someone that you want to learn from. I feel very lucky with Marynel, she’s been a fabulous advisor. I’ve worked pretty closely with Scaz as well and they both foster this excitement about the work, but also care about me as a person. I’m not just a cog in the research machine.

The other thing I’d say is to find a lab where you have flexibility if your interests change, because it is a long time to be working on a set of projects.

For our final question, have you got an interesting non-AI related fact about you?

My main summertime hobby is playing golf. My whole family is into it – for my grandma’s 100th birthday party we had a family golf outing where we had about 40 of us golfing. And actually, that summer, when my grandma was 99, she had a par on one of the par threes – she’s my golfing role model!

About Kate

Kate Candon is a PhD candidate at Yale University in the Computer Science Department, advised by Professor Marynel Vázquez. She studies human-robot interaction, and is particularly interested in enabling robots to better learn from natural human feedback so that they can become better collaborators. She was selected for the AAMAS Doctoral Consortium in 2023 and HRI Pioneers in 2024. Before starting in human-robot interaction, she received her B.S. in Mathematics with Computer Science from MIT and then worked in consulting and in government healthcare.

Page 1 of 4
1 2 3 4