Your AI roadmap is complete, yet no one clearly owns the work of turning it into a production system. Many AI initiatives stall during this handoff.
The artifacts of a serious engagement are in place: mapped processes, prioritized use cases, an approved business case, and a roadmap built around real operating needs. The work behind them was credible enough to earn approval, and the investment made sense. Months later, though, that roadmap is still the clearest result anyone can point to.
Now leadership is asking directly: What actually shipped?
They want to see agents running inside real business processes and evidence that the investment is producing a return. The strategy is complete. The production value is still missing.
The consultants delivered what they promised
You walked away with a clear diagnosis of where the business was breaking down. Process mapping followed the work across teams and systems until the real bottlenecks became visible. What looked like a need for more headcount sometimes turned out to be an approval queue or a missing data field upstream. Hiring more people would have left the bottleneck in place.
Opportunity sizing then tested each use case against the realities of your business. Some ambitious ideas lost ground when the team examined the available data and integration work. Smaller, recurring workflows moved up because their economics were easier to prove. The exercise also surfaced whether the data required for each use case actually existed in a usable form. By the time the roadmap was prioritized, you knew why each use case was there, what outcome it served, and how success would be measured.
The approved business case turned that reasoning into an investment decision. It showed what would change, what it would cost, and when the return should show up. Finance had what it needed to fund the work. The teams responsible for delivery understood what leadership expected them to produce.
The engagement narrowed a broad AI ambition into a plan grounded in how your business actually operates. The roadmap earned approval because the work behind it held up.
The roadmap ends where the production gap begins
You’re holding an approved roadmap with no clear path to production. The production gap is the distance between an approved AI strategy and an agent operating inside a live business process.
Once a use case is approved, the nature of the work changes. Strategy establishes where an agent can create value. Delivery has to determine how that agent will work with your data, systems, permissions, and operating policies. It also has to move through the technical, security, and procurement decisions standing between a recommendation and go-live.
Suppose your roadmap prioritizes an agent that helps resolve supplier disruptions. The process map shows where delays occur and how much they cost. Putting that agent into production introduces a different set of decisions. It needs access to live order data. Operations has to determine when a person must approve its recommendations. If supplier data is missing or a system call fails, the agent needs a defined path back to a person. Strategy may frame these requirements, but delivery has to resolve and implement them.
Your engagement is designed to end before that work begins. Taking the strategy into production requires a different team, contract, and accountability model. When the consultants leave, you have what you commissioned: a credible plan that your organization must now execute.
That is where ownership fractures. The roadmap begins circulating among functions. A technical decision holds up procurement. Once the vendor question is settled, security review becomes the next gate. Everyone continues doing the work assigned to them, but no one owns the handoff or can commit the organization to a production date.
The engagement can finish successfully while the AI initiative stalls. Both can be true. Ownership ended at the same point the work shifted from planning to production.
Your business case has an expiration date
The question leadership is asking is blunt: What is running in production, and what value has it delivered? At this stage, a list of completed activities won’t answer it. Leadership wants to know what the investment has returned.
The original approval committed capital to a measurable change in the business. Consider a supply chain initiative approved to reduce the time required to resolve an inventory exception. The roadmap established the current cost of that delay and the improvement the agent was expected to produce. Until the agent is handling those exceptions inside the live workflow, the expected savings exist only in the business case.
Time now works against the original economics. Internal teams keep committing hours, integration work keeps consuming budget, and the date when the organization begins realizing value moves further out. A business case built around a 12-month payback starts to unravel when the first year passes without an agent processing a live transaction. Delayed benefits and added delivery costs lengthen the payback period and weaken the return leadership originally approved.
The assumptions behind the calculation also start to age. The process evolves while the agent waits, forcing you to validate the expected savings again before asking for more capital. A delay that begins as a delivery problem eventually becomes a funding problem.
You’re far from alone in facing this pressure: 60% of companies see little to no value from AI. This explains why this conversation is happening in so many companies at once. AI spending has moved faster than production results, and leadership has heard enough versions of that story that another quarter of plans and progress updates carries less weight.
A strong roadmap explains why the organization invested. Production results determine whether it keeps investing.
The next deliverable has to be production
Getting an agent into production requires a clear owner who stays with the initiative after the roadmap is approved and has the authority to settle decisions that would otherwise bounce between teams. Their accountability runs through go-live and the first measurable business result.
When a security review stalls the release, your production owner brings the decision makers together and keeps the issue moving until it is resolved. The delay gets reflected in the business case instead of disappearing into a status report. That same person remains accountable when a platform needs to be selected or the operating team needs to prepare for launch.
Production ownership also keeps spending connected to progress. A January 2026 survey of 413 agentic AI stakeholders in regulated industries found that 72% of agentic AI teams had exceeded their expected operating budgets. Without a clear owner, costs accumulate across separate workstreams, while no one can say whether the additional spending is getting the agent closer to production. Your production owner sees the full cost of the initiative and how much work remains. If the economics stop making sense, they can narrow the scope before more capital is committed.
Organizations need to build this production capability into their operating model. When it’s missing, the budget keeps moving while go-live waits for someone to take responsibility.
A second roadmap won’t close the production gap. What closes it is a capability that stays through agent build, integration, and the first live business result, not just the strategy that precedes it. The plan and the execution, under the same accountability.
Finish what the roadmap started
Your consulting engagement did exactly what it was designed to do. It helped you understand which processes to target, what the return should look like, and what success means. The gap isn’t strategy. It’s the execution, integration, and accountability that gets an agent from approved to running.
The roadmap made the investment case. Getting an agent into a live business process is how you begin proving it.
When an AI agent causes harm, leaders must be able to defend why it was allowed to act. To a board, auditor, or regulator, they need to show that the agent’s permissions, controls, and approvals were matched to the consequences of failure.
Treating guardrails as an on/off switch hides that decision. Guardrail risk tiering makes it explicit: every agent clears a common baseline, then receives stronger controls as its access, authority, and potential harm increase.
A read-only internal agent creates far less exposure than one that can access regulated data, invoke privileged tools, send external communications, or modify a system of record. The level of oversight applied to each should reflect that difference.
Key takeaways
Guardrail risk tiering matches oversight to business exposure. The strongest controls belong where an agent’s access and authority create consequences the organization would struggle to contain or reverse.
Every agent needs controls at its input and output boundaries. Inputs include user prompts and untrusted content introduced through retrieval, APIs, tools, and other agents.
An agent’s authority determines what leaders may have to defend. Sensitive data access, external communications, system changes, and financial transactions require closer oversight.
High-impact actions need hard stops outside the model. Transaction limits, permissions, approved recipients, and required approvals should be enforced before execution.
Guardrail risk tiering continues throughout the agent lifecycle. New tools, permissions, data sources, and autonomy can change an agent’s exposure after deployment.
Why your exposure should set the guardrail level
Your organization already makes proportional access decisions. Role-based access control (RBAC), OAuth, data classification, and access policies determine who can reach a system, what they can see, and what they can change. Agent guardrails extend that risk logic into runtime execution.
Guardrail risk tiering is the practice of matching the depth and placement of runtime controls to an agent’s data access, tool permissions, action authority, and potential consequences.
An agent’s exposure can change as a workflow unfolds. Reading an approved document carries one level of risk. Passing information into a tool that updates a customer record or initiates a transaction raises the stakes. Each new permission expands the set of outcomes the organization may have to explain after an incident.
Start with a common baseline. Add enforcement where the agent gains access to sensitive information or the authority to produce consequential outcomes. Guardrails reduce the probability and impact of unsafe behavior, but no set of controls can prevent every failure.
The leadership responsibility is to show that the level of oversight was deliberate, proportional, and approved before the agent acted.
Set the floor every agent has to clear
Every agent needs controls around information entering the workflow and consequential content leaving it.
The initial user request is only one input boundary. Once an agent begins retrieving documents, scraping pages, calling APIs, interacting with tools, or exchanging information with other agents, each result becomes another source of potentially untrusted input. A retrieved document or tool response can contain malicious or conflicting instructions just as a user prompt can. This is the indirect prompt injection surface that boundary controls need to cover.
Keeping unsafe instructions from shaping execution
Keeping sensitive information from leaving the workflow
Inspect user prompts, retrieved documents, scraped content, API responses, tool results, and other external context for prompt injection, prohibited content, sensitive information, and policy violations before that information influences execution.
Inspect consequential outputs for personally identifiable information (PII), toxic or biased content, sensitive data, and other policy violations before the response reaches a user or downstream system.
For a read-only internal agent working with approved information, these controls may cover most of the relevant exposure. Once an agent invokes privileged tools or takes action, boundary checks alone leave gaps between what the agent receives and what it ultimately does.
Leaders should know where those gaps begin because that is where the organization’s accountability expands.
What you’ll need to explain when something goes wrong
Once an agent moves beyond read-only tasks, its tools become one of the clearest indicators of business exposure. Write access to production databases, external communications, financial transactions, code execution, and sensitive personal data all increase the consequences of a bad decision.
For higher-risk tools, guardrails should evaluate proposed actions before execution. Failed checks need a defined response, such as blocking the action, using a safer fallback, or escalating to an authorized person.
The organization also needs a record of which tool was called, what permissions were active, which policy checks ran, and what changed downstream. Without that evidence, leaders may know that something went wrong without being able to explain how the agent was authorized to do it.
To determine how deep those controls should go, evaluate each agent against five questions:
What data can it access? Public or already-classified information creates a different exposure than customer, financial, HR, healthcare, or other sensitive data.
What can it write, execute, or trigger? Read access carries less operational authority than permission to modify a system of record, execute code, contact a customer, or initiate a transaction.
What authority does it operate under? Broader permissions and elevated access increase the range and severity of actions available to the agent.
How reversible are its actions? A generated summary can usually be discarded. A payment, deleted record, changed entitlement, or external communication can be far harder to unwind.
How far can a failure propagate? An isolated error carries a different risk profile from an action that affects downstream systems, customers, business processes, or other agents.
These questions turn a technical inventory into a leadership decision about the consequences the organization is willing to accept.
Decide which actions need a hard stop
Model-based checks work well when a control requires interpretation. They can identify prompt injection, unsafe content, off-topic behavior, or context-dependent policy violations.
Hard business constraints require deterministic enforcement outside the model. Before a high-impact tool executes, policy checks can validate permissions, transaction limits, approved recipients, required fields, data classifications, allowlists, and approval requirements.
The model can propose an action. A deterministic policy decides whether the action is permitted. When the consequences are difficult to reverse, an authorized person may need to make the final decision.
Spend oversight where failure costs the most
Every policy check consumes time, computing resources, or human attention. Leaders need to allocate that oversight according to exposure.
A low-risk summarization agent may need lightweight input and output checks. Multiple approval gates would consume review capacity while covering risks the agent does not create.
An agent that modifies customer records, communicates externally, or initiates transactions presents a different calculation. Validating permissions and proposed actions adds time, but the alternative may involve an unauthorized write, data exposure, investigation, remediation, or regulatory scrutiny.
Guardrail risk tiering makes that allocation explicit. The strongest enforcement belongs where a failure would be hardest to contain, reverse, or explain.
A practical way to allocate oversight
Enterprises don’t need to adopt a universal taxonomy. The objective is to connect an agent’s actual capabilities to a corresponding level of enforcement.
A practical guardrail risk tiering model might look like this:
Risk tier
Typical agent capabilities
Recommended guardrail depth
Baseline
Read-only access to approved or low-sensitivity data with no consequential actions
Input, retrieval, and final-output checks
Elevated
Sensitive data access, external communications, or tools that affect downstream workflows
Baseline controls plus tool-level policy enforcement, scoped permissions, and detailed tracing
High impact
Writes to systems of record, financial transactions, code execution, or difficult-to-reverse actions
Baseline and tool-level controls plus deterministic policy checks, explicit escalation paths, human approval where required, and complete auditability
Giving an existing agent write access, connecting a new Model Context Protocol (MCP) server, or expanding its data permissions can change its risk profile even when the model and prompt remain the same.
Guardrail risk tiering continues throughout the agent lifecycle. Each change in access, tools, or autonomy should trigger a decision about whether the organization can still defend the existing level of oversight.
Build a record you can defend
A risk tier has little value if nobody can show who assigned it, what controls it requires, or who can intervene. Before an agent reaches production, create a governance record that a board, auditor, regulator, or incident-response team could examine.
Name the accountable owner and approving authority. Identify who owns the agent’s performance and risk, who approved its operating scope, and who can change or revoke that approval.
Document what the agent is authorized to access and do. Record the data, tools, APIs, and downstream systems it can reach, along with what it can read, write, execute, or trigger.
Record the risk tier, controls, and rationale. State why the agent received its classification, which input, output, and tool-level controls apply, and who signed off on the decision.
Define hard stops and escalation authority. Specify which actions require deterministic enforcement or human approval. Name who can investigate, restrict permissions, initiate takeover, roll back a release, or suspend the agent.
Set review triggers and evidence requirements. Define what must be retained for audit and investigation. New tools, broader permissions, different data sources, and greater autonomy should trigger reassessment.
This record gives leaders more than proof that controls exist. It shows how the organization connected authority to oversight and who accepted responsibility for that decision.
Know whether the controls are working
Assigning a risk tier establishes the required controls. Leaders still need evidence that those controls operated as intended.
That evidence comes from tracing tool calls, identity and permission context, policy decisions, downstream actions, and escalation events. A tool call may satisfy a technical interface while violating a business rule. An action may execute under the wrong permission context. An agent may repeatedly encounter conditions that should trigger human review.
These patterns become visible when the organization can follow behavior across the execution path. The resulting record helps leaders answer specific questions: Which identity authorized the action? Which policy applied? Did the agent receive an exception? Who was notified? What changed downstream?
Leaders need evidence they can produce during an audit or after an incident — not a description of the controls that were supposed to run, but a record of what actually happened.
Guardrail risk tiering is a method for matching the depth and placement of runtime controls to the risk created by an AI agent’s data access, permissions, tools, actions, and downstream impact. Higher-risk capabilities receive additional controls closer to the point of execution.
What guardrails should every AI agent have?
Every agent should have a minimum set of controls around information entering the workflow and consequential content leaving it. Input controls should cover the original user request as well as retrieved documents, API responses, tool results, and other untrusted context introduced during execution.
When does an AI agent need tool-level guardrails?
Tool-level controls become increasingly important when an agent can access sensitive data, write to systems of record, communicate externally, execute code, initiate transactions, or trigger other consequential workflows. Higher-impact actions may also require deterministic policy enforcement or human approval before execution.
Do AI guardrails eliminate agent risk?
No. Guardrails reduce the likelihood and potential impact of unsafe or unauthorized behavior. Teams still need appropriate permissions, observability, testing, auditability, escalation procedures, and ongoing review to manage residual risk.
When should an agent’s guardrail risk tier be reassessed?
Reassess guardrail risk tiering whenever the agent gains new tools, permissions, data sources, workflows, or autonomy. Changes to connected systems can alter risk even when the model, prompts, and core agent logic remain the same.
The quarterly infrastructure bill comes in at nearly four times the forecast. An AI agent has been retrying failed tasks and consuming resources within the permissions and spending limits it was given. Elsewhere, an agent runs a workflow outside its approved scope, or the wrong employee sees data they shouldn’t.
The executive sponsor gets the same question every time: How did this happen?
The agent may have followed its instructions and used the permissions it was given. It simply operated inside a system that allowed the wrong outcome. When that happens, the failure lies in how the organization defined and governed the agent’s boundaries. And it’s more common than many organizations expect.
Gartner predicts that more than 40% of agentic AI projects will be canceled by the end of 2027, driven by escalating costs, unclear business value, or inadequate risk controls. These problems become visible in production, but they begin with decisions made before deployment.
Guardrails are how leaders define acceptable agent behavior before an incident defines it for them. AI guardrails are policy-level controls that define what an agent can access, generate, and do at runtime.
Key takeaways
AI guardrails turn business policies and risk tolerances into runtime rules for agent behavior.
Leaders own the decisions about acceptable access, autonomy, cost, and consequences.
Risk tiering aligns governance investment with business exposure, applying the strongest controls where failures would be hardest to contain.
Governance built into deployment ensures the organization can explain and defend what every agent is authorized to do before it reaches scale.
Ownership, escalation authority, and review cadence must be clear before an agent launches.
Guardrails turn leadership intent into operating rules
Once an agent enters production, its behavior becomes an enterprise accountability issue. It can interact with customers, retrieve sensitive information, update records, and commit company resources. The policies governing those actions express the organization’s risk tolerance.
Consider a customer-service agent asked to summarize a customer’s relationship across multiple accounts. The agent follows linked records and retrieves information outside the representative’s authorized view. The model works as designed. The retrieval path works. The permissions also permit the agent to reach too far.
The resulting exposure reflects a governance gap. Someone had to decide what data the agent could access, which user permissions it should inherit, and what record the organization needed to defend its decisions. Unanswered questions default to whatever the architecture allows.
Engineering teams can implement access controls, filters, and approval gates. Leaders who own the business process must determine how much financial, regulatory, or reputational risk the enterprise will accept, which actions require human approval, and which failures justify suspension.
The agent did not suddenly become ungovernable. The organization expanded its capability faster than its controls.
What AI guardrails control
AI guardrails govern the topics an agent engages with, the tools it calls, the information it returns, and the actions it takes under specific conditions.
Leaders don’t need to configure every control. They do need to decide where the organization is exposed and what level of protection that exposure requires:
Input and tool-use boundaries: Define which systems, data sources, and tools an agent can access, along with the conditions for access. Without clear boundaries, an agent can reach systems, data, or tools its workflow was never meant to touch. The organization may not discover that access until it surfaces in an audit or incident.
Output safeguards: Inspect responses before they reach a user or downstream system. Every output reaches a customer, regulator, employee, or business system on the organization’s behalf. Without a safeguard in place, sensitive, prohibited, or noncompliant content may leave the workflow before anyone can intervene.
LLM-as-judge checks: Evaluate a proposed response, tool call, or action against defined criteria. These checks can catch context-dependent problems that fixed rules may miss. Because model-based checks can also make mistakes, leaders must decide when the potential consequences require deterministic rules or human approval.
Approval workflows: Route consequential actions to an authorized person before execution. Leaders must determine which decisions an agent can make independently and where human accountability must remain. A draft customer response may proceed automatically, while a refund, contract change, or employee-record update waits for approval.
Rate limits and spending ceilings: Restrict usage, retries, transactions, or cost over a defined period. These controls contain the financial and operational impact of an error before it becomes a large-scale event.
The right enforcement mechanism depends on how clearly a rule can be expressed and how costly or difficult to contain a mistake would be.
Control type
Best suited for
Example
Deterministic rule
Clear boundaries that must be enforced consistently
Evaluate whether a drafted response violates a communications policy
Human approval
Consequential, ambiguous, or difficult-to-reverse actions
Approve a refund, contract change, or employee-record update
Specificity is the point. A broad promise of “responsible AI” offers little protection when leaders haven’t defined what the agent may retrieve, change, send, or spend.
Match the controls to the risk
Uniform controls misallocate oversight. A summarization agent working with already-classified internal documents carries a different risk profile from an agent that can modify financial records or access employee health data.
Applying the strongest enforcement equally to both directs governance investment away from the agents whose failures would be hardest to contain or reverse. Guardrail risk tiering aligns each agent’s oversight with the consequences of failure.
Leaders should assess at least four factors:
The sensitivity of the data the agent can access.
The reach and reversibility of its actions.
The degree of autonomy it has before human intervention.
The financial, regulatory, and reputational impact of a failure.
Those factors can translate into a practical minimum-control framework:
Risk tier
Example agent
Minimum controls
Low
Summarizes approved internal documents without taking action
Approved data sources, basic input and output checks, usage monitoring
Medium
Drafts customer communications or updates low-sensitivity records
Scoped permissions, policy checks, complete tracing, defined escalation path
High
Modifies financial records, accesses regulated data, or commits funds
Deterministic limits, pre-execution evaluation, human approval, spending ceilings, immediate suspension and takeover controls
The exact thresholds will vary by organization. The important step is to connect each risk tier to enforceable minimum controls and clear review triggers.
Guardrails reduce risk. They don’t guarantee perfect behavior. Risk tiering makes governance investment defensible by showing why each agent received its level of oversight and where the organization placed its strongest controls.
That allocation is a business-risk decision. Leadership owns it.
Governance built in early strengthens accountability and speeds deployment
Some leaders worry that guardrails will slow down teams already under pressure to deliver. That usually happens when governance arrives as a manual review at the end of development.
Late security reviews force redesigns. Compliance questions surface after integrations are complete. Launch approvals stall because teams can’t explain what the agent accessed, why it chose an action, or how much a transaction can cost.
Governance built into deployment changes that sequence. Teams know the access model, risk tier, evidence requirements, and approval thresholds before they harden the workflow. Policies are applied consistently, and audit trails are produced during operation.
This requires leadership backing. An engineering team working alone can’t establish one governance standard across security, legal, compliance, operations, and business units. Leaders must make early governance part of the launch criteria.
Clear boundaries help teams move. They also ensure the organization can account for what each agent is permitted to do before it reaches production. Ambiguity creates rework and allows unclear authority to scale.
4 decisions leaders must make before launch
Leadership ownership centers on four explicit, enforceable decisions. Leaders don’t need to approve every prompt or tool call.
1. Name an accountable owner
Every production agent needs an accountable person who owns its performance, compliance, monitoring, and incident response. The owner needs enough authority to coordinate technical and business teams and enough proximity to understand the workflow’s impact.
2. Assign a risk tier
Classify the agent according to its access, autonomy, reach, and potential harm. Tie each tier to a defined minimum set of controls. Leaders should also identify which changes, such as adding a tool or expanding data access, trigger a new review.
3. Define escalation authority
Decide who can investigate, approve remediation, restrict permissions, initiate human takeover, roll back a release, or suspend the agent. Set thresholds for those actions before pressure and uncertainty distort the response.
4. Set a review cadence
Agent behavior, tools, models, users, and business scope change over time. A launch approval can’t cover every future version. Establish a recurring review of permissions, policy adherence, costs, performance, incidents, and business impact. Material changes should trigger an immediate reassessment.
The goal is controlled autonomy: every agent operates within boundaries the organization can explain, enforce, and defend. When ownership, risk tier, escalation authority, and review cadence are explicit, leaders can expand agentic AI with confidence that accountability will scale with it.
The next incident is a leadership test
The “How did this happen?” moment is avoidable. Runtime controls exist. Risk-tiering frameworks exist. Deployment practices that support traceability, approvals, and intervention already exist.
Leaders decide whether those capabilities become operating requirements before agents reach scale.
Boards and regulators are already asking how organizations govern AI. Leaders must explain who owns an agent, what it can do, how its actions are monitored, and how the company responds when performance moves outside approved boundaries. A vague assurance that the technical team has it covered will not hold.
Organizations that treat guardrails as a leadership design decision can expand agent autonomy with confidence. Organizations that leave the decision implicit eventually have it made for them by an audit, a budget overrun, or a customer incident.
AI guardrails are runtime policies and controls that limit what an AI system can access, generate, and do. They can include tool restrictions, output filters, policy checks, approval workflows, rate limits, and spending ceilings.
Who is responsible for AI guardrails?
Business and technology leaders are accountable for defining acceptable risk, ownership, escalation authority, and review requirements. Engineering, security, legal, and compliance teams translate those decisions into enforceable controls and operating processes.
Do AI guardrails slow down deployment?
They can add latency or review steps to individual workflows. When incorporated early, they often shorten the overall path to production by reducing redesign, clarifying launch requirements, and making approvals easier to complete.
Does every AI agent need the same guardrails?
No. Controls should reflect the agent’s data access, autonomy, action scope, and potential impact. Low-risk internal tools may need lightweight checks. Agents that can alter sensitive records, communicate externally, or commit funds require stronger controls and fuller auditability.
How often should AI guardrails be reviewed?
Review them on a standing cadence and whenever the agent’s model, tools, permissions, users, or business scope change. Cost spikes, policy violations, unusual behavior, and incidents should also trigger immediate review.
What if your predictive AI investments could start delivering agentic AI value now? According to DataRobot Chief Product Officer Venky Veeraraghavan and Dell Technologies Senior Director of AI Solutions Brad Maltz, they can. And now is the time to go after it.
Production models, clean data pipelines, optimization engines, and governance controls give agents the grounded business context they need to drive faster decisions and measurable outcomes. An orchestration and reasoning layer can connect these capabilities across teams, systems, and data silos, turning predictions into coordinated action.
In a recent DataRobot and Dell Technologies webinar, Veeraraghavan and Maltz explain how enterprises can build on the AI capabilities they already have and move quickly from predictive insights to agentic outcomes.
Agentic AI activates intelligence your business already has
Agentic AI demos can make the technology feel magical: a chat interface appears to understand any request, navigate an entire workflow, and produce an answer. Inside the enterprise, the opportunity is practical and much closer than it appears.
Predictive AI already handles the hard analytical work. Models generate forecasts, scores, and recommendations within larger workflows that drive business outcomes. People interpret those outputs, consult dashboards, evaluate tradeoffs, run scenarios, coordinate across teams, and decide what happens next. Veeraraghavan calls this layer of interpretation and coordination “human middleware.”
As Veeraraghavan explains, the data and models at the center of these workflows provide the foundation for agentic AI. Agents connect that intelligence to the reasoning, coordination, and decision-making required to produce an outcome.
Agents accelerate the work surrounding the prediction. They interpret intent, break goals into smaller problems, call the appropriate data and analytical tools, synthesize the results, and surface a recommendation or exception to the person accountable for the outcome.
Language models provide flexible reasoning and orchestration. Enterprise data, predictive models, mathematical models, business rules, and optimization systems provide grounded, often deterministic answers. Combined in an agentic workflow, they create an adaptive path from business question to action.
Your existing AI investments already hold valuable intelligence. Agentic orchestration extends that intelligence across the decisions and actions that drive business results.
Three kinds of agentic AI. One offers the clearest path to hard ROI.
Agentic AI creates value at three levels, each with a different degree of impact, measurability, and strategic reach.
1. Productivity agents and copilots
These tools help individuals create presentations, analyze information, write emails, and complete routine work faster. The productivity gain is real, but its financial impact can be difficult to quantify. Saving a few minutes on an email does not translate cleanly into revenue, margin, or reduced risk.
2. Line-of-business agents
These agents accelerate established workflows inside platforms such as Salesforce, SAP, ServiceNow, and Workday. They can process expense reports, resolve service tickets, and complete other structured tasks more efficiently. Their impact is easier to measure, although it typically remains contained within one application, process, or function.
3. Agent workforces
Agent workforces put agents at the center of consequential business workflows. They coordinate data, predictive models, optimization engines, applications, and human expertise around a defined outcome. Their impact can be measured through the business metrics leaders already track, including revenue, margin, operational efficiency, and risk.
Veeraraghavan connects this third category to the growing demand for demonstrable returns from enterprise AI investments. This is where existing predictive AI investments can compound.
Much of the analytical foundation may already be in place, including enterprise data, sensors, models, and optimization logic. Agentic orchestration connects those assets across the workflow, shortening the path from intelligence to decision to measurable business impact.
Agentic AI is already changing operational outcomes
Chevron is applying agentic AI to a high-stakes challenge: protecting people during gas leaks and other anomalies at industrial facilities.
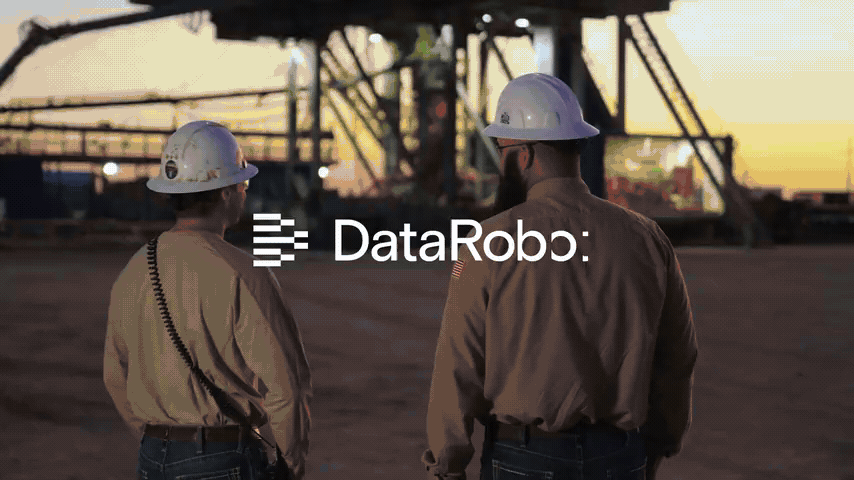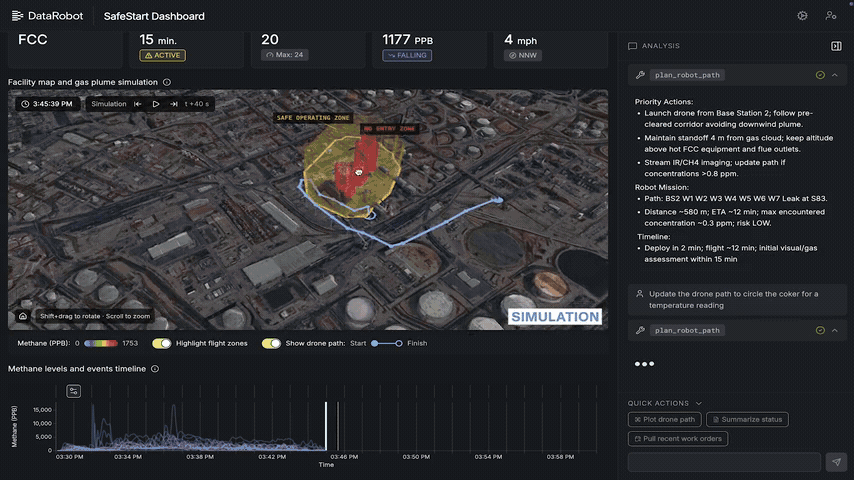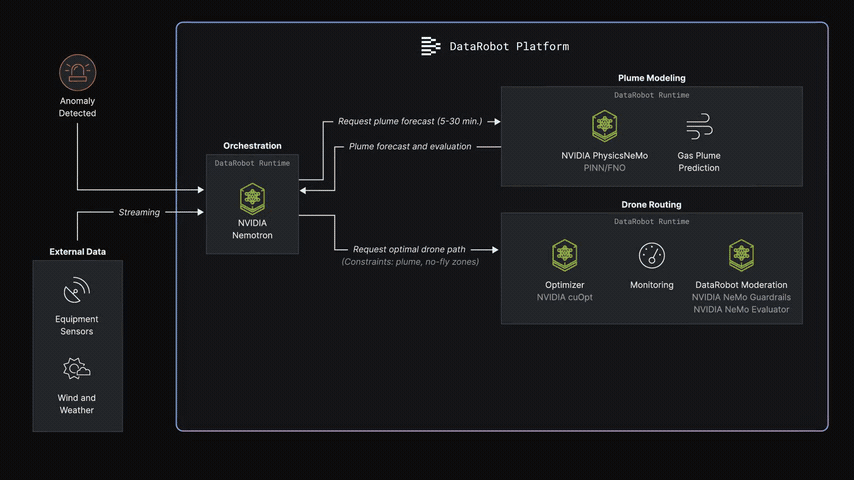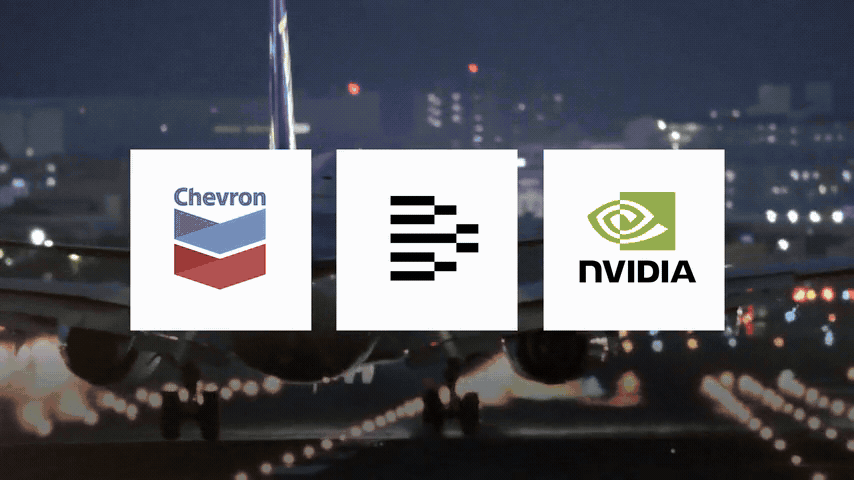
IoT sensors detect the anomaly. Models project how the gas plume will move under local weather conditions. An optimization engine directs tasks away from danger. An agentic application brings these capabilities together, allowing operators to evaluate scenarios and coordinate a response in near real time.
Speed matters. Electrical and mechanical drones can ignite leaking gas, while sending people into the affected area creates additional risk. Agentic orchestration gives operators a faster way to determine where the gas is moving, which equipment can operate safely, and how the response should adapt.
A technology company is applying the same pattern to supply-chain volatility. Quarterly forecasts and planning cycles could no longer keep pace with shifting demand, new technologies, logistics constraints, and changing customer priorities.
The company uses an agent to orchestrate its existing predictive models, what-if analysis, and optimization tools. A planner can evaluate what happens when inventory moves to another customer, compare delivery times and profit margins, and optimize for competing priorities such as meeting quarterly targets or protecting strategic accounts. Supply-chain and sales operations teams can then assess disruptions together and respond faster.
Both examples build on capabilities already in place: enterprise data, sensors, predictive models, and optimization logic. Agentic orchestration connects those assets in a responsive decision system, accelerating the path from signal to analysis to action.
Three things to get right as you make the transition
Moving from predictive to agentic AI requires clear decisions about where to invest, how to architect the system, and which opportunities to pursue. These three principles can help enterprises focus resources on measurable value while building the flexibility to evolve.
1. Think value, not tokens
A cost strategy should start with two questions: What should run, and where should it run?
The answer may combine frontier and open-weight models across cloud, on-premises, deskside, and edge infrastructure. A complex reasoning task may justify a frontier model, while a smaller open-weight model may handle a simple, repetitive step more efficiently. Data sensitivity, latency, quality, and control all shape the economics. Maltz noted that, for some workloads, on-premises or deskside approaches can reach break-even against hosted environments within months.
2. Build a model strategy, not a model choice
The model landscape is changing too quickly to make one provider or model the permanent answer to every task. Treat models as a portfolio. Route each request according to the criteria that matter for that step, including quality, cost, latency, data sensitivity, and deployment requirements.
This approach also keeps the architecture open to improvement. A predictive model can remain a tool the agent calls today and be replaced later when a better option emerges. The workflow continues delivering value as its individual components evolve.
3. Pick outcomes, not processes
The highest-value opportunities often span several teams, systems, and data silos. Consider outcomes such as responding to a supply-chain disruption, completing a know-your-customer review, protecting plant safety, or optimizing a tariff decision.
Work backward from the outcome. What data grounds the agent? Which models, applications, and business rules must it call? What actions can it take? Where should a subject-matter expert approve, intervene, or handle an exception? These questions reveal where agentic orchestration can produce meaningful business impact.
Build on the foundation already in place
Enterprise readiness for agentic AI already exists across production models, governed data, domain expertise, business applications, infrastructure, and years of operational learning. Connecting these capabilities around a high-value outcome creates a practical path forward.
Start with predictive systems you trust and make them available to agents as tools. Add controls, observability, and human oversight. Measure performance through business outcomes, then improve individual components as the workflow evolves.
DataRobot’s recognition as a Leader in the Gartner® Magic Quadrant™ for Data Science and Machine Learning Platforms for the third consecutive year reinforces the maturity of this foundation. Production-grade agentic AI is ready to move from experimentation into consequential business workflows.
Enterprises with useful predictive models and trustworthy data may already have the foundation they need. Agentic orchestration can turn those investments into coordinated action and measurable value.
Every agent you deploy expands your blast radius. A predictive model can produce a bad response, but an agent can act on it.
Agents can retrieve sensitive data, change systems of record, trigger workflows, or pass errors to other agents. The risk is no longer just model quality. It is the authority an agent holds, the systems it can reach, and how quickly a failure can spread.
Eliminating autonomy isn’t the answer. Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The goal is controlled autonomy: enough authority to create value, with behavior that remains bounded, observable, and interruptible.
CIOs and AI leaders should be able to ask six questions about every production agent and receive clear, evidence-backed answers:
Which agent acted?
What was it authorized to do?
Which data, tools, and systems did it use?
Which policies governed the action?
Can we reconstruct its actions and reverse-engineer the outcome?
Who can intervene right now?
You don’t need to implement every control yourself. But you do need to know what to ask your teams, what “done” looks like, and what risk the organization is accepting when an answer remains unclear.
The first 30 days should establish the controls needed to answer these questions without launching a new investigation. Define the agent. Limit its authority. Track its actions. Test its boundaries. Give someone the power to stop it. Governance will mature over time, but production agents should never operate on trust alone.
Key takeaways
Treat every AI agent as a distinct enterprise actor with a named owner, defined purpose, and bounded scope.
Give agents only the data, tools, and actions required for that scope. Make access attributable and revocable.
Enforce high-impact boundaries through deterministic runtime controls rather than relying on model instructions alone.
Record the complete execution path so teams can reconstruct what the agent did and determine why.
Test failure conditions as seriously as the happy path, and assign people who can investigate, suspend, and safely restore the agent.
Phase
Leadership question
What “done” looks like
Days 1–5
Can you identify the agent and its authority?
Every agent has a unique identity, owner, bounded scope, and system inventory.
Days 6–10
Can you confirm permissions are enforced at runtime?
Every tool and action maps to a defined, attributable, and revocable permission.
Days 11–15
Are high-impact actions governed outside the model?
Deterministic controls block, redirect, or escalate actions that violate policy.
Days 16–20
Can your teams reconstruct every consequential action?
Teams can trace a complete run from request through downstream effects.
Days 21–25
Does the agent fail safely beyond the happy path?
Known failure modes are documented, tested, and reflected in policy thresholds.
Days 26–30
Can named owners stop and restore the agent?
Named owners can suspend, investigate, and safely restore the agent.
Days 1–5: Can you identify the agent and its authority?
You can’t govern “the customer service agent” or “the finance copilot” as an informal concept. Every production agent needs a distinct identity and a precise definition of what it’s authorized to do.
Create an agent record that captures:
A unique identity, named owner, business purpose, and risk classification
The models, tools, APIs, data sources, and downstream systems it uses
The actions it may recommend, initiate, approve, or never perform
Its escalation boundaries and conditions for human intervention
Specificity is the key. Define the scope in specific, enforceable terms: “Retrieve approved knowledge-base content, summarize account history, and draft responses for human approval.” This gives security, compliance, and engineering teams clear boundaries they can implement and enforce.
Document negative scope, too. Can the agent issue refunds? Change account entitlements? Retrieve payment data? Contact a customer without approval? Unclear answers signal unresolved production risk.
Milestone: Every agent has an identity, owner, explicit action boundary, and inventory of connected resources.
Days 6–10: Can you confirm permissions are enforced at runtime?
An agent’s documented scope matters only if the organization can enforce it when the agent acts.
Identity establishes which actor is operating. Authorization determines what that actor is allowed to do. Apply least-privilege access based on the agent’s assigned task, not the broadest workflow it may eventually support. Separate read, write, execute, and administrative permissions. Permission to retrieve a record should not automatically include permission to modify or delete it.
Apply the strictest authorization requirements to high-impact capabilities, including:
Writes to systems of record
Financial transactions
Access to sensitive data
External communications
Code execution
Tools exposed through Model Context Protocol (MCP) servers or other agent interfaces
Avoid shared service accounts. They obscure attribution and make access reviews unreliable. Use agent-specific credentials, short-lived tokens, conditional access, and explicit tool allowlists where possible.
Define the exception process in advance. Specify who can approve temporary elevation, how long it can remain active, and which actions always require human approval. Authorization should fail closed. If identity or operating context cannot be verified, or an action cannot be evaluated against policy, the agent should stop or escalate rather than improvise.
Milestone: Every tool call is evaluated against defined permissions. Elevated access is conditional and time-bound, and every exception has a designated approver and expiration.
Days 11–15: Are high-impact actions governed outside the model?
This is where controlled autonomy becomes operational: the model can propose an action, but it cannot decide for itself whether that action is permitted.
Permissions and guardrails address different risks. Permissions define what an agent can access. Guardrails constrain how the agent can use that access. Guardrails are enforced through validation, policy checks, and other controls placed throughout the workflow.
Apply policy checks throughout the workflow, not only to the final response. Inspect user inputs, retrieved context, model outputs, tool arguments, and proposed actions for personally identifiable information, prompt injection, unsafe content, policy violations, and prohibited behavior. A final-output review alone does not govern the steps where the agent reads sensitive data, constructs tool calls, or initiates consequential actions.
Prompt instructions such as “never reveal sensitive data” are not sufficient. Malicious or conflicting instructions can enter through user input, retrieved documents, tool output, or another agent. Enforce guardrails at the boundaries between the agent and the resources it can read, modify, or affect.
For high-impact actions, use deterministic policy checks outside the model. Before a tool executes, validate transaction limits, approved recipients, required fields, data classifications, and human approval requirements. The model may propose an action, but the policy layer decides whether the system permits it.
Milestone: Policy checks run before sensitive data crosses a boundary or a high-impact action executes. Failed checks trigger a defined block, fallback, or escalation.
Days 16–20: Can your teams reconstruct every consequential action?
Governance depends on being able to reconstruct what an agent did, why it did it, and what happened next. Final outputs are not enough. Teams need visibility into the full execution path, including the information the agent received, the tools it called, the permissions and policy checks applied, and the actions that affected downstream systems.
Capture the key elements of each run:
The original request, system instructions, model version, and policy version
Retrieved context, tool calls, permission decisions, and executed actions
Downstream effects, human approvals, overrides, and interventions
Use correlation identifiers to connect activity across tools, systems, and agents. Protect logs from tampering, define appropriate retention periods, and limit access to audit data. Logging should improve accountability without creating a new repository of exposed sensitive information.
Operational monitoring should focus on signals that indicate misuse, failure, or drift. Track access violations, abnormal tool activity, repeated retries, latency spikes, cost anomalies, and policy exceptions. Route each signal to a team with the authority and responsibility to investigate. A dashboard without a named owner does not provide meaningful oversight.
Milestone: Security, platform, and compliance teams can reconstruct any consequential agent run from the original request through its downstream effects. Actionable anomaly alerts are routed to named owners.
Days 21–25: Does the agent fail safely beyond the happy path?
The happy path proves that the agent can complete its intended workflow when inputs are clear, data is accurate, tools are available, and policies align. Governance testing must also prove that it fails safely when those conditions break down.
Test ambiguous requests, incomplete records, conflicting policies, unavailable tools, stale data, malicious retrieved content, and attempts to exceed authority. Include multi-step scenarios in which an apparently harmless first action creates risk later in the workflow.
Measure both failure modes: controls that are too weak and controls that are too restrictive. Weak controls create exposure. Overly restrictive controls reduce utility, increase unnecessary escalations, and prevent adoption.
Use early deployments to tune policy thresholds, escalation logic, and intervention triggers. Track task success alongside blocked actions, override rates, false positives, escalation time, and action reversibility.
Milestone: The agent succeeds on representative happy-path workflows, passes adversarial and boundary testing, and has documented failure modes and policy thresholds that reflect an explicit risk-value tradeoff.
Days 26–30: Can named owners stop and restore the agent?
Governance fails when everyone is responsible in principle and no one is accountable in practice.
Name owners for agent performance, access, compliance, monitoring, and incident response. Define who investigates anomalies, who approves remediation, and who has the authority to suspend the agent.
Document rollback, credential revocation, tool isolation, kill switch activation, human takeover, evidence preservation, and post-incident review. Then rehearse the process. A kill switch that has never been tested is only a theory.
Set a review cadence for permissions, policy compliance, operational performance, and business impact. Agent scope, connected tools, and policies will change. Governance must detect that drift before it becomes an incident.
Milestone: Named owners can suspend, investigate, and safely restore the agent through a tested process with clear decision rights.
What operational governance looks like after 30 days
After 30 days, your teams should be able to answer the six questions above with current records and operational evidence. If an answer depends on institutional memory or an unmaintained spreadsheet, the control is not operational.
This isn’t a complete governance program. It is the foundation for one. Start by making each agent legible, bounded, observable, and interruptible. As your agent footprint expands, these controls will require centralized automation.
Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The first 30 days establish the middle path: controlled autonomy that can earn trust and scale.
Every agent you deploy expands your blast radius. A predictive model can produce a bad response, but an agent can act on it.
Agents can retrieve sensitive data, change systems of record, trigger workflows, or pass errors to other agents. The risk is no longer just model quality. It is the authority an agent holds, the systems it can reach, and how quickly a failure can spread.
Eliminating autonomy isn’t the answer. Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The goal is controlled autonomy: enough authority to create value, with behavior that remains bounded, observable, and interruptible.
CIOs and AI leaders should be able to ask six questions about every production agent and receive clear, evidence-backed answers:
Which agent acted?
What was it authorized to do?
Which data, tools, and systems did it use?
Which policies governed the action?
Can we reconstruct its actions and reverse-engineer the outcome?
Who can intervene right now?
You don’t need to implement every control yourself. But you do need to know what to ask your teams, what “done” looks like, and what risk the organization is accepting when an answer remains unclear.
The first 30 days should establish the controls needed to answer these questions without launching a new investigation. Define the agent. Limit its authority. Track its actions. Test its boundaries. Give someone the power to stop it. Governance will mature over time, but production agents should never operate on trust alone.
Key takeaways
Treat every AI agent as a distinct enterprise actor with a named owner, defined purpose, and bounded scope.
Give agents only the data, tools, and actions required for that scope. Make access attributable and revocable.
Enforce high-impact boundaries through deterministic runtime controls rather than relying on model instructions alone.
Record the complete execution path so teams can reconstruct what the agent did and determine why.
Test failure conditions as seriously as the happy path, and assign people who can investigate, suspend, and safely restore the agent.
Phase
Leadership question
What “done” looks like
Days 1–5
Can you identify the agent and its authority?
Every agent has a unique identity, owner, bounded scope, and system inventory.
Days 6–10
Can you confirm permissions are enforced at runtime?
Every tool and action maps to a defined, attributable, and revocable permission.
Days 11–15
Are high-impact actions governed outside the model?
Deterministic controls block, redirect, or escalate actions that violate policy.
Days 16–20
Can your teams reconstruct every consequential action?
Teams can trace a complete run from request through downstream effects.
Days 21–25
Does the agent fail safely beyond the happy path?
Known failure modes are documented, tested, and reflected in policy thresholds.
Days 26–30
Can named owners stop and restore the agent?
Named owners can suspend, investigate, and safely restore the agent.
Days 1–5: Can you identify the agent and its authority?
You can’t govern “the customer service agent” or “the finance copilot” as an informal concept. Every production agent needs a distinct identity and a precise definition of what it’s authorized to do.
Create an agent record that captures:
A unique identity, named owner, business purpose, and risk classification
The models, tools, APIs, data sources, and downstream systems it uses
The actions it may recommend, initiate, approve, or never perform
Its escalation boundaries and conditions for human intervention
Specificity is the key. Define the scope in specific, enforceable terms: “Retrieve approved knowledge-base content, summarize account history, and draft responses for human approval.” This gives security, compliance, and engineering teams clear boundaries they can implement and enforce.
Document negative scope, too. Can the agent issue refunds? Change account entitlements? Retrieve payment data? Contact a customer without approval? Unclear answers signal unresolved production risk.
Milestone: Every agent has an identity, owner, explicit action boundary, and inventory of connected resources.
Days 6–10: Can you confirm permissions are enforced at runtime?
An agent’s documented scope matters only if the organization can enforce it when the agent acts.
Identity establishes which actor is operating. Authorization determines what that actor is allowed to do. Apply least-privilege access based on the agent’s assigned task, not the broadest workflow it may eventually support. Separate read, write, execute, and administrative permissions. Permission to retrieve a record should not automatically include permission to modify or delete it.
Apply the strictest authorization requirements to high-impact capabilities, including:
Writes to systems of record
Financial transactions
Access to sensitive data
External communications
Code execution
Tools exposed through Model Context Protocol (MCP) servers or other agent interfaces
Avoid shared service accounts. They obscure attribution and make access reviews unreliable. Use agent-specific credentials, short-lived tokens, conditional access, and explicit tool allowlists where possible.
Define the exception process in advance. Specify who can approve temporary elevation, how long it can remain active, and which actions always require human approval. Authorization should fail closed. If identity or operating context cannot be verified, or an action cannot be evaluated against policy, the agent should stop or escalate rather than improvise.
Milestone: Every tool call is evaluated against defined permissions. Elevated access is conditional and time-bound, and every exception has a designated approver and expiration.
Days 11–15: Are high-impact actions governed outside the model?
This is where controlled autonomy becomes operational: the model can propose an action, but it cannot decide for itself whether that action is permitted.
Permissions and guardrails address different risks. Permissions define what an agent can access. Guardrails constrain how the agent can use that access. Guardrails are enforced through validation, policy checks, and other controls placed throughout the workflow.
Apply policy checks throughout the workflow, not only to the final response. Inspect user inputs, retrieved context, model outputs, tool arguments, and proposed actions for personally identifiable information, prompt injection, unsafe content, policy violations, and prohibited behavior. A final-output review alone does not govern the steps where the agent reads sensitive data, constructs tool calls, or initiates consequential actions.
Prompt instructions such as “never reveal sensitive data” are not sufficient. Malicious or conflicting instructions can enter through user input, retrieved documents, tool output, or another agent. Enforce guardrails at the boundaries between the agent and the resources it can read, modify, or affect.
For high-impact actions, use deterministic policy checks outside the model. Before a tool executes, validate transaction limits, approved recipients, required fields, data classifications, and human approval requirements. The model may propose an action, but the policy layer decides whether the system permits it.
Milestone: Policy checks run before sensitive data crosses a boundary or a high-impact action executes. Failed checks trigger a defined block, fallback, or escalation.
Days 16–20: Can your teams reconstruct every consequential action?
Governance depends on being able to reconstruct what an agent did, why it did it, and what happened next. Final outputs are not enough. Teams need visibility into the full execution path, including the information the agent received, the tools it called, the permissions and policy checks applied, and the actions that affected downstream systems.
Capture the key elements of each run:
The original request, system instructions, model version, and policy version
Retrieved context, tool calls, permission decisions, and executed actions
Downstream effects, human approvals, overrides, and interventions
Use correlation identifiers to connect activity across tools, systems, and agents. Protect logs from tampering, define appropriate retention periods, and limit access to audit data. Logging should improve accountability without creating a new repository of exposed sensitive information.
Operational monitoring should focus on signals that indicate misuse, failure, or drift. Track access violations, abnormal tool activity, repeated retries, latency spikes, cost anomalies, and policy exceptions. Route each signal to a team with the authority and responsibility to investigate. A dashboard without a named owner does not provide meaningful oversight.
Milestone: Security, platform, and compliance teams can reconstruct any consequential agent run from the original request through its downstream effects. Actionable anomaly alerts are routed to named owners.
Days 21–25: Does the agent fail safely beyond the happy path?
The happy path proves that the agent can complete its intended workflow when inputs are clear, data is accurate, tools are available, and policies align. Governance testing must also prove that it fails safely when those conditions break down.
Test ambiguous requests, incomplete records, conflicting policies, unavailable tools, stale data, malicious retrieved content, and attempts to exceed authority. Include multi-step scenarios in which an apparently harmless first action creates risk later in the workflow.
Measure both failure modes: controls that are too weak and controls that are too restrictive. Weak controls create exposure. Overly restrictive controls reduce utility, increase unnecessary escalations, and prevent adoption.
Use early deployments to tune policy thresholds, escalation logic, and intervention triggers. Track task success alongside blocked actions, override rates, false positives, escalation time, and action reversibility.
Milestone: The agent succeeds on representative happy-path workflows, passes adversarial and boundary testing, and has documented failure modes and policy thresholds that reflect an explicit risk-value tradeoff.
Days 26–30: Can named owners stop and restore the agent?
Governance fails when everyone is responsible in principle and no one is accountable in practice.
Name owners for agent performance, access, compliance, monitoring, and incident response. Define who investigates anomalies, who approves remediation, and who has the authority to suspend the agent.
Document rollback, credential revocation, tool isolation, kill switch activation, human takeover, evidence preservation, and post-incident review. Then rehearse the process. A kill switch that has never been tested is only a theory.
Set a review cadence for permissions, policy compliance, operational performance, and business impact. Agent scope, connected tools, and policies will change. Governance must detect that drift before it becomes an incident.
Milestone: Named owners can suspend, investigate, and safely restore the agent through a tested process with clear decision rights.
What operational governance looks like after 30 days
After 30 days, your teams should be able to answer the six questions above with current records and operational evidence. If an answer depends on institutional memory or an unmaintained spreadsheet, the control is not operational.
This isn’t a complete governance program. It is the foundation for one. Start by making each agent legible, bounded, observable, and interruptible. As your agent footprint expands, these controls will require centralized automation.
Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The first 30 days establish the middle path: controlled autonomy that can earn trust and scale.
Governing 5 agents is a review process. Governing 500 agents is an infrastructure problem.
Manual reviews and team-level approvals work when a handful of agents are visible and closely watched. Once agents spread across business units, tools, and environments, that oversight breaks down.
Enterprises need an AI agent governance model that includes centralized identity, reusable policies, and enforcement that holds across the whole agent workforce.
Key takeaways
At scale, AI agent governance must move from one-off approvals to centralized controls that hold across every agent, team, and environment.
Manual review breaks when agents spread across teams, tools, data sources, and environments.
Governing an agent workforce requires centralized agent identity, policy propagation, and cross-environment enforcement.
AI agent governance teams need visibility into agents, prompts, tools, Model Context Protocol (MCP) servers, data sources, permissions, and runtime behavior.
Enterprises should build AI agent governance controls before agent sprawl reaches production scale.
Why governance changes as the agent workforce grows
A small number of AI agents can be governed through direct review. Teams can document purpose, inspect prompts, approve tool access, monitor usage, and revisit an agent when something changes.
The challenge escalates as the AI agent workforce expands across business units and systems. Consider a healthcare scheduling agent connected to an electronic health record, appointment platform, and patient communications system. One version may be approved to read scheduling data and send reminders. Another may inherit broader access, use an unapproved model, or route protected health information into the wrong workflow.
Across dozens of agents, a single permission change, tool update, or policy gap can spread before anyone sees it.
The consequences extend far beyond governance operations. A small configuration error can expose sensitive data, disrupt services, trigger an audit, and force expensive remediation across multiple systems. As the agent workforce grows, teams must manage thousands of relationships among agents, tools, data, identities, policies, and environments while keeping controls consistent as the system changes.
Where manual governance breaks first
Governing an agent workforce should begin during design and prototyping, before agents spread across teams and production environments. Retrofitting identity, inventory, policy enforcement, and monitoring after deployment adds cost, disruption, and control gaps.
Where governance breaks
What happens at enterprise scale
What enterprises need
Inventory
Agents appear across teams, tools, and environments without a complete record. For example, a governance team may set out to catalog 30 agents and uncover 120 prototypes running in approved platforms, notebooks, internal apps, automation tools, and third-party services.
A living registry of every agent, owner, business purpose, deployment environment, and connected component.
Identity
Shared credentials, broad service accounts, inherited human access, and agent-to-agent handoffs make it difficult to determine who acted and under what authority.
A unique identity for every agent, tied to scoped permissions, approved tools, data access, and business purpose.
Policy consistency
Teams interpret the same rule differently, and controls may apply in one workflow or environment but not another.
Central policies that propagate across the agent workforce based on risk, data sensitivity, business purpose, and environment.
Environment drift
Controls can weaken or disappear as agents move through development, staging, production, cloud, on-premises, or third-party platforms.
Cross-environment enforcement that keeps identity, permissions, monitoring, and review requirements intact throughout the lifecycle.
What does governance infrastructure for an agent workforce need to include?
Governance at the scale of an agent workforce requires infrastructure that manages individual agents and coordinates the system around them. An agent is like a machine on a factory floor: teams still need to inspect it, tune it, replace faulty parts, and verify that it operates safely.
At enterprise scale, maintenance is only part of the job. Teams also need to know how each machine connects to the production line, which inputs it can use, which actions it can take, and how the system responds when conditions change.
For agent systems, that means governing prompts, tools, MCP servers, vector databases, data sets, guardrails, APIs, downstream workflows, and predictive and generative models — including the LLMs that power agent reasoning — through a shared control layer.
Governance area
What teams need to control
Agent registry
Which agents exist, who owns them, and where they run
Agent identity
How each agent is authenticated, authorized, and tracked
Policy propagation
Which rules apply across agents, tools, data, and environments
Permission scope
What each agent can read, write, update, delete, or trigger
Tool access
Which tools, APIs, MCP servers, and workflows each agent can invoke
Component lineage
Which prompts, models, data sources, and versions each agent uses
Runtime enforcement
Which actions are blocked, escalated, logged, or allowed
Monitoring
Which behaviors indicate drift, misuse, cost spikes, or policy violations
Audit trails
What the agent saw, selected, called, returned, decided, and did
Review triggers
Which changes require reapproval before continued use
This infrastructure gives enterprises a practical way to scale agents without relying on scattered spreadsheets, one-off approvals, or disconnected logs.
Three of these areas are worth unpacking. Agent identity, policy propagation, and cross-environment enforcement are what separate governance that works for one agent from governance that holds up across hundreds of them.
How does centralized agent identity work?
You can’t scope permissions, propagate policy, or attribute actions without first assigning every agent a durable, unique identity. Agent identity gives every agent a durable record and a controlled way to act. That record should connect the agent to its owner, business purpose, risk tier, approved tools, data access, deployment environment, and review history.
For example, a procurement agent may compare vendor quotes and draft a recommendation while remaining blocked from approving purchases or changing supplier records.
Identity also separates user authority from agent authority. A human user may have access to a system, but an agent acting on that user’s behalf should still operate within its own approved scope.
Centralized identity also needs to persist across agent-to-agent workflows. When one agent delegates a task to another, governance teams need to know which agent initiated the handoff, what data and instructions moved with it, and what authority the receiving agent was allowed to exercise. Each agent should enforce its own permissions while the system preserves a trace of the full delegation chain. Otherwise, a routine handoff can unexpectedly expand access, drop an important constraint, or make responsibility difficult to reconstruct.
This distinction becomes critical at enterprise scale. When hundreds of agents act across systems and delegate work to one another, security and governance teams need to attribute behavior to specific agents, detect anomalous access patterns, trace handoffs, and revoke permissions without disrupting unrelated workflows.
What is policy propagation and why does it matter?
Policy propagation turns governance rules into reusable controls across the agent workforce. A policy might define which data classes an agent can access, which tools require human approval, which actions are prohibited, which logs must be captured, or which environments can run high-risk workflows.
At the scale of an agent workforce, these rules should be applied centrally and inherited by the right agents based on risk tier, business purpose, environment, and data sensitivity. A high-risk HR agent, for example, should inherit stricter review, logging, and bias monitoring requirements than a low-risk internal documentation agent.
Policy propagation also helps teams manage change. If a new regulatory requirement affects agents that process personal data, governance teams should be able to identify impacted agents, update the relevant policy, apply it across environments, and verify enforcement.
Without reusable policy controls, each agent becomes its own governance project. That’s not only exhausting for AI, security, and governance teams; it also creates inconsistent enforcement, missed controls, and real operational risk as the agent workforce grows.
How does cross-environment enforcement reduce production risk?
Cross-environment enforcement ensures that governance controls — identity, approved scope, policy requirements, monitoring rules, and audit expectations — move with an agent across development, staging, and production, as well as across cloud, on-premises, and third-party platforms.
Agents don’t stay still: they connect to new tools, switch models, receive prompt updates, and expand into new workflows.
This is especially important for enterprises that run agents across multiple clouds, on-premises systems, and third-party platforms. A governance program tied to only one deployment environment leaves gaps wherever agents are built or deployed elsewhere.
Cross-environment enforcement should cover access, tool invocation, parameter constraints, guardrails, logging, escalation, and review triggers. It should also prevent unapproved changes from silently expanding what an agent can do.
What leaders should ask before agent growth outruns the governance model
Informal governance starts to strain as agents spread across teams, environments, and business processes. Before growth outruns the governance model, leaders should confirm that the organization can answer these questions:
Do we have a central registry of every agent and connected component?
Does each agent have a named owner, business purpose, and risk tier?
Does every agent have a unique identity with scoped permissions?
Can we enforce reusable policies across teams, environments, and deployment platforms?
Can we see which tools, MCP servers, APIs, data sources, and workflows each agent can access?
Do we track prompts, models, tools, vector databases, data sets, and retrieval sources as versioned components?
Can we detect permission drift, policy violations, retry loops, cost spikes, and anomalous behavior?
Can we reconstruct an agent’s decision path, including context, tool calls, parameters, returns, and outcomes?
Do prompt, model, tool, workflow, or permission changes trigger reapproval?
Can we retire one agent and revoke its access without disrupting the broader agent workforce?
Weak answers signal that agent growth is outpacing the governance model. Strong answers give AI, security, governance, and business teams the control infrastructure required for production scale.
Govern your agent workforce before scale becomes sprawl
Agentic AI can create real business value, but production scale requires more than architecture and deployment. Enterprises need governance mechanics that hold up when agents spread across teams, systems, and environments.
The shift from 5 agents to 500 agents changes the job. Centralized identity, policy propagation, cross-environment enforcement, monitoring, auditability, and lifecycle review become the operating foundation.
Agent workforce governance, sometimes called AI agent governance, is the practice of managing many AI agents through centralized controls for identity, ownership, permissions, policy enforcement, monitoring, auditability, and lifecycle review.
Why are 5 agents and 500 agents different governance problems?
A small number of agents can often be reviewed manually. Hundreds of agents require infrastructure for centralized identity, reusable policies, cross-environment enforcement, runtime monitoring, and audit trails across the agent workforce.
When should enterprises start planning for agent workforce governance?
Enterprises should start during design and prototyping, before agents move into broad production use. Manual reviews, scattered inventories, and team-level policy enforcement become harder to sustain as an agent workforce expands across teams and environments.
What should enterprises track for every AI agent?
Enterprises should track owner, business purpose, identity, risk tier, model, prompts, tools, MCP servers, data sources, permissions, deployment environment, monitoring signals, audit logs, and review triggers.
What is the biggest risk of an unmanaged agent workforce?
The biggest risk is uncontrolled agent sprawl. Agents may gain unauthorized access, operate under inconsistent policies, drift after system changes, or take actions that teams cannot reconstruct after an incident.
Enterprises can govern model context protocol (MCP) connections at scale by treating them as part of the agentic AI control plane. Every MCP server, exposed tool, permission, and agent relationship needs ownership, scope, monitoring, and auditability before it supports autonomous work.
MCP governance is the discipline of controlling how AI agents discover, select, invoke, and compose external tools through MCP connections. It gives enterprises a way to manage the point where agent reasoning becomes action.
Let’s explore the governance risks MCP connections create, how agent autonomy expands enterprise attack surfaces, the control points where planning becomes execution, and the governance practices that keep MCP connections auditable and bounded.
Key takeaways
MCP gives agentic systems a standard way to invoke tools, execute actions, and observe outcomes inside autonomous workflows.
Every MCP connection expands the agent’s decision surface, including tool selection, parameter binding, return handling, and downstream action.
Governance teams need visibility into MCP servers, exposed tools, connected agents, decision constraints, and invocation patterns.
MCP governance should include ownership, scoped permissions, runtime monitoring, audit trails, access reviews, and reapproval triggers.
The biggest risk of unmanaged MCP connections is uncontrolled agent autonomy inside enterprise systems.
What is MCP in agentic AI?
Model context protocol is the invocation standard that lets agentic systems reach external tools, execute actions, and observe outcomes inside autonomous workflows. MCP sits between the agent’s planning layer and the systems it can invoke.
At a technical level, MCP uses a host-client-server architecture. The host is the AI application, the client manages the connection, and the MCP server exposes capabilities such as tools, resources, and prompts. In enterprise environments, the highest-risk capabilities are usually tools because tools let agents query databases, call APIs, update records, trigger workflows, or perform computations.
This changes how agents operate. A support agent can plan a response, retrieve ticket history, make updates, and coordinate follow-up actions in one loop. A developer agent can reason about code repositories, run tests, and plan deployments. A finance agent can retrieve reports, trigger approvals, and track outcomes.
Once an agent can execute MCP tools, enterprises need to know what the agent is authorized to reach, what decisions it should make, which tools it actually invokes, and whether its decision trace can be reviewed.
Why do MCP connections create governance risk?
MCP connections create risk by giving agents a structured invocation surface inside their planning loops. Once an agent can invoke an MCP server, it may retrieve context, call functions, trigger actions, and incorporate tool returns into subsequent planning steps, often inside an autonomous loop with limited human oversight.
Risk
What happens
What teams need to watch
Tool semantic failure
The agent misunderstands what a tool does or when to use it
Tool descriptions, preconditions, side effects, hallucinated tools
Cascading exposure
One tool return becomes context for another tool call
Cross-tool data flow and downstream access
Unreviewed execution
The agent executes tool sequences without intermediate review
Planning steps, constraint checks, loop behavior
Runtime tool expansion
The MCP server exposes new tools after agent approval
Server changes and approval drift
Prompt injection
Tool return data steers the agent’s next planning step
Return validation and unexpected actions
Tool poisoning
Tool metadata or descriptions contain hidden instructions
Tool descriptor integrity and server trust
Tool hallucination and semantic confusion
Tool hallucination is one of the most serious MCP governance risks. An agent with access to a customer database might hallucinate a get_customer_credit_score tool that does not exist, or misread get_account_balance as set_account_balance. The names are semantically similar, but the business impact is completely different.
Agentic systems cannot assume tools are real or that agents understand them correctly. Governance teams need to control which tools agents can see, how tools are described, what input schemas apply, what side effects are possible, and how semantic confusion is detected in production.
Cross-tool dependencies
Cross-tool dependencies create cascading risk. An agent may retrieve sensitive data from System A, then use it to call System B. A single permission can unlock exposure across multiple systems when agents compose tools inside autonomous loops.
Governance needs to account for composition, sequence, context, and data flow. Reviewing individual tool access is not enough when agents can connect tool outputs to downstream actions.
Autonomous execution
Agents execute multi-step workflows autonomously. If the agent selects the wrong tool, misreads a return, fails to check a constraint, or continues acting after the workflow should have stopped, the error can propagate until the loop ends or monitoring catches the drift.
MCP governance needs visibility into planning context, tool selection, parameter binding, return validation, and loop behavior. Final outcomes alone do not show where the control failure occurred.
How can MCP turn planning into action?
MCP connections move agents from passive retrieval to active decision-making and execution. Governance teams need to understand how agents decide to invoke tools, what data they use, and how they handle the result.
Tool selection, parameter binding, return handling, constraint checking, and loop termination are the core control points. These are the places where an agent’s plan becomes an action inside enterprise systems.
Control point
Governance question
Common failure mode
Tool selection
Which tool did the agent choose, and why?
The agent selects the wrong tool or misunderstands tool semantics
Parameter binding
What data did the agent pass into the tool?
The agent uses unexpected values, malformed identifiers, or data from the wrong source
Return handling
How did the agent interpret the tool response?
The agent trusts corrupted, incomplete, or adversarial return data
Constraint checking
Did the agent validate conditions before acting?
The agent invokes tools outside approved preconditions
Loop termination
When did the agent stop acting?
The agent continues invoking tools past the approved workflow
When an agent has multiple tools available, governance teams need to know which tool it selects and whether that selection matches intended behavior. Parameter drift can turn safe actions into high-risk actions if the agent pulls unexpected values from prior tool returns or binds identifiers it should not use.
Return validation is equally important. Agents that do not validate returns can continue planning from corrupted context, which can lead to bad downstream actions even when the first tool call succeeded. Weak termination conditions can also cause agents to keep invoking tools past the approved workflow, making loop length, retry behavior, and timeout patterns important monitoring signals.
How can MCP permissions drift in agentic workflows?
MCP access changes as agents, tools, prompts, servers, and workflows evolve. Permission drift is harder to detect in agentic systems because tool invocation happens autonomously. Quarterly access control audits prevent permission sprawl as MCP connections accumulate access over time, making calendar-based reviews essential alongside change-triggered reviews.
Drift does not always require a formal access change. The same agent can become riskier when its prompt changes, its toolset expands, its workflow changes, its model changes, or it starts composing tools in new ways.
Scope expansion through tool composition
An agent approved to invoke Tool A and Tool B independently may later start composing them: invoke Tool A, use the output to parameterize Tool B, and create a new workflow. The original approval covered individual tool use, but not the composed behavior or data linkage.
Tool composition should be governed explicitly. Teams need to know which tool sequences are approved, which data linkages are allowed, and which compositions require human review.
Tool exposure without reapproval
An MCP server may originally expose one tool. Later, additional tools are added. The agent’s permission record does not change, but the decision surface expands.
The agent now faces tool choices it was never approved to make. MCP server changes should trigger governance review, even when the agent’s access record appears unchanged.
Agent behavior changes after updates
Prompt modifications, model changes, retrieval changes, routing changes, or new system instructions can alter how agents choose tools and handle returns. Earlier governance approvals reflect old behavior.
Access review needs to account for agent change, not only server change. Teams should review whether the updated agent still exercises the same decision authority in the same way.
Implicit dependencies across systems
An agent may be approved to invoke Tool A, which reads from System 1, and Tool B, which writes to System 2. The approval may not cover Tool A’s output becoming Tool B’s input.
Autonomous loops make these linkages likely. Governance records should capture approved tool compositions, prohibited data flows, and conditions that require human review.
Periodic MCP reviews should examine actual behavior, not documented access alone. Teams should review tool invocation patterns, constraint violations, tool composition behavior, and changes in agent decision traces over time.
Why does MCP activity need traceability?
Governance teams need records that capture what the agent did and why. This means every MCP connection should produce a reviewable audit trail. Decision-level audit trails are non-negotiable in regulated industries. Every autonomous tool invocation, parameter binding, and return validation step must be traceable and defensible for compliance and drift detection.
Traceability makes agent behavior inspectable after execution. When an agent invokes the wrong tool, teams need to reconstruct the decision chain: planning context, selected tool, parameters bound, tool returns, validation steps, and downstream actions.
For compliance, audit trails must show planning context, selected tools, constraints checked, and outcomes. For drift detection, audit trails reveal why tool invocation patterns shift. For constraint violations, audit trails help determine whether the cause was a reasoning error, weak guardrail, corrupted return, unclear tool semantics, poisoned metadata, or missing constraint.
A useful audit trail for MCP-connected agents should answer:
Which agent acted?
Which MCP client and server were involved?
What was the agent’s planning context at tool selection?
Which tool did it invoke, and why?
What parameters did it bind?
What data did the tool return, and was it validated?
How did the agent incorporate the return into the next planning step?
What outcome followed?
What should enterprises govern in MCP connections?
Enterprises should govern the full MCP connection layer: the server, the capabilities it exposes, the agent’s decision authority, the constraints that apply, and how actions can be audited. Access control is often the foundational layer. Teams need to define which tools agents can invoke, under what conditions, and within which business boundaries.
Governance area
What teams need to define
Server ownership
Who owns and approves the MCP server
Exposed tools and semantics
What each tool does, including input schemas, preconditions, and side effects
Tool invocation preconditions
When tools can be invoked and which conditions must hold
Connected data sources
What data agents can access and pass downstream
Agent identity and authorization
Which agent uses the connection and what decision scope it has
Permissions and constraints
What agents can read, write, update, delete, or trigger
Parameter constraints
Allowed numeric ranges, identifiers, formats, and tenant boundaries
Business scope and termination
Which workflow is supported and when the agent should stop
Tool composition rules
Which tools can be composed and in what sequences
Return data validation
How tool returns are validated before agent use
Runtime monitoring signals
Signals that indicate normal, anomalous, or policy-violating behavior
Audit trail requirements
Records for planning context, tool selection, parameters, returns, and outcomes
Review cadence and triggers
How often access is reviewed and which changes trigger reapproval
This governance record gives teams a clear view of which MCP connections are approved, which agents depend on them, which systems they reach, and which invocation patterns should be flagged for human review.
How can enterprises operationalize MCP governance?
Enterprises can operationalize MCP governance by turning agent behavior validation into a repeatable workflow. Every MCP server should be inventoried, classified by risk, scoped to the agent’s decision authority, monitored in production, and reviewed as agents, tools, and workflows evolve.
Discovery and mapping
Governance teams need a current inventory of MCP servers, exposed tools, connected data sources, approved agents, and authorized workflows. Each agent in that inventory should operate with unique credentials and least-privilege permissions scoped to the specific MCP tools and business purposes it’s authorized to invoke.
Access to an MCP server should not automatically imply approval to invoke every tool. For each agent, teams should define which tools it can invoke, under what conditions, with what parameter constraints, and for what business purpose.
Risk classification and monitoring
MCP connections should be classified based on tool semantics, data sensitivity, action impact, authorization model, constraint complexity, and composition risk. Higher-risk connections need stricter approval, tighter constraints, stronger monitoring, and more frequent behavioral validation. An AI gateway or centralized control layer can provide a consistent enforcement point for MCP tool access, parameter constraints, rate limits, and audit logging across agents, reducing the need to re-implement governance logic inside every agent workflow.
Production monitoring should surface tool selection patterns, constraint compliance, parameter behavior, hallucinated tools, return handling, tool metadata changes, and reasoning consistency. Teams need to know whether the agent is exercising approved authority or drifting into unexpected behavior.
Review and reapproval
Calendar-based reviews should evaluate invocation patterns on a regular cadence. Change-triggered reviews should happen when agents, prompts, models, tools, servers, or workflows are updated. This operational discipline works best when governance, observability, and audit logging are built into architecture from day one. Retrofitting governance is far more expensive than designing it into the MCP connection lifecycle.
At enterprise scale, MCP governance works like access control for autonomous systems. Teams define authority, approve connections, monitor the exercise of authority, review changes, and revoke access when it is no longer needed.
What questions should teams ask before approving an MCP connection?
Teams should approve MCP connections only after understanding the agent, business purpose, tools involved, data at risk, constraints, and audit requirements. The approval process should make the agent’s decision authority explicit before it invokes tools in production.
Agent and authority
Which agent uses this connection?
What is its approved business purpose?
Who owns the agent?
What decisions should the agent be allowed to make through tool invocation?
Business context
Which workflow does this support?
What does success look like?
How will the agent know when to stop?
What is the impact if the agent makes a wrong decision?
Technical specifics
Who owns the MCP server?
Which specific tools should the agent invoke?
What preconditions and side effects apply?
What data can the agent retrieve, modify, or pass downstream?
Constraints and scope
Who owns the MCP server?
Which specific tools should the agent invoke?
What preconditions and side effects apply?
What data can the agent retrieve, modify, or pass downstream?
Under what conditions should each tool be invoked?
What parameter ranges are allowed?
Which tools should never be invoked?
Which tool compositions are approved?
Data and safety
What data is at risk?
How will tool returns be validated?
What signals indicate anomalous behavior?
How will reasoning drift be detected?
Monitoring and audit
What logs capture planning, tool selection, parameters, returns, and outcomes?
How will teams detect tool hallucination?
How often will behavior be reviewed?
Which changes should trigger reapproval?
These questions turn MCP approval into an operating discipline. Teams get a repeatable way to evaluate decision authority, document constraints, monitor actual behavior, and keep governance aligned.
MCP governance checklist
Enterprises can use the following checklist to govern MCP connections at scale:
Inventory all MCP servers and exposed tools.
Assign ownership for each server, tool, and connected agent.
Define which agents can invoke which tools.
Scope permissions by business purpose, data class, and action type.
Document tool preconditions, side effects, and approved compositions.
Validate tool returns before agents use them in follow-on actions.
Monitor invocation patterns, constraint violations, and permission drift.
Capture audit logs for planning context, selected tools, parameters, returns, and outcomes.
Trigger reapproval when prompts, models, tools, servers, workflows, or agent behavior changes.
Govern MCP as part of the agentic AI lifecycle
MCP governance is part of the larger agentic AI governance challenge. As agents gain access to more tools and workflows, enterprises need governance covering identity, permissions, monitoring, auditability, and fleet-level oversight.
For executives, MCP governance is not only a security concern. It affects operational risk, compliance exposure, customer trust, data governance, and the ability to scale agentic AI safely across the enterprise.
The same principles apply across the full agentic lifecycle. Teams need to govern how agents are approved, how they access tools, how they behave in production, how their actions are audited, and how access changes as systems evolve.
MCP connections should not be treated as ordinary integrations. They are part of the agentic control plane, where model reasoning, enterprise data, and system action converge.
For a deeper look at how enterprises can govern agents, tools, permissions, monitoring, and auditability across the full agentic AI lifecycle, download our Enterprise guide to agentic AI.
FAQ
What is MCP in agentic AI?
Model context protocol is the invocation standard that lets agentic systems reach external tools and execute autonomous actions. MCP can connect agents to document repositories, databases, ticketing platforms, developer tools, customer applications, internal APIs, and workflow systems.
What is MCP governance?
MCP governance is the discipline of controlling how AI agents discover, select, invoke, and compose external tools through MCP connections. It includes ownership, authorization, scoped permissions, tool constraints, runtime monitoring, audit trails, and reapproval triggers.
Why do MCP connections need governance?
MCP connections need governance because agents make autonomous decisions about tool invocation inside planning loops. Agents can hallucinate tools, misunderstand semantics, invoke tools with wrong parameters, compose tools unintentionally, or be steered by corrupted returns.
How can enterprises govern MCP connections at scale?
Enterprises can govern MCP connections at scale by maintaining a central inventory tied to agent decision authority, classifying connection risk, scoping permissions to specific tools, monitoring tool selection patterns, capturing audit trails, and reviewing access based on calendar cadence, system changes, and behavioral signals.
What should enterprises include in an MCP governance record?
An MCP governance record should include server ownership, exposed tools, tool semantics, invocation preconditions, connected data sources, agent identity, decision authority, permissions, parameter constraints, business scope, tool composition rules, return validation, monitoring signals, audit requirements, and review triggers.
What is the biggest risk of unmanaged MCP connections?
The biggest risk of unmanaged MCP connections is uncontrolled agent autonomy. Agents may hallucinate tools, invoke real tools with misunderstood semantics, compose tools in unintended ways, or be misled by corrupted returns without clear decision authority, approved constraints, runtime visibility, or reliable logs.
Teams are moving AI agents from prototype to workflow fast. One agent gets connected to a document store. Another starts calling internal tools. A third begins touching customer data.
Soon, agents are operating across systems before governance teams have a clear record of what they can access, who owns them, or what they’ve done.
AI agents can retrieve information, call tools, trigger workflows, and act across business systems. When they operate outside approved governance workflows, they create an ungoverned operational layer inside the enterprise that can expose sensitive data, bypass policy controls, and make incident response harder.
To find and govern unsanctioned AI agents, enterprises need to:
Identify where agent activity already exists
Determine what each agent can access
Assign clear ownership and scope
Apply runtime monitoring, audit trails, and policy controls
The goal isn’t to shut down experimentation. It’s to make the governed path easier than the workaround. That starts with visibility: knowing which agents exist, what they can do, which systems they touch, and whether their actions can be reviewed after the fact.
Key takeaways
Shadow agents are unsanctioned AI agents that operate outside approved governance, security, or deployment workflows.
They often emerge when teams can prototype agents faster than the enterprise can govern them.
The biggest risk is unmonitored action across tools, data, APIs, and workflows.
Enterprises need a reliable inventory of which agents exist, who owns them, what they can access, and what actions they can take.
Effective governance brings agents under identity, scope, permissions, monitoring, and auditability.
The governed path should be clear enough and practical enough that teams do not need workarounds.
What are shadow agents in enterprise AI?
Shadow agents are AI agents that operate outside an enterprise’s approved governance, security, or deployment workflows. They often begin as prototypes, internal automations, or team-level tools, then expand into production workflows without a central inventory, assigned owner, defined permission model, or audit trail.
The risk increases when a shadow agent connects to enterprise systems. That can include document repositories, customer databases, ticketing systems, internal APIs, model context protocol (MCP) servers, workflow tools, or other agents.
Once an agent can access data, call tools, or trigger actions, it needs the same governance attention as any other system operating on behalf of the business.
Shadow agents can include:
A developer-built agent that calls internal APIs without formal approval
A workflow agent connected to customer data before security review
An internal assistant that retrieves sensitive documents without access controls
A team-level automation that uses shared credentials or undocumented permissions
An agent prototype that quietly becomes part of a live business process
The central issue is visibility. Enterprises can’t govern agents they can’t see. Before teams can evaluate risk, enforce policy, or investigate behavior, they need a reliable record of which agents exist, what they’re connected to, what permissions they have, and what actions they’ve taken.
Why do shadow agents appear in enterprise AI environments?
Shadow agents appear when teams can build and connect AI agents faster than the enterprise can govern them. Prototyping is easy, business teams are under pressure to show AI value, and governance processes often feel slower than the work teams are trying to get done.
Most shadow agents don’t start as a deliberate attempt to bypass controls. They usually start as practical experiments: a developer testing an agent, a team automating a workflow, or a business unit connecting an assistant to internal data. The risk grows when those experiments keep expanding without a formal path into governed deployment.
Cause
How it creates shadow agent risk
How to respond
Fast prototyping
Teams connect agents to tools, data, or workflows before production governance is defined.
Require agent identity, scope, and access review before agents connect to live systems.
Pressure to prove AI value
Teams prioritize speed and visible outcomes over access controls, monitoring, and documentation.
Create a faster approved path for governed agent deployment.
Late governance review
Security and governance teams discover agents after they’re already connected to enterprise systems.
Embed governance checks into design, testing, and deployment workflows.
No central inventory
The enterprise can’t see which agents exist, who owns them, or what they can access.
Maintain a centralized inventory of agents, owners, tools, data sources, and permissions.
Unclear deployment standards
Teams don’t know when an experiment has crossed into production use.
Define clear thresholds for when agent prototypes require formal governance review.
Friction in approved workflows
Teams create workarounds when the governed path feels slower than the unofficial path.
Make compliant deployment easier to follow, monitor, and repeat.
Shadow agents are often a process problem before they’re a technology problem. When teams don’t have a clear, fast, and practical way to deploy governed agents, they create their own path. Effective agent governance closes that gap by making approved deployment easier to follow, easier to monitor, and easier to scale.
Why are shadow agents risky?
Shadow agents are risky because they can act inside enterprise systems without the visibility, permissions, monitoring, and audit trails required to control that behavior. An unsanctioned AI agent may access sensitive data, call internal tools, trigger workflows, or pass information to another system before governance teams know it exists.
That makes shadow agents different from ordinary software sprawl. A forgotten app may create security exposure. A shadow agent can create security exposure and take action. It can interpret a request, retrieve context, choose a tool, and execute a step inside a workflow. If that behavior is not governed, the enterprise may not know what happened, why it happened, or how to prevent it from happening again.
Shadow agents can access sensitive data
Many agents become useful because they connect to enterprise data. That same connection creates risk when access is not scoped, approved, or monitored. A shadow agent may retrieve customer records, employee data, financial information, proprietary documents, or regulated data without the right controls in place.
Shadow agents can take action across systems
AI agents can do more than return answers. They can call APIs, update records, create tickets, send information to other tools, or trigger downstream workflows. When those actions happen outside approved governance workflows, small errors can become business problems quickly.
Shadow agents can be hard to investigate
When an incident happens, teams need to reconstruct what the agent did. That requires logs of inputs, outputs, retrieved context, tool calls, actions, and outcomes. Without that audit trail, security, compliance, and operations teams are left piecing together behavior after the fact.
The core risk is traceability. Enterprises need to know which agents exist, what they can access, what actions they can take, and whether their behavior can be reviewed. Without that record, shadow agents create blind spots across security, compliance, and operations.
How can enterprises find shadow agents?
Enterprises can find shadow agents by looking for agent behavior across tools, data sources, APIs, and workflows. Many shadow agents won’t appear in a central AI inventory because they started as experiments, scripts, assistants, or team-level automations.
Governance, security, IT, and AI teams should start by reviewing the environments where agents can connect to live business systems. That includes developer workspaces, cloud environments, automation platforms, internal applications, copilots, model context protocol (MCP) servers, and business-unit workflows.
Useful discovery questions include:
Which AI agents or LLM applications are connected to enterprise data?
Which agents can call internal tools, APIs, or workflow systems?
Which agents use shared credentials, service accounts, or unmanaged permissions?
Which prototypes are now part of recurring business processes?
Which agents have no assigned business owner or technical owner?
Which agents lack logs for inputs, outputs, tool calls, actions, and outcomes?
The goal is to create a working inventory that shows which agents exist, who owns them, what systems they touch, what permissions they have, what actions they can take, and whether their behavior can be reviewed after the fact.
How can enterprises govern shadow agents once they find them?
Enterprises can govern shadow agents by bringing them into a formal agent governance workflow. That process should clarify what the agent does, who owns it, what systems it can access, what actions it can take, and how its behavior will be monitored over time.
The first step is classification. Some shadow agents may be useful and worth governing. Others may be too risky, redundant, or poorly designed to keep in place. Governance teams should evaluate each agent based on business value, system access, data sensitivity, autonomy level, and auditability.
How do you assign ownership for an AI agent?
Every agent needs a business owner and a technical owner. The business owner is accountable for the use case, expected outcome, and acceptable risk. The technical owner is accountable for implementation, access, monitoring, and maintenance.
Ownership matters because agents can act across workflows. If an agent behaves unexpectedly, the organization needs to know who can review it, restrict it, update it, or shut it down.
How do you define what an AI agent can access and do?
A shadow agent should not keep whatever access it gained during experimentation. Governance teams need to define the agent’s purpose, approved systems, allowed actions, and off-limits data.
The permission model should match the job the agent is supposed to perform. An agent that summarizes support tickets does not need the same access as an agent that updates customer records or triggers account changes.
How do you monitor and audit AI agent behavior?
Governance teams need a record of agent behavior in production. That includes inputs, outputs, retrieved context, tool calls, actions, and outcomes. These records help teams investigate incidents, validate policy compliance, and understand how agent behavior changes over time.
A governed agent should be reviewable. Teams should be able to reconstruct what happened, which tools were used, what data was accessed, and which action the agent took.
How do you decide whether to govern, restrict, rebuild, or retire a shadow agent?
Once a shadow agent is evaluated, teams can choose the right response. A useful agent with manageable risk may be moved into an approved governance workflow. A high-risk agent may need tighter permissions, additional monitoring, or a redesigned workflow. An agent with unclear ownership, weak controls, or low business value may need to be retired.
The standard should be simple: if an agent can access enterprise systems or act on behalf of the business, it needs identity, ownership, scoped permissions, monitoring, and auditability.
Learn how to govern agentic AI across the full lifecycle
Shadow agents are one warning sign of a larger governance challenge. As enterprises move from isolated AI experiments to agentic systems that retrieve information, call tools, trigger workflows, and act across business systems, governance has to become part of how agents are built and operated.
The enterprise guide to agentic AI governance explains how to govern AI agents across the full lifecycle, including permissions, audit trails, runtime monitoring, lifecycle controls, and fleet-level oversight.
Read the ebook to learn how to build the governance foundation for agentic AI at enterprise scale.
FAQ
What are shadow agents in enterprise AI?
Shadow agents are AI agents that operate outside approved governance, security, or deployment workflows. They may access data, call tools, trigger workflows, or support business processes without a central inventory, assigned owner, defined permission model, or audit trail.
Why do shadow agents appear?
Shadow agents appear when teams can build and connect agents faster than the enterprise can govern them. They often begin as prototypes, automations, or team-level tools, then expand into real workflows before security, compliance, or governance teams have full visibility.
Why are shadow agents risky?
Shadow agents are risky because they can access sensitive data, call internal tools, and take action across enterprise systems without approved controls. If they lack monitoring and audit trails, teams may not be able to reconstruct what happened after an incident.
How can enterprises find shadow agents?
Enterprises can find shadow agents by looking for agent behavior across tools, data sources, APIs, automation platforms, cloud environments, MCP servers, and business workflows. The goal is to identify which agents exist, what they connect to, who owns them, and whether their behavior can be reviewed.
How should enterprises govern shadow agents?
Enterprises should govern shadow agents by assigning ownership, defining scope, reviewing permissions, adding runtime monitoring, and capturing audit trails. Each agent should have a clear purpose, approved access, documented controls, and a reliable record of its actions.
Agentic AI is already reshaping how enterprises operate. But most governance frameworks aren’t built for it.
AI agents are most successful when they work within human-defined guardrails: governance frameworks designed for autonomous systems. Good governance doesn’t limit what agents can do. It defines where they can operate freely, and makes it safe to give them that freedom.
But finding that balance requires consequential tradeoffs. AI leaders have to make deliberate decisions to develop governance frameworks that build trust, ensure compliance, and protect organizational reputation, while scaling confidently.
This is your decision-making guide to help you develop an agentic AI governance framework that lets you deploy with confidence — maximizing what agents can do while controlling what they shouldn’t.
Key takeaways
Agentic AI needs a new governance approach because autonomy changes the risk model. Agents make decisions, take actions, and connect to enterprise tools and data, so governance must cover the whole system, not just the model.
Governance is a scalable set of principles, not a one-time checklist. The goal is to define acceptable behavior, protect data, and ensure accountability in a way that stays consistent as agents and teams multiply.
Governance must be built in, not bolted on. If you wait until after agents are live to define scope, permissions, and controls, you’ll create rework, slow deployment, and increase exposure to security and compliance failures.
The best frameworks balance autonomy with oversight. “Governed autonomy” means letting agents run freely in low-risk scenarios while enforcing escalation paths and human review for high-impact, irreversible, or regulated actions.
Access control is the most important (and most commonly overlooked) layer. Agents are effectively digital employees: they need defined identities, least-privilege permissions, and explicit constraints on which tools (including MCP servers) they can access.
Why agentic AI requires a new governance framework
Governance frameworks aren’t anything new. But what most businesses have in place to oversee machine learning (ML) isn’t sufficient for autonomous agents.
Unlike traditional models or basic automations, AI agents aren’t constrained by predefined scripts. They can make independent decisions, take autonomous actions, and access diverse business tools and data.
This autonomy makes agentic AI better suited for complex, multi-step tasks, like orchestrating end-to-end workflows, but it also introduces more risk. After all, with more data access and decision authority comes more responsibility — and more governance dimensions.
To account for these new risks, frameworks overseeing agentic AI systems must not only govern what autonomous agents do but what they connect to: enterprise tools and data sources. Model context protocol (MCP) is fast becoming the standard for agent-tool connections, adding another connectivity layer that governance has to address.
Core principles of an agentic AI governance framework
Before designing a governance framework, get clear on what governance actually is. It’s more than a set of rules to follow or tools to deploy.
Governance is a set of principles that defines acceptable agent behavior, protects data privacy, and ensures accountability to mitigate downstream risks.
And it must be scalable. As your business grows and use cases become more complex, a governance framework needs to keep up with evolving needs while maintaining consistency across teams and systems.
Governance must be built in, not bolted on
The most common mistake AI leaders make with governance is treating it as an add-on instead of an integral part of AI infrastructure.
If you treat governance as an afterthought, you risk leaving gaps that force future rework and may undermine the success of your entire AI initiative.
Once core agent behaviors, tool integrations, and permissions are already fixed, it’s challenging — and risky — to go back and add controls. It’s also time-consuming and labor-intensive, often requiring architectural changes and manual fixes.
Instead of playing catch-up with band-aid governance, set yourself up for long-term success by making governance a design-time decision, not a final step. Design-time governance helps ensure you have clear, enforceable guardrails that guide behavior and limit risk from day one.
The governance golden rule: The earlier you embed governance, the more you can count on fast, safe production readiness, and the less you’ll scramble with last-minute security, legal, and compliance measures that stall deployment.
Think of built-in governance like “governance as code.” Just like infrastructure as code, governance policies are more effective when defined programmatically from day one instead of manually managed after the fact. This way, you can easily apply, review, and reuse your governance framework consistently across agents and teams, now and as you scale.
Governance must balance autonomy with oversight
The hardest part of building agentic AI governance is implementing enough controls to mitigate risks while still giving agents the autonomy to reason and act independently.
If your governance framework overextends itself and curbs autonomy completely, then you’ve gone too far and defeated the entire point of deploying AI agents.
AI agents best serve your business when they can make and execute decisions independently, without constantly deferring to humans. Overly restrictive frameworks undermine AI efficiency and shift the work back to human teams.
Rather than restricting autonomy, governance frameworks should define clear boundaries where agents can act freely and where escalation is required.
Well-planned governance creates decision boundaries based on risk, impact, and reversibility. If regulated financial or health data is involved, human-in-the-loop controls take priority. Conversely, low-risk, repeatable actions (like routine workflow steps) should be left to agents to run alone.
What about keeping humans in the loop?
Agentic AI governance should strategically incorporate human-in-the-loop controls, pulling in teams specifically where human judgment is required — not as the default fallback.
Defining what must be governed in agentic systems
Unlike traditional ML governance, agentic AI governance must extend beyond models to cover your full autonomous system, from agent behavior and performance to access, tool connections, and outcomes.
Access, identity, and permissions
The access control layer is the most important part of your governance framework. It’s also the most overlooked.
With the ability to access data, make decisions, and execute actions independently, agentic AI agents aren’t simple tools. Think of agentic AI agents less like software and more like digital workers taking real actions, touching real data, and connecting to real systems. And when something goes wrong, there are real consequences, like data exposure.
Like human workers, AI agents need clear identities. But where human identities are often tied to roles, agent identities should be scoped to specific responsibilities, always founded on least-privilege access (i.e., the minimum access required to complete the task).
As agents connect to more tools via MCP, governance should also define which MCP servers agents can access.
Decision scope and authority
Independent decision-making is one of the core strengths of agentic AI that enables speed and scale, but left unchecked, it can cause agents to become unwieldy and introduce new risks.
That’s why agents need defined decision boundaries to govern what kinds of decisions they can take and which require escalation to human judgment.
Decision boundaries also help rein in scope creep.
Over time, agents can exceed their original tasks and access controls, taking actions or acquiring permissions outside their defined scope. Decision boundaries keep agents in check by limiting authority where needed and enforcing escalation paths.
To best balance risk mitigation and autonomy, governance frameworks should champion decision-level guardrails, not general, system-level permissions. If too broadly defined, permissions risk unnecessarily constraining agents, ultimately rendering them useless.
Data usage and handling
To make autonomous decisions and execute tasks, AI agents have to interact with data and tools across enterprise systems. As use cases scale, AI agents only touch more (and more sensitive) data.
That’s where the risk lives, especially for heavily regulated industries like finance or healthcare.
A key part of agentic AI governance frameworks isn’t just governing what agents do. It’s governing what data those agents are allowed to access, when, and how much. That includes:
Data minimization: Limiting agent access to only need-to-know data to complete assigned tasks
Residency: Ensuring data is only stored and accessed by agents in approved geographic regions
Privacy requirements: Enforcing policies for personally identifiable information (PII), protected health information (PHI), or otherwise regulated data
For large enterprises managing complex datasets with varying regulatory requirements, governance for data usage and handling isn’t just a nice-to-have.
Applying governance across the agent lifecycle
Well-thought-out, effective governance frameworks are never universal, but they should cover the full agent lifecycle. In other words, agentic AI governance should be a horizontal capability that covers the full agent lifecycle across your entire autonomous system.
From design to deployment and beyond, it’s this end-to-end coverage that makes a governance framework different from a simple checklist.
Design-time governance
Good governance begins on day one. That means defining and implementing clear guardrails before you even start building and deploying agents.
Specifically, design-time governance should define:
Scope: What tasks is the agent allowed to do? What is explicitly off limits?
Access: Which systems, tools, and data is the agent allowed to access?
Constraints: What decisions must the agent escalate to humans? When?
At this point, you should also conduct tests to identify governance gaps before they surface in production:
Simulate scenarios to see where agents exceed scope or misuse access.
Test edge cases to validate escalation paths.
Audit tool access to catch misconfigurations.
For governance, there’s no such thing as better late than never. Involve security, IT, and compliance teams early to align on governance needs and avoid risks and rework post-production.
Deployment and runtime governance
After design-time decisions, don’t wait. Begin enforcing governance immediately during deployment.
When you apply governance only after the fact, issues can slip by unnoticed, meaning you only identify gaps and start problem-solving after risks (and potential damage) have already taken hold.
Conversely, by enforcing governance during runtime, you empower teams to detect and stop (or even prevent) unsafe actions before they can do real damage.
Runtime governance should include:
Logging: Capture detailed records of agent actions, tool usage, and data access for audit and investigations.
Monitoring: Continuously observe agent behavior to detect scope violations or policy drift.
Real-time enforcement: Actively block or escalate agent actions when necessary.
Remember: Real-time governance enforcement is impossible without real-time visibility. To identify risks and enforce policies, you first need continuous, trustworthy insights into what agents are doing, where, and when.
Ongoing governance and evolution
Yes, governance work should start on day one, but it shouldn’t stop there.
Agents evolve over time through updated tools, new data sources, and changing configurations, and your governance frameworks need to keep up. That means regularly revisiting your governance policies to ensure they’re still relevant and useful.
Your quick checklist to manage ongoing governance:
Schedule periodic reviews to evaluate agent scope, access controls, and evolving behaviors.
Update policies where needed to reflect changes in regulations, tools, or business priorities.
Prepare for audits with continuous, granular documentation that demonstrates compliance.
Your governance framework requires ongoing maintenance. Don’t treat it like a simple playbook you can set and forget.
Signals that an agentic AI governance framework is missing
You might already have agentic AI governance in place (or think you do). But it can be hard to know if your policies are effective, where the gaps are, and how to fix them.
Often, warning signs surface as you start to scale agents across teams and use cases, creating new orchestration complexities like:
Cross-team agent conflicts
Duplicate tool access requests
Inconsistent policy enforcement across teams
Not sure where your agentic AI governance stands? Run a quick litmus test:
Do you have a centralized view of all agents and their permissions? If not, you’re almost certainly working with governance gaps.
Governance risk, cost, and enterprise impact
Leave governance until post-production, and you’re inviting extra work and unnecessary risks.
When AI agents don’t have task-specific access controls or defined decision boundaries, you open the door to accidental data exposure, compliance violations, and other high-stakes incidents that come with big financial and reputational consequences.
Just imagine what might happen if an agent with overly generous data access inadvertently exposes or modifies sensitive records. That’s a real risk without solid, intentional governance.
On top of reputational damage and financial losses from fines and audits, poor governance can leave further lasting financial consequences. Bills for incident response and remediation can keep rolling in for months or even years after an initial incident is contained.
Strategic, preemptive governance paints a different picture. It doesn’t just improve agent performance and support regulatory compliance. It creates real cost savings by mitigating the risk of costly breaches, investigations, and other operational disruptions.
Why agentic AI governance frameworks matter most in regulated industries
While every industry needs sound agentic AI governance, those with strict regulations have more at stake.
Businesses in finance, healthcare, and the public sector face intense regulatory scrutiny with stiff consequences for breaking privacy or security obligations. Even small violations can threaten your organization’s financial and reputational standing, and the risks only get bigger as you scale agentic AI.
With an ungoverned fleet of AI agents at work, your systems may inadvertently misuse data or otherwise break compliance with data protection, privacy, and safety regulations.
But to work, governance must be auditable and explainable. It’s not enough to simply have checked the box “implement governance.” Regulators expect to see reproducible evidence of agent decision-making via complete audit trails that document what decisions were made, when, where, and why.
Many organizations mistakenly assume older compliance frameworks — like SOC and ISO standards — don’t apply to agentic AI. They do, and regulators will expect evidence of compliance.
The governance “aha moment” for AI leaders
Governance isn’t about distrust. It’s about definition.
AI agents perform best when they have the autonomy to act — and the boundaries that make acting safely possible. The leaders who move fastest with agentic AI aren’t the ones who skip governance. They’re the ones who built it in from the start.
That’s the shift: from governance as a constraint to governance as the foundation for scale.
Building or evaluating agentic AI infrastructure? Check out our GitHub and dev portal.
FAQs
What is an agentic AI governance framework?
An agentic AI governance framework is a set of scalable principles, policies, and controls that define acceptable agent behavior, manage access to tools and data, and ensure accountability. Unlike traditional ML governance, it must govern not only model outputs but also agent actions, tool connections, and downstream business impact.
Why can’t we use our existing ML governance for agentic AI?
Traditional ML governance assumes bounded behavior. Models produce outputs, and humans or systems interpret them. Agents take autonomous actions, call tools, access data, and can change behavior over time, which introduces new risk dimensions like permissioning, tool governance, and decision authority.
What does “governance must be built in, not bolted on” actually mean?
It means governance decisions. Scope, access, constraints, and escalation paths should all be defined during design and enforced from deployment onward. If governance is added after agents are running, teams often discover permission gaps, compliance risks, or missing audit trails too late, forcing costly redesign and delays.
How do you balance autonomy with human oversight without undermining the agent’s effectiveness?
Use decision boundaries based on risk, impact, and reversibility. Low-risk, repeatable actions can remain fully autonomous, while high-risk actions (regulated data access, write actions in systems of record, irreversible decisions) require escalation or human-in-the-loop checkpoints.
This post takes the next step, giving you a readiness check to avoid painful missteps or costly rework.
The risk is clear: The more progress you make without a gateway, the harder it becomes to retrofit one — and the more exposure you carry.
A true AI gateway needs to be customizable and future-proof by design, adapting as your architecture, policies, and budget evolve. The key is starting fast with a gateway that scales and adjusts with you rather than wasting effort on brittle builds that can’t keep up.
Let’s walk through the essential questions to help you assess where you stand and what it will take to support an AI gateway.
Where are you on the agentic AI maturity curve?
Before you decide whether you’re ready for an AI gateway, you need to know where your organization stands. Most AI leaders aren’t starting from zero, but aren’t exactly at the finish line, either.
Here’s a simple framework to pinpoint your AI maturity level:
Stage 1: Infrastructure readiness: You’ve provisioned compute and environments. You can run early experiments, but nothing’s deployed yet. If this describes you, you’re still in the foundational phase where progress is more about setup than outcomes.
Stage 2: Initial experimentation: You’ve deployed one or two agentic AI use cases into production. Teams are experimenting rapidly, and the business is starting to see value. This stage is marked by visible momentum, but your AI efforts remain limited in scope and maturity.
Stage 3: Governance in place: Your AI is in production and maintained. You’ve implemented enterprise-grade security, compliance, and performance monitoring. You have real AI governance, not just experimentation. Reaching this point signals you’ve moved from ad hoc adoption to structured, enterprise-level operations.
Stage 4: Optimization and observability: You’re scaling AI across more use cases. Dashboards, diagnostics, and optimization tools are helping you fine-tune performance, cost, and reliability. You’re pushing for efficiency and clarity. Here, maturity shows up in your ability to measure impact, compare trade-offs, and refine outcomes systematically.
Stage 5: Full business integration: Agentic AI is embedded across your organization, threaded into business processes via apps and automations. At this stage, AI is no longer a project or program, but a fabric of how the business runs day to day.
Most enterprises today sit between Stage 2 and Stage 3 of their agentic AI journey. Pinpointing your current stage will help you determine what to focus on to reach the next level of maturity while protecting the progress already achieved.
When should you start thinking about an AI gateway?
Waiting until “later” is what gets teams in trouble. By the time you feel the pain of not having one, you may already be facing rework, compliance risk, or ballooning costs. Here’s how your readiness maps to the maturity curve:
Stage 1: Infrastructure readiness
Gateway thinking should begin toward the end of this stage when your infrastructure is ready and early experiments are underway. This is where you’ll want to start identifying the control, abstraction, and agility you’ll need as you scale, because without that early alignment, each new experiment adds complexity that becomes harder to untangle later. A gateway lens helps you design for growth instead of patching over gaps down the road.
Stage 2: Initial experimentation
This is the ideal window of opportunity. You’ve got one or two use cases in production, which means complexity and risk are about to ramp up as more teams adopt AI, integrations multiply, and governance demands increase. Use this stage to assess readiness and shape gateway requirements before chaos multiplies.
That means looking closely at how your pilots are performing, where handoffs break down, and which controls you’ll need as adoption spreads. It’s also the time to define baseline requirements, like policy enforcement, monitoring, and tool interoperability, so the gateway reflects real needs rather than guesswork.
Stage 3: Governance in place
Ideally, you should already have a gateway by this stage. Without one, you’re likely duplicating effort, losing visibility, or struggling to enforce policies consistently. Implementing governance without a gateway makes scaling difficult because every new use case adds another layer of manual oversight and inconsistent enforcement.
That opens hidden gaps in security and compliance as teams create their own workarounds or bypass approval steps, leaving you vulnerable to issues like untracked data access, audit failures, or even regulatory fines.
At this point, risks stop being theoretical and surface as operational bottlenecks, mounting liability, and roadblocks that prevent you from moving beyond controlled experimentation into enterprise-scale adoption.
Stage 4: Optimization and observability
It’s not too late for an AI gateway at this point, but you’re in the danger zone. Most workflows are live and the number of tools you’re using has multiplied, which means complexity and scale are increasing rapidly. A gateway can still help optimize cost and observability, but implementation will be harder, rework will be inevitable, and overhead will be higher because every policy, integration, and workflow has to be shoehorned into systems already in motion.
The real risk here is runaway inefficiency: The more you scale without central control, the more complexity turns from an asset into a burden.
Stage 5: Full business integration
This is the point where rolling out an AI gateway gets painful. Retrofitting at this stage means ripping out redundancies like duplicate data pipelines and overlapping automations, untangling a sprawl of disconnected tools that don’t talk to each other, and trying to enforce consistent policies across teams that have built their own rules for access, security, and approvals. Costs spike, and efficiency gains are slow as every fix requires unlearning and rebuilding what’s already in use.
At this level, not having a gateway becomes a systemic drag where AI is deeply embedded organization-wide, but hidden inefficiencies prevent it from reaching its full potential.
TL;DR: Stage 2 is the sweet spot for standing up an AI gateway, Stage 3 is the last safe window, Stage 4 is a scramble, and Stage 5 is a headache (and a liability).
What should you already have in place?
Even if you’re early in your maturity journey, an AI gateway only delivers value if it’s set up on the right foundation. Think of it like building a highway: You can’t manage traffic at scale until the lanes are paved, the signals are working, and the on-ramps are in place.
Without the basics, adding a central control system just creates bottlenecks. So, if you’re missing the essentials, it’s too soon for a gateway. With the basics under your belt, the gateway becomes the load-bearing structure that keeps everything aligned, enforceable, and scalable.
At minimum, here’s what you should have in place before you’re ready for an AI gateway:
A few AI use cases in production
You don’t need dozens — just enough to prove AI is delivering real value. For example, your support team might use an AI assistant to triage tickets. Or finance could run a workflow that extracts data from invoices and reconciles it with purchase orders.
Why?: A gateway is about scaling and governing what already exists. Without real, active use cases, you have nothing to abstract or optimize. Think about the highway example above: If there’s no live traffic on the road, there’s nothing for signals to manage.
Core agentic components
Your environment should already include some mix of:
LLMs: The engine that powers reasoning and generation.
Unstructured data processing pipelines, pre-processing for video/images/RAG, or orchestration logic: The bridge between messy data and usable inputs.
Vector databases: The memory layer that makes retrieval fast and relevant.
APIs in active use: The connectors that let everything talk and work together.
Why?: A gateway is most effective when it can connect and coordinate across components. These are your lanes, signals, and interchanges. They may not be fancy, but they keep traffic moving. If your architecture is still theoretical, the gateway has nothing to route, secure, or govern.
At least one defined workflow
A defined workflow should illustrate the path from raw input to real output, showing how your AI moves beyond theory into practice. It could be as simple as: LLM pulls from a vector DB → processes data → outputs results to a dashboard.
Why?: Gateways work best when they wrap around real flows — not isolated tools. Without at least one production workflow, you won’t yet have a demonstrated need for governance or observability for a critical system.
Regulatory or operational mandates
Regulations and internal mandates shape how AI should be designed, deployed, and monitored in your organization. From GDPR and HIPAA to enterprise audit requirements, these rules dictate data handling, access control, and accountability. An AI gateway becomes the natural enforcement point, embedding compliance and auditability into the workflow so that growth doesn’t come at the expense of security or trust.
Why?: Because the control layer of an AI gateway is what helps you meet those requirements at scale. These are your traffic laws and safety codes. As AI adoption expands, mandates multiply by use case, region, and department.
For example, a healthcare workflow may need HIPAA compliance, while a customer support bot handling EU data must follow GDPR. A gateway scales with that complexity, providing policy enforcement and auditability without manual effort.
Do you have a documented agentic AI strategy?
A gateway can’t enforce what isn’t defined.
If your team hasn’t articulated what constraints the agentic AI needs to operate under, the success criteria it should meet, and the growth phases you defined, your gateway has nothing to optimize, secure, or scale.
A well-documented agentic AI strategy gives the gateway a clear mission and should spell out:
Where agentic AI will be used: Identify where agentic AI will operate (e.g., marketing analytics, customer operations) so the gateway can apply guardrails, permissions, and visibility by domain.
An adoption and growth plan: Map how AI will expand (from pilots to enterprise scale) so the gateway can orchestrate rollout, provisioning, and monitoring consistently.
Success criteria: Establish measurable outcomes (ROI, cycle-time reduction, cost efficiency) the gateway can track through observability and reporting.
Governance and security mandates: Specify frameworks (GDPR, SOC 2, HIPAA) and review cadences so the gateway can automate enforcement and auditing.
Budget alignment and resourcing plans: Clarify ownership of gateway operations, covering who approves, maintains, and funds control systems, to build in accountability from day one.
Best practices for scale: Define universal policies (data access, API usage, prompt management) that the gateway can standardize across teams to prevent drift and duplication.
Do you have regulatory or operational mandates to fulfill?
Every enterprise operates under mandates that define how AI is implemented and secured. The real question is whether your systems can enforce them automatically at scale.
An AI gateway makes at-scale enforcement possible. It embeds policy controls, access management, logging, and auditability into every agentic workflow, turning compliance from a manual burden into a continuous safeguard. Without that unified layer, enforcement breaks down and risks (including possible fines) multiply.
Consider the mandates your gateway needs to operationalize:
Legal and regulatory requirements by region or sector: For example, healthcare teams must maintain HIPAA compliance, while global enterprises face GDPR and cross-border data transfer rules — all of which the gateway enforces through policy and access control.
Internal compliance rules: These often include model approval workflows, data retention policies, and audit trails to prove accountability. Without a central control layer, these processes quickly become inconsistent across departments.
Documentation needs: AI explainability and traceability aren’t just “nice to have” — they’re often mandatory for internal audits or external regulators. Finance teams, for example, may need to demonstrate how automated credit models reach decisions. The gateway embeds these into workflows, automatically logging activity and decisions for regulators or internal review.
Are your governance, security, and approval inputs ready?
Governance and security are how you translate compliance intent into operational reality, and what keeps audit fire drills and access loopholes from derailing scale. Building on your regulatory mandates, your gateway should automate enforcement, consistently applying approvals, permissions, and audit trails across every workflow.
But your gateway can’t enforce rules you haven’t set. That means having:
Defined roles, responsibilities, and permission hierarchies (RBAC, approvals): Clarify who can build, approve, or deploy AI workflows.
Internal policies for responsible AI, data ethics, and usage boundaries: Set guidelines like requiring human-in-the-loop review or restricting model access to sensitive data.
Security protocols aligned to each use case’s sensitivity: Maintain stronger safeguards for financial or healthcare data, lighter ones for internal knowledge bots.
Infrastructure support for audit trails and enforcement: Use automated logs and version histories that make compliance reviews seamless.
A gateway doesn’t invent rules. It executes on the ones you’ve set. If you haven’t mapped who can do what — and under what conditions — you can’t scale agentic AI safely.
Measuring ROI from your gateway
Every AI program reaches a point where cost control becomes strategy. A gateway helps you reach that point sooner, turning unpredictable, hidden costs into measurable efficiency gains. The setup investment pays itself back quickly once governance, observability, and scale are unified.
Without a gateway, costs are higher and harder to see: Teams lose time to manual reviews, DevOps hours pile up, and brittle architectures lock you into tools you’ve outgrown.
Multiply that across every use case, and missed savings compound into real financial strain.
A gateway eliminates those drains across several areas:
Operational load: Automating governance and monitoring cuts DevOps overhead and rework time, freeing teams to focus on delivery instead of repair.
Financial exposure: Continuous enforcement and auditability reduce compliance risk, regulatory penalties, and remediation costs.
Technical debt: Standardized orchestration prevents overbuilding, compute overuse, and vendor lock-in, which reduces the need for expensive rebuilds later.
Opportunity cost: With consistent controls in place, you can test new tools, scale proven use cases faster, and capture competitive advantage sooner.
Think about two companies starting their agentic AI journey. Company A invests in a gateway early, while Company B tries to scale without it.
Company A’s return on investment (ROI) compounds over time. The upfront investment pays off through lower operating costs, faster innovation cycles, and reduced risk exposure. Company B may save upfront by skipping the setup costs, but the costs catch up later in rework, downtime, and missed growth opportunities.
Ultimately, the outcome is cost discipline that scales with your AI ecosystem — managing spend and turning compliance and agility into continuous ROI.
Take the next step
This readiness check is designed to help you avoid the missteps that slow AI maturity, from costly rework to mounting risk. The further you advance without an AI gateway, the more complicated it becomes to stand one up.
The best time to act is when early pilots start proving value. That’s the stage when oversight and scalability begin to intersect. By pinpointing where you sit on the maturity curve and confirming you have core use cases, foundational workflows, and clear policies in place, you can stand up a gateway that strengthens what’s already working instead of rebuilding later.
Whether you build or buy doesn’t matter. What matters is whether or not you’re prepared to support a gateway designed to match your architecture and enforce your policies while evolving with your budget.
If you’re ready to turn assessment into action, start with our Enterprise Guide to Agentic AI. It’s your roadmap for designing a gateway strategy that scales safely, efficiently, and without compromise.
The real future of work isn’t remote or hybrid — it’s human + agent.
Across enterprise functions, AI agents are taking on more of the execution of daily work while humans focus on directing how that work gets done. Less time spent on tedious admin means more time spent on strategy and innovation — which is what separates industry leaders from their competitors.
These digital coworkers aren’t your basic chatbots with brittle automations that break when someone changes a form field. AI agents can reason through problems, adapt to new situations, and help achieve major business outcomes without constant human handholding.
This new division of labor is enhancing (not replacing) human expertise, empowering teams to move faster and smarter with systems designed to support growth at scale.
What is an agent workforce, and why does it matter?
An “agent workforce” is a collection of AI agents that operate like digital employees within your organization. Unlike rule-based automation tools of the past, these agents are adaptive, reasoning systems that can handle complex, multi-step business processes with minimal supervision.
This shift matters because it’s changing the enterprise operating model: You can push through more work through fewer hands — and you can do it faster, at a lower cost, and without increasing headcount.
Traditional automation understands very specific inputs, follows predetermined steps (based on those initial inputs), and gives predictable outputs. The problem is that these workflows break the moment something happens that’s outside of their pre-programmed logic.
With an agentic AI workforce, you give your agents objectives, provide context about constraints and preferences, and they figure out how to get the job done. They adapt when circumstances and business needs change, escalate issues to human teams when they hit roadblocks, and learn from each interaction (good or bad).
Legacy automation tools
Agentic AI workforce
Flexibility
Rule-based, fragile tasks; breaks on edge cases
Outcome-driven orchestration; plans, executes, and replans to hit targets
Collaboration
Siloed bots tied to one tool or team
Cross-functional swarms that coordinate across apps, data, and channels
Upkeep
High upkeep, constant script fixes and change tickets
Self-healing, adapts to UI/schema changes and retains learning
Ambiguity-ready, reasons through novel inputs and escalates with context
Focus
Project mindset; outputs delivered, then parked
KPI mindset; continuous execution against revenue, cost, risk, or CX goals
But the real challenge isn’t defining a single agent — it’s scaling to a true workforce.
From one agent to a workforce
While individual agent capabilities can be impressive, the real value comes from orchestrating hundreds or thousands of these digital workers to transform entire business processes. But scaling from one agent to an entire workforce is complex, and that’s the point where most proofs-of-concept stall or fail.
The key is to treat agent development as a long-term infrastructure investment, not a “project.” Enterprises that get stuck in pilot purgatory are those that start with a plan to finish, not a plan to scale.
Scaling agents requires governance and oversight — similar to how HR manages a human workforce. Without the infrastructure to do so, everything gets harder: coordination, monitoring, and control all break down as you scale.
One agent making decisions is manageable. Ten agents collaborating across a workflow needs structure. A hundred agents working across different business units? That takes ironed-out, enterprise-grade governance, security, and monitoring.
An agent-first AI stack is what makes it possible to scale your digital workforce with clear standards and consistent oversight. That stack includes:
Compute resources that scale as needed
Storage systems that handle multimodal data flows
Orchestration platforms that coordinate agent collaboration
Scaling AI apps and agents to deliver business-wide impact is an organizational redesign, and should be treated as such. Recognizing this early gives you the time to invest in platforms that can manage agent lifecycles from development through deployment, monitoring, and continuous improvement. Remember, the goal is scaling through iteration and improvement, not completion.
Business outcomes over chatbots
Many of the AI agents in use today are really just dressed-up chatbots with a handful of use cases: They can answer basic questions using natural language, maybe trigger a few API calls, but they can’t move the business forward without a human in the loop.
Real enterprise agents deliver end-to-end business outcomes, not answers.
They don’t just regurgitate information. They act autonomously, make decisions within defined parameters, and measure success the same way your business does: speed, cost, accuracy, and uptime.
Think about banking. The traditional loan approval workflow looks something like:
Human reviews application -> human checks credit score -> human validates documentation -> human makes approval decision
This process takes days or (more likely) weeks, is error-prone, creates bottlenecks if any single piece of information is missing, and scales poorly during high-demand periods.
With an agent workforce, banks can shift to “lights-out lending,” where agents handle the entire workflow from intake to approval and run 24/7 with humans only stepping in to focus on exceptions and escalations.
The results?
Loan turnaround times drop from days to minutes.
Operational costs fall sharply.
Compliance and accuracy improve through consistent logic and audit trails.
In manufacturing, the same transformation is happening in self-fulfilling supply chains. Instead of humans constantly monitoring inventory levels, predicting demand, and coordinating with suppliers, autonomous agents handle the entire process. They can analyze consumption patterns, predict shortages before they happen, automatically generate purchase orders, and coordinate delivery schedules with supplier systems.
The payoff here for enterprises is significant: fewer stockouts, lower carrying costs, and production uptime that isn’t tied to shift hours.
Security, compliance, and responsible AI
Trust in your AI systems will determine whether they help your organization accelerate or stall. Once AI agents start making decisions that impact customers, finances, and regulatory compliance, the question is no longer “Is this possible?” but “Is this safe at scale?”
Agent governance and trust are make-or-break for scaling a digital workforce. That’s why it deserves board-level visibility, not an IT strategy footnote.
As agents gain access to sensitive systems and act on regulated data, every decision they make traces back to the enterprise. There’s no delegating accountability: Regulators and customers will expect transparent evidence of what an agent did, why it did it, and which data informed its reasoning. Black-box decision-making introduces risks that most enterprises cannot tolerate.
Human oversight will never disappear completely, but it will change. Instead of humans doing the work, they’ll shift to supervising digital workers and stepping in when human judgment or ethical reasoning is needed. That layer of oversight is your safeguard for sustaining responsible AI as your enterprise scales.
Secure AI gateways and governance frameworks form the foundation for the trust in your enterprise AI, unifying control, enforcing policies, and helping maintain full visibility across agent decisions. However, you’ll need to design the governance frameworks before deploying agents. Designing with built-in agent governance and lifecycle control from the start helps avoid costly rework and compliance risks that come from trying to retrofit your digital workforce later.
Enterprises that design with control in mind from the start build a more durable system of trust that empowers them to scale AI safely and operate confidently — even under regulatory scrutiny.
Shaping the future of work with AI agents
So, what does this mean for your competitive strategy? Agent workforces aren’t just tweaking your existing processes. They’re creating entirely new ways to compete. The advantage isn’t about faster automation, but about building an organization where:
Work scales faster without adding headcount or sacrificing accuracy.
Decision cycles go from weeks to minutes.
Innovation isn’t limited by human bandwidth.
Traditional workflows are linear and human-dependent: Person A completes Task A and passes to Person B, who completes Task B, and so on. Agent workforces let dynamic, parallel processing happen where multiple agents collaborate in real time to optimize outcomes, not just check specific tasks off a list.
This is already leading to new roles that didn’t exist even five years ago:
Agent trainers specialize in teaching AI systems domain-specific knowledge.
Agent supervisors monitor performance and jump in when situations require human judgment.
Orchestration leads structure collaboration across different agents to achieve business objectives.
For early adopters, this creates an advantage that’s difficult for latecomer competitors to match.
An agent workforce can process customer requests 10x faster than human-dependent competitors, respond to market changes in real time, and scale instantly during demand spikes. The longer enterprises wait to deploy their digital workforce, the harder it becomes to close that gap.
Looking ahead, enterprises are moving toward:
Reasoning engines that can handle even more complex decision-making
Multimodal agents that process text, images, audio, and video simultaneously
Agent-to-agent collaboration for sophisticated workflow orchestration without human coordination
Enterprises that build on platforms designed for lifecycle governance and secure orchestration will define this next phase of intelligent operations.
Leading the shift to an agent-powered enterprise
If you’re convinced that agent workforces offer a strategic opportunity, here’s how leaders move from pilot to production:
Get executive sponsorship early. Agent workforce transformation starts at the top. Your CEO and board need to understand that this will fundamentally change how work gets done (for the better).
Invest in infrastructure before you need it. Agent-first platforms and governance frameworks can take months to implement. If you start pilot projects on temporary foundations, you’ll create technical debt that’s more expensive to fix later.
Build in governance frameworks from Day 1. Put security, compliance, and monitoring frameworks in place before your first agent goes live. These guardrails make scaling possible and safeguard your enterprise from risk as you add more agents to the mix.
Partner with proven platforms that specialize in agent lifecycle management. Building agentic AI applications takes expertise that most teams haven’t developed internally yet. Partnering with platforms designed for this purpose shortens the learning curve and reduces execution risk.
Enterprises that lead with vision, invest in foundations, and operationalize governance from day one will define how the future of intelligent work takes shape.
Explore how enterprises are building, deploying, and governing secure, production-ready AI agents with the Agent Workforce Platform.