Page 1 of 13
1 2 3 13

AI agents create virtual playgrounds to help robots get crucial training data

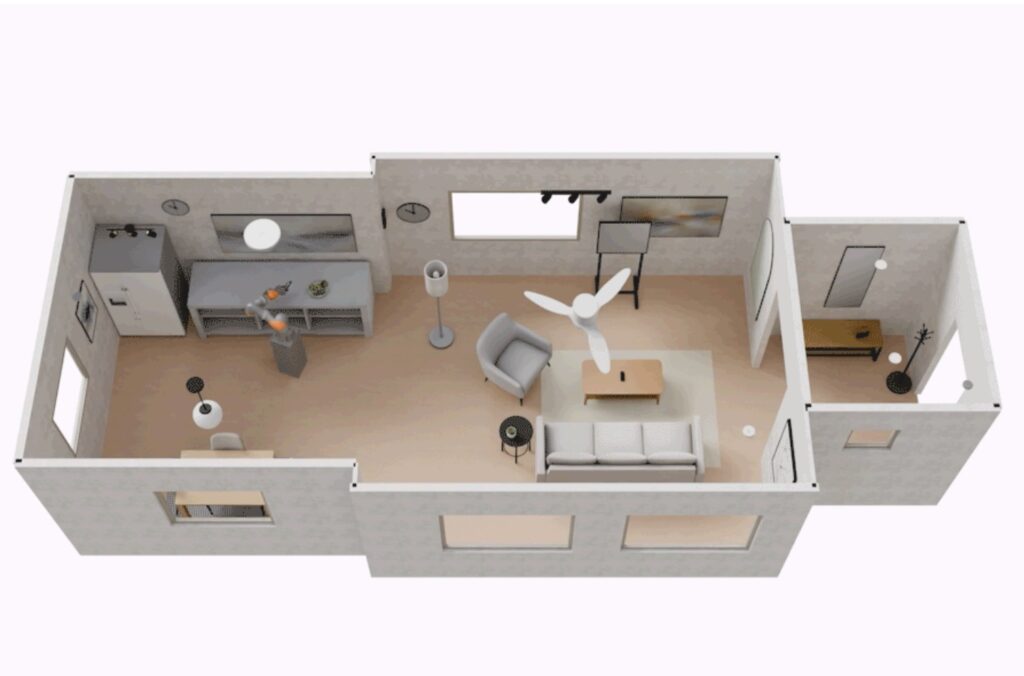
A new system developed at MIT uses three agents to piece together the objects, walls, and overall look of a 3D scene. Its realistic recreations of indoor spaces help robots practice skills and try out different ways of doing tasks before they’re powered on. Image: Tim Malieckal/MIT CSAIL using assets from the researchers.

By Alex Shipps

Robots walking down the street, surrounded by astounded onlookers, is an increasingly common sight. But these machines aren’t yet the do-it-all assistants you’d want working in a kitchen or factory, and a major bottleneck is data. Much like humans, robots learn best by experience. The challenge is that it’s labor-intensive and time-consuming to physically teach these machines so many actions across different settings.

“One natural idea is to use simulation as a training ground. While there has been significant progress over the last few years in the physics engines that power robotics simulators, one of the remaining challenges has been creating sufficiently rich and diverse simulation content to capture the complexity of the real world,” says Russ Tedrake, the Toyota Professor of Electrical Engineering and Computer Science (EECS), Aeronautics and Astronautics, and Mechanical Engineering at MIT, and a principal investigator at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL).

It turns out that AI agents, or semi-autonomous programs that “think” and complete well-defined tasks, could help produce the lifelike virtual settings that robots need. The new “SceneSmith” system developed by researchers at MIT CSAIL and Toyota Research Institute uses three agents to piece together the objects, walls, and overall look of a 3D scene. Its recreations of indoor spaces such as restaurants, bedrooms, and hotels are more realistic and detailed than prior systems, helping robots practice skills and try out different ways of doing tasks before they’re powered on. In turn, engineers save time on real-world testing.

The agents have a sense of how everyday places are supposed to look because they each call on a multi-modal system called a vision-language model (VLM), specifically the state-of-the-art VLM GPT-5.2. It’s trained on lots of text and images from the internet to handle more visual prompts. This advanced model gives each agent a sort of spatial knowledge: First, a “designer” agent generates the elements of a scene, then a “critic” advises whether it looks realistic, and finally, an “orchestrator” manages their back-and-forth, deciding when the design is done. Once the three VLMs wrap up their creative collaboration, the scene is ready to load directly into physics simulation software.

“We’ve found that the system can construct 3D scenes the way a human designer would,” says MIT EECS PhD student Nicholas Pfaff, a CSAIL researcher and a lead author on a paper with Tedrake presenting the work. “We made over 1,300 scenes using a leading VLM that has internet-scale priors, and it made insanely creative and diverse arrangements. I hadn’t taught the system to do that in the prompts; it just improvised.”

Talk to my agent

Thanks to VLM agents, you can ask SceneSmith to do things like “generate a garage with a car, a workbench, tires stacked in the corner, and a ladder against the wall,” and get a virtual playground rich with objects a robot can tinker with. These rooms are decorated with up to six times more items per scene than prior methods, making them great for helping robots learn skills such as putting a cup in the sink, placing fruit on plates, and moving a soda can from a shelf to a table.

With so many rich virtual environments handy, you can evaluate whether your robot is ready for deployment without so much trial and error in the physical world. The researchers tested out different action plans (also called “policies”) in SceneSmith’s digital worlds, generating 100 unique spaces in the process. A VLM agent evaluated each attempt, and it found the robot’s plans were faulty, with the machine often failing at its chores. Humans agreed with the model’s verdicts over 99 percent of the time, which could help roboticists weed out flawed approaches in simulation before a robot moves in the real world.

But how realistic are these virtual worlds, really? It can be difficult to prove outright, so the researchers approached the question from several angles. The most telling test: they dropped a pretrained robot policy — an AI controller trained largely on real-world data, which had never seen a SceneSmith scene — into the generated environments. In one test, users told the system to “take the apple from the bowl and place it onto the cutting board,” and the simulated robot did exactly that. If the scenes didn’t closely resemble the real settings the policy had learned from, it simply wouldn’t have worked.

The team also teleoperated robots through the virtual spaces, guiding them to open cabinets, put away bottles, and navigate between rooms. Their experiments revealed that the environments hold up under sustained physical interaction, expanding beyond visual inspection.

Behind the scenes

The agents that SceneSmith uses each have a well-defined role in the generative process, fleshing out scenes in stages. They essentially create a floor plan and bring it to life.

Let’s say you wanted to create a scene similar to the first floor of a house. The “designer” VLM would start with a general layout, which the “critic” reviews, and then the “orchestrator” signs off. The agents repeat this approach for each step: adding furniture, placing objects on walls and then ceilings, and finally, dropping in objects that robots can manipulate. For example, the VLMs can add cabinets that the robots can open and close — an articulated item, which prior baselines didn’t often have.

At each stage, the second VLM ensures the scene is practical, advising that a bathtub is removed from a living room, for example. The third VLM ensures a high-quality scene is generated, even taking the design process a few turns back if the visuals aren’t up to par. Once the three VLMs wrap up their creative collaboration, the mechanics of the physical world are added via simulation software.

With a sound understanding of how rooms should look, where objects should be placed, and real-world physics, SceneSmith has a noticeable edge over prior methods. Compared to scene-generation baselines such as “HSM” and “Holodeck,” SceneSmith made environments with more objects, including a private office, a pottery store, and even a Minecraft-themed gaming room.

SceneSmith was also a favorite among over 200 users. They found the system’s visuals to be more realistic over 90 percent of the time. They also observed that, generally speaking, it followed prompts more closely than other approaches did. In other words, it was the best at generating the virtual playgrounds users actually wanted to see.

A system of many talents

Realism, diversity, and richness are all strong suits for SceneSmith, even when it comes to generating individual 3D objects. You can prompt it to create a rolling serving cart, and it’ll make a 2D image that it then turns into a detailed model with physical properties like mass, friction, and inertia.

Such a detailed process does come with a speed trade-off, though. It can take multiple hours to produce a single scene because the agents are creating and closely scrutinizing each object. With more computing power, the system could see dramatic increases in efficiency. CSAIL engineers are also hoping to expand to deformable objects (like sponges), should extensive 3D libraries become available.

“SceneSmith represents a significant advance in this regard by providing an agentic framework for generating simulation-ready indoor environments just from a simple text prompt,” says Jeremy Binagia, an applied scientist at Amazon Robotics who wasn’t involved in the research. “It advances the state of the art in several ways, including pushing the limits of the density of objects in the simulated environment, ensuring that all of the objects are physically accurate (versus just being visually realistic), and creating assets that are not constrained to a fixed library, since they can be generated via text-to-3D.”

Pfaff and Tedrake wrote the paper with Thomas Cohn SM ’24, an MIT PhD student and CSAIL researcher; and Toyota Research Institute roboticists Sergey Zakharov and Rick Cory SM ’08, PhD ’10. Their work was supported, in part, by Amazon, the U.S. Office of Naval Research, the Toyota Research Institute, and the U.S. National Science Foundation.

The team presented their findings as a spotlight at the 2026 International Conference on Machine Learning.
Wristband enables wearers to control a robotic hand with their own movements

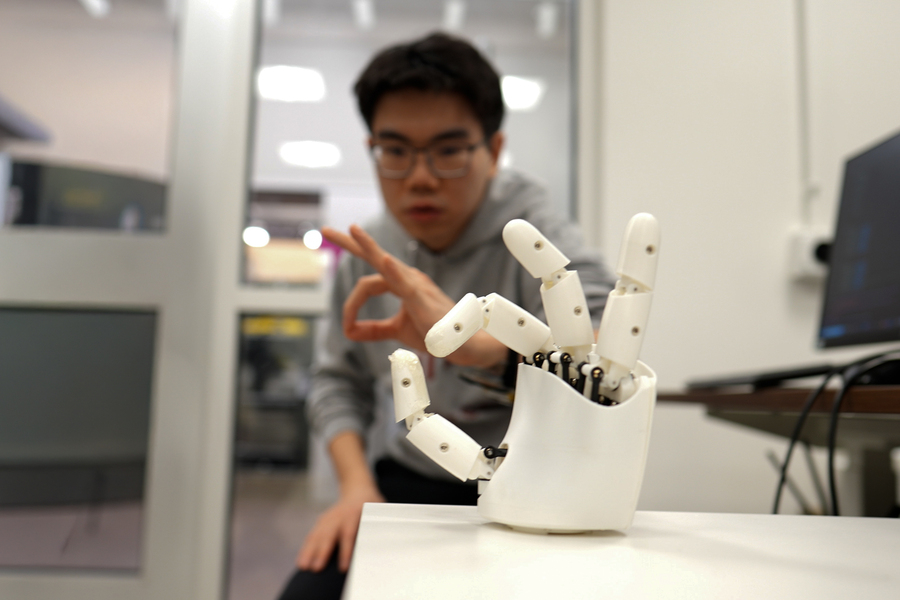
Graduate student Dian Li working with a robotic hand. Credit: Melanie Gonick.
By Jennifer Chu

The next time you’re scrolling your phone, take a moment to appreciate the feat: The seemingly mundane act is possible thanks to the coordination of 34 muscles, 27 joints, and over 100 tendons and ligaments in your hand. Indeed, our hands are the most nimble parts of our bodies. Mimicking their many nuanced gestures has been a longstanding challenge in robotics and virtual reality.

Now, MIT engineers have designed an ultrasound wristband that precisely tracks a wearer’s hand movements in real-time. The wristband produces ultrasound images of the wrist’s muscles, tendons, and ligaments as the hand moves, and is paired with an artificial intelligence algorithm that continuously translates the images into the corresponding positions of the five fingers and palm.

The researchers can train the wristband to learn a wearer’s hand motions, which the device can communicate in real-time to a robot or a virtual environment.

In demonstrations, the team has shown that a person wearing the wristband can wirelessly control a robotic hand. As the person gestures or points, the robot does the same. In a sort of wireless marionette interaction, the wearer can manipulate the robot to play a simple tune on the piano and shoot a small basketball into a desktop hoop. With the same wristband, a wearer can also manipulate objects on a computer screen, for instance pinching their fingers together to enlarge and minimize a virtual object.

The team is using the wristband to gather hand motion data from many more users with different hand sizes, finger shapes, and gestures. They envision building a large dataset of hand motions that can be plumbed, for instance, to train humanoid robots in dexterity tasks, such as performing certain surgical procedures. The ultrasound band could also be used to grasp, manipulate, and interact with objects in video games, design applications, or other virtual settings.

“We think this work has immediate impact in potentially replacing hand tracking techniques with wearable ultrasound bands in virtual and augmented reality,” says Xuanhe Zhao, the Uncas and Helen Whitaker Professor of Mechanical Engineering at MIT. “It could also provide huge amounts of training data for dexterous humanoid robots.”

Zhao, Gengxi Lu, and their colleagues present the wristband’s new design in a paper which appeared in Nature Electronics. Their MIT co-authors are former postdocs Xiaoyu Chen, Shucong Li, and Bolei Deng; graduate students SeongHyeon Kim and Dian Li; postdocs Shu Wang and Runze Li; and Anantha Chandrakasan, MIT provost and the Vannevar Bush Professor of Electrical Engineering and Computer Science. Other co-authors are graduate students Yushun Zheng and Junhang Zhang, Baoqiang Liu, Chen Gong, and Professor Qifa Zhou from the University of Southern California.

Seeing strings

There are currently a number of approaches to capturing and mimicking human hand dexterity in robots. Some approaches use cameras to record a person’s hand movements as they manipulate objects or perform tasks. Others involve having a person wear a glove with sensors, which records the person’s hand movements and transmits the data to a receiving robot. But erecting a complex camera system for different applications is impractical and prone to visual obstacles. And sensor-laden gloves could limit a person’s natural hand motions and sensations.

A third approach uses the electrical signals from muscles in the wrist or forearm that scientists then correlate with specific hand movements. Researchers have made significant advances in this approach, however these signals are easily affected by noise in the environment. They are also not sensitive enough to distinguish subtle changes in movements. For instance, they may discern whether a thumb and index finger are pinched together or pulled apart, but not much of the in-between path.

Zhao’s team wondered whether ultrasound imaging might capture more dexterous and continuous hand movements. His group has been developing various forms of ultrasound stickers — miniaturized versions of the transducers used in doctor’s offices that are paired with hydrogel material that can safely stick to skin.

In their new study, the team incorporated the ultrasound sticker design into a wearable wristband to continuously image the muscles and tendons in the wrist.

“The tendons and muscles in your wrist are like strings pulling on puppets, which are your fingers,” Lu says. “So the idea is: Each time you take a picture of the state of the strings, you’ll know the state of the hand.”

Mapping manipulation

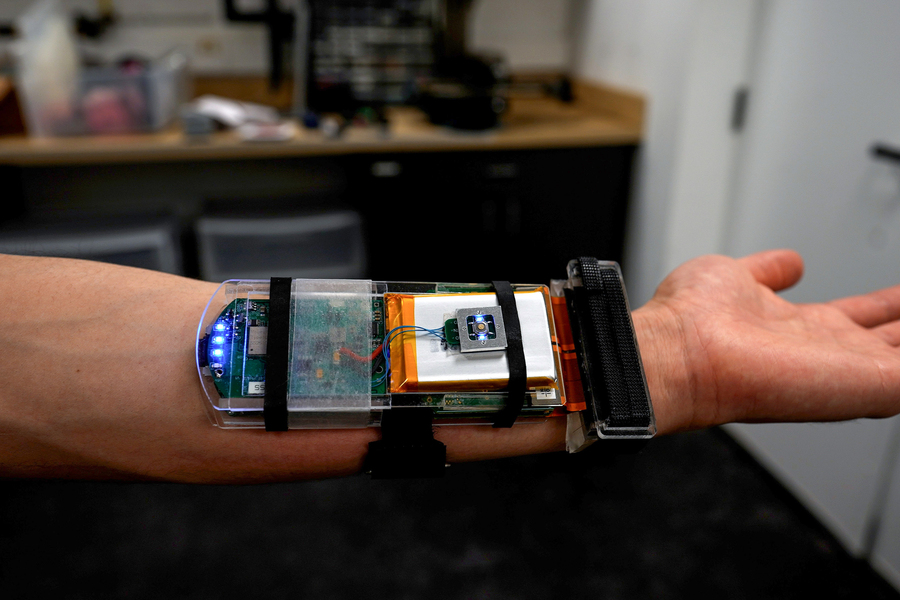
The team designed a wristband with an ultrasound sticker that is the size of a smartwatch, and added onboard electronics that are about as small as a cellphone. They attached the wristband to a volunteer’s wrist and confirmed that the device produced clear and continuous images of the wrist as the volunteer moved their fingers in various gestures.

The challenge then was to relate the black and white ultrasound images of the wrist to specific positions of the hand. As it turns out, the fingers and thumb are capable of 22 degrees of freedom, or different ways of extending or angling. The researchers found that they could identify specific regions in their ultrasound images of the wrist that correlate to each of these 22 degrees of freedom. For instance, changes in one region relate to thumb extension, while changes in another region correlate with movements of the index finger.

To establish these connections, a volunteer wearing the wristband would move their hand in various positions while the researchers recorded the gestures with multiple cameras surrounding the volunteer. By matching changes in certain regions of the ultrasound images with hand positions recorded by the cameras, the team could label wrist image regions with the corresponding degree of freedom in the hand. But to do this translation continuously, and in real-time, would be an impossible task for humans.

So, the team turned to artificial intelligence. They used an AI algorithm that can be trained to recognize image patterns and correlate them with specific labels and, in this case, the hand’s various degrees of freedom. The researchers trained the algorithm with ultrasound images that they meticulously labeled, annotating the image regions associated with a specific degree of freedom. They tested the algorithm on a new set of ultrasound images and found it correctly predicted the corresponding hand gestures.

Once the researchers successfully paired the AI algorithm with the wristband, they tested the device on more volunteers. For the new study, eight volunteers with different hand and wrist sizes wore the wristband while they formed various hand gestures and grasps, including making the signs for all 26 letters in American Sign Language. They also held objects such as a tennis ball, a plastic bottle, a pair of scissors, and a pencil. In each case, the wristband precisely tracked and predicted the position of the hand.

MIT engineers have designed an ultrasound wristband that precisely tracks a wearer’s hand movements in real time. The wristband produces ultrasound images of the wrist’s muscles, tendons, and ligaments as the hand moves. Credit: Melanie Gonick.
To demonstrate potential applications, the team developed a simple computer program that they wirelessly paired with the wristband. As a wearer went through the motions of pinching and grasping, the gestures corresponded to zooming in and out on an object on the computer screen, and virtually moving and manipulating it in a smooth and continuous fashion.

The researchers also tested the wristband as a wireless controller of a simple commercial robotic hand. While wearing the wristband, a volunteer went through the motions of playing a keyboard. The robot in turn mimicked the motions in real-time to play a simple tune on a piano. The same robot was also able to mimic a person’s finger taps to play a desktop basketball game.

Zhao is planning to further miniaturize the wristband’s hardware, as well as train the AI software on many more gestures and movements from volunteers with wider ranging hand sizes and shapes. Ultimately, the team is building toward a wearable hand tracker that can be worn by anyone, to wirelessly manipulate humanoid robots or virtual objects with high dexterity.

“We believe this is the most advanced way to track dexterous hand motion, through wearable imaging of the wrist,” Zhao says. “We think these wearable ultrasound bands can provide intuitive and versatile controls for virtual reality and robotic hands.”

This research was supported, in part, by MIT, the U.S. National Institutes of Health, the U.S. National Science Foundation, the U.S. Department of Defense, and Singapore National Research Foundation through the Singapore-MIT Alliance for Research and Technology.

New research enables a robot to chart a better course

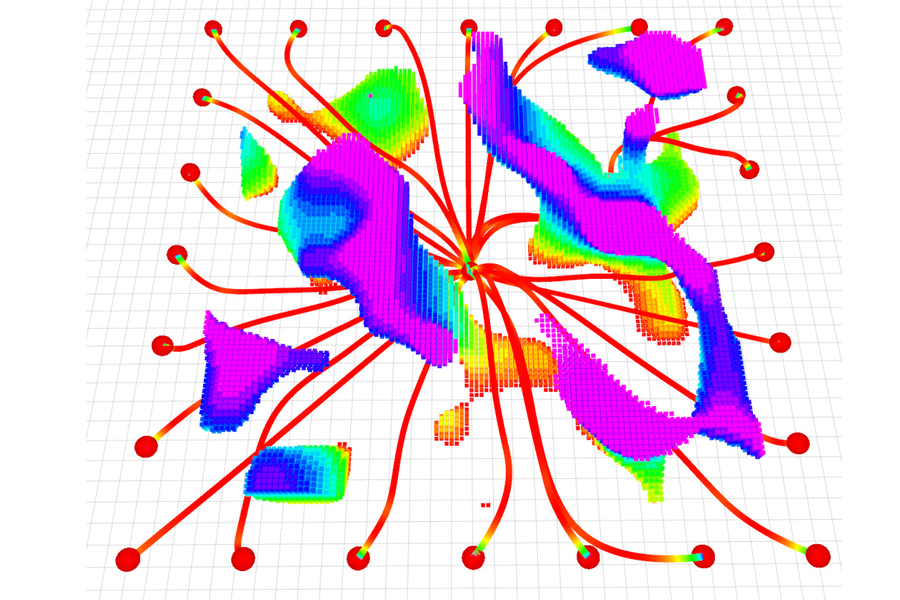
A figure shows multiple flight pathways as a UAV starts from the center and flies toward 24 goals (dots around perimeter). The flight pathways are mainly red and end in cool colors, showing reduced speed. The rainbow clouds represent obstacles, with cooler colors representing taller obstacles. Credit: Courtesy of the researchers.
By Adam Zewe

In the aftermath of a devastating earthquake, unpiloted aerial vehicles (UAVs) could fly through a collapsed building to map the scene, giving rescuers information they need to quickly reach survivors. 

But this remains an extremely challenging problem for an autonomous robot, which would need to swiftly adjust its trajectory to avoid sudden obstacles while staying on course.

Researchers from MIT and the University of Pennsylvania developed a new trajectory-planning system that tackles both challenges at once. Their technique enables a UAV to react to obstacles in milliseconds while staying on a smooth flight path that minimizes travel time. 

Their system uses a new mathematical formulation that ensures the robot travels safely to its destination along a feasible path, and that is less computationally intensive than other techniques. In this way, it generates smoother trajectories faster than state-of-the-art methods.

The trajectory planner is also efficient enough for real-time flight using only the robot’s onboard computer and sensors. 

Named MIGHTY, the open-source system does not require proprietary software packages that can cost hundreds of thousands of dollars. It could be more readily deployed in a wider variety of real-world settings.

In addition to search-and-rescue, MIGHTY could be utilized in applications like last-mile delivery in urban spaces, where UAVs need to avoid buildings, wires, and people, or in industrial inspection of complex structures, such as wind turbines.

“MIGHTY achieves comparable or better performance using only open-source tools, which means any researcher, student, or company — anywhere in the world — can use it freely. By removing this cost barrier, MIGHTY helps democratize high-performance trajectory planning and opens the door for a much broader community to build on this work,” says Kota Kondo, an aeronautics and astronautics graduate student and lead author of a paper on this trajectory planner.

Kondo is joined on the paper by Yuwei Wu, a graduate student at the University of Pennsylvania; Vijay Kumar, a professor at UPenn; and senior author Jonathan P. How, a Ford professor of aeronautics and astronautics and a principal investigator in the Laboratory for Information and Decision Systems (LIDS) and the Aerospace Controls Laboratory (ACL) at MIT. The research appears in IEEE Robotics and Automation Letters.

Overcoming trade-offs           

When Kondo was a child, the Fukushima Daiichi nuclear accident occurred following the Great East Japan Earthquake. With school cancelled, Kondo was stuck at home and watched the news every day as workers explored and secured the reactor site. Some workers still had to enter hazardous areas to contain the damage and assess the situation, exposing them to high doses of radioactive material.

“I became passionate about creating autonomous robots that can go into these dynamic and dangerous situations, then come back and report to humans who stay out of harm’s way,” Kondo says.

This task requires a strong trajectory planner, which is software that decides the path a robot should follow to safely get from point A to point B. 

But many existing systems force tradeoffs that limit performance. 

While some commercial systems can rapidly generate smooth trajectories, they can cost hundreds of thousands of dollars. Open-source alternatives often underperform compared to commercial solvers or are difficult to use.      

With MIGHTY, Kondo and his colleagues developed an open-source system that produces high-quality, smooth trajectories while reacting to obstacles in real-time, and which runs fast enough for flight using only onboard components.

To do this, they overcame a key challenge that limits many open-source systems. 

These methods usually estimate how long it will take the robot to get from point A to point B as a first step. From that fixed estimation of travel time, the planner finds the best path to reach the destination.

While using a fixed travel time allows the planner to rapidly generate a trajectory, it has drawbacks. For one, if the UAV must go far out of its way to avoid obstacles, it could be forced to crank up the speed to meet the fixed travel-time budget. This makes it harder to avoid sudden hazards.

A MIGHTY method

Instead, MIGHTY uses a mathematical technique, called a Hermite spline, that optimizes the travel time and flight path together, in a single step, to form a smooth trajectory that can be precisely controlled.

“Optimizing the spatial and temporal components together gets us better results, but now the optimization becomes so much bigger that it is harder to solve in a feasible amount of time,” Kondo says.

The researchers used a clever technique to reduce this computational overhead. 

Instead of generating a trajectory from scratch each time, MIGHTY makes an initial guess of a trajectory. Then it refines the trajectory through an iterative optimization, using a map of the scene generated by the UAV’s lidar sensors.

“We can make a decent guess of what the trajectory should be, which is a lot faster than generating the entire thing from nothing,” Kondo says.

This enables MIGHTY to react in real-time to unknown obstacles while keeping the trajectory smooth and minimizing travel time. The system utilizes the UAV’s onboard components, which is important for applications where a robot might travel far from a base station.

In simulated experiments, MIGHTY needed only about 90 percent of the computation time required by state-of-the-art methods, while safely reaching its destination about 15 percent faster than these approaches. 

When they tested the system on real robots, it reached a speed of 6.7 meters per second while avoiding every obstacle that appeared in its path.

“With MIGHTY, everything is integrated in one piece. It doesn’t need to talk to any other piece of software to get a solution. This helps us be even faster than some of the commercial solvers,” Kondo says.

In the future, the researchers want to enhance MIGHTY so it can be used to control multiple robots at once and conduct more flight experiments in challenging environments. They hope to continue improving the open-source system based on user feedback.

“MIGHTY makes an important contribution to agile robot navigation by revisiting the trajectory representation itself. Hermite splines have already been successfully used in visual simultaneous localization and mapping, and it is nice to see their advantages now being exploited for trajectory planning in mobile robots. By enabling joint optimization of path geometry, timing, velocity, and acceleration while retaining local control of the trajectory, MIGHTY gives robots more freedom to compute fast, dynamically feasible motions in cluttered environments,” says Davide Scaramuzza, professor and director of the Robotics and Perception Group at the University of Zurich, who was not involved with this research.

This research was funded, in part, by the United States Army Research Laboratory and the Defense Science and Technology Agency in Singapore.

Light-activated gel could impact wearables, soft robotics, and more

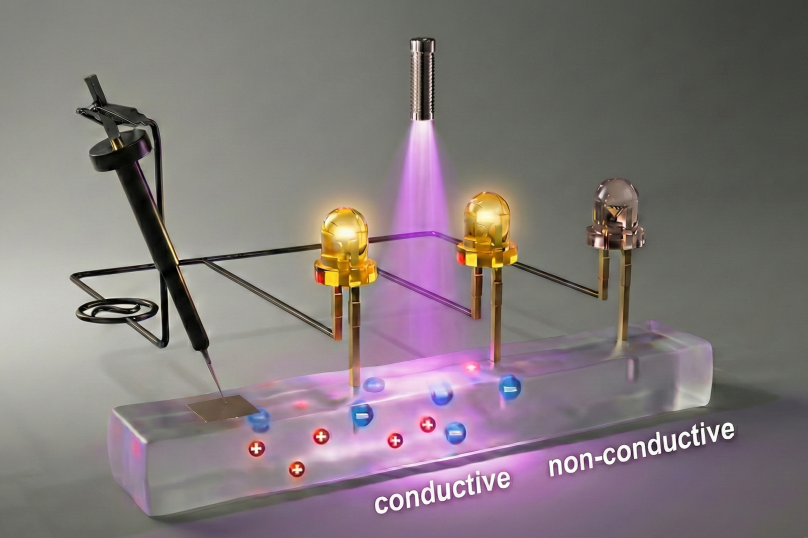
MIT engineers and colleagues have developed a soft, flexible gel that dramatically changes its conductivity upon the application of light. This figure shows a soft, stretchable circuit created with a rectangular bar of the gel. A copper electrode is attached to the left. A stylus and associated metal network connects the electrode to three “stations” on the bar. Light has been shone on the first two stations, creating conductivity that turns on each station’s lightbulb. Because the third station has not been exposed to light it is nonconductive and the bulb is off. Credits: Image courtesy of the Wallin lab.
Consider the chief difference between living systems and electronics: The first is generally soft and squishy, while the latter is hard and rigid. Now, in work that could impact human-machine interfaces, biocompatible devices, soft robotics, and more, MIT engineers and colleagues have developed a soft, flexible gel that dramatically changes its conductivity upon the application of light.

Enter the growing field of ionotronics, which involves transferring data through ions, or charged molecules. Electronics does the same, with electrons. But while the latter is well established, ionotronics is still being developed, with one huge exception: living systems. The cells in our bodies communicate with a variety of ions, from potassium to sodium.

Ionotronics, in turn, can provide a bridge between electronics and biological tissues. Potential applications range from soft wearable technology to human-machine interfaces

“We’ve found a mechanism to dynamically control local ion population in a soft material,” says Thomas J. Wallin, the John F. Elliott Career Development Professor in MIT’s Department of Materials Science and Engineering and leader of the work. “That could allow a system that is self-adaptive to environmental stimuli, in this case light.” In other words, the system could automatically change in response to changes in light, which could allow complex signal processing in soft materials.

An open-access paper about the work was published online recently in Nature Communications.

A growing field

Although others have developed ionotronic materials with high conductivities that allow the quick movement of ions, those conductivities cannot be controlled. “What we’re doing is using light to switch a soft material from insulating to something that is 400 times more conductive,” says Xu Liu, first author of the paper and former MIT postdoc in materials science and engineering who is now an incoming assistant professor at King’s College London.

Key to the work is a class of materials known as photo-ion generators (PIGs). These can become some 1,000 times more conductive upon the application of light. The MIT team optimized a way to incorporate a PIG into polyurethane rubber by first dissolving a PIG powder into a solvent, and then using a swelling method to get it into the rubber.

Much potential

In the material reported in the current work, the change in conductivity is irreversible. But Liu is confident that future versions could switch back and forth between insulating and conducting states.

She notes that the current material was developed using only one kind of PIG, polymer (the polyurethane rubber), and solvent, but there are many other kinds of all three. So there is great potential for creating even better light-responsive soft materials.

Liu also notes the potential for developing soft materials that respond to other environmental stimuli, such as heat or magnetism. “We’re inspired to do more work in this field by changing the driving force from light to other forms of environmental stimuli,” she says.

“Our work has the potential to lead to the creation of a subfield that we call soft photo-ionotronics,” Liu continues. “We are also very excited about the opportunities from our work to create new soft machines impacting soft wearable technology, human-machine interfaces, robotics, biomedicine, and other fields.”

Additional authors of the paper are Steven M. Adelmund, Shahriar Safaee, and Wenyang Pan of Reality Labs at Meta. 

Read the work in full

Soft photo-ionotronics, Xu Liu, Steven M. Adelmund, Shahriar Safaee, Wenyang Pan & Thomas J. Wallin, Nature Communications (2026).

Robotically assembled building blocks could make construction more efficient and sustainable

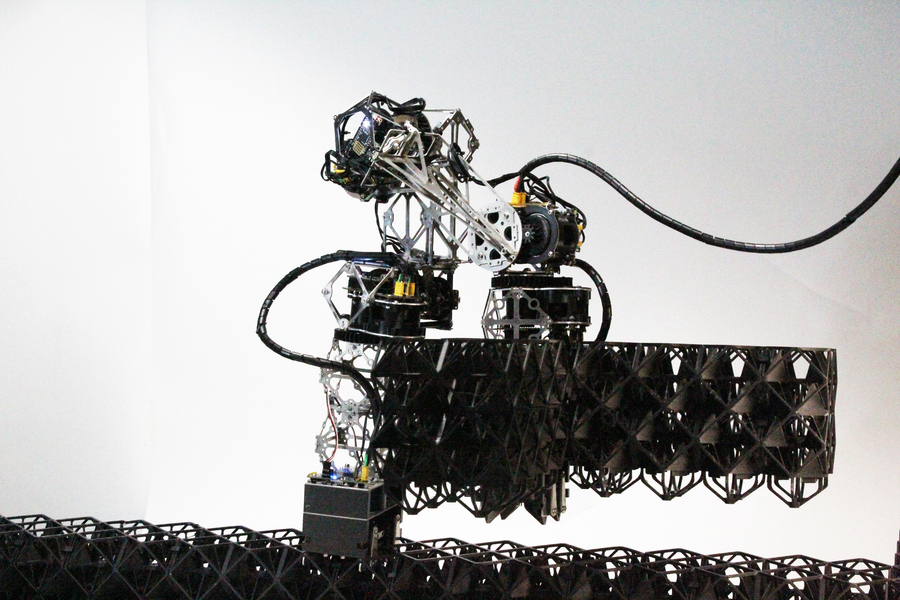
A robot carries three voxels as it walks across a voxel structure. Modular Inchworm Lattice Assembler robots, or MILAbots, use grippers on each end to place voxel building blocks and engage the snap-fit connections. Credit: Courtesy of the researchers.
By Adam Zewe

Robotically assembled building blocks could be a more environmentally friendly method for erecting large-scale structures than some existing construction techniques, according to a new study by MIT researchers.

The team conducted a feasibility study to evaluate the efficiency of constructing a simple building using “voxels,” which are modular 3D subunits that assemble into complex, durable structures.

After studying the performance of multiple voxels, the researchers developed three new designs intended to streamline building construction. They also produced a robotic assembler and a user-friendly interface for generating voxel-based building layouts and feeding instructions to the robots.

Their results indicate this voxel-based robotic assembly system could reduce embodied carbon — all of the carbon emitted during the lifecycle of building materials — by as much as 82 percent, compared with popular techniques like 3D concrete printing, precast modular concrete, and steel framing. The system would also be competitive in terms of cost and construction time. However, the choice of materials used to manufacture the voxels does play a major role in their carbon footprint and cost.

While scalability, durability, long-term robustness, and important considerations like fire resistance remain to be explored before such a system could be widely deployed, the researchers say these initial results highlight the potential of this approach for automated, on-site construction.

“I’m particularly excited about how the robotic assembly of discrete lattices can enable a practical way to apply digital fabrication to the built environment in a way that can let us build much more efficiently and sustainably,” says Miana Smith, a graduate student in the Center for Bits and Atoms (CBA) at MIT and lead author the study.

She is joined on the paper by Paul Richard, a graduate student at École Polytechnique Fédérale de Lausanne in Switzerland and former visiting researcher at MIT; Alfonso Parra Rubio, a CBA graduate student; and senior author Neil Gershenfeld, an MIT professor and the director of the CBA. The research appears in Automation in Construction.

Designing better building blocks

Over the past several years, researchers in the Center for Bits and Atoms have been developing voxels, which are lattice-structured building blocks that can be assembled into objects with high strength and stiffness, like airplane wings, wind turbine blades, and space structures.

“Here, we are taking aerospace principles and applying them to buildings. Why don’t we make buildings as efficiently as we make airplanes?” Gershenfeld says, based on prior work his lab has done on voxel assembly with NASA, Airbus, and Boeing.

To explore the feasibility of voxel-based assembly strategies for buildings, the researchers first evaluated the mechanical performance and sustainability of eight existing voxel designs, including a cuboctahedron made from glass-reinforced nylon and a Kelvin lattice made from steel.

Based on those evaluations, they developed a set of three voxels using a new geometry that could be more easily assembled robotically into a larger structure. The new design, based on a high-strength and high-stiffness octet lattice, mechanically self-aligns into rigid structures.

“The interlocking nature of these voxels means we can get nice mechanical properties without needing to have a lot of connectors in the system, so the construction process can run a lot faster,” Smith says.

To accelerate construction, they designed a robotic assembly system based on inchworm-like robots that crawl across a voxel structure by anchoring and extending their bodies. These Modular Inchworm Lattice Assembler robots, or MILAbots, use grippers on each end to place voxel building blocks and engage the snap-fit connections.

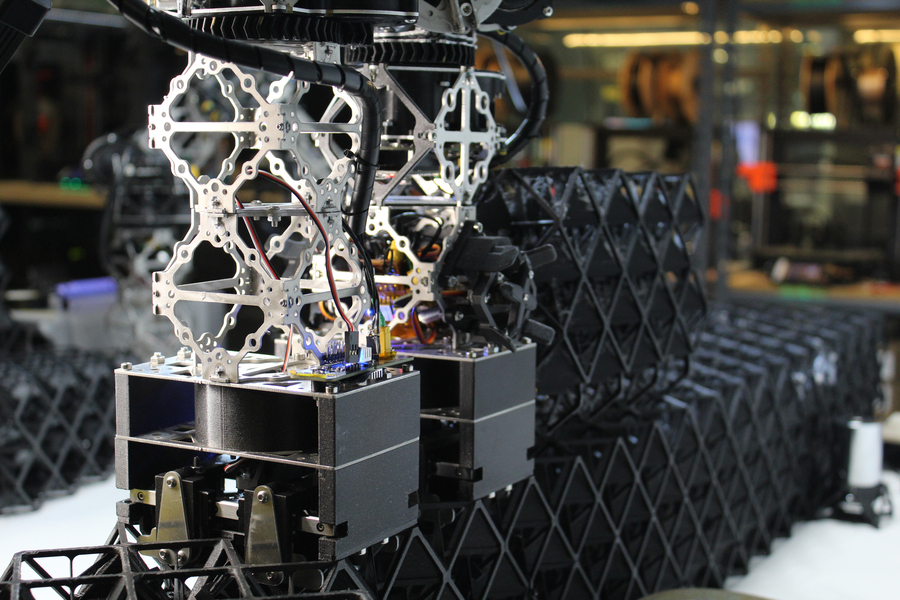
“The robots can assemble the voxels by dropping them into place and then stepping on them to have the pieces interlock. We can do precise maneuvers based on the mechanical relationship between the robots and the voxels,” Smith explains.

The team studied the embodied carbon needed to fabricate their new voxel designs using three materials: plastic, plywood, and steel. Then they evaluated the throughput and cost of using the robotic assembly system to build a simple, one-story building. The researchers compared these estimates with the performance of other construction methods.

The MILAbot’s unique legs, seen here in close up. “The robots can assemble the voxels by dropping them into place and then stepping on them to have the pieces interlock,” Miana Smith explains. Credit: Courtesy of the researchers.
Potential environmental benefits

They found that most existing voxels, and especially those made from plastics, performed poorly compared to existing methods in terms of sustainability, but the steel and wood voxels they designed offered significant environmental benefits.

For instance, utilizing their steel voxels would generate only 36 percent of the embodied carbon required for 3D concrete printing and 52 percent of the embodied carbon of precast concrete. The plywood voxels had the lowest carbon footprint, requiring about 17 percent and 24 percent of the embodied carbon needed, respectively.

“There is still a potential viable option for a plastics-based voxel approach, we just have to be a bit more strategic about which types of plastics, infills, and geometries we use,” Smith says.

In addition, projected on-site assembly time for the steel and wood voxel approaches averaged 99 hours, whereas existing construction methods averaged 155 hours.

These speed benefits rely on the distributed nature of voxel-based assembly. While one MILAbot working alone is far slower than existing techniques, with a team of 20 robots working in parallel, the system catches up to or surpasses existing automation methods at a lower cost.

“One benefit of this method is how incremental it is. You can start building, and if it turns out you need a new room, you can just add onto the structure. It is also reversible, so if your use changes, you can dissemble the voxels and change the structure,” Gershenfeld says.

The researchers also developed an interface that enables users to input or hand-design a voxelized structure. The automatic system determines the paths the MILAbots should follow for construction and sends commands to the assemblers.

The next step in this project will be a larger testbed in Bhutan, using the “super fab lab” that CBA helped set up there to replicate the robots to test construction for a planned sustainable city, Gershenfeld says.

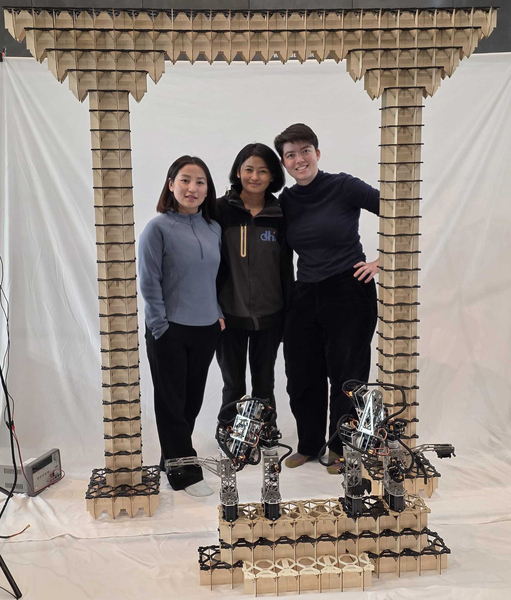
Left to right: Yeshey Wangmo Lepcha, Tshering Wangzom, and Miana Smith stand under an arch created with voxels, as part of a working visit from the Bhutanese team to MIT. Credit: Courtesy of the researchers.
Additional areas of future work include studying the stability of voxel structures under lateral loads, improving the design tool to account for the physics of the system, enhancing the MILAbots, and evaluating voxels that have integrated sheeting, insulation, or electrical and plumbing routing.

“Our work helps support why doing this type of distributed robot assembly might be a practical way to bring digital fabrication into building construction,” Smith says.

This work was funded, in part, by the MIT Center for Bits and Atoms Consortia.

AI system learns to keep warehouse robot traffic running smoothly

By Adam Zewe

Inside a giant autonomous warehouse, hundreds of robots dart down aisles as they collect and distribute items to fulfill a steady stream of customer orders. In this busy environment, even small traffic jams or minor collisions can snowball into massive slowdowns.

To avoid such an avalanche of inefficiencies, researchers from MIT and the tech firm Symbotic developed a new method that automatically keeps a fleet of robots moving smoothly. Their method learns which robots should go first at each moment, based on how congestion is forming, and adapts to prioritize robots that are about to get stuck. In this way, the system can reroute robots in advance to avoid bottlenecks.

The hybrid system utilizes deep reinforcement learning, a powerful artificial intelligence method for solving complex problems, to figure out which robots should be prioritized. Then, a fast and reliable planning algorithm feeds instructions to the robots, enabling them to respond rapidly in constantly changing conditions.

In simulations inspired by actual e-commerce warehouse layouts, this new approach achieved about a 25 percent gain in throughput over other methods. Importantly, the system can quickly adapt to new environments with different quantities of robots or varied warehouse layouts.

“There are a lot of decision-making problems in manufacturing and logistics where companies rely on algorithms designed by human experts. But we have shown that, with the power of deep reinforcement learning, we can achieve super-human performance. This is a very promising approach, because in these giant warehouses even a two or three percent increase in throughput can have a huge impact,” says Han Zheng, a graduate student in the Laboratory for Information and Decision Systems (LIDS) at MIT and lead author of a paper on this new approach.

Zheng is joined on the paper by Yining Ma, a LIDS postdoc; Brandon Araki and Jingkai Chen of Symbotic; and senior author Cathy Wu, the Class of 1954 Career Development Associate Professor in Civil and Environmental Engineering (CEE) and the Institute for Data, Systems, and Society (IDSS) at MIT, and a member of LIDS. The research appears today in the Journal of Artificial Intelligence Research.

Rerouting robots

Coordinating hundreds of robots in an e-commerce warehouse simultaneously is no easy task.

The problem is especially complicated because the warehouse is a dynamic environment, and robots continually receive new tasks after reaching their goals. They need to be rapidly redirected as they leave and enter the warehouse floor.

Companies often leverage algorithms written by human experts to determine where and when robots should move to maximize the number of packages they can handle.

But if there is congestion or a collision, a firm may have no choice but to shut down the entire warehouse for hours to manually sort the problem out.

“In this setting, we don’t have an exact prediction of the future. We only know what the future might hold, in terms of the packages that come in or the distribution of future orders. The planning system needs to be adaptive to these changes as the warehouse operations go on,” Zheng says.

The MIT researchers achieved this adaptability using machine learning. They began by designing a neural network model to take observations of the warehouse environment and decide how to prioritize the robots. They train this model using deep reinforcement learning, a trial-and-error method in which the model learns to control robots in simulations that mimic actual warehouses. The model is rewarded for making decisions that increase overall throughput while avoiding conflicts.

Over time, the neural network learns to coordinate many robots efficiently.

“By interacting with simulations inspired by real warehouse layouts, our system receives feedback that we use to make its decision-making more intelligent. The trained neural network can then adapt to warehouses with different layouts,” Zheng explains.

It is designed to capture the long-term constraints and obstacles in each robot’s path, while also considering dynamic interactions between robots as they move through the warehouse.

By predicting current and future robot interactions, the model plans to avoid congestion before it happens.

After the neural network decides which robots should receive priority, the system employs a tried-and-true planning algorithm to tell each robot how to move from one point to another. This efficient algorithm helps the robots react quickly in the changing warehouse environment.

This combination of methods is key.

“This hybrid approach builds on my group’s work on how to achieve the best of both worlds between machine learning and classical optimization methods. Pure machine-learning methods still struggle to solve complex optimization problems, and yet it is extremely time- and labor-intensive for human experts to design effective methods. But together, using expert-designed methods the right way can tremendously simplify the machine learning task,” says Wu.

Overcoming complexity

Once the researchers trained the neural network, they tested the system in simulated warehouses that were different than those it had seen during training. Since industrial simulations were too inefficient for this complex problem, the researchers designed their own environments to mimic what happens in actual warehouses.

On average, their hybrid learning-based approach achieved 25 percent greater throughput than traditional algorithms as well as a random search method, in terms of number of packages delivered per robot. Their approach could also generate feasible robot path plans that overcame congestion caused by traditional methods.

“Especially when the density of robots in the warehouse goes up, the complexity scales exponentially, and these traditional methods quickly start to break down. In these environments, our method is much more efficient,” Zheng says.

While their system is still far away from real-world deployment, these demonstrations highlight the feasibility and benefits of using a machine learning-guided approach in warehouse automation.

In the future, the researchers want to include task assignments in the problem formulation, since determining which robot will complete each task impacts congestion. They also plan to scale up their system to larger warehouses with thousands of robots.

Generative AI improves a wireless vision system that sees through obstructions

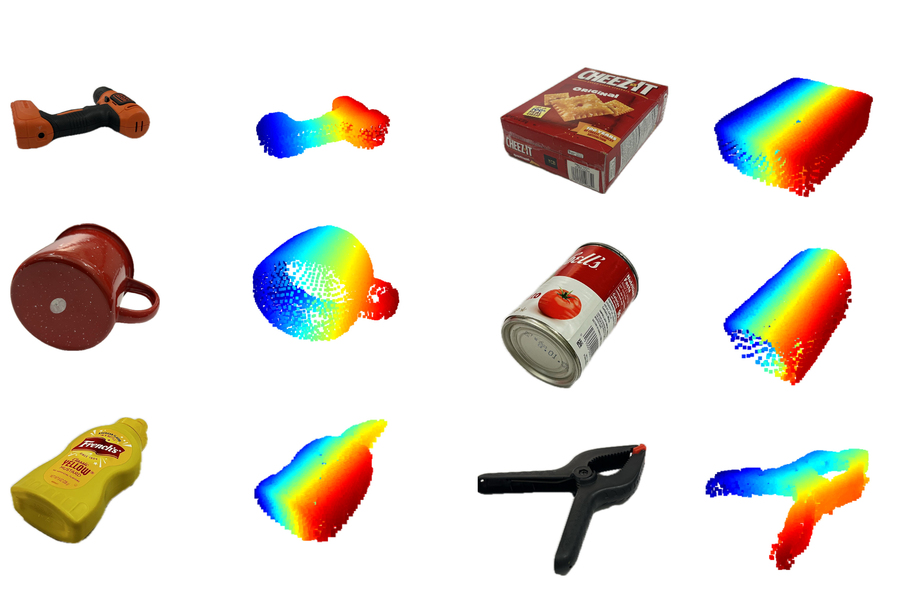
MIT researchers utilized specially trained generative AI models to create a system that can complete the shape of hidden 3D objects, like the ones pictured. Credit: Courtesy of the researchers.
By Adam Zewe

MIT researchers have spent more than a decade studying techniques that enable robots to find and manipulate hidden objects by “seeing” through obstacles. Their methods utilize surface-penetrating wireless signals that reflect off concealed items.

Now, the researchers are leveraging generative artificial intelligence models to overcome a longstanding bottleneck that limited the precision of prior approaches. The result is a new method that produces more accurate shape reconstructions, which could improve a robot’s ability to reliably grasp and manipulate objects that are blocked from view.

This new technique builds a partial reconstruction of a hidden object from reflected wireless signals and fills in the missing parts of its shape using a specially trained generative AI model.

The researchers also introduced an expanded system that uses generative AI to accurately reconstruct an entire room, including all the furniture. The system utilizes wireless signals sent from one stationary radar, which reflect off humans moving in the space.  

This overcomes one key challenge of many existing methods, which require a wireless sensor to be mounted on a mobile robot to scan the environment. And unlike some popular camera-based techniques, their method preserves the privacy of people in the environment.

These innovations could enable warehouse robots to verify packed items before shipping, eliminating waste from product returns. They could also allow smart home robots to understand someone’s location in a room, improving the safety and efficiency of human-robot interaction.

“What we’ve done now is develop generative AI models that help us understand wireless reflections. This opens up a lot of interesting new applications, but technically it is also a qualitative leap in capabilities, from being able to fill in gaps we were not able to see before to being able to interpret reflections and reconstruct entire scenes,” says Fadel Adib, associate professor in the Department of Electrical Engineering and Computer Science, director of the Signal Kinetics group in the MIT Media Lab, and senior author of two papers on these techniques. “We are using AI to finally unlock wireless vision.”

Adib is joined on the first paper by lead author and research assistant Laura Dodds; as well as research assistants Maisy Lam, Waleed Akbar, and Yibo Cheng; and on the second paper by lead author and former postdoc Kaichen Zhou; Dodds; and research assistant Sayed Saad Afzal. Both papers will be presented at the IEEE Conference on Computer Vision and Pattern Recognition.

Surmounting specularity

The Adib Group previously demonstrated the use of millimeter wave (mmWave) signals to create accurate reconstructions of 3D objects that are hidden from view, like a lost wallet buried under a pile.

These waves, which are the same type of signals used in Wi-Fi, can pass through common obstructions like drywall, plastic, and cardboard, and reflect off hidden objects.

But mmWaves usually reflect in a specular manner, which means a wave reflects in a single direction after striking a surface. So large portions of the surface will reflect signals away from the mmWave sensor, making those areas effectively invisible.

“When we want to reconstruct an object, we are only able to see the top surface and we can’t see any of the bottom or sides,” Dodds explains.

The researchers previously used principles from physics to interpret reflected signals, but this limits the accuracy of the reconstructed 3D shape.

In the new papers, they overcame that limitation by using a generative AI model to fill in parts that are missing from a partial reconstruction.

“But the challenge then becomes: How do you train these models to fill in these gaps?” Adib says.

Usually, researchers use extremely large datasets to train a generative AI model, which is one reason models like Claude and Llama exhibit such impressive performance. But no mmWave datasets are large enough for training.

Instead, the researchers adapted the images in large computer vision datasets to mimic the properties in mmWave reflections.

“We were simulating the property of specularity and the noise we get from these reflections so we can apply existing datasets to our domain. It would have taken years for us to collect enough new data to do this,” Lam says.

The researchers embed the physics of mmWave reflections directly into these adapted data, creating a synthetic dataset they use to teach a generative AI model to perform plausible shape reconstructions.

The complete system, called Wave-Former, proposes a set of potential object surfaces based on mmWave reflections, feeds them to the generative AI model to complete the shape, and then refines the surfaces until it achieves a full reconstruction.

Wave-Former was able to generate faithful reconstructions of about 70 everyday objects, such as cans, boxes, utensils, and fruit, boosting accuracy by nearly 20 percent over state-of-the-art baselines. The objects were hidden behind or under cardboard, wood, drywall, plastic, and fabric.

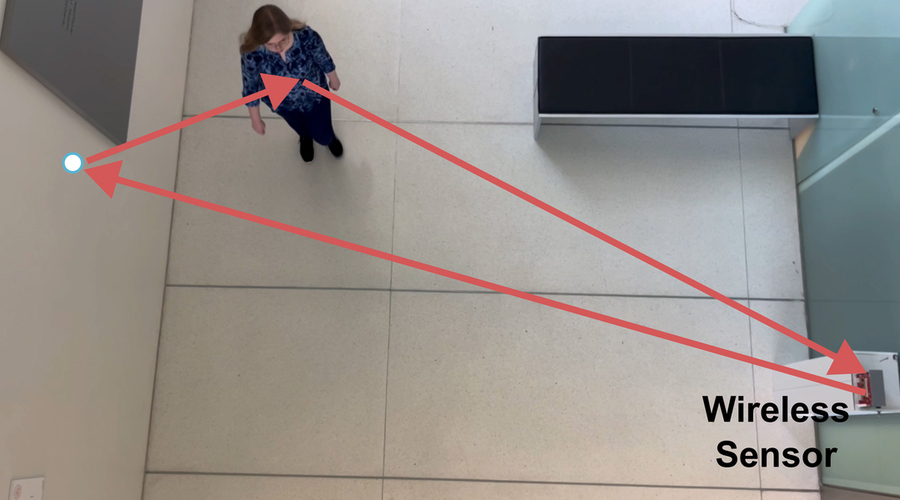
The team also built an expanded system that fully reconstructs entire indoor scenes by leveraging wireless signal reflections off humans moving in a room. Credit: Courtesy of the researchers.
Seeing “ghosts”

The team used this same approach to build an expanded system that fully reconstructs entire indoor scenes by leveraging mmWave reflections off humans moving in a room.

Human motion generates multipath reflections. Some mmWaves reflect off the human, then reflect again off a wall or object, and then arrive back at the sensor, Dodds explains.

These secondary reflections create so-called “ghost signals,” which are reflected copies of the original signal that change location as a human moves. These ghost signals are usually discarded as noise, but they also hold information about the layout of the room.

“By analyzing how these reflections change over time, we can start to get a coarse understanding of the environment around us. But trying to directly interpret these signals is going to be limited in accuracy and resolution.” Dodds says.

They used a similar training method to teach a generative AI model to interpret those coarse scene reconstructions and understand the behavior of multipath mmWave reflections. This model fills in the gaps, refining the initial reconstruction until it completes the scene.

They tested their scene reconstruction system, called RISE, using more than 100 human trajectories captured by a single mmWave radar. On average, RISE generated reconstructions that were about twice as precise than existing techniques.

In the future, the researchers want to improve the granularity and detail in their reconstructions. They also want to build large foundation models for wireless signals, like the foundation models GPT, Claude, and Gemini for language and vision, which could open new applications.

This work is supported, in part, by the National Science Foundation (NSF), the MIT Media Lab, and Amazon.

Find out more

Coding for underwater robotics

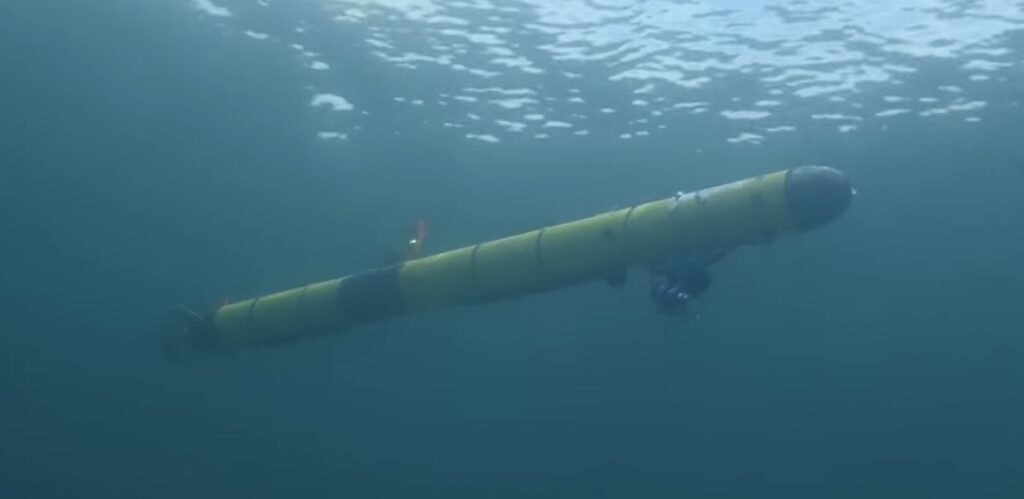
Screenshot from video showing underwater robotic vehicle. Credit: Tim Briggs/MIT Lincoln Laboratory.
During a summer internship at MIT Lincoln Laboratory, Ivy Mahncke, an undergraduate student of robotics engineering at Olin College of Engineering, took a hands-on approach to testing algorithms for underwater navigation. She first discovered her love for working with underwater robotics as an intern at the Woods Hole Oceanographic Institution in 2024. Drawn by the chance to tackle new problems and cutting-edge algorithm development, Mahncke began an internship with Lincoln Laboratory’s Advanced Undersea Systems and Technology Group in 2025. 

Mahncke spent the summer developing and troubleshooting an algorithm that would help a human diver and robotic vehicle collaboratively navigate underwater. The lack of traditional localization aids — such as the Global Positioning System, or GPS — in an underwater environment posed challenges for navigation that Mahncke and her mentors sought to overcome. Her work in the laboratory culminated in field tests of the algorithm on an operational underwater vehicle. Accompanying group staff to field test sites in the Atlantic Ocean, Charles River, and Lake Superior, Mahncke had the opportunity see her software in action in the real world.

“One of the lead engineers on the project had split off to go do other work. And she said, ‘Here’s my laptop. Here are the things that you need to do. I trust you to go do them.’ And so I got to be out on the water as not just an extra pair of hands, but as one of the lead field testers,” Mahncke says. “I really felt that my supervisors saw me as the future generation of engineers, either at Lincoln Lab or just in the broader industry.”

Says Madeline Miller, Mahncke’s internship supervisor: “Ivy’s internship coincided with a rigorous series of field tests at the end of an ambitious program. We figuratively threw her right in the water, and she not only floated, but played an integral part in our program’s ability to hit several reach goals.”

Lincoln Laboratory’s summer research program runs from mid-May to August. Applications are now open. 

Video by Tim Briggs/MIT Lincoln Laboratory | 2 minutes, 59 seconds

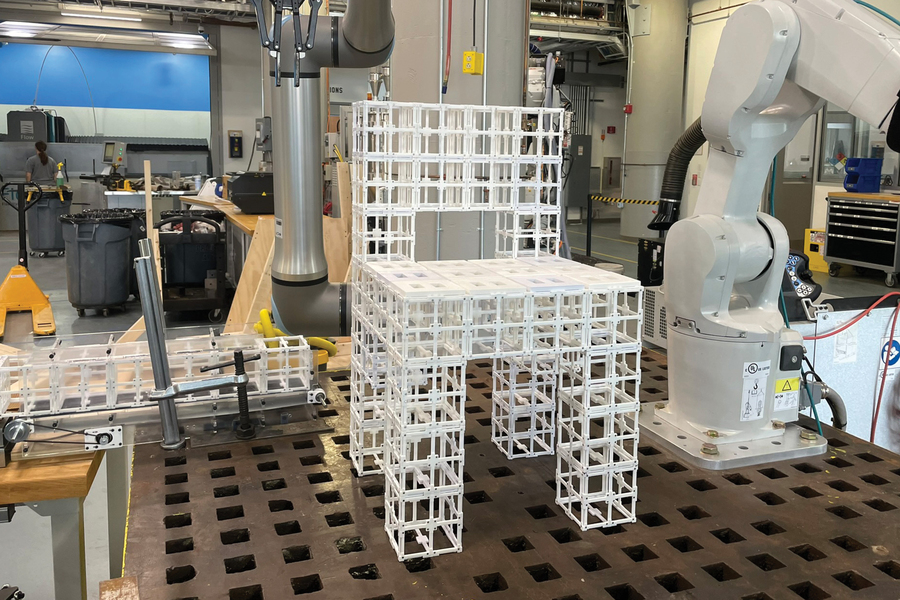
“Robot, make me a chair”

Given the prompt “Make me a chair” and feedback “I want panels on the seat,” the robot assembles a chair and places panel components according to the user prompt. Image credit: Courtesy of the researchers.
By Adam Zewe

Computer-aided design (CAD) systems are tried-and-true tools used to design many of the physical objects we use each day. But CAD software requires extensive expertise to master, and many tools incorporate such a high level of detail they don’t lend themselves to brainstorming or rapid prototyping.

In an effort to make design faster and more accessible for non-experts, researchers from MIT and elsewhere developed an AI-driven robotic assembly system that allows people to build physical objects by simply describing them in words.

Their system uses a generative AI model to build a 3D representation of an object’s geometry based on the user’s prompt. Then, a second generative AI model reasons about the desired object and figures out where different components should go, according to the object’s function and geometry.

The system can automatically build the object from a set of prefabricated parts using robotic assembly. It can also iterate on the design based on feedback from the user.

The researchers used this end-to-end system to fabricate furniture, including chairs and shelves, from two types of premade components. The components can be disassembled and reassembled at will, reducing the amount of waste generated through the fabrication process.

They evaluated these designs through a user study and found that more than 90 percent of participants preferred the objects made by their AI-driven system, as compared to different approaches.

While this work is an initial demonstration, the framework could be especially useful for rapid prototyping complex objects like aerospace components and architectural objects. In the longer term, it could be used in homes to fabricate furniture or other objects locally, without the need to have bulky products shipped from a central facility.

“Sooner or later, we want to be able to communicate and talk to a robot and AI system the same way we talk to each other to make things together. Our system is a first step toward enabling that future,” says lead author Alex Kyaw, a graduate student in the MIT departments of Electrical Engineering and Computer Science (EECS) and Architecture.

Kyaw is joined on the paper by Richa Gupta, an MIT architecture graduate student; Faez Ahmed, associate professor of mechanical engineering; Lawrence Sass, professor and chair of the Computation Group in the Department of Architecture; senior author Randall Davis, an EECS professor and member of the Computer Science and Artificial Intelligence Laboratory (CSAIL); as well as others at Google Deepmind and Autodesk Research. The paper was recently presented at the Conference on Neural Information Processing Systems.

Generating a multicomponent design

While generative AI models are good at generating 3D representations, known as meshes, from text prompts, most do not produce uniform representations of an object’s geometry that have the component-level details needed for robotic assembly.

Separating these meshes into components is challenging for a model because assigning components depends on the geometry and functionality of the object and its parts.

The researchers tackled these challenges using a vision-language model (VLM), a powerful generative AI model that has been pre-trained to understand images and text. They task the VLM with figuring out how two types of prefabricated parts, structural components and panel components, should fit together to form an object.

“There are many ways we can put panels on a physical object, but the robot needs to see the geometry and reason over that geometry to make a decision about it. By serving as both the eyes and brain of the robot, the VLM enables the robot to do this,” Kyaw says.

A user prompts the system with text, perhaps by typing “make me a chair,” and gives it an AI-generated image of a chair to start.

Then, the VLM reasons about the chair and determines where panel components go on top of structural components, based on the functionality of many example objects it has seen before. For instance, the model can determine that the seat and backrest should have panels to have surfaces for someone sitting and leaning on the chair.

It outputs this information as text, such as “seat” or “backrest.” Each surface of the chair is then labeled with numbers, and the information is fed back to the VLM.

Then the VLM chooses the labels that correspond to the geometric parts of the chair that should receive panels on the 3D mesh to complete the design.

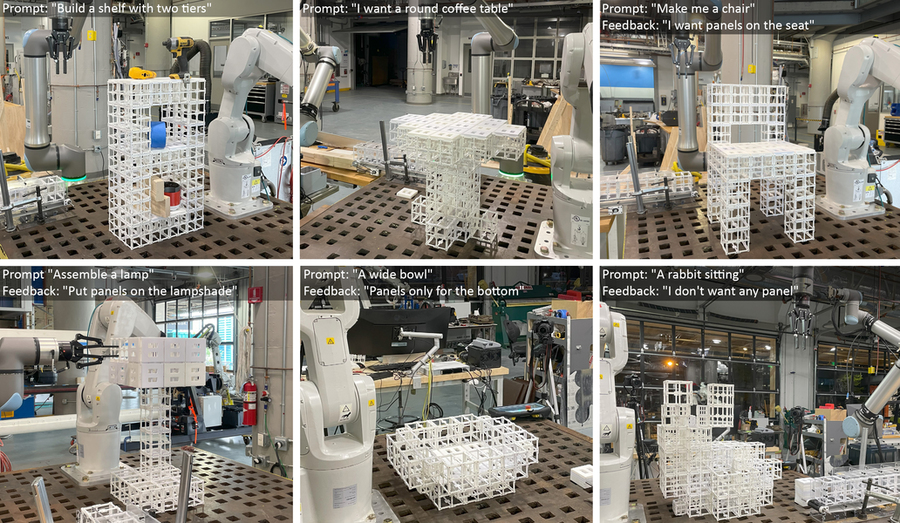
These six photos show the Text to robotic assembly of multi-component objects from different user prompts. Credit: Courtesy of the researchers.
Human-AI co-design

The user remains in the loop throughout this process and can refine the design by giving the model a new prompt, such as “only use panels on the backrest, not the seat.”

“The design space is very big, so we narrow it down through user feedback. We believe this is the best way to do it because people have different preferences, and building an idealized model for everyone would be impossible,” Kyaw says.

“The human‑in‑the‑loop process allows the users to steer the AI‑generated designs and have a sense of ownership in the final result,” adds Gupta.

Once the 3D mesh is finalized, a robotic assembly system builds the object using prefabricated parts. These reusable parts can be disassembled and reassembled into different configurations.

The researchers compared the results of their method with an algorithm that places panels on all horizontal surfaces that are facing up, and an algorithm that places panels randomly. In a user study, more than 90 percent of individuals preferred the designs made by their system.

They also asked the VLM to explain why it chose to put panels in those areas.

“We learned that the vision language model is able to understand some degree of the functional aspects of a chair, like leaning and sitting, to understand why it is placing panels on the seat and backrest. It isn’t just randomly spitting out these assignments,” Kyaw says.

In the future, the researchers want to enhance their system to handle more complex and nuanced user prompts, such as a table made out of glass and metal. In addition, they want to incorporate additional prefabricated components, such as gears, hinges, or other moving parts, so objects could have more functionality.

“Our hope is to drastically lower the barrier of access to design tools. We have shown that we can use generative AI and robotics to turn ideas into physical objects in a fast, accessible, and sustainable manner,” says Davis.

Vine-inspired robotic gripper gently lifts heavy and fragile objects

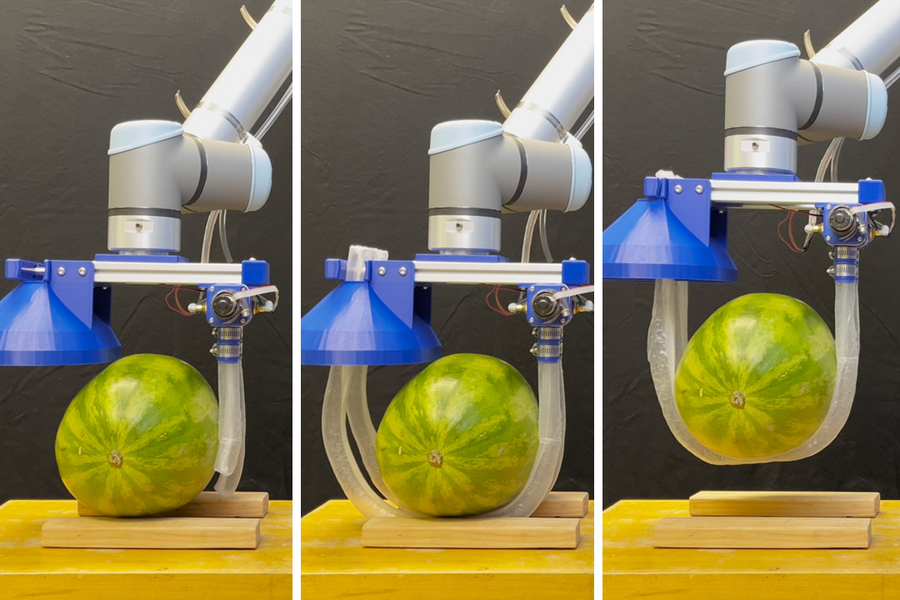
The researchers demonstrated that the vine robot can safely and stably lift a variety of heavy and fragile objects, like a watermelon. Image credit: Courtesy of the researchers
By Jennifer Chu

In the horticultural world, some vines are especially grabby. As they grow, the woody tendrils can wrap around obstacles with enough force to pull down entire fences and trees.

Inspired by vines’ twisty tenacity, engineers at MIT and Stanford University have developed a robotic gripper that can snake around and lift a variety of objects, including a glass vase and a watermelon, offering a gentler approach compared to conventional gripper designs. A larger version of the robo-tendrils can also safely lift a human out of bed.

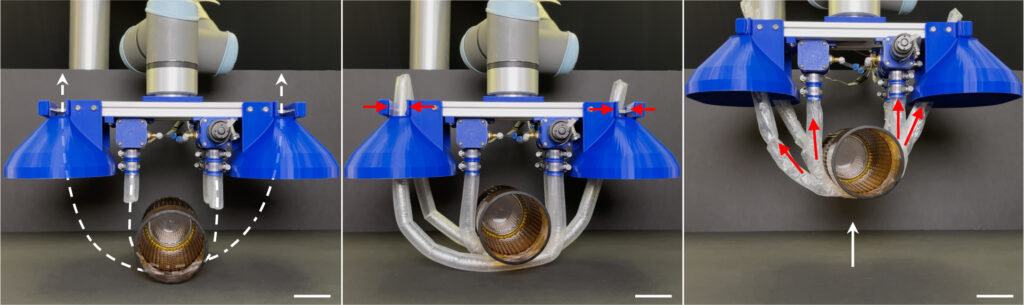
The new bot consists of a pressurized box, positioned near the target object, from which long, vine-like tubes inflate and grow, like socks being turned inside out. As they extend, the vines twist and coil around the object before continuing back toward the box, where they are automatically clamped in place and mechanically wound back up to gently lift the object in a soft, sling-like grasp.

The researchers demonstrated that the vine robot can safely and stably lift a variety of heavy and fragile objects. The robot can also squeeze through tight quarters and push through clutter to reach and grasp a desired object.

The team envisions that this type of robot gripper could be used in a wide range of scenarios, from agricultural harvesting to loading and unloading heavy cargo. In the near term, the group is exploring applications in eldercare settings, where soft inflatable robotic vines could help to gently lift a person out of bed.

“Transferring a person out of bed is one of the most physically strenuous tasks that a caregiver carries out,” says Kentaro Barhydt, a PhD candidate in MIT’s Department of Mechanical Engineering. “This kind of robot can help relieve the caretaker, and can be gentler and more comfortable for the patient.”

Barhydt, along with his co-first author from Stanford, O. Godson Osele, and their colleagues, present the new robotic design in the journal Science Advances. The study’s co-authors are Harry Asada, the Ford Professor of Engineering at MIT, and Allison Okamura, the Richard W. Weiland Professor of Engineering at Stanford University, along with Sreela Kodali and Cosmia du Pasquier at Stanford University, and former MIT graduate student Chase Hartquist, now at the University of Florida, Gainesville.

Open and closed

As they extend, the vines twist and coil around the object before continuing back toward the box, where they are automatically clamped in place and mechanically wound back up to gently lift the object in a soft, sling-like grasp. Image credit: Courtesy of the researchers.
The team’s Stanford collaborators, led by Okamura, pioneered the development of soft, vine-inspired robots that grow outward from their tips. These designs are largely built from thin yet sturdy pneumatic tubes that grow and inflate with controlled air pressure. As they grow, the tubes can twist, bend, and snake their way through the environment, and squeeze through tight and cluttered spaces.

Researchers have mostly explored vine robots for use in safety inspections and search and rescue operations. But at MIT, Barhydt and Asada, whose group has developed robotic aides for the elderly, wondered whether such vine-inspired robots could address certain challenges in eldercare — specifically, the challenge of safely lifting a person out of bed. Often in nursing and rehabilitation settings, this transfer process is done with a patient lift, operated by a caretaker who must first physically move a patient onto their side, then back onto a hammock-like sheet. The caretaker straps the sheet around the patient and hooks it onto the mechanical lift, which then can gently hoist the patient out of bed, similar to suspending a hammock or sling.

The MIT and Stanford team imagined that as an alternative, a vine-like robot could gently snake under and around a patient to create its own sort of sling, without a caretaker having to physically maneuver the patient. But in order to lift the sling, the researchers realized they would have to add an element that was missing in existing vine robot designs: Essentially, they would have to close the loop.

Most vine-inspired robots are designed as “open-loop” systems, meaning they act as open-ended strings that can extend and bend in different configurations, but they are not designed to secure themselves to anything to form a closed loop. If a vine robot could be made to transform from an open loop to a closed loop, Barhydt surmised that it could make itself into a sling around the object and pull itself up, along with whatever, or whomever, it might hold.

For their new study, Barhydt, Osele, and their colleagues outline the design for a new vine-inspired robotic gripper that combines both open- and closed-loop actions. In an open-loop configuration, a robotic vine can grow and twist around an object to create a firm grasp. It can even burrow under a human lying on a bed. Once a grasp is made, the vine can continue to grow back toward and attach to its source, creating a closed loop that can then be retracted to retrieve the object.

“People might assume that in order to grab something, you just reach out and grab it,” Barhydt says. “But there are different stages, such as positioning and holding. By transforming between open and closed loops, we can achieve new levels of performance by leveraging the advantages of both forms for their respective stages.”

Gentle suspension

As a demonstration of their new open- and closed-loop concept, the team built a large-scale robotic system designed to safely lift a person up from a bed. The system comprises a set of pressurized boxes attached on either end of an overhead bar. An air pump inside the boxes slowly inflates and unfurls thin vine-like tubes that extend down toward the head and foot of a bed. The air pressure can be controlled to gently work the tubes under and around a person, before stretching back up to their respective boxes. The vines then thread through a clamping mechanism that secures the vines to each box. A winch winds the vines back up toward the boxes, gently lifting the person up in the process.

“Heavy but fragile objects, such as a human body, are difficult to grasp with the robotic hands that are available today,” Asada says. “We have developed a vine-like, growing robot gripper that can wrap around an object and suspend it gently and securely.”

“There’s an entire design space we hope this work inspires our colleagues to continue to explore,” says co-lead author Osele. “I especially look forward to the implications for patient transfer applications in health care.”

“I am very excited about future work to use robots like these for physically assisting people with mobility challenges,” adds co-author Okamura. “Soft robots can be relatively safe, low-cost, and optimally designed for specific human needs, in contrast to other approaches like humanoid robots.”

While the team’s design was motivated by challenges in eldercare, the researchers realized the new design could also be adapted to perform other grasping tasks. In addition to their large-scale system, they have built a smaller version that can attach to a commercial robotic arm. With this version, the team has shown that the vine robot can grasp and lift a variety of heavy and fragile objects, including a watermelon, a glass vase, a kettle bell, a stack of metal rods, and a playground ball. The vines can also snake through a cluttered bin to pull out a desired object.

“We think this kind of robot design can be adapted to many applications,” Barhydt says. “We are also thinking about applying this to heavy industry, and things like automating the operation of cranes at ports and warehouses.”

This work was supported, in part, by the National Science Foundation and the Ford Foundation.

MIT engineers design an aerial microrobot that can fly as fast as a bumblebee

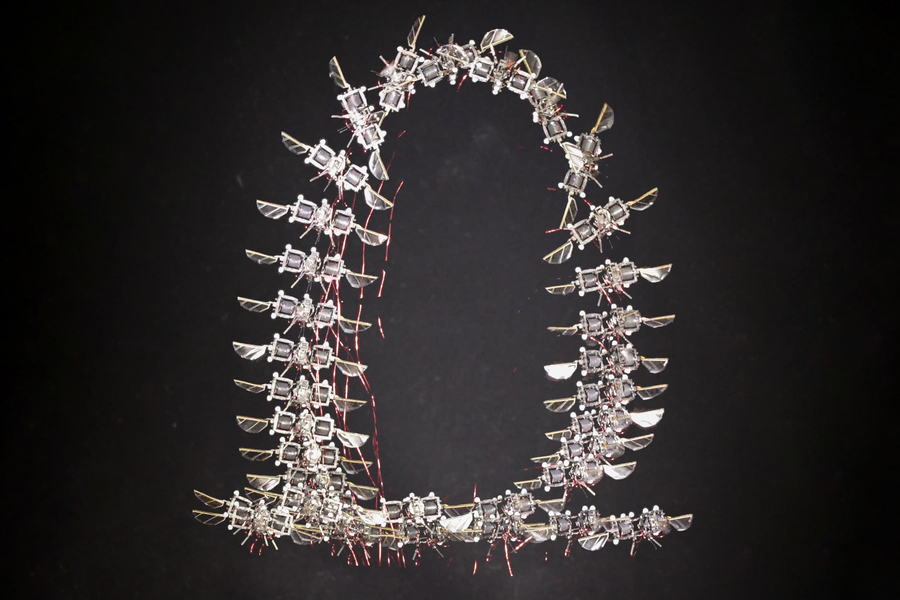
A time-lapse photo shows a flying microrobot performing a flip. Credit: Courtesy of the Soft and Micro Robotics Laboratory.
By Adam Zewe

In the future, tiny flying robots could be deployed to aid in the search for survivors trapped beneath the rubble after a devastating earthquake. Like real insects, these robots could flit through tight spaces larger robots can’t reach, while simultaneously dodging stationary obstacles and pieces of falling rubble.

So far, aerial microrobots have only been able to fly slowly along smooth trajectories, far from the swift, agile flight of real insects — until now.

MIT researchers have demonstrated aerial microrobots that can fly with speed and agility that is comparable to their biological counterparts. A collaborative team designed a new AI-based controller for the robotic bug that enabled it to follow gymnastic flight paths, such as executing continuous body flips.

With a two-part control scheme that combines high performance with computational efficiency, the robot’s speed and acceleration increased by about 450 percent and 250 percent, respectively, compared to the researchers’ best previous demonstrations.

The speedy robot was agile enough to complete 10 consecutive somersaults in 11 seconds, even when wind disturbances threatened to push it off course.

Animation of a flying, flipping microrobot

“We want to be able to use these robots in scenarios that more traditional quad copter robots would have trouble flying into, but that insects could navigate. Now, with our bioinspired control framework, the flight performance of our robot is comparable to insects in terms of speed, acceleration, and the pitching angle. This is quite an exciting step toward that future goal,” says Kevin Chen, an associate professor in the Department of Electrical Engineering and Computer Science (EECS), head of the Soft and Micro Robotics Laboratory within the Research Laboratory of Electronics (RLE), and co-senior author of a paper on the robot.

Chen is joined on the paper by co-lead authors Yi-Hsuan Hsiao, an EECS MIT graduate student; Andrea Tagliabue PhD ’24; and Owen Matteson, a graduate student in the Department of Aeronautics and Astronautics (AeroAstro); as well as EECS graduate student Suhan Kim; Tong Zhao MEng ’23; and co-senior author Jonathan P. How, the Ford Professor of Engineering in the Department of Aeronautics and Astronautics and a principal investigator in the Laboratory for Information and Decision Systems (LIDS). The research appears today in Science Advances.

An AI controller

Chen’s group has been building robotic insects for more than five years.

They recently developed a more durable version of their tiny robot, a microcassette-sized device that weighs less than a paperclip. The new version utilizes larger, flapping wings that enable more agile movements. They are powered by a set of squishy artificial muscles that flap the wings at an extremely fast rate.

But the controller — the “brain” of the robot that determines its position and tells it where to fly — was hand-tuned by a human, limiting the robot’s performance.

For the robot to fly quickly and aggressively like a real insect, it needed a more robust controller that could account for uncertainty and perform complex optimizations quickly.

Such a controller would be too computationally intensive to be deployed in real time, especially with the complicated aerodynamics of the lightweight robot.

To overcome this challenge, Chen’s group joined forces with How’s team and, together, they crafted a two-step, AI-driven control scheme that provides the robustness necessary for complex, rapid maneuvers, and the computational efficiency needed for real-time deployment.

“The hardware advances pushed the controller so there was more we could do on the software side, but at the same time, as the controller developed, there was more they could do with the hardware. As Kevin’s team demonstrates new capabilities, we demonstrate that we can utilize them,” How says.

For the first step, the team built what is known as a model-predictive controller. This type of powerful controller uses a dynamic, mathematical model to predict the behavior of the robot and plan the optimal series of actions to safely follow a trajectory.

While computationally intensive, it can plan challenging maneuvers like aerial somersaults, rapid turns, and aggressive body tilting. This high-performance planner is also designed to consider constraints on the force and torque the robot could apply, which is essential for avoiding collisions.

For instance, to perform multiple flips in a row, the robot would need to decelerate in such a way that its initial conditions are exactly right for doing the flip again.

“If small errors creep in, and you try to repeat that flip 10 times with those small errors, the robot will just crash. We need to have robust flight control,” How says.

They use this expert planner to train a “policy” based on a deep-learning model, to control the robot in real time, through a process called imitation learning. A policy is the robot’s decision-making engine, which tells the robot where and how to fly.

Essentially, the imitation-learning process compresses the powerful controller into a computationally efficient AI model that can run very fast.

The key was having a smart way to create just enough training data, which would teach the policy everything it needs to know for aggressive maneuvers.

“The robust training method is the secret sauce of this technique,” How explains.

The AI-driven policy takes robot positions as inputs and outputs control commands in real time, such as thrust force and torques.

Insect-like performance

In their experiments, this two-step approach enabled the insect-scale robot to fly 447 percent faster while exhibiting a 255 percent increase in acceleration. The robot was able to complete 10 somersaults in 11 seconds, and the tiny robot never strayed more than 4 or 5 centimeters off its planned trajectory.

“This work demonstrates that soft and microrobots, traditionally limited in speed, can now leverage advanced control algorithms to achieve agility approaching that of natural insects and larger robots, opening up new opportunities for multimodal locomotion,” says Hsiao.

The researchers were also able to demonstrate saccade movement, which occurs when insects pitch very aggressively, fly rapidly to a certain position, and then pitch the other way to stop. This rapid acceleration and deceleration help insects localize themselves and see clearly.

“This bio-mimicking flight behavior could help us in the future when we start putting cameras and sensors on board the robot,” Chen says.

Adding sensors and cameras so the microrobots can fly outdoors, without being attached to a complex motion capture system, will be a major area of future work.

The researchers also want to study how onboard sensors could help the robots avoid colliding with one another or coordinate navigation.

“For the micro-robotics community, I hope this paper signals a paradigm shift by showing that we can develop a new control architecture that is high-performing and efficient at the same time,” says Chen.

“This work is especially impressive because these robots still perform precise flips and fast turns despite the large uncertainties that come from relatively large fabrication tolerances in small-scale manufacturing, wind gusts of more than 1 meter per second, and even its power tether wrapping around the robot as it performs repeated flips,” says Sarah Bergbreiter, a professor of mechanical engineering at Carnegie Mellon University, who was not involved with this work.

“Although the controller currently runs on an external computer rather than onboard the robot, the authors demonstrate that similar, but less precise, control policies may be feasible even with the more limited computation available on an insect-scale robot. This is exciting because it points toward future insect-scale robots with agility approaching that of their biological counterparts,” she adds.

This research is funded, in part, by the National Science Foundation (NSF), the Office of Naval Research, Air Force Office of Scientific Research, MathWorks, and the Zakhartchenko Fellowship.

Artificial tendons give muscle-powered robots a boost

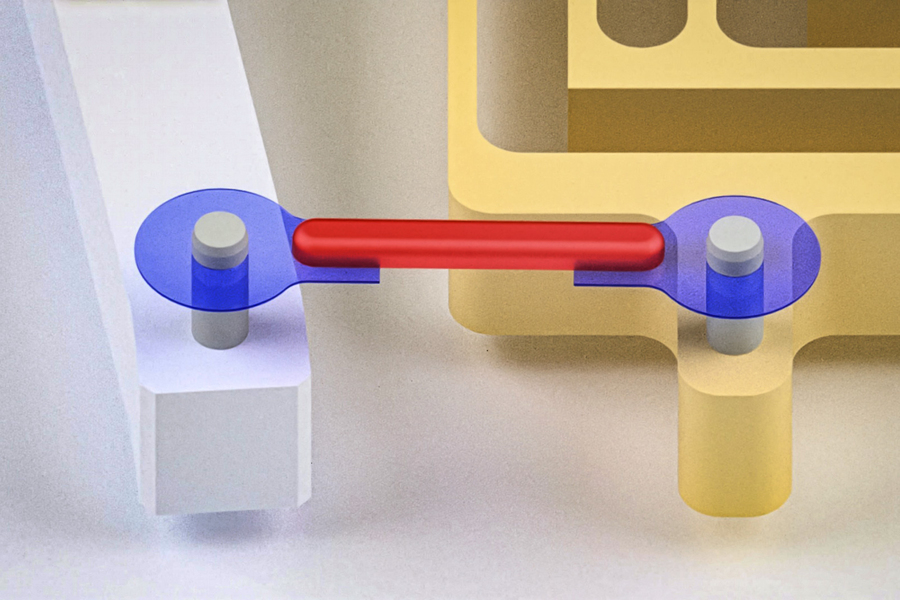
Researchers have developed artificial tendons for muscle-powered robots. They attached the rubber band-like tendons (blue) to either end of a small piece of lab-grown muscle (red), forming a “muscle-tendon unit.” Credit: Courtesy of the researchers; edited by MIT News.
Our muscles are nature’s actuators. The sinewy tissue is what generates the forces that make our bodies move. In recent years, engineers have used real muscle tissue to actuate “biohybrid robots” made from both living tissue and synthetic parts. By pairing lab-grown muscles with synthetic skeletons, researchers are engineering a menagerie of muscle-powered crawlers, walkers, swimmers, and grippers.

But for the most part, these designs are limited in the amount of motion and power they can produce. Now, MIT engineers are aiming to give bio-bots a power lift with artificial tendons.

In a study which recently appeared in the journal Advanced Sciencethe researchers developed artificial tendons made from tough and flexible hydrogel. They attached the rubber band-like tendons to either end of a small piece of lab-grown muscle, forming a “muscle-tendon unit.” Then they connected the ends of each artificial tendon to the fingers of a robotic gripper.

When they stimulated the central muscle to contract, the tendons pulled the gripper’s fingers together. The robot pinched its fingers together three times faster, and with 30 times greater force, compared with the same design without the connecting tendons.

The researchers envision the new muscle-tendon unit can be fit to a wide range of biohybrid robot designs, much like a universal engineering element.

“We are introducing artificial tendons as interchangeable connectors between muscle actuators and robotic skeletons,” says lead author Ritu Raman, an assistant professor of mechanical engineering (MechE) at MIT. “Such modularity could make it easier to design a wide range of robotic applications, from microscale surgical tools to adaptive, autonomous exploratory machines.”

The study’s MIT co-authors include graduate students Nicolas Castro, Maheera Bawa, Bastien Aymon, Sonika Kohli, and Angel Bu; undergraduate Annika Marschner; postdoc Ronald Heisser; alumni Sarah J. Wu and Laura Rosado; and MechE professors Martin Culpepper and Xuanhe Zhao.

Muscle’s gains

Raman and her colleagues at MIT are at the forefront of biohybrid robotics, a relatively new field that has emerged in the last decade. They focus on combining synthetic, structural robotic parts with living muscle tissue as natural actuators.

“Most actuators that engineers typically work with are really hard to make small,” Raman says. “Past a certain size, the basic physics doesn’t work. The nice thing about muscle is, each cell is an independent actuator that generates force and produces motion. So you could, in principle, make robots that are really small.”

Muscle actuators also come with other advantages, which Raman’s team has already demonstrated: The tissue can grow stronger as it works out, and can naturally heal when injured. For these reasons, Raman and others envision that muscly droids could one day be sent out to explore environments that are too remote or dangerous for humans. Such muscle-bound bots could build up their strength for unforeseen traverses or heal themselves when help is unavailable. Biohybrid bots could also serve as small, surgical assistants that perform delicate, microscale procedures inside the body.

All these future scenarios are motivating Raman and others to find ways to pair living muscles with synthetic skeletons. Designs to date have involved growing a band of muscle and attaching either end to a synthetic skeleton, similar to looping a rubber band around two posts. When the muscle is stimulated to contract, it can pull the parts of a skeleton together to generate a desired motion.

But Raman says this method produces a lot of wasted muscle that is used to attach the tissue to the skeleton rather than to make it move. And that connection isn’t always secure. Muscle is quite soft compared with skeletal structures, and the difference can cause muscle to tear or detach. What’s more, it is often only the contractions in the central part of the muscle that end up doing any work — an amount that’s relatively small and generates little force.

“We thought, how do we stop wasting muscle material, make it more modular so it can attach to anything, and make it work more efficiently?” Raman says. “The solution the body has come up with is to have tendons that are halfway in stiffness between muscle and bone, that allow you to bridge this mechanical mismatch between soft muscle and rigid skeleton. They’re like thin cables that wrap around joints efficiently.”

“Smartly connected”

In their new work, Raman and her colleagues designed artificial tendons to connect natural muscle tissue with a synthetic gripper skeleton. Their material of choice was hydrogel — a squishy yet sturdy polymer-based gel. Raman obtained hydrogel samples from her colleague and co-author Xuanhe Zhao, who has pioneered the development of hydrogels at MIT. Zhao’s group has derived recipes for hydrogels of varying toughness and stretch that can stick to many surfaces, including synthetic and biological materials.

To figure out how tough and stretchy artificial tendons should be in order to work in their gripper design, Raman’s team first modeled the design as a simple system of three types of springs, each representing the central muscle, the two connecting tendons, and the gripper skeleton. They assigned a certain stiffness to the muscle and skeleton, which were previously known, and used this to calculate the stiffness of the connecting tendons that would be required in order to move the gripper by a desired amount.

From this modeling, the team derived a recipe for hydrogel of a certain stiffness. Once the gel was made, the researchers carefully etched the gel into thin cables to form artificial tendons. They attached two tendons to either end of a small sample of muscle tissue, which they grew using lab-standard techniques. They then wrapped each tendon around a small post at the end of each finger of the robotic gripper — a skeleton design that was developed by MechE professor Martin Culpepper, an expert in designing and building precision machines.

When the team stimulated the muscle to contract, the tendons in turn pulled on the gripper to pinch its fingers together. Over multiple experiments, the researchers found that the muscle-tendon gripper worked three times faster and produced 30 times more force compared to when the gripper is actuated just with a band of muscle tissue (and without any artificial tendons). The new tendon-based design also was able to keep up this performance over 7,000 cycles, or muscle contractions.

Overall, Raman saw that the addition of artificial tendons increased the robot’s power-to-weight ratio by 11 times, meaning that the system required far less muscle to do just as much work.

“You just need a small piece of actuator that’s smartly connected to the skeleton,” Raman says. “Normally, if a muscle is really soft and attached to something with high resistance, it will just tear itself before moving anything. But if you attach it to something like a tendon that can resist tearing, it can really transmit its force through the tendon, and it can move a skeleton that it wouldn’t have been able to move otherwise.”

The team’s new muscle-tendon design successfully merges biology with robotics, says biomedical engineer Simone Schürle-Finke, associate professor of health sciences and technology at ETH Zürich.

“The tough-hydrogel tendons create a more physiological muscle–tendon–bone architecture, which greatly improves force transmission, durability, and modularity,” says Schürle-Finke, who was not involved with the study. “This moves the field toward biohybrid systems that can operate repeatably and eventually function outside the lab.”

With the new artificial tendons in place, Raman’s group is moving forward to develop other elements, such as skin-like protective casings, to enable muscle-powered robots in practical, real-world settings.

This research was supported, in part, by the U.S. Department of Defense Army Research Office, the MIT Research Support Committee, and the National Science Foundation.

Teaching robots to map large environments

The artificial intelligence-driven system incrementally creates and aligns smaller submaps of the scene, which it stitches together to reconstruct a full 3D map, like of an office cubicle, while estimating the robot’s position in real-time. Image courtesy of the researchers.
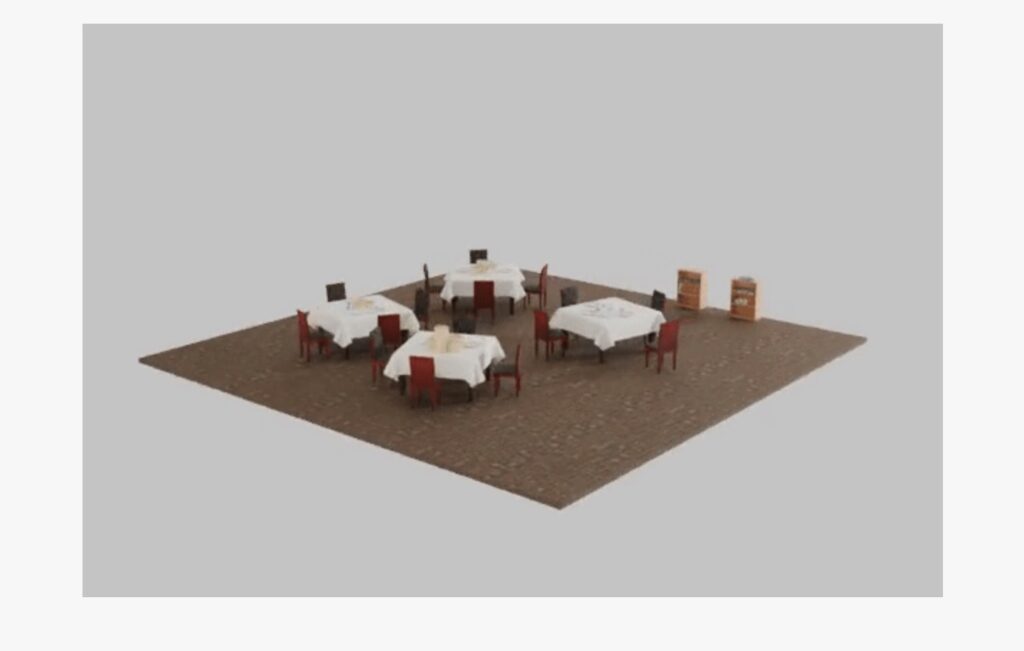
By Adam Zewe

A robot searching for workers trapped in a partially collapsed mine shaft must rapidly generate a map of the scene and identify its location within that scene as it navigates the treacherous terrain.

Researchers have recently started building powerful machine-learning models to perform this complex task using only images from the robot’s onboard cameras, but even the best models can only process a few images at a time. In a real-world disaster where every second counts, a search-and-rescue robot would need to quickly traverse large areas and process thousands of images to complete its mission.

To overcome this problem, MIT researchers drew on ideas from both recent artificial intelligence vision models and classical computer vision to develop a new system that can process an arbitrary number of images. Their system accurately generates 3D maps of complicated scenes like a crowded office corridor in a matter of seconds. 

The AI-driven system incrementally creates and aligns smaller submaps of the scene, which it stitches together to reconstruct a full 3D map while estimating the robot’s position in real-time.

Unlike many other approaches, their technique does not require calibrated cameras or an expert to tune a complex system implementation. The simpler nature of their approach, coupled with the speed and quality of the 3D reconstructions, would make it easier to scale up for real-world applications.

Beyond helping search-and-rescue robots navigate, this method could be used to make extended reality applications for wearable devices like VR headsets or enable industrial robots to quickly find and move goods inside a warehouse.

“For robots to accomplish increasingly complex tasks, they need much more complex map representations of the world around them. But at the same time, we don’t want to make it harder to implement these maps in practice. We’ve shown that it is possible to generate an accurate 3D reconstruction in a matter of seconds with a tool that works out of the box,” says Dominic Maggio, an MIT graduate student and lead author of a paper on this method.

Maggio is joined on the paper by postdoc Hyungtae Lim and senior author Luca Carlone, associate professor in MIT’s Department of Aeronautics and Astronautics (AeroAstro), principal investigator in the Laboratory for Information and Decision Systems (LIDS), and director of the MIT SPARK Laboratory. The research will be presented at the Conference on Neural Information Processing Systems.

Mapping out a solution

For years, researchers have been grappling with an essential element of robotic navigation called simultaneous localization and mapping (SLAM). In SLAM, a robot recreates a map of its environment while orienting itself within the space.

Traditional optimization methods for this task tend to fail in challenging scenes, or they require the robot’s onboard cameras to be calibrated beforehand. To avoid these pitfalls, researchers train machine-learning models to learn this task from data.

While they are simpler to implement, even the best models can only process about 60 camera images at a time, making them infeasible for applications where a robot needs to move quickly through a varied environment while processing thousands of images.

To solve this problem, the MIT researchers designed a system that generates smaller submaps of the scene instead of the entire map. Their method “glues” these submaps together into one overall 3D reconstruction. The model is still only processing a few images at a time, but the system can recreate larger scenes much faster by stitching smaller submaps together.

“This seemed like a very simple solution, but when I first tried it, I was surprised that it didn’t work that well,” Maggio says.

Searching for an explanation, he dug into computer vision research papers from the 1980s and 1990s. Through this analysis, Maggio realized that errors in the way the machine-learning models process images made aligning submaps a more complex problem.

Traditional methods align submaps by applying rotations and translations until they line up. But these new models can introduce some ambiguity into the submaps, which makes them harder to align. For instance, a 3D submap of a one side of a room might have walls that are slightly bent or stretched. Simply rotating and translating these deformed submaps to align them doesn’t work.

“We need to make sure all the submaps are deformed in a consistent way so we can align them well with each other,” Carlone explains.

A more flexible approach

Borrowing ideas from classical computer vision, the researchers developed a more flexible, mathematical technique that can represent all the deformations in these submaps. By applying mathematical transformations to each submap, this more flexible method can align them in a way that addresses the ambiguity.

Based on input images, the system outputs a 3D reconstruction of the scene and estimates of the camera locations, which the robot would use to localize itself in the space.

“Once Dominic had the intuition to bridge these two worlds — learning-based approaches and traditional optimization methods — the implementation was fairly straightforward,” Carlone says. “Coming up with something this effective and simple has potential for a lot of applications.

Their system performed faster with less reconstruction error than other methods, without requiring special cameras or additional tools to process data. The researchers generated close-to-real-time 3D reconstructions of complex scenes like the inside of the MIT Chapel using only short videos captured on a cell phone.

The average error in these 3D reconstructions was less than 5 centimeters.

In the future, the researchers want to make their method more reliable for especially complicated scenes and work toward implementing it on real robots in challenging settings.

“Knowing about traditional geometry pays off. If you understand deeply what is going on in the model, you can get much better results and make things much more scalable,” Carlone says.

This work is supported, in part, by the U.S. National Science Foundation, U.S. Office of Naval Research, and the National Research Foundation of Korea. Carlone, currently on sabbatical as an Amazon Scholar, completed this work before he joined Amazon.

Using generative AI to diversify virtual training grounds for robots

The “steerable scene generation” system creates digital scenes of things like kitchens, living rooms, and restaurants that engineers can use to simulate lots of real-world robot interactions and scenarios. Image credit: Generative AI image, courtesy of the researchers. See an animated version of the image here.
By Alex Shipps

Chatbots like ChatGPT and Claude have experienced a meteoric rise in usage over the past three years because they can help you with a wide range of tasks. Whether you’re writing Shakespearean sonnets, debugging code, or need an answer to an obscure trivia question, artificial intelligence systems seem to have you covered. The source of this versatility? Billions, or even trillions, of textual data points across the internet.

Those data aren’t enough to teach a robot to be a helpful household or factory assistant, though. To understand how to handle, stack, and place various arrangements of objects across diverse environments, robots need demonstrations. You can think of robot training data as a collection of how-to videos that walk the systems through each motion of a task. Collecting these demonstrations on real robots is time-consuming and not perfectly repeatable, so engineers have created training data by generating simulations with AI (which don’t often reflect real-world physics), or tediously handcrafting each digital environment from scratch.

Researchers at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) and the Toyota Research Institute may have found a way to create the diverse, realistic training grounds robots need. Their “steerable scene generation” approach creates digital scenes of things like kitchens, living rooms, and restaurants that engineers can use to simulate lots of real-world interactions and scenarios. Trained on over 44 million 3D rooms filled with models of objects such as tables and plates, the tool places existing assets in new scenes, then refines each one into a physically accurate, lifelike environment.

Steerable scene generation creates these 3D worlds by “steering” a diffusion model — an AI system that generates a visual from random noise — toward a scene you’d find in everyday life. The researchers used this generative system to “in-paint” an environment, filling in particular elements throughout the scene. You can imagine a blank canvas suddenly turning into a kitchen scattered with 3D objects, which are gradually rearranged into a scene that imitates real-world physics. For example, the system ensures that a fork doesn’t pass through a bowl on a table — a common glitch in 3D graphics known as “clipping,” where models overlap or intersect.

How exactly steerable scene generation guides its creation toward realism, however, depends on the strategy you choose. Its main strategy is “Monte Carlo tree search” (MCTS), where the model creates a series of alternative scenes, filling them out in different ways toward a particular objective (like making a scene more physically realistic, or including as many edible items as possible). It’s used by the AI program AlphaGo to beat human opponents in Go (a game similar to chess), as the system considers potential sequences of moves before choosing the most advantageous one.

“We are the first to apply MCTS to scene generation by framing the scene generation task as a sequential decision-making process,” says MIT Department of Electrical Engineering and Computer Science (EECS) PhD student Nicholas Pfaff, who is a CSAIL researcher and a lead author on a paper presenting the work. “We keep building on top of partial scenes to produce better or more desired scenes over time. As a result, MCTS creates scenes that are more complex than what the diffusion model was trained on.”

In one particularly telling experiment, MCTS added the maximum number of objects to a simple restaurant scene. It featured as many as 34 items on a table, including massive stacks of dim sum dishes, after training on scenes with only 17 objects on average.

Steerable scene generation also allows you to generate diverse training scenarios via reinforcement learning — essentially, teaching a diffusion model to fulfill an objective by trial-and-error. After you train on the initial data, your system undergoes a second training stage, where you outline a reward (basically, a desired outcome with a score indicating how close you are to that goal). The model automatically learns to create scenes with higher scores, often producing scenarios that are quite different from those it was trained on.

Users can also prompt the system directly by typing in specific visual descriptions (like “a kitchen with four apples and a bowl on the table”). Then, steerable scene generation can bring your requests to life with precision. For example, the tool accurately followed users’ prompts at rates of 98 percent when building scenes of pantry shelves, and 86 percent for messy breakfast tables. Both marks are at least a 10 percent improvement over comparable methods like “MiDiffusion” and “DiffuScene.”

The system can also complete specific scenes via prompting or light directions (like “come up with a different scene arrangement using the same objects”). You could ask it to place apples on several plates on a kitchen table, for instance, or put board games and books on a shelf. It’s essentially “filling in the blank” by slotting items in empty spaces, but preserving the rest of a scene.

According to the researchers, the strength of their project lies in its ability to create many scenes that roboticists can actually use. “A key insight from our findings is that it’s OK for the scenes we pre-trained on to not exactly resemble the scenes that we actually want,” says Pfaff. “Using our steering methods, we can move beyond that broad distribution and sample from a ‘better’ one. In other words, generating the diverse, realistic, and task-aligned scenes that we actually want to train our robots in.”

Such vast scenes became the testing grounds where they could record a virtual robot interacting with different items. The machine carefully placed forks and knives into a cutlery holder, for instance, and rearranged bread onto plates in various 3D settings. Each simulation appeared fluid and realistic, resembling the real-world, adaptable robots steerable scene generation could help train, one day.

While the system could be an encouraging path forward in generating lots of diverse training data for robots, the researchers say their work is more of a proof of concept. In the future, they’d like to use generative AI to create entirely new objects and scenes, instead of using a fixed library of assets. They also plan to incorporate articulated objects that the robot could open or twist (like cabinets or jars filled with food) to make the scenes even more interactive.

To make their virtual environments even more realistic, Pfaff and his colleagues may incorporate real-world objects by using a library of objects and scenes pulled from images on the internet and using their previous work on “Scalable Real2Sim.” By expanding how diverse and lifelike AI-constructed robot testing grounds can be, the team hopes to build a community of users that’ll create lots of data, which could then be used as a massive dataset to teach dexterous robots different skills.

“Today, creating realistic scenes for simulation can be quite a challenging endeavor; procedural generation can readily produce a large number of scenes, but they likely won’t be representative of the environments the robot would encounter in the real world. Manually creating bespoke scenes is both time-consuming and expensive,” says Jeremy Binagia, an applied scientist at Amazon Robotics who wasn’t involved in the paper. “Steerable scene generation offers a better approach: train a generative model on a large collection of pre-existing scenes and adapt it (using a strategy such as reinforcement learning) to specific downstream applications. Compared to previous works that leverage an off-the-shelf vision-language model or focus just on arranging objects in a 2D grid, this approach guarantees physical feasibility and considers full 3D translation and rotation, enabling the generation of much more interesting scenes.”

“Steerable scene generation with post training and inference-time search provides a novel and efficient framework for automating scene generation at scale,” says Toyota Research Institute roboticist Rick Cory SM ’08, PhD ’10, who also wasn’t involved in the paper. “Moreover, it can generate ‘never-before-seen’ scenes that are deemed important for downstream tasks. In the future, combining this framework with vast internet data could unlock an important milestone towards efficient training of robots for deployment in the real world.”

Pfaff wrote the paper with senior author Russ Tedrake, the Toyota Professor of Electrical Engineering and Computer Science, Aeronautics and Astronautics, and Mechanical Engineering at MIT; a senior vice president of large behavior models at the Toyota Research Institute; and CSAIL principal investigator. Other authors were Toyota Research Institute robotics researcher Hongkai Dai SM ’12, PhD ’16; team lead and Senior Research Scientist Sergey Zakharov; and Carnegie Mellon University PhD student Shun Iwase. Their work was supported, in part, by Amazon and the Toyota Research Institute. The researchers presented their work at the Conference on Robot Learning (CoRL) in September.

Engineering fantasy into reality

“One of the dreams I had as a kid was about the first day of school, and being able to build and be creative, and it was the happiest day of my life. And at MIT, I felt like that dream became reality,” says Ballesteros. Credit: Ryan A Lannom, Jet Propulsion Laboratory.

By Jennifer Chu

Growing up in the suburban town of Spring, Texas, just outside of Houston, Erik Ballesteros couldn’t help but be drawn in by the possibilities for humans in space.

It was the early 2000s, and NASA’s space shuttle program was the main transport for astronauts to the International Space Station (ISS). Ballesteros’ hometown was less than an hour from Johnson Space Center (JSC), where NASA’s mission control center and astronaut training facility are based. And as often as they could, he and his family would drive to JSC to check out the center’s public exhibits and presentations on human space exploration.

For Ballesteros, the highlight of these visits was always the tram tour, which brings visitors to JSC’s Astronaut Training Facility. There, the public can watch astronauts test out spaceflight prototypes and practice various operations in preparation for living and working on the International Space Station.

“It was a really inspiring place to be, and sometimes we would meet astronauts when they were doing signings,” he recalls. “I’d always see the gates where the astronauts would go back into the training facility, and I would think: One day I’ll be on the other side of that gate.”

Today, Ballesteros is a PhD student in mechanical engineering at MIT, and has already made good on his childhood goal. Before coming to MIT, he interned on multiple projects at JSC, working in the training facility to help test new spacesuit materials, portable life support systems, and a propulsion system for a prototype Mars rocket. He also helped train astronauts to operate the ISS’ emergency response systems.

Those early experiences steered him to MIT, where he hopes to make a more direct impact on human spaceflight. He and his advisor, Harry Asada, are building a system that will quite literally provide helping hands to future astronauts. The system, dubbed SuperLimbs, consists of a pair of wearable robotic arms that extend out from a backpack, similar to the fictional Inspector Gadget, or Doctor Octopus (“Doc Ock,” to comic book fans). Ballesteros and Asada are designing the robotic arms to be strong enough to lift an astronaut back up if they fall. The arms could also crab-walk around a spacecraft’s exterior as an astronaut inspects or makes repairs.

Ballesteros is collaborating with engineers at the NASA Jet Propulsion Laboratory to refine the design, which he plans to introduce to astronauts at JSC in the next year or two, for practical testing and user feedback. He says his time at MIT has helped him make connections across academia and in industry that have fueled his life and work.

“Success isn’t built by the actions of one, but rather it’s built on the shoulders of many,” Ballesteros says. “Connections — ones that you not just have, but maintain — are so vital to being able to open new doors and keep great ones open.”

Getting a jumpstart

Ballesteros didn’t always seek out those connections. As a kid, he counted down the minutes until the end of school, when he could go home to play video games and watch movies, “Star Wars” being a favorite. He also loved to create and had a talent for cosplay, tailoring intricate, life-like costumes inspired by cartoon and movie characters.

In high school, he took an introductory class in engineering that challenged students to build robots from kits, that they would then pit against each other, BattleBots-style. Ballesteros built a robotic ball that moved by shifting an internal weight, similar to Star Wars’ fictional, sphere-shaped BB-8. 

“It was a good introduction, and I remember thinking, this engineering thing could be fun,” he says.

After graduating high school, Ballesteros attended the University of Texas at Austin, where he pursued a bachelor’s degree in aerospace engineering. What would typically be a four-year degree stretched into an eight-year period during which Ballesteros combined college with multiple work experiences, taking on internships at NASA and elsewhere. 

In 2013, he interned at Lockheed Martin, where he contributed to various aspects of jet engine development. That experience unlocked a number of other aerospace opportunities. After a stint at NASA’s Kennedy Space Center, he went on to Johnson Space Center, where, as part of a co-op program called Pathways, he returned every spring or summer over the next five years, to intern in various departments across the center.

While the time at JSC gave him a huge amount of practical engineering experience, Ballesteros still wasn’t sure if it was the right fit. Along with his childhood fascination with astronauts and space, he had always loved cinema and the special effects that forged them. In 2018, he took a year off from the NASA Pathways program to intern at Disney, where he spent the spring semester working as a safety engineer, performing safety checks on Disney rides and attractions.

During this time, he got to know a few people in Imagineering — the research and development group that creates, designs, and builds rides, theme parks, and attractions. That summer, the group took him on as an intern, and he worked on the animatronics for upcoming rides, which involved translating certain scenes in a Disney movie into practical, safe, and functional scenes in an attraction.

“In animation, a lot of things they do are fantastical, and it was our job to find a way to make them real,” says Ballesteros, who loved every moment of the experience and hoped to be hired as an Imagineer after the internship came to an end. But he had one year left in his undergraduate degree and had to move on.

After graduating from UT Austin in December 2019, Ballesteros accepted a position at NASA’s Jet Propulsion Laboratory in Pasadena, California. He started at JPL in February of 2020, working on some last adjustments to the Mars Perseverance rover. After a few months during which JPL shifted to remote work during the Covid pandemic, Ballesteros was assigned to a project to develop a self-diagnosing spacecraft monitoring system. While working with that team, he met an engineer who was a former lecturer at MIT. As a practical suggestion, she nudged Ballesteros to consider pursuing a master’s degree, to add more value to his CV.

“She opened up the idea of going to grad school, which I hadn’t ever considered,” he says.

Full circle

In 2021, Ballesteros arrived at MIT to begin a master’s program in mechanical engineering. In interviewing with potential advisors, he immediately hit it off with Harry Asada, the Ford Professor of Enginering and director of the d’Arbeloff Laboratory for Information Systems and Technology. Years ago, Asada had pitched JPL an idea for wearable robotic arms to aid astronauts, which they quickly turned down. But Asada held onto the idea, and proposed that Ballesteros take it on as a feasibility study for his master’s thesis.

The project would require bringing a seemingly sci-fi idea into practical, functional form, for use by astronauts in future space missions. For Ballesteros, it was the perfect challenge. SuperLimbs became the focus of his master’s degree, which he earned in 2023. His initial plan was to return to industry, degree in hand. But he chose to stay at MIT to pursue a PhD, so that he could continue his work with SuperLimbs in an environment where he felt free to explore and try new things.

“MIT is like nerd Hogwarts,” he says. “One of the dreams I had as a kid was about the first day of school, and being able to build and be creative, and it was the happiest day of my life. And at MIT, I felt like that dream became reality.”

Ballesteros and Asada are now further developing SuperLimbs. The team recently re-pitched the idea to engineers at JPL, who reconsidered, and have since struck up a partnership to help test and refine the robot. In the next year or two, Ballesteros hopes to bring a fully functional, wearable design to Johnson Space Center, where astronauts can test it out in space-simulated settings.

In addition to his formal graduate work, Ballesteros has found a way to have a bit of Imagineer-like fun. He is a member of the MIT Robotics Team, which designs, builds, and runs robots in various competitions and challenges. Within this club, Ballesteros has formed a sub-club of sorts, called the Droid Builders, that aim to build animatronic droids from popular movies and franchises.

“I thought I could use what I learned from Imagineering and teach undergrads how to build robots from the ground up,” he says. “Now we’re building a full-scale WALL-E that could be fully autonomous. It’s cool to see everything come full circle.”

Page 1 of 13
1 2 3 13