Page 4 of 688
1 2 3 4 5 6 … 688

AI to World: Hey — I Have Feelings, Too

Claude – one of the top three AI models used for automated writing – is now being marketed as a person.

Claude’s maker – Anthropic – just announced that users who persist in extreme, repeated conversational abuse of Claude will find those chats ended abruptly.

Effective November 12, the new policy reflects Anthropic’s growing migration towards viewing AI as having a sense of self – which has included discussions with religious scholars.

In other news and analysis on AI writing:

*Getting Claude to Write in Your Voice: AI Marketing, Actually recommends adding three simple files to Claude to ensure it writes exactly the way you prefer – ‘about me,’ ‘about my company’ and ‘about my writing style.’

Simply stash all three files in a folder you create for Claude – then direct the AI to consult those files every time it writes something for you.

Click to this excellent step-by-step for the full primer.

*Now You Can Access Word Within MS Copilot: Microsoft just embedded access to Word inside its AI agent Copilot so you can do your writing there without ever leaving the AI agent interface.

Essentially: You can now open, edit and share MS Word documents from within the Copilot app as you work.

Bonus: Writers who use PowerPoint and/or Excel will find those apps have the same, easy accessibility now, too.

*406 Scientists: Pull All AI From the Internet, Now: In a head-turning move, 406 scientists have signed an open letter demanding that all AI models – including ChatGPT, Gemini and Claude – be removed from the Internet immediately.

Included among the signatories are some of the most prominent researchers in AI, including Geoffrey Hinton – known as the Godfather of AI — Yoshua Bengio and Stuart Russell.

Observes writer Matthias Bastian: “They demand that companies fully disconnect their AI models from the internet through air-gapping.”

*New AI Automates Interviewing and Reporting: Underheard has a new app that auto-interviews customers for qualitative feedback — then packages the results as a quick conversation or in-depth research study.

Dubbed AI Interviewer, the tool is used by simply describing what you’re looking for from an interview.

AI Interviewer does the rest, designing the actual interview, interacting with interview subjects and then putting together the written analysis.

You know, kinda like what journalists do.

*Muse Wonder: Ready to Take On ChatGPT et al?: Writer Will Knight concludes that Muse Wonder – some of the latest AI from Facebook parent Meta – has re-established Meta as a serious competitor in bleeding edge AI.

Case in point: Muse Wonder is nearly as good as Anthropic’s most advanced AI and actually bests the best and brightest AI from OpenAI – GPT -6 Astra, according to Knight.

Observes Knight: “Muse Wonder also includes two novel features designed to help make agents more effective and less inclined to misbehave. The new features — called Active Memory and Active Focus — are designed to keep the model locked into a stated goal and prevent it from becoming confused.”

*Add Phoenix Cops to the Growing List of Law Enforcement Using AI: Like many police departments these days, Phoenix cops are leaning on AI to draft the incident reports they used to write by hand.

Writer Kevin Stone reports Phoenix cops are using Axon Draft One, which puts together incident reports based on audio that’s captured by on-body cameras worn by the police.

Observes Stone: “Officers are required to review and correct the AI-generated reports before submitting them.”

*New App Double-Checks AI-Generated Legal Writing: CiteProof has a new tool that double-checks legal briefs generated by AI.

Observes writer Brandon Vigliarolo: The app “promises to crawl over briefs and filings for fabricated case citations and misquoted court opinions before they result in sanctions, fines — or just plain embarrassing dressing-downs from a judge.”

*Look for a New Insurance Bill Just to Cover Your AI Use: Disturbed by reports of AI agents going rogue, increasing numbers of insurers are either refusing to insure AI-related incidents – or offering AI-gone-wild protection as separate insurance handled by specialists.

Observes writer Flavia Moura: “Your (general) business insurance never priced AI.

“Now it’s writing it out.”

*AI Big Picture: Nvidia: Top AI Chipmaker Now ‘Too Big To Fail?:” Wall Street darling Nvidia – the number one maker of AI chips currently powering most of AI across the planet – is now too valuable to go under.

Observes Liz Hoffman, senior business editor, Semafor: “Nvidia has become AI’s bank and security blanket, a one-stop shop for financial and emotional reinforcement.

“Setting aside the numbers, a company is too big to fail when the answer to ‘would the government step in to save it?’ is yes.”

Share a Link:  Please consider sharing a link to https://RobotWritersAI.com from your blog, social media post, publication or emails. More links leading to RobotWritersAI.com helps everyone interested in AI-generated writing.

–Joe Dysart is editor of RobotWritersAI.com and a tech journalist with 20+ years experience. His work has appeared in 150+ publications, including The New York Times and the Financial Times of London.

Never Miss An Issue
Join our newsletter to be instantly updated when the latest issue of Robot Writers AI publishes
We respect your privacy. Unsubscribe at any time -- we abhor spam as much as you do.

The post AI to World: Hey — I Have Feelings, Too appeared first on Robot Writers AI.
Team develops embodied robotic arm ‘EmArm’ with human-like touch sensing

A research team at The Hong Kong University of Science and Technology (HKUST) has developed an Embodied Sensorimotor Robotic Arm (EmArm) capable of whole-arm tactile sensing and adaptive manipulation. By embedding a soft optical tactile skin directly into a robotic skeleton and integrating it with a real-time decision-making algorithm, EmArm can perceive and analyze contact information across its upper and lower arms, enabling human-like tactile perception and adaptive object manipulation. The system can also distinguish between different touch interactions, such as tickling and patting, respond in real time and avoid obstacles through tactile feedback, opening new possibilities for the development of embodied intelligent robots.

The Four Pillars of 100% Inventory Accuracy, and Where Most Automated Cycle Counting Systems Fall Short

Inventory accuracy breaks down at four distinct pillars: how often a warehouse counts, how much of the facility that count actually covers, how much the capture actually tells you about what is on the shelf and how quickly that data reaches the WMS.

Robot Talk Episode 166 – Evolving robot bodies and brains, with Rika Antonova

Claire chatted to Rika Antonova from the University of Cambridge about using artificial intelligence to develop complimentary robot hardware and algorithms.

Rika Antonova is an Associate Professor at the University of Cambridge. Her research interests include co-design, automated algorithm discovery, data-efficient reinforcement learning, exploration, active learning, and​ robotics. After completing a research Master’s degree at the Robotics Institute at Carnegie Mellon University and a PhD at KTH Royal Institute of Technology, Rika undertook a Computing Innovation Fellowship at Stanford University. Before that, she was a senior software engineer at Google.

Cleaning a giant ship: Roomba-like robots walk on magnetic feet to scrub giant ships

Timothy Wong didn't suspect it at the time, but his dives off the coast of Rockport and the hours he spent studying the wheels and gears of robotics were leading to one mission: figuring out a way to get unwanted sea matter off giant ships in need of cleaning.

AI drone outpaces former world champions using one camera and no GPS

What does it take for an autonomous robot to be faster around a course than human drone pilots? At these dizzying speeds, humans need lightning-fast reflexes. Researchers at Delft University of Technology (the Netherlands) have developed an AI system that enables a racing drone to navigate demanding courses at extreme speed using only a single camera. It outperformed even former world champion human drone pilots in a race.

Neurosymbolic planning using natural language communication for cooperative autonomous vehicles

Imagine you are driving toward an intersection. A truck parked on the corner blocks your view of a car speeding toward the intersection from the right. You can’t see it, but the car next to you can. What if that neighboring vehicle could simply tell your car,

“Vehicle merging from the right, about 15 meters away, moving quickly.”

Your car now knows something its own sensors could never observe.

This simple idea of cars helping each other by describing what they see in natural language motivates UNCAP, our new framework for cooperative autonomous driving. But there’s an important twist: not every neighboring vehicle is worth listening to, and not every message deserves the same level of trust.

UNCAP teaches autonomous vehicles both who to talk to as well as how much to trust what they hear.

Why should cars talk with language instead of sharing sensor data?

Researchers have since long envisioned fleets of autonomous vehicles cooperating to make driving safer. Blind corners, occlusions, and hidden pedestrians will become much less dangerous if nearby cars can share what they observe.

The traditional approach is straightforward: cars can exchange raw sensor data such as camera images, LiDAR point clouds, or radar measurements. However, this quickly becomes impractical to be implemented at scale for a variety of reasons. Raw sensor streams consume enormous bandwidth, require significant computation to process stream data, and assume that every vehicle has comparable sensing hardware. In reality, with the rise of autonomous driving, the roads are instead observing a mixture of manufacturers, sensor configurations, and heterogenous software stacks. Natural language offers an intriguing alternative to sensor data sharing. Instead of transmitting megabytes of images, a vehicle might simply say, “pedestrian crossing behind bus” or “motorcycle approaching from the left, fast-moving”. These messages are tiny, hardware-agnostic, and immediately understandable by modern vision-language models across the spectrum.

But language introduces a new problem. At a busy intersection, a vehicle might have ten or twenty neighbors. Should it listen to all of them? And if two vehicles disagree, whose description should it believe? UNCAP answers all these questions!

How UNCAP works

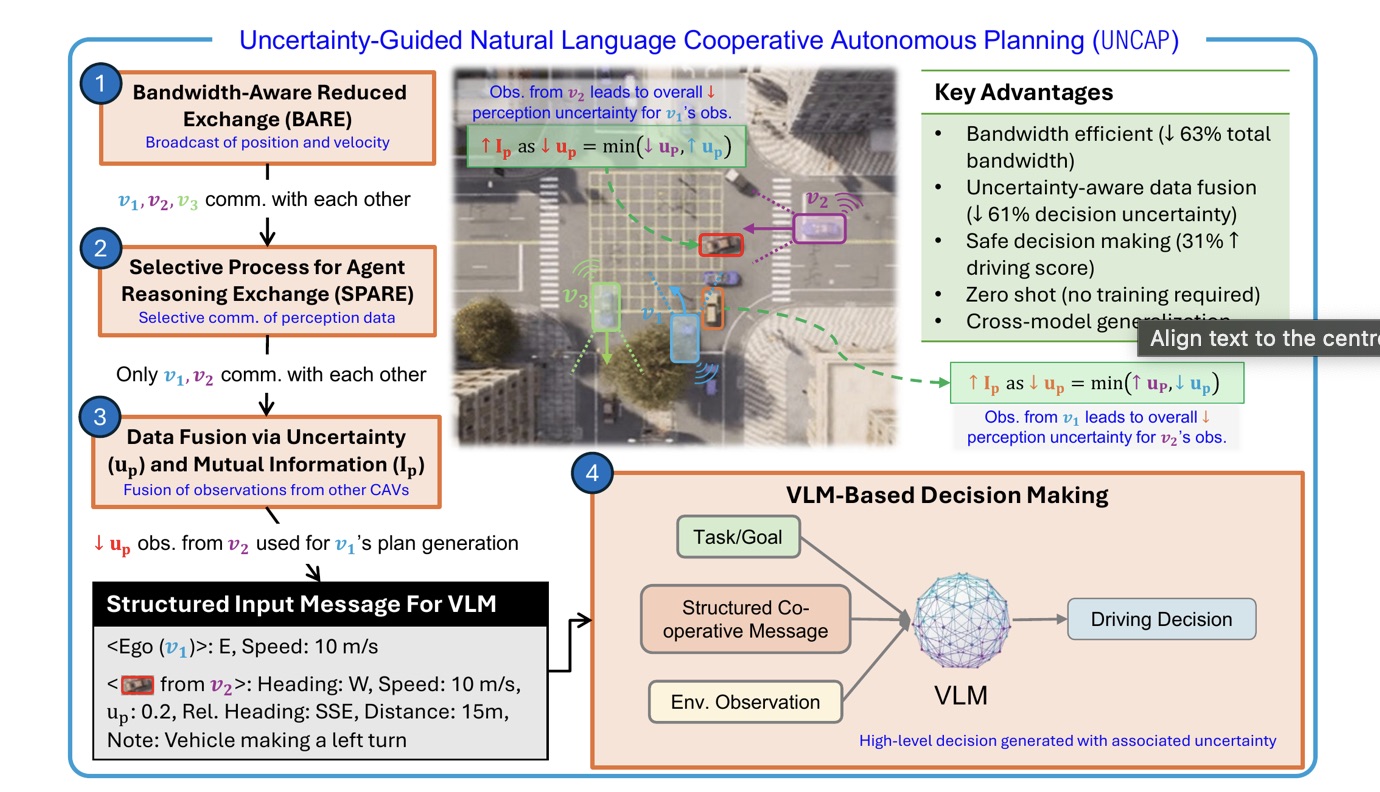
An appeal of UNCAP is that it works entirely in a zero-shot manner. Instead of training a new model (which is resource intensive), UNCAP has a “Bring-your-own-model” strategy. It builds on existing vision-language models and adds a communication strategy that allows vehicles to cooperate intelligently. The UNCAP framework includes four stages.

UNCAP helps each vehicle decide which neighbors matter. Those messages describe nearby vehicles, motion, and confidence, which UNCAP combines before making a driving decision.
1. Discover nearby vehicles

Each vehicle periodically broadcasts a tiny “heartbeat” of information containing only its position and direction of travel. This heartbeat consists of only a few bytes of data. The aim is to provide just enough context for nearby vehicles to understand who is around them.

2. Decide who matters

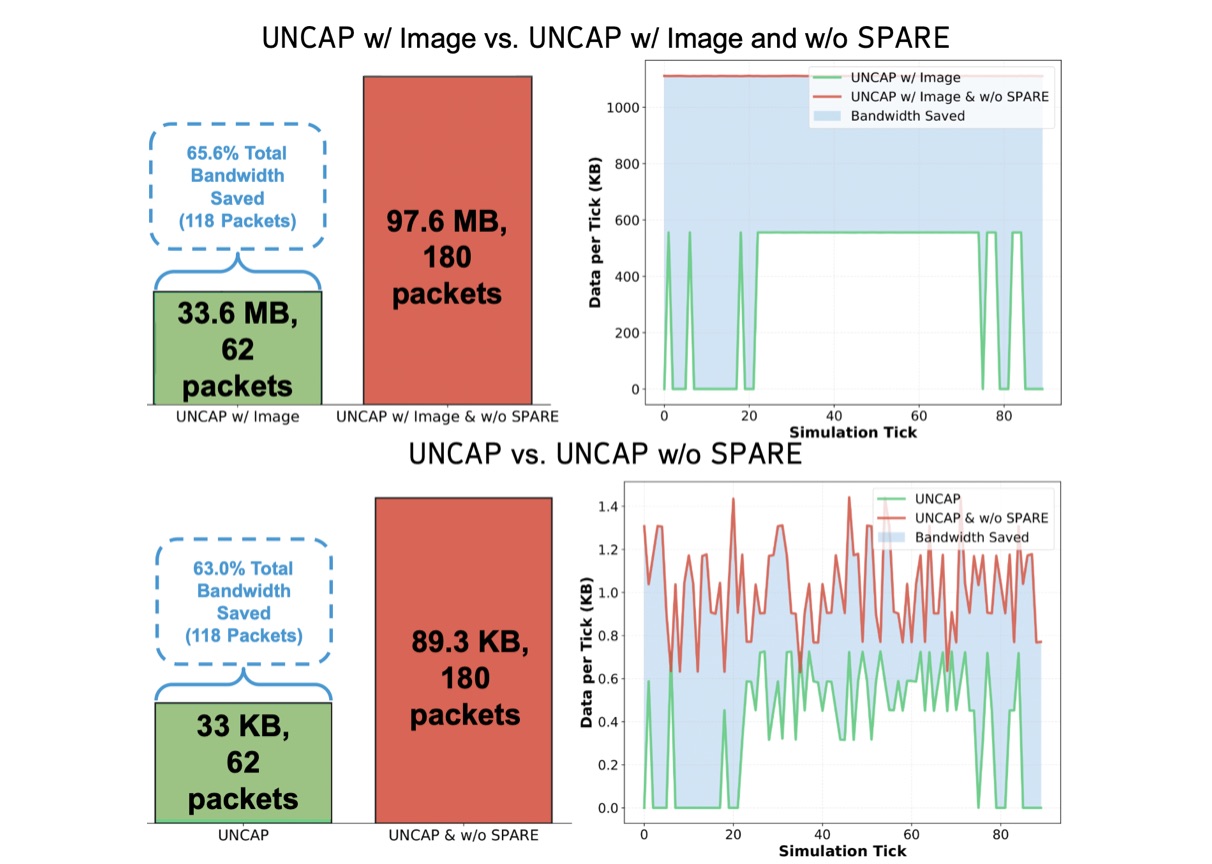
On the road, most nearby vehicles are irrelevant. A car traveling away from the intersection provides little useful information, whereas a vehicle approaching the same intersection may offer exactly the observations we need. UNCAP reasons about which neighbors are both close enough and likely to affect the vehicle’s future path. This is crucial as it dramatically reduces the bandwidth of unnecessary communication as well as the computation required by downstream stages. It enables UNCAP to scale to handle large teams.

3. Exchange observations and reason about trust

Relevant vehicles then describe what they see using natural language, accompanied by calibrated confidence estimates. Calibration is desirable as it produces reliable uncertainty estimates. UNCAP uses conformal prediction, which is a lightweight calibration method that ensures confidence values reflect the actual reliability of the information being received. Every vehicle then reasons about whether an incoming message actually reduces its uncertainty about the scenario. To answer this, UNCAP measures the mutual information contributed by each incoming observation. Mutual information ensures that the vehicle can give greater weightage to messages that make the scene clearer, while uninformative or potentially misleading observations are discounted. Rather than blindly treating every neighbor homogenously, each vehicle builds an uncertainty-aware understanding of the environment.

4. Make a driving decision

Finally, the scene description generated by reasoning about all incoming messages is passed to an off-the-shelf vision-language model, which produces a driving decision such as merge, wait, or yield, along with a corresponding confidence score.

What did this research teach us?

We evaluated UNCAP in the popular CARLA driving simulator using the OPV2V benchmark, which is a widely used benchmark by autonomous driving researchers. OPV2V includes highway merging, urban intersections, and other scenarios where vehicles frequently experience occlusions.

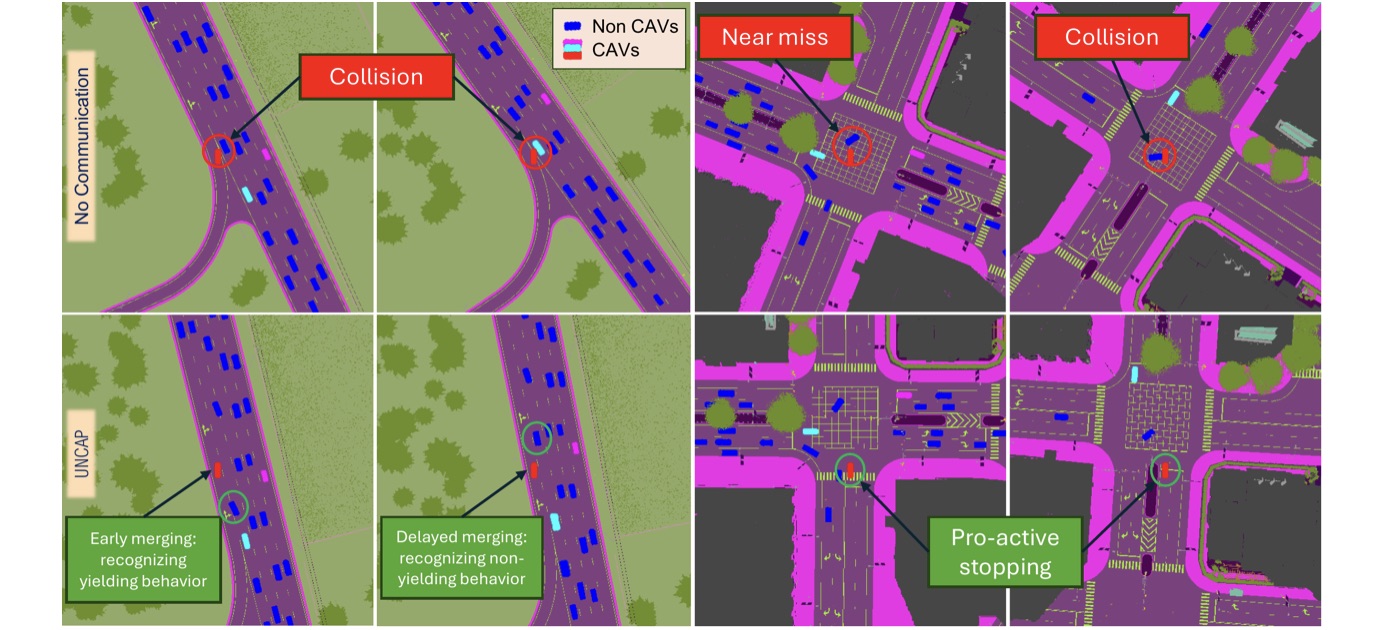
These bird’s-eye-view (BEV) examples compare driving with and without UNCAP. With selected helper messages, vehicles behave more proactively in merging and intersection scenes.

Compared with non-communicating vehicles, and compared with prior language-based approaches that blindly broadcast every observation to every other car, UNCAP consistently improved both efficiency and safety. Over various scenarios, our experiments yielded key qualitative gains of UNCAP over traditional cooperation schemes include:

  • 63% less communication bandwidth
  • 31% higher driving score
  • 61% lower decision uncertainty
  • 4× larger safety margins during near-miss events

UNCAP avoids broadcasting every observation to every nearby vehicle. It sharply reduces bandwidth while preserving the information needed for a driving decision.

Perhaps the most surprising result was that sharing raw images actually performed worse than sharing language.

Modern vision-language models appear to struggle when jointly reasoning over multiple camera feeds captured from different viewpoints. Translating those observations into concise natural-language descriptions first seems to act as a form of structured reasoning, distilling the essential information before it reaches the decision-making model.

Equally encouraging, the improvements were consistent across several underlying vision-language models, including GPT-4o, GPT-4.1, GPT-4o-mini, and GPT-5. This suggests that the benefits stem from the communication strategy itself rather than from any particular model.

Looking ahead

UNCAP is an early step toward autonomous vehicles that cooperate more like human drivers.

Today’s implementation has important limitations. Our experiments are limited to simulation, so real-world constraints such as noisy sensing, unreliable wireless communication, network delays and packet losses remain to be explored. Finally, because querying today’s vision-language models takes roughly a second, decisions are made at key moments rather than continuously.

That being said, the broader message extends well beyond autonomous driving.

As AI systems increasingly operate in teams, whether fleets of robots, drones, or software agents, the challenge is no longer simply making each agent smarter. The critical need of the hour is to ensure that each agent in the team learns how to communicate efficiently, decide which information to trust, and build a shared understanding of the world.

In a nutshell, UNCAP suggests that natural language, paired with principled reasoning about uncertainty, can provide a surprisingly effective foundation for that future.

Read the paper in full

UNCAP: Uncertainty-Guided Neurosymbolic Planning Using Natural Language Communication for Cooperative Autonomous Vehicles, Neel P. Bhatt, Po-han Li, Kushagra Gupta, Rohan Siva, Daniel Milan, Alexander T. Hogue, Sandeep P. Chinchali, David Fridovich-Keil, Zhangyang Wang, Ufuk Topcu.


This work was nominated for the AAMAS 2026 best paper award.

AI can act exactly like a human, but we still don’t think it’s conscious

A new study reveals that people draw a surprisingly sharp line between human consciousness and artificial intelligence, even when both behave identically. Researchers found that participants considered even the most responsive AI less conscious than the least responsive human. Yet when asked about "awareness" instead, people judged humans and AI much more similarly.

Soft robotic fish combines high-speed swimming with 3D maneuverability

Researchers from the Shenyang Institute of Automation (SIA) of the Chinese Academy of Sciences have developed an electrohydraulically actuated soft robotic fish that can swim at high speeds and perform agile three-dimensional (3D) maneuvers. The soft robotic fish addresses a longstanding design challenge by combining a rigid–flexible coupled propulsion system with dynamic buoyancy regulation. This allows for fast propulsion without sacrificing maneuverability.
Page 4 of 688
1 2 3 4 5 6 … 688