SUTD researchers have developed a reinforcement-learning-based safety system that teaches a stair-traversing service robot to brace itself mid-fall, addressing one of the biggest barriers to deploying autonomous robots on staircases.
In robotics, there’s peak performance, and there’s everyday performance. The strain of scaling from the controlled pilot environment to the uncontrolled stress of real-time operations is where many deployments fall apart.
Claire chatted to Ahti Heinla from Starship Technologies about their AI-powered delivery robots that operate independently on streets and pavements.
Ahti Heinla is the co-founder and CEO of Starship Technologies, the world’s leading autonomous delivery company building AI-powered robots that operate fully independently in real-world environments. One of the original engineers behind Skype’s billion-dollar success, Ahti later made a quiet pivot into robotics, spending the past decade advancing practical, consumer-facing AI. Under his leadership, Starship has completed more than 10 million autonomous deliveries with a fleet of over 2,700 robots navigating streets, pavements, weather, and people, without human intervention.
Artificial Intelligence (AI) is a rapidly growing technology that is used for a wide range of applications across industries. Small, mid-sized, mid-sized, and multinational companies are using AI technology and enhancing their capabilities to work smart in this digital sphere.
Like retail, e-commerce, and manufacturing sectors, AI is gaining prominence across healthcare and pharma sectors. Leveraging the power of this modern Artificial Intelligence in Pharma Industry, the companies are finding innovative ways to resolve some of the significant issues that the pharma sector is facing today.
Yes. AI-powered apps using machine learning, deep learning, predictive analytics, and big data have brought a radical shift in the paradigm of pharma.
Artificial intelligence in Pharmaceutical Industry has the potential to promote innovation, while at the same time increasing productivity and providing better results. In addition, Artificial Intelligence in Pharma Industry offers a value proposition to the companies by creating new and latest business models.
You can observe AI implementation in almost every aspect of the pharmaceutical field. From drug discovery and development to drug manufacturing to supply chain and marketing, AI has its impact. Hence, AI in Pharmaceuticals and Healthcare ensures cost-effectively operations, business efficiency, and hassle-free approvals for new drugs. We learn more about benefits of artificial intelligence in pharmaceutical industry as well.
In this article, we would like to give you a brief overview of the top 10 AI applications in the pharmaceutical sector. These best AI trends & use cases in pharma will let you understand the rapid AI adoption in pharma.
The Best Applications Of Artificial Intelligence In Pharmaceutical Industry
#1 Drug Discovery Process and Design
The use of AI in the pharmaceutical industry for the design and development of drugs is increasing. From making small molecules to determining novel biological targets, AI plays a prominent role in drug target identification and validation. It is widely used for multi-target drug innovation and biomarker identification in an efficient way with great accuracy.
A major benefit of the pharma industry is that when AI is administered during drug testing, it minimizes the drug development time. Artificial Intelligence in Pharma Industry will also benefit drug developers to accomplish clinical trials faster and launch their products into the market for use. It leads to a cost and time-saving development process and also makes the innovative drugs available for improving patient care without side effects.
For example, researchers in pharmaceutical can identify and verify novel cancer drugs using data such as longitudinal EMR records (Electronic Medical Records) and other omic data. The AI systems using ML and other data analytics algorithms will extract insights from EMR data and creates the best formulations to design and develop drugs that cure tumors well.
#2 R&D
Pharma companies across the globe are using advanced AI-powered tools and ML algorithms to smoothen the drug research, development, and innovation process. These technology tools are designed to detect complex patterns in large datasets. Therefore, AI in pharma industry can be used to resolve problems associated with the research and development process.
This ability to study patterns of various diseases and to determine which composite formulations are best suited for the treatment of specific symptoms of a particular disease is excellent. Pharma industries can invest in the R&D of such drugs that are more likely to treat a disease or medical condition successfully.
#3 Disease Prevention
Pharmaceutical organizations can use Artificial intelligence to develop medicines Parkinson’s and Alzheimer’s and very rare diseases.
As per Global Genes, it is a fact that almost 95% of rare diseases do not have more drugs to treat and cure faster. However, thanks to the innovative capabilities of AI and ML. The use of AI in the pharmaceutical industry will completely transform this scenario and ensure the most-advanced models for detecting hazardous diseases in the early stage and improve patient outcomes.
#4 Next-Level Diagnosis
Physicians can use advanced machine learning systems to gather, process, and analyze patient health care data. Healthcare professionals across the globe are using deep learning and ML to securely store patient data in the centralized storage system or cloud. It is called Electronic Medical Records (EMR).
Physicians may refer to these health records when they need to understand the effect of a specific genetic trait on a patient’s health or how medicine treats it. Machine Learning systems can use data stored in EMRs to generate real-time estimates for diagnostic purposes and to indicate appropriate treatment for the patient.
As ML technologies are capable of processing and analyzing large amounts of data quickly, they can help speed up the diagnostic process, thereby saving millions of lives.
#5 Epidemic Prediction
Pharma companies and healthcare industries are using ML and AI technologies to monitor and assess the spread of infections worldwide. These modern technologies are used for consuming data collected from various resources, analyzing several environmental, biological, and geographical factors on the population health of diverse geographical regions, and deriving data insights to reduce the impact of epidemics in the future.
Artificial intelligence and machine learning models are particularly beneficial for underdeveloped economies that lack medical infrastructure and financial framework to combat the spread of infection.
A good example of this is the ML-based malaria outbreak prediction model, which serves as a warning tool for malaria outbreaks and helps health care providers take the best action to combat it.
#6Identifying Clinical Trials
It is one of the key pharmaceutical use cases for embracing AI into existing models. The use of AI in the pharmaceutical industry for identifying drug candidates which are under final clinical trials from vast clinical data is on the rise.
Artificial Intelligence in Pharmaceutical Industry will help companies in analyzing thousands of samples in minutes and automatically logs data related to how patients are responding during clinical trials.
Here are a few advantages of using AI in pharma industry for clinical trials:
AI apps help in monitoring drug performance and evaluating drug responses
With the integration of speech recognition technologies, AI apps for pharma will be helpful for recording patients’ oral text during drug trial phases. It means that AI applications will record patients’ responses.
Hence, the use of artificial intelligence in clinical trials has the potential in fastening clinical trials and introduce the safest drugs into the market. It is also one of the top use cases for Machine Learning in Pharma. Speech analysis and real-time patient and drug monitoring activities will be done accurately using ML, deep learning, and natural language processing technologies.
#7 Drug Adherences and Dosage
The adoption of AI in Pharmaceuticals and Healthcare is increasing at a rapid pace for identifying the right amount of drug intake to ensure the safety of drug consumers. AI technology will monitor patients during clinical trials and suggest the right amount of dosage at regular intervals.
These are all key pharmaceutical use Cases for Embracing AI. AI in Pharmaceuticals and Healthcare will definitely accelerate automation in processes and drive more accuracy than ever before.
These AI trends & use cases in pharma will assist drug development and healthcare companies in ensuring efficacy across end-to-end production lines and delivering top-notch performance in front of the FDA.
Conclusion
The scope of Artificial intelligence and machine learning in the Pharma industry looks very promising in the future. AI opportunities for pharma companies are unmeasurable.
The use of AI applications in pharma will ensure operational excellence across drug structure design, drug development processes, selecting patients for clinical trials, monitoring drug performance, identifying proper dosage, etc.
At this year’s Google I/O, the atmosphere at the Shoreline Amphitheatre was electric as the CEO laid out a vision for a world deeply intertwined with agentic AI. We heard about the sheer computing muscle of the new TPU 8i […]
Scientists at the USC Viterbi School of Engineering have developed a robotic hand that can hear a melody once and play it back after just two minutes of self-taught practice on a keyboard, without relying on sheet music or preprogrammed scores.
Cyborg insects have long been studied as bio-hybrid systems that combine living organisms with small electronic devices. These systems may one day support tasks such as disaster search and rescue, environmental monitoring, and sensing in spaces too small or dangerous for conventional robots. However, most existing systems control insects based mainly on externally visible behavior, such as whether the insect is walking or stopping.
Mechanical hands dexterous enough to thread a needle, childlike dancing robots and adult-sized ones to help with deliveries were on display Thursday as the Humanoids Summit Tokyo opened.
For us, Automte less about showcasing products and more about engaging in engineering discussions, such as managing duty cycles and thermal limits, addressing torque versus size constraints, and evaluating control architectures.
MIT engineers and colleagues have developed a soft, flexible gel that dramatically changes its conductivity upon the application of light. This figure shows a soft, stretchable circuit created with a rectangular bar of the gel. A copper electrode is attached to the left. A stylus and associated metal network connects the electrode to three “stations” on the bar. Light has been shone on the first two stations, creating conductivity that turns on each station’s lightbulb. Because the third station has not been exposed to light it is nonconductive and the bulb is off. Credits: Image courtesy of the Wallin lab.
Consider the chief difference between living systems and electronics: The first is generally soft and squishy, while the latter is hard and rigid. Now, in work that could impact human-machine interfaces, biocompatible devices, soft robotics, and more, MIT engineers and colleagues have developed a soft, flexible gel that dramatically changes its conductivity upon the application of light.
Enter the growing field of ionotronics, which involves transferring data through ions, or charged molecules. Electronics does the same, with electrons. But while the latter is well established, ionotronics is still being developed, with one huge exception: living systems. The cells in our bodies communicate with a variety of ions, from potassium to sodium.
Ionotronics, in turn, can provide a bridge between electronics and biological tissues. Potential applications range from soft wearable technology to human-machine interfaces
“We’ve found a mechanism to dynamically control local ion population in a soft material,” says Thomas J. Wallin, the John F. Elliott Career Development Professor in MIT’s Department of Materials Science and Engineering and leader of the work. “That could allow a system that is self-adaptive to environmental stimuli, in this case light.” In other words, the system could automatically change in response to changes in light, which could allow complex signal processing in soft materials.
Although others have developed ionotronic materials with high conductivities that allow the quick movement of ions, those conductivities cannot be controlled. “What we’re doing is using light to switch a soft material from insulating to something that is 400 times more conductive,” says Xu Liu, first author of the paper and former MIT postdoc in materials science and engineering who is now an incoming assistant professor at King’s College London.
Key to the work is a class of materials known as photo-ion generators (PIGs). These can become some 1,000 times more conductive upon the application of light. The MIT team optimized a way to incorporate a PIG into polyurethane rubber by first dissolving a PIG powder into a solvent, and then using a swelling method to get it into the rubber.
Much potential
In the material reported in the current work, the change in conductivity is irreversible. But Liu is confident that future versions could switch back and forth between insulating and conducting states.
She notes that the current material was developed using only one kind of PIG, polymer (the polyurethane rubber), and solvent, but there are many other kinds of all three. So there is great potential for creating even better light-responsive soft materials.
Liu also notes the potential for developing soft materials that respond to other environmental stimuli, such as heat or magnetism. “We’re inspired to do more work in this field by changing the driving force from light to other forms of environmental stimuli,” she says.
“Our work has the potential to lead to the creation of a subfield that we call soft photo-ionotronics,” Liu continues. “We are also very excited about the opportunities from our work to create new soft machines impacting soft wearable technology, human-machine interfaces, robotics, biomedicine, and other fields.”
Additional authors of the paper are Steven M. Adelmund, Shahriar Safaee, and Wenyang Pan of Reality Labs at Meta.
Read the work in full
Soft photo-ionotronics, Xu Liu, Steven M. Adelmund, Shahriar Safaee, Wenyang Pan & Thomas J. Wallin, Nature Communications (2026).
Engineers have invented an ingenious liquid-metal pump that could make future soft robotics and wearable devices much more portable and agile. The innovation, led by the University of Bristol and published in the journal Nature Communications, presents a low-voltage power source with the potential to transform robotic systems for a wide range of applications, from robotic legs to haptic gloves used in medical and industrial settings.
Symmetry is everywhere in nature, from the bilateral form of vertebrates to the radial geometry of starfish. For decades, roboticists have tried to copy these shapes and their abilities with bodies that look like humans, dogs or insects.
Cornell researchers used stretchable fiber-optic sensors to create a soft robot gripper that can predict the ripeness of strawberries by touch. Credit: Anand Mishra.
By David Nutt
When assessing the ripeness of fruit, sight and smell can tell you a lot, but the best indicator is often how the fruit feels.
The technology, developed in the lab of Rob Shepherd, the John F. Carr Professor of Mechanical Engineering in the Cornell Duffield College of Engineering, could lead to more resilient and ecological food production and increase the availability of fruit species that are difficult to cultivate.
Shepherd’s Organic Robotics Lab previously demonstrated the potential of stretchable fiber-optic sensors to give soft robotic systems the ability to feel the same dynamic, tactile sensations that enable humans to navigate the natural world. In recent years, the team has expanded into agriculture, designing a soft robotic gripper that injects living plant leaves with sensors that help it detect and communicate with its environment.
“The great thing about Cornell is we’re a really great agriculture school, and a lot of avenues are opening up because of it,” Shepherd said. “It really allows us to uniquely combine our robotics expertise with our agricultural prominence.”
To develop a way to evaluate and handle fruit with care, Shepherd’s team partnered with Marvin Pritts, professor of horticulture and global development in the College of Agriculture and Life Sciences, who specializes in developing sustainable production methods for berry crops.
In order to train and test their gripper, they needed a model fruit. And for that, they turned to the strawberry.
“You can accurately tell when strawberries are ripe by their color,” Shepherd said. “So we could train our model to know if it’s ripe based on touch, then validate our model by looking at the color. And Anand was able to accurately estimate whether it was the right time to pick strawberries based off of the stiffness he measured.”
The soft robot gripper has an equally soft touch. The gripper is equipped with two different fiber-optic sensors, one to measure the curvature of the finger, and the other to measure the pressure at the fingertip. This way the robot can estimate the shape of an object and adjust its grip accordingly to grasp the ripe fruit without bruising it.
“The fiber-optic strain gauges have the same mechanical properties as the grippers that are using them. So it’s kind of like the flesh feels the fruit, rather than having separate sensors,” Shepherd said.
The researchers also included a planetary gear mechanism so, once the fruit is grasped, the robot wrist can rotate and twist the strawberry off its vine, instead of pulling or plucking it, which can strain and damage the fruit.
This soft-gripping technology, developed in the Organic Robotics Lab, could lead to more resilient and ecological food production and increase the availability of fruit species that are difficult to cultivate. Credit: Anand Mishra.
For cases in which touch isn’t enough, the researchers installed a camera in the gripper’s palm to find fruit that are occluded by leaves or other vegetation. However, the device will be particularly handy when ripeness can’t be detected visually, such as for avocadoes, pineapples or – Shepherd’s favorite – pawpaws.
“The problem with pawpaws is you can’t see when they’re ripe, and they ripen so fast that if you’re not there at the right time, you just miss them,” he said. “And you can’t harvest and ship them, because they don’t survive shipping very well, either. That’s one reason we don’t have pawpaws in grocery stores. But this can help with that.”
The technology could have an even greater impact on sustainable farming practices.
“Robots will allow us to do things we cannot do economically right now. We have row crops because row crops fit our machines. But if we have a larger amount of smaller robots, we can have mixed cropping of different species that support each other,” Shepherd said. “Instead of having soy one year and corn the next, you can have them both. Or you could have interspersed species that are resistant to pestilence, that help block infestations and reduce the amount of pesticides and fertilizer. You can have drought resistance from canopy species.
“It’s very complicated to manage a farm that way,” he said, “and robots could allow us to do that.”
The research was supported by the National Science Foundation Center for Research on Programmable Plant Systems (CROPPS) and the Cornell Institute for Digital Agriculture.
Every LLM deployment has a ceiling, a latency curve, and a unit cost. Most teams operate blindly, discovering their deployment limits only when over-provisioning exhausts their GPU budget or peak traffic causes a catastrophic failure.
Three numbers matter: maximum sustained concurrency before GPU saturation, end-to-end latency at that concurrency, and cost per million tokens at sustained load. These metrics emerge from how the model interacts with your hardware, runtime, tokenizer, and traffic mix.
DataRobot 11.8 changes that with LLM Profiling Jobs: a native integration of NVIDIA AIPerf, the industry-standard generative AI benchmarking tool. One authenticated POST benchmarks any DataRobot LLM deployment serving an OpenAI-compatible web server, sweeps the concurrency range and use cases you define, and returns the empirical inputs to Quota Reservations (available in DataRobot 11.9).
Why LLM capacity is hard to predict
LLM inference doesn’t scale linearly. Compute and memory demands per request depend dynamically on prompt length, response length, sampling parameters, and KV cache utilization.A deployment that serves 50 short chat turns per second can stall at 5 long-context RAG requests per second on the same hardware. Four distinct behaviors make static or speculative capacity estimates unreliable:
Latency is non-linear in concurrency. Time to first token and inter-token latency stay roughly flat across a wide concurrency range, then rise sharply once GPU memory bandwidth or compute saturates. TTFT rises when prefill compute saturates; inter-token latency rises when decode memory bandwidth saturates. Which one bites first depends on the workload mix and the deployment’s GPU configuration (single card or a cluster). The saturation knee is the operating point that matters, and it can’t be inferred from a single low-load measurement.
Throughput and latency trade off. You can squeeze more total tokens per second out of a deployment by running it at higher concurrency, at the cost of slower per-user response. The right trade-off depends on your SLO, not on a generic recommendation.
Use case mix matters. Two deployments running the same model on the same hardware can have very different capacity if one serves short Q&A and the other serves long-context summarization. The mix has to be in the test, or the test is wrong.
Caching and routing change the answer. Prefix caching (common in agentic coding with periodic compaction) and KV-aware routing can lift effective throughput dramatically. Profiles run against a cold deployment with random inputs represent the floor, not the ceiling.
LLM Profiling Jobs make those curves visible.
How LLM benchmarks help
Defend capacity and quota decisions with measured data. When finance questions a four-H100 footprint, or when cross-functional teams negotiate shared capacity, you can justify the architecture with empirical profiling data. Saturation knee, SLO target, and forecast traffic make GPU sizing an evidence-based line item. The same numbers feed Quota Reservations directly.
Account for cost per consumer. Total token throughput plus the GPU instance cost gives a cost-per-million-tokens figure that supports chargeback or showback. Attribute spend to consumers proportionally to their reservations, not by guesswork.
Compare models and hardware on equal terms. Hold the workload profile constant and vary one dimension at a time: the same model on different GPU configurations (a B200 node vs a B300 node, or 4×H100 vs 8×H100), or different models on the same configuration (Qwen3.6 35B-A3B MoE vs Qwen3.6 27B dense). Because AIPerf metrics match NVIDIA’s published NIM benchmarks, the numbers are also directly comparable to public benchmarks for the same model and hardware combinations. The right input for procurement and capacity-sizing decisions before a hardware order.
Prove a change is safe before you ship it. Before a model upgrade, vLLM bump, driver swap, or GPU migration, rerun the same profile and compare against the prior baseline. Regressions show up in the metrics, not in incident reports.
What LLM benchmark metrics mean
The four headline metrics AIPerf returns map directly to user experience and to GPU economics:
Time to first token (TTFT, ms). Measures how long a user waits between submitting a prompt and seeing the first character; this metric is dominated by prefill compute.
Inter-token latency (ITL, ms). Average time between successive output tokens once generation has started. Sets the perceived “typing speed” of the response.
Request throughput (requests/sec). Full request-and-response cycles per second at the tested concurrency. The basis for the Capacity (RPM) value on Quota Reservations.
Total token throughput (tokens/sec). Total tokens (input plus output) processed per second across all concurrent requests. The basis for cost-per-token economics.
For each metric, AIPerf reports averages and percentiles (p50, p90, p99). When GPU saturation is detected during the sweep, estimatedCapacity reports the iteration immediately before it. When saturation isn’t detected (the common case, since the profiler isn’t co-located with the deployment), estimatedCapacity reports the last iteration tested. Sweep wide enough that the curve clearly bends, or treat the result as a lower bound.
Submitting a job
A profiling request takes four parameters: a deploymentId (the ID of the DataRobot LLM deployment you want to profile), a list of concurrency levels to sweep, a request count scalar (how many requests each concurrent worker issues), and one or more use cases. Each use case defines an input sequence length (ISL), an output sequence length (OSL), standard deviations for both, and a weight (prob). Weights across all use cases must sum to 100.
Poll the Status API with the returned statusId. When the job finishes, the API returns 303 See Other and the Location header points to the results endpoint:
estimatedCapacity is the sustained operating point. results contains one entry per concurrency level tested, with the full metric set.
Reading the curve
The estimated-capacity numbers tell you the sustained ceiling. The per-iteration results show you how the deployment behaves as load climbs toward that ceiling. The table below is an illustrative example.
When AIPerf detects GPU saturation during the sweep, it identifies the iteration before it (concurrency 50 here) and returns those metrics as estimatedCapacity. When saturation isn’t detected, estimatedCapacity is simply the last iteration tested, which is why the sweep needs to extend past the knee. Anything past that point trades user-perceived latency for marginal throughput gains. If the product spec calls for TTFT under 1 second, the curve shows the deployment supports up to roughly 50 concurrent requests with margin: provision GPU so peak concurrent demand stays at or below that level.
From profiling result to Quota Reservations config
The bridge from a profiling run to a Quota Reservations configuration is direct:
Quota setting
Where it comes from
Example (from sample above)
Capacity (RPM)
estimatedCapacity.request_throughput × 60
8.84 req/sec × 60 ≈ 530 RPM
Utilization Threshold
Pick 70–80% of Capacity so enforcement engages before the saturation knee
80% → enforcement at ~424 RPM
Reserved % per consumer
Sized to the minimum each priority consumer needs during contention
30% Production Agent A, 20% Agent B, 30% Agent C, 20% unreserved pool
Take the sample result: 4,524 total tokens per second sustained (input plus output). That is roughly 16.3 million tokens per hour from one deployment.
If the underlying GPU instance costs $X per hour, the cost per million tokens is $X / 16.3. For an instance at $4 per hour, that is about $0.25 per million tokens. For $12 per hour, about $0.74. To calculate cost per million output tokens—the standard benchmark for public API comparisons—divide the total cost by the workload’s output share. For example, given an ISL of 200 and an OSL of 1000, output accounts for roughly 83% of total tokens. At a $4 hourly instance price, this translates to approximately $0.30 per million output tokens.
Every benchmark run gives you a fresh, accurate cost-per-token figure for the exact model, hardware, and quantization combination you’re running. After a vLLM upgrade or a hardware swap, re-run the same profile and confirm your unit economics improved instead of trusting a vendor claim. This is the foundation for per-token and per-agent cost transparency in chargeback.
Choosing your inputs
A useful profile starts with two questions: what concurrency range do you expect in production, and what does your traffic actually look like?
Concurrencies to sweep. Start wide ([1, 10, 50, 100]) to locate the saturation knee, then narrow (such as [40, 50, 60, 70]) for an SLO-grade reading around that point.
Request count scalar. Set it high enough that each iteration runs long enough to smooth out noise. A scalar of 2 is a reasonable starting point. Raise it if variance looks high.
Use cases. Match your real traffic mix. If you serve 70% short chat turns (ISL 200, OSL 300) and 30% long-context RAG (ISL 4000, OSL 800), define two use cases with prob: 70 and prob: 30. Testing a blended traffic mix exposes tail-latency behavior (such as p99 spikes) that a single-use-case average obscures.
Tokenizer. Set it explicitly. The benchmark depends on accurate token counts, so the matching tokenizer is part of a correct measurement.
Operational notes
Profiling generates synthetic load. Run jobs against a non-production LLM deployment or during a maintenance window.
Because the traffic is synthetic, prefill cache hits won’t appear in token metrics.
Profiling treats the deployment as a black box. Whether the deployment runs on one GPU or many, and whatever combination of tensor, pipeline, data, or expert parallelism it uses, the profile measures the externally observable result.
Jobs can be canceled with a DELETE to the profiling job ID. Cancellation is best-effort and may not stop a run that is nearly complete.
Before you submit, store your Hugging Face token in DataRobot Credential Management as an “API Token (API Key)” credential. AIPerf uses it to fetch the model tokenizer, and the stored credential prevents rate-limit errors.
Get access
LLM Profiling Jobs are in private preview in DataRobot 11.8. To enable on your tenant, contact your DataRobot account team. They will turn on the Enable Dynamic Quota Capacity Profiling feature flag (the internal name for LLM Profiling Jobs) and configure the profiling job image in your cluster.
At the core of the Titanium platform is a unique combination of multi-axis control, high computing power, and integrated functional safety, all within an exceptionally small footprint.
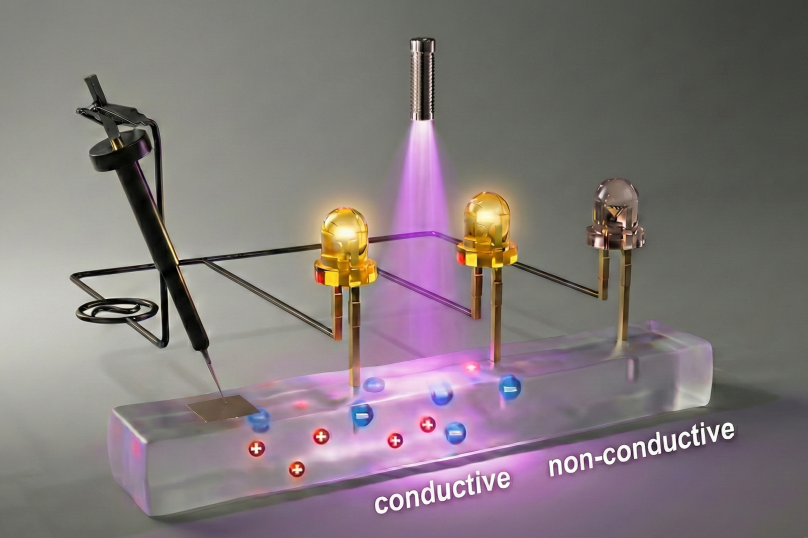 MIT engineers and colleagues have developed a soft, flexible gel that dramatically changes its conductivity upon the application of light. This figure shows a soft, stretchable circuit created with a rectangular bar of the gel. A copper electrode is attached to the left. A stylus and associated metal network connects the electrode to three “stations” on the bar. Light has been shone on the first two stations, creating conductivity that turns on each station’s lightbulb. Because the third station has not been exposed to light it is nonconductive and the bulb is off. Credits: Image courtesy of the Wallin lab.
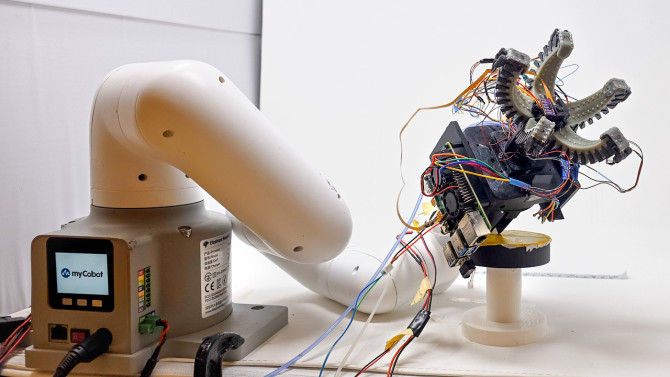 Cornell researchers used stretchable fiber-optic sensors to create a soft robot gripper that can predict the ripeness of strawberries by touch. Credit: Anand Mishra.
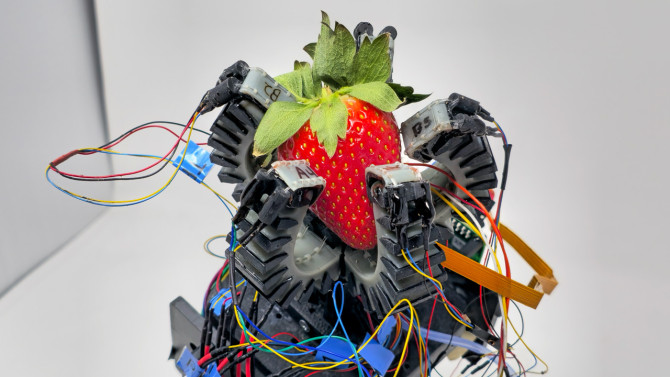 This soft-gripping technology, developed in the Organic Robotics Lab, could lead to more resilient and ecological food production and increase the availability of fruit species that are difficult to cultivate. Credit: Anand Mishra.