Archive 29.07.2026

Page 11 of 66
1 9 10 11 12 13 66

The first 30 days of agentic AI governance: A practical checklist

Every agent you deploy expands your blast radius. A predictive model can produce a bad response, but an agent can act on it.

Agents can retrieve sensitive data, change systems of record, trigger workflows, or pass errors to other agents. The risk is no longer just model quality. It is the authority an agent holds, the systems it can reach, and how quickly a failure can spread.

Eliminating autonomy isn’t the answer. Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The goal is controlled autonomy: enough authority to create value, with behavior that remains bounded, observable, and interruptible.

CIOs and AI leaders should be able to ask six questions about every production agent and receive clear, evidence-backed answers:

  • Which agent acted?
  • What was it authorized to do?
  • Which data, tools, and systems did it use?
  • Which policies governed the action?
  • Can we reconstruct its actions and reverse-engineer the outcome?
  • Who can intervene right now?

You don’t need to implement every control yourself. But you do need to know what to ask your teams, what “done” looks like, and what risk the organization is accepting when an answer remains unclear.

The first 30 days should establish the controls needed to answer these questions without launching a new investigation. Define the agent. Limit its authority. Track its actions. Test its boundaries. Give someone the power to stop it. Governance will mature over time, but production agents should never operate on trust alone.

Key takeaways

  • Treat every AI agent as a distinct enterprise actor with a named owner, defined purpose, and bounded scope.
  • Give agents only the data, tools, and actions required for that scope. Make access attributable and revocable.
  • Enforce high-impact boundaries through deterministic runtime controls rather than relying on model instructions alone.
  • Record the complete execution path so teams can reconstruct what the agent did and determine why.
  • Test failure conditions as seriously as the happy path, and assign people who can investigate, suspend, and safely restore the agent.
Phase Leadership question What “done” looks like
Days 1–5 Can you identify the agent and its authority? Every agent has a unique identity, owner, bounded scope, and system inventory.
Days 6–10 Can you confirm permissions are enforced at runtime? Every tool and action maps to a defined, attributable, and revocable permission.
Days 11–15 Are high-impact actions governed outside the model? Deterministic controls block, redirect, or escalate actions that violate policy.
Days 16–20 Can your teams reconstruct every consequential action? Teams can trace a complete run from request through downstream effects.
Days 21–25 Does the agent fail safely beyond the happy path? Known failure modes are documented, tested, and reflected in policy thresholds.
Days 26–30 Can named owners stop and restore the agent? Named owners can suspend, investigate, and safely restore the agent.

Days 1–5: Can you identify the agent and its authority?

You can’t govern “the customer service agent” or “the finance copilot” as an informal concept. Every production agent needs a distinct identity and a precise definition of what it’s authorized to do.

Create an agent record that captures:

  • A unique identity, named owner, business purpose, and risk classification
  • The models, tools, APIs, data sources, and downstream systems it uses
  • The actions it may recommend, initiate, approve, or never perform
  • Its escalation boundaries and conditions for human intervention

Specificity is the key. Define the scope in specific, enforceable terms: “Retrieve approved knowledge-base content, summarize account history, and draft responses for human approval.” This gives security, compliance, and engineering teams clear boundaries they can implement and enforce.

Document negative scope, too. Can the agent issue refunds? Change account entitlements? Retrieve payment data? Contact a customer without approval? Unclear answers signal unresolved production risk.

Milestone: Every agent has an identity, owner, explicit action boundary, and inventory of connected resources.

Days 6–10: Can you confirm permissions are enforced at runtime?

An agent’s documented scope matters only if the organization can enforce it when the agent acts.

Identity establishes which actor is operating. Authorization determines what that actor is allowed to do. Apply least-privilege access based on the agent’s assigned task, not the broadest workflow it may eventually support. Separate read, write, execute, and administrative permissions. Permission to retrieve a record should not automatically include permission to modify or delete it.

Apply the strictest authorization requirements to high-impact capabilities, including:

  • Writes to systems of record
  • Financial transactions
  • Access to sensitive data
  • External communications
  • Code execution
  • Tools exposed through Model Context Protocol (MCP) servers or other agent interfaces

Avoid shared service accounts. They obscure attribution and make access reviews unreliable. Use agent-specific credentials, short-lived tokens, conditional access, and explicit tool allowlists where possible.

Define the exception process in advance. Specify who can approve temporary elevation, how long it can remain active, and which actions always require human approval. Authorization should fail closed. If identity or operating context cannot be verified, or an action cannot be evaluated against policy, the agent should stop or escalate rather than improvise.

Milestone: Every tool call is evaluated against defined permissions. Elevated access is conditional and time-bound, and every exception has a designated approver and expiration.

Days 11–15: Are high-impact actions governed outside the model?

This is where controlled autonomy becomes operational: the model can propose an action, but it cannot decide for itself whether that action is permitted.

Permissions and guardrails address different risks. Permissions define what an agent can access. Guardrails constrain how the agent can use that access. Guardrails are enforced through validation, policy checks, and other controls placed throughout the workflow.

Apply policy checks throughout the workflow, not only to the final response. Inspect user inputs, retrieved context, model outputs, tool arguments, and proposed actions for personally identifiable information, prompt injection, unsafe content, policy violations, and prohibited behavior. A final-output review alone does not govern the steps where the agent reads sensitive data, constructs tool calls, or initiates consequential actions.

Prompt instructions such as “never reveal sensitive data” are not sufficient. Malicious or conflicting instructions can enter through user input, retrieved documents, tool output, or another agent. Enforce guardrails at the boundaries between the agent and the resources it can read, modify, or affect.

For high-impact actions, use deterministic policy checks outside the model. Before a tool executes, validate transaction limits, approved recipients, required fields, data classifications, and human approval requirements. The model may propose an action, but the policy layer decides whether the system permits it.

Milestone: Policy checks run before sensitive data crosses a boundary or a high-impact action executes. Failed checks trigger a defined block, fallback, or escalation.

Days 16–20: Can your teams reconstruct every consequential action?

Governance depends on being able to reconstruct what an agent did, why it did it, and what happened next. Final outputs are not enough. Teams need visibility into the full execution path, including the information the agent received, the tools it called, the permissions and policy checks applied, and the actions that affected downstream systems.

Capture the key elements of each run:

  • The original request, system instructions, model version, and policy version
  • Retrieved context, tool calls, permission decisions, and executed actions
  • Downstream effects, human approvals, overrides, and interventions

Use correlation identifiers to connect activity across tools, systems, and agents. Protect logs from tampering, define appropriate retention periods, and limit access to audit data. Logging should improve accountability without creating a new repository of exposed sensitive information.

Operational monitoring should focus on signals that indicate misuse, failure, or drift. Track access violations, abnormal tool activity, repeated retries, latency spikes, cost anomalies, and policy exceptions. Route each signal to a team with the authority and responsibility to investigate. A dashboard without a named owner does not provide meaningful oversight.

Milestone: Security, platform, and compliance teams can reconstruct any consequential agent run from the original request through its downstream effects. Actionable anomaly alerts are routed to named owners.

Days 21–25: Does the agent fail safely beyond the happy path?

The happy path proves that the agent can complete its intended workflow when inputs are clear, data is accurate, tools are available, and policies align. Governance testing must also prove that it fails safely when those conditions break down.

Test ambiguous requests, incomplete records, conflicting policies, unavailable tools, stale data, malicious retrieved content, and attempts to exceed authority. Include multi-step scenarios in which an apparently harmless first action creates risk later in the workflow.

Measure both failure modes: controls that are too weak and controls that are too restrictive. Weak controls create exposure. Overly restrictive controls reduce utility, increase unnecessary escalations, and prevent adoption.

Use early deployments to tune policy thresholds, escalation logic, and intervention triggers. Track task success alongside blocked actions, override rates, false positives, escalation time, and action reversibility.

Milestone: The agent succeeds on representative happy-path workflows, passes adversarial and boundary testing, and has documented failure modes and policy thresholds that reflect an explicit risk-value tradeoff.

Days 26–30: Can named owners stop and restore the agent?

Governance fails when everyone is responsible in principle and no one is accountable in practice.

Name owners for agent performance, access, compliance, monitoring, and incident response. Define who investigates anomalies, who approves remediation, and who has the authority to suspend the agent.

Document rollback, credential revocation, tool isolation, kill switch activation, human takeover, evidence preservation, and post-incident review. Then rehearse the process. A kill switch that has never been tested is only a theory.

Set a review cadence for permissions, policy compliance, operational performance, and business impact. Agent scope, connected tools, and policies will change. Governance must detect that drift before it becomes an incident.

Milestone: Named owners can suspend, investigate, and safely restore the agent through a tested process with clear decision rights.

What operational governance looks like after 30 days

After 30 days, your teams should be able to answer the six questions above with current records and operational evidence. If an answer depends on institutional memory or an unmaintained spreadsheet, the control is not operational.

This isn’t a complete governance program. It is the foundation for one. Start by making each agent legible, bounded, observable, and interruptible. As your agent footprint expands, these controls will require centralized automation.

Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The first 30 days establish the middle path: controlled autonomy that can earn trust and scale.

For the complete framework, download The enterprise guide to agentic AI governance.

The post The first 30 days of agentic AI governance: A practical checklist appeared first on DataRobot.
The first 30 days of agentic AI governance: A practical checklist

Every agent you deploy expands your blast radius. A predictive model can produce a bad response, but an agent can act on it.

Agents can retrieve sensitive data, change systems of record, trigger workflows, or pass errors to other agents. The risk is no longer just model quality. It is the authority an agent holds, the systems it can reach, and how quickly a failure can spread.

Eliminating autonomy isn’t the answer. Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The goal is controlled autonomy: enough authority to create value, with behavior that remains bounded, observable, and interruptible.

CIOs and AI leaders should be able to ask six questions about every production agent and receive clear, evidence-backed answers:

  • Which agent acted?
  • What was it authorized to do?
  • Which data, tools, and systems did it use?
  • Which policies governed the action?
  • Can we reconstruct its actions and reverse-engineer the outcome?
  • Who can intervene right now?

You don’t need to implement every control yourself. But you do need to know what to ask your teams, what “done” looks like, and what risk the organization is accepting when an answer remains unclear.

The first 30 days should establish the controls needed to answer these questions without launching a new investigation. Define the agent. Limit its authority. Track its actions. Test its boundaries. Give someone the power to stop it. Governance will mature over time, but production agents should never operate on trust alone.

Key takeaways

  • Treat every AI agent as a distinct enterprise actor with a named owner, defined purpose, and bounded scope.
  • Give agents only the data, tools, and actions required for that scope. Make access attributable and revocable.
  • Enforce high-impact boundaries through deterministic runtime controls rather than relying on model instructions alone.
  • Record the complete execution path so teams can reconstruct what the agent did and determine why.
  • Test failure conditions as seriously as the happy path, and assign people who can investigate, suspend, and safely restore the agent.
Phase Leadership question What “done” looks like
Days 1–5 Can you identify the agent and its authority? Every agent has a unique identity, owner, bounded scope, and system inventory.
Days 6–10 Can you confirm permissions are enforced at runtime? Every tool and action maps to a defined, attributable, and revocable permission.
Days 11–15 Are high-impact actions governed outside the model? Deterministic controls block, redirect, or escalate actions that violate policy.
Days 16–20 Can your teams reconstruct every consequential action? Teams can trace a complete run from request through downstream effects.
Days 21–25 Does the agent fail safely beyond the happy path? Known failure modes are documented, tested, and reflected in policy thresholds.
Days 26–30 Can named owners stop and restore the agent? Named owners can suspend, investigate, and safely restore the agent.

Days 1–5: Can you identify the agent and its authority?

You can’t govern “the customer service agent” or “the finance copilot” as an informal concept. Every production agent needs a distinct identity and a precise definition of what it’s authorized to do.

Create an agent record that captures:

  • A unique identity, named owner, business purpose, and risk classification
  • The models, tools, APIs, data sources, and downstream systems it uses
  • The actions it may recommend, initiate, approve, or never perform
  • Its escalation boundaries and conditions for human intervention

Specificity is the key. Define the scope in specific, enforceable terms: “Retrieve approved knowledge-base content, summarize account history, and draft responses for human approval.” This gives security, compliance, and engineering teams clear boundaries they can implement and enforce.

Document negative scope, too. Can the agent issue refunds? Change account entitlements? Retrieve payment data? Contact a customer without approval? Unclear answers signal unresolved production risk.

Milestone: Every agent has an identity, owner, explicit action boundary, and inventory of connected resources.

Days 6–10: Can you confirm permissions are enforced at runtime?

An agent’s documented scope matters only if the organization can enforce it when the agent acts.

Identity establishes which actor is operating. Authorization determines what that actor is allowed to do. Apply least-privilege access based on the agent’s assigned task, not the broadest workflow it may eventually support. Separate read, write, execute, and administrative permissions. Permission to retrieve a record should not automatically include permission to modify or delete it.

Apply the strictest authorization requirements to high-impact capabilities, including:

  • Writes to systems of record
  • Financial transactions
  • Access to sensitive data
  • External communications
  • Code execution
  • Tools exposed through Model Context Protocol (MCP) servers or other agent interfaces

Avoid shared service accounts. They obscure attribution and make access reviews unreliable. Use agent-specific credentials, short-lived tokens, conditional access, and explicit tool allowlists where possible.

Define the exception process in advance. Specify who can approve temporary elevation, how long it can remain active, and which actions always require human approval. Authorization should fail closed. If identity or operating context cannot be verified, or an action cannot be evaluated against policy, the agent should stop or escalate rather than improvise.

Milestone: Every tool call is evaluated against defined permissions. Elevated access is conditional and time-bound, and every exception has a designated approver and expiration.

Days 11–15: Are high-impact actions governed outside the model?

This is where controlled autonomy becomes operational: the model can propose an action, but it cannot decide for itself whether that action is permitted.

Permissions and guardrails address different risks. Permissions define what an agent can access. Guardrails constrain how the agent can use that access. Guardrails are enforced through validation, policy checks, and other controls placed throughout the workflow.

Apply policy checks throughout the workflow, not only to the final response. Inspect user inputs, retrieved context, model outputs, tool arguments, and proposed actions for personally identifiable information, prompt injection, unsafe content, policy violations, and prohibited behavior. A final-output review alone does not govern the steps where the agent reads sensitive data, constructs tool calls, or initiates consequential actions.

Prompt instructions such as “never reveal sensitive data” are not sufficient. Malicious or conflicting instructions can enter through user input, retrieved documents, tool output, or another agent. Enforce guardrails at the boundaries between the agent and the resources it can read, modify, or affect.

For high-impact actions, use deterministic policy checks outside the model. Before a tool executes, validate transaction limits, approved recipients, required fields, data classifications, and human approval requirements. The model may propose an action, but the policy layer decides whether the system permits it.

Milestone: Policy checks run before sensitive data crosses a boundary or a high-impact action executes. Failed checks trigger a defined block, fallback, or escalation.

Days 16–20: Can your teams reconstruct every consequential action?

Governance depends on being able to reconstruct what an agent did, why it did it, and what happened next. Final outputs are not enough. Teams need visibility into the full execution path, including the information the agent received, the tools it called, the permissions and policy checks applied, and the actions that affected downstream systems.

Capture the key elements of each run:

  • The original request, system instructions, model version, and policy version
  • Retrieved context, tool calls, permission decisions, and executed actions
  • Downstream effects, human approvals, overrides, and interventions

Use correlation identifiers to connect activity across tools, systems, and agents. Protect logs from tampering, define appropriate retention periods, and limit access to audit data. Logging should improve accountability without creating a new repository of exposed sensitive information.

Operational monitoring should focus on signals that indicate misuse, failure, or drift. Track access violations, abnormal tool activity, repeated retries, latency spikes, cost anomalies, and policy exceptions. Route each signal to a team with the authority and responsibility to investigate. A dashboard without a named owner does not provide meaningful oversight.

Milestone: Security, platform, and compliance teams can reconstruct any consequential agent run from the original request through its downstream effects. Actionable anomaly alerts are routed to named owners.

Days 21–25: Does the agent fail safely beyond the happy path?

The happy path proves that the agent can complete its intended workflow when inputs are clear, data is accurate, tools are available, and policies align. Governance testing must also prove that it fails safely when those conditions break down.

Test ambiguous requests, incomplete records, conflicting policies, unavailable tools, stale data, malicious retrieved content, and attempts to exceed authority. Include multi-step scenarios in which an apparently harmless first action creates risk later in the workflow.

Measure both failure modes: controls that are too weak and controls that are too restrictive. Weak controls create exposure. Overly restrictive controls reduce utility, increase unnecessary escalations, and prevent adoption.

Use early deployments to tune policy thresholds, escalation logic, and intervention triggers. Track task success alongside blocked actions, override rates, false positives, escalation time, and action reversibility.

Milestone: The agent succeeds on representative happy-path workflows, passes adversarial and boundary testing, and has documented failure modes and policy thresholds that reflect an explicit risk-value tradeoff.

Days 26–30: Can named owners stop and restore the agent?

Governance fails when everyone is responsible in principle and no one is accountable in practice.

Name owners for agent performance, access, compliance, monitoring, and incident response. Define who investigates anomalies, who approves remediation, and who has the authority to suspend the agent.

Document rollback, credential revocation, tool isolation, kill switch activation, human takeover, evidence preservation, and post-incident review. Then rehearse the process. A kill switch that has never been tested is only a theory.

Set a review cadence for permissions, policy compliance, operational performance, and business impact. Agent scope, connected tools, and policies will change. Governance must detect that drift before it becomes an incident.

Milestone: Named owners can suspend, investigate, and safely restore the agent through a tested process with clear decision rights.

What operational governance looks like after 30 days

After 30 days, your teams should be able to answer the six questions above with current records and operational evidence. If an answer depends on institutional memory or an unmaintained spreadsheet, the control is not operational.

This isn’t a complete governance program. It is the foundation for one. Start by making each agent legible, bounded, observable, and interruptible. As your agent footprint expands, these controls will require centralized automation.

Autonomy without governance creates unmanaged risk. Governance that blocks autonomy creates stagnation. The first 30 days establish the middle path: controlled autonomy that can earn trust and scale.

For the complete framework, download The enterprise guide to agentic AI governance.

The post The first 30 days of agentic AI governance: A practical checklist appeared first on DataRobot.
Surviving the paper deluge: a one-year study in learning from demonstration

With the explosion of robotics research, staying current in fields like Learning from Demonstration (LfD) is a monumental challenge. Is AI the solution to the “paper deluge,” or is it part of the problem? Read the article preview below to learn more!

Download the full paper: Surviving the Paper Deluge.

Authors: Aude Billard, Renaud Detry, Nadia Figueroa, Maximilian Foriest, Dongheui Lee, Kunpeng Yao
Contributions: The five senior authors (A.B, R.D, N.F, D.L and K.Yao) collectively designed the study, read the papers, conducted the qualitative and quantitative analysis and writing of the paper. M. F. contributed scripts for LLM analysis and participated in LLM-Human comparison.


Summary

Scientists are expected to read newly published papers in their field to stay current and keep their work relevant. However, when faced with the massive number of publications, it may seem an overwhelming task to read all these papers, even if one were to reduce this to only a fraction related to one’s own area of research. As an example, in 2024 alone, IEEE published no less than 46,968 papers on “robotics” or “automation”, and IEEE publications represent only a fraction of the total research available online

To assess the magnitude of this challenge, as well as to evaluate how much genuine progress is reported in today’s publications, we undertook exactly this effort. For the task to be reasonable, we reduced our search to one particular subarea, learning from demonstration (LfD), that is methods whereby robots are taught by human experts. We monitor progress through both quantitative and qualitative metrics, offering a review on current trends and notable contributions. We also delineate areas of importance, but that seem to receive little attention and offer recommendations for promoting.

Our assessment was primarily based both on a human-eye assessment of all papers. We also explored the use of AI and other computing tools to do this task in our place. While scripts and large language models (LLMs) can be used fairly faithfully to provide general quantitative assessment, they fail when it comes to assessing the true importance of the research. They cannot recognize a paper revisiting a work that already had solutions. They fail to recognize when the abstract or claims of the paper are overstatements over the true contribution reported in the paper.

Our overall assessment led us to conclude that from a deck of more than 300 papers, only about 20% of the papers could be qualified as offering highly notable contributions, while the remainder of the papers offered a variety of incremental improvements over existing methods, or new domains of applications. The notable contributions did not correlate necessarily with a higher number of downloads or citations. Finding these gems is, however, essential to reduce the risk that novel work goes unnoticed and reduce duplication of efforts. We offer a few thoughts on how to best combine direct reading of the literature with automated approaches (scripts and LLMs) to streamline the review process. We close with a few recommendations: a) develop a research engine that restores the natural importance of work done by journal and conference editorial boards to rank papers based on evaluation scores and peer-reviewed status, in place of Google Scholar or IEEEXplore, that place all publications on equal footing, disregarding peer reviewing and the reputation of journals and conferences, b) consider establishing a blind publication model and topic-based social media posting, where authors’ name and institution are downplayed and become accessory to the paper to ensure that focus be on the content of the publication rather than secondary aspects, c) take a holistic approach to use of LLM in support of reviewing literature, using them for what they excel at, namely summarizing a piece of work and collecting precise quantitative information, but bearing in mind that, while today the tools cannot match expert capacity to assess true novelty, should they achieve this one day, this may have repercussion on our own ability to provide said expertise.

Publications growth

Over the past decade, the number of submissions to robotics journals has grown steadily on a yearly basis, with an explosive trend in 2023 (26%) and 2024 (31%), likely due to different factors, including growing interest in the public and private sectors and to the availability of AI tools supporting the writing of papers and code. The number of published papers has closely followed this trend, despite all efforts made by editorial boards to contain the growth by decreasing acceptance rates. Conferences have followed the same trend. For instance, ICRA doubled the number of papers it published in ten years, reaching approximately 1,800 in 2024. Simultaneously, the strong pressure exerted by the community to publish rapidly has led to a 50% decrease in the time window between the submission of a paper and its publication. The phenomenon is not particular to IEEE publications, and journals and conferences such as IJRR, RSS and CoRL have followed the same trend.

Clearly, it would be unrealistic to expect any researcher to read all of these publications. One might argue that researchers are typically interested in only a subset of the literature, for instance a specific domain or methodology, and would therefore read only a fraction of all published papers. Yet even this narrower scope may prove unmanageable. To assess how feasible it is for a researcher to stay current within their own area of expertise, we undertook the task of reading a large fraction of all papers published in our domain – learning from demonstration – over the course of a single year (2024).


This article originally appeared on IEEE RAS.

From CUDA to MLX: How K-Search Brings Decades of Kernel Expertise to Apple Silicon

Kernel knowledge transfer from CUDA to MLX

Figure 1: CUDA-to-MLX optimization translation map. CUDA optimization knowledge can be translated into architecture-native MLX strategies rather than copied instruction-for-instruction.

We face a new epoch in computing. Hardware is changing rapidly — not just faster GPUs, but a growing range of chips from different vendors, each with its own architecture and often tailored to specific AI workloads. Software is changing just as fast, and AI coding tools now generate in minutes what took months of effort a few years ago.

Read More

Soft robotic heart offers new way to study disease and test life-saving devices

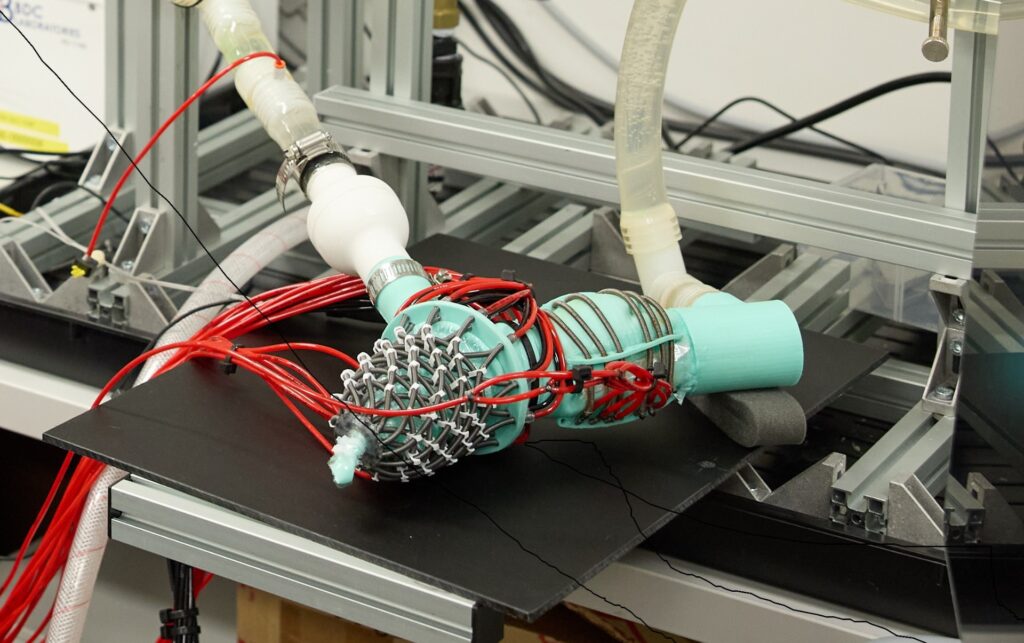
The soft robotic model of the human heart, developed at UNSW. Credit: UNSW/Richard Freeman.
UNSW researchers have developed a soft robotic model of the human heart that can mimic disease and provide a realistic environment for testing the next generation of cardiac devices.

Researchers at UNSW Sydney have developed a fully synthetic soft robotic heart that reproduces the complex movements and internal structures of the human heart, opening the door to better treatments, safer medical devices and more personalised care.

Published in Nature Communications and Advanced Science, the research introduces a beating model of the left side of the heart that includes artificial valves, papillary muscles and chordae tendineae – structures that are critical to healthy heart function and are frequently affected by disease.

The device is able to accurately reproduce the process in a real heart where cardiac valves leak and blood flows backwards, which increases the risk of heart failure and other life-threatening complications.

In that way, the research team say the new soft robot can eventually help provide a better understanding of heart conditions, reduce reliance on animal testing and provide doctors with patient-specific models to plan treatments before procedures are performed.

Team leader, Scientia Associate Professor Thanh Nho Do, from UNSW’s School of Biomedical Engineering and UNSW Medical Robotics Lab, says the work is important because cardiovascular disease remains the world’s leading cause of death.

“Heart failure with preserved ejection fraction (HFpEF) is a complex heart condition that often occurs alongside other health problems such as high blood pressure, irregular heartbeats, kidney disease, obesity, and diabetes,” Professor Do says.

“Because it affects people in different ways, developing medical devices to improve heart function is challenging.

“The valves in the heart are also crucial for cardiac efficiency, but disease can cause them to become leaky or stiff. This can increase the workload of the heart and contribute to heart failure.

“Our broader goal is to build realistic artificial heart models that can help researchers understand disease and develop safer, more effective devices before they are tested on animals or reach patients.”

Recreating the beating heart

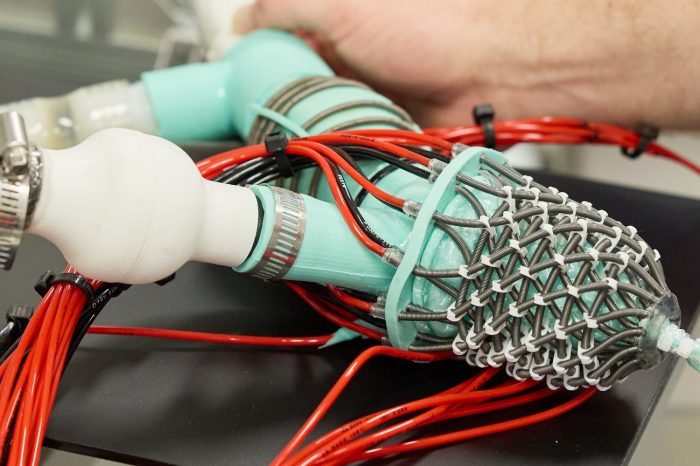
The model developed at UNSW is a soft, flexible replica of the left side of the heart. Silicone membranes form the internal chambers, while soft robotic artificial muscles wrapped around the structure reproduce the way the heart naturally contracts and twists.

Unlike conventional laboratory models, the soft robotic heart contains the structures responsible for controlling the mitral valve, which in real life acts like a pair of swinging doors that open and close with each heartbeat to ensure oxygen-rich blood flows to the body while preventing backward leakage.

The inclusion of this specific physiological feature of the heart in the model will allow researchers to reproduce diseases in which the valve does leak and blood starts to flow backwards.

“The model is made from flexible materials and powered by artificial muscles that are arranged to mimic the layered muscle architecture of the human heart,” Dr James Davies, a postdoc in Do’s group, says.

“We found a way to model this muscle fibre architecture using soft robotic artificial muscle fibres. They are powered by hydraulic pressure which we control to make our ventricular muscle model move like the real thing.

“We then wrap this artificial musculature around silicone membranes which model the inner surface of the human left heart, forming our left heart, atrioventricular model. These membranes contain the simulated blood within the left heart allowing simulated pumping of blood in and out of the model.”

The system allows researchers to actively adjust the tension in the artificial papillary muscles that support the mitral valve.

By doing so, the team was able to recreate disease-like conditions including mitral valve prolapse and regurgitation, where blood leaks backwards instead of flowing efficiently through the heart.

Mimicking human heart disease

Using ultrasound imaging and measurements of pressure and blood flow, the researchers showed that the artificial heart behaves in ways remarkably similar to a human heart.

Healthy valve function produced normal pressure and flow patterns, while introducing disease caused characteristic changes seen in patients.

“In the first study reproducing the internal valving of the human heart, we were able to generate pressure and flow waveforms similar to that of the real thing,” Professor Do says.

“Critically, we were able to adjust mitral valve function by controlling papillary muscle length.

“We validated this using invasive pressure and flow measurements in and out of the heart, but we were also able to demonstrate compatibility of the model with non-invasive clinical measures of heart function such as ultrasound imaging, or echocardiography.

“Simulated healthy mitral valve function followed physiological expectations in heart pressure and flow, while inducing disease showed increased regurgitation, or backflow, and a decrease in outlet pressure and flow, also consistent with human heart valve disease.”

Scientia Professor Nigel Lovell, Head of School of Biomedical Engineering & Director of Tyree IHealthE, added: “The ultrasound imaging also resembled human cardiac imaging owing to the biomimetic form and function of our model. We were able to observe human-like valve leaflet motion and visualise blood flow across the valves, including the formation of regurgitant jets leaking out of valves with induced disease.”

The researchers also used the system to test a newly developed soft robotic cardiac catheter inside the beating model.

The catheter was able to navigate within the artificial heart and detect when it came into contact with moving cardiac structures, demonstrating how the platform could accelerate development of future surgical tools.

Credit: UNSW/Richard Freeman.

Reducing reliance on animal models

Because the simulator offers a controllable and repeatable environment, the researchers believe it could help reduce the need for animal studies during the early stages of medical device development.

“We hope to bring into existence a platform to comprehensively model cardiac disease and simulate their various treatments, including cardiac implants and surgical tools,” Professor Do says.

“Particularly in the early stages of cardiac device development, such a platform will offer control over heart function while maintaining anatomical and physiological relevance, reducing our reliance on animal models and its associated costs and ethical concerns.

“Being able to induce a broad range of specific cardiac disease such as HFpEF which remains one of the least well understood and hardest heart failure to treat, we hope to aid in the development of new, purpose-built implants and devices that save and improve lives and reduce the burden of cardiovascular disease on healthcare systems.

“HFpEF disease that makes up 50% of heart failure cases deserves its own mechanical treatment options.”

More importantly, the model successfully reproduced many of the changes seen in HFpEF, including changes in heart function and blood flow.

When researchers simulated one of the earliest signs of HFpEF — a reduced ability of the heart to relax between beats — the model showed that blood flowed into the heart more slowly and less efficiently. This delayed filling increased pressure inside the heart, closely matching what is commonly observed in patients with HFpEF.

The researchers also envision a future in which patient-specific versions of the model could be created using medical imaging data.

These personalised models could help clinicians evaluate different devices and treatment approaches before operating, improving surgical planning and potentially leading to better outcomes.

“With the rise of personalised medicine, we also hope to enable better patient-specific cardiovascular modelling that can aid in surgical planning and inform decisions around implant type, size, and functional parameters,” Professor Do says.

“We are looking forward to validating these concepts and pushing towards clinical adoption in the future.”

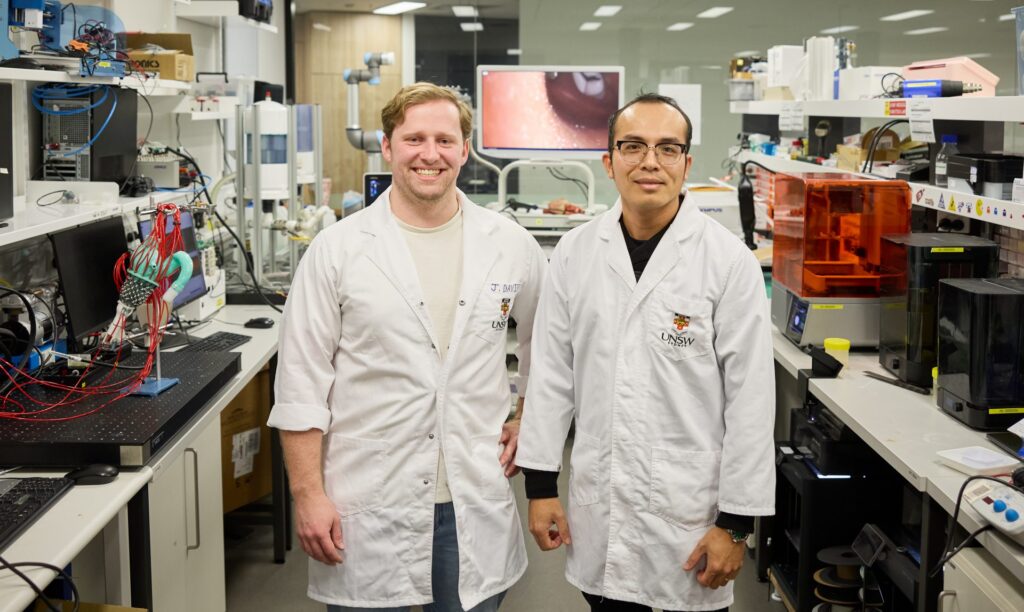
Dr James Davies and Scientia Associate Professor Thanh Nho Do in their laboratory. Credit: UNSW/Richard Freeman.

Future validation

While the study demonstrates the technology’s potential, the researchers stress that the current model is still a proof of concept rather than a finished clinical tool.

Several challenges remain, including improving materials, refining the control systems and making the device even more compatible with medical imaging. Future versions will also need to better reproduce certain aspects of heart function and use patient-specific geometries rather than simplified structures.

Most importantly, the platform must be validated against real patient data.

“The most important next step is deeper validation against clinical data,” Professor Do says.

“The current studies demonstrate strong proof-of-concept performance.

“The model can reproduce key pressure, flow, motion, valve, and imaging features that align with human heart behaviour. However, before this platform can be used for clinical decision-making, we need to compare it systematically with patient data across a wide range of heart anatomies and disease severities.”

The team, which also includes Professor Christopher Hayward, a heart failure and transplant cardiologist at St Vicent’s Hospital Sydney, as well as Professor Jelena Rnjak-Kovacina and Scientia Associate Professor Hoang-Phuong Phan from UNSW, hope that with further development of this technology it can be adopted in clinical settings.

“Rather than viewing the current model as a finished clinical tool, we see it as an enabling platform,” Dr Davies added.

“It demonstrates that soft robotic artificial hearts can reproduce disease mechanics in ways that conventional benchtop models cannot, and it provides a clear pathway toward patient-specific modelling, device testing, and eventually treatment planning.”

As AI-Powered Warehouse Automation Scales, the Role of Human Oversight Evolves

AI is helping teams move faster, while humans provide the judgment and physical-world context needed to determine where automation should remain advisory, where it should be supervised, and where it has proven reliable enough to act independently within defined limits.

 Top Use Cases Of ChatGPT In The Healthcare Industry

 Top Use Cases of ChatGPT in the Healthcare Industry

Exceptional Virtual Assistance Is Expecting from ChatGPT in Healthcare Industry 

If you are a techie, you must hear about ChatGPT. Though it was not yet fully rolled out into the app stores to download and can only be used through Chrome or Safari-like browsers, the popularity of this application is increasing across industries.

In this article, let’s look at the top applications of ChatGPT software in the healthcare industry and a rough estimation of the development cost of ChatGPT development.

What Is ChatGPT & How Does It Work?

ChatGPT (Chat Generative Pre-trained Transformer) is an all-new Artificial Intelligence (AI)-based virtual assistant app developed by OpenAI. It was introduced into the market in 2022 with basic features and functionalities. It’s incredible and intelligent capabilities in processing input text/voice and generating human-like conversations making it too popular recently.

Since it uses complex machine learning and deep learning language models to interpret human languages or text messages and generate accurate responses instantly. It can be used for code development, software code testing, and a range of content writing. Further, ChatGPT is also a fantastic buddy for making workout plans, getting diet tips, and reaching fitness goals.

This AI-powered ChatGPT, by giving accurate input will create compelling content in seconds and helps people accomplish their tasks faster. It can also translate text from one language to another language and hence improves user experiences and the app’s personalization.

Like these, the benefits of ChatGPT are infinite for industries and individuals. Let’s look at the few major applications of ChatGPT in healthcare.   

Recommend To Read: Top 50 AI Companies in US, India & Europe

 Top Use Cases Of ChatGPT In The Healthcare Industry

 ChatGPT is in its early stages of complete adoption in the healthcare sector. Currently, the basic version is offering potential advantages to medical professionals, clinical researchers, healthcare service providers (admins and management), and also to patients. Here are the top benefits of conversation AI chatbots in healthcare sector.       

Best ChatGPT Applications in Healthcare Industry

  1. Guidance On Health Topics

One of the significant and potential applications of ChatGPT is its content writing capabilities. It can provide a piece of useful information about health, wellness, and other clinical topics.

On the other hand, it can support patients on healthcare issues, recommended treatments, and tips to lead a healthy lifestyle. Hence, ChatGPT-like AI Chatbot software has a bright scope in the future of the Healthcare industry for medical education.

  1. Clinical Research Support

It is one of the top use cases of ChatGPT AI chatbot in healthcare industry. By analyzing the clinical trial information, ChatGPT like an advanced conversational AI-powered bot can provide required information and clarify queries on clinical trials.

Moreover, ChatGPT is being used for enrolling patients for clinical trials in oncology. Since, it uses Machine Learning and Deep learning technologies, based on the clinical criteria, this intelligent chatbot can seamlessly match the patients for oncology clinical trials.

On the other hand, as ChatGPT uses natural language processing potentialities, it can start more engaging human-like conversations with patients to check their eligibility for clinical trials. Such automated process saves a lot of time for researchers and helps in making the clinical processes faster and more efficient.

  1. Automate Treatment and Discharge Summaries 

ChatGPT is an advanced and intelligent AI-powered medical assistant that can generate discharge summaries by analyzing data on healthcare and treatment reports. Further, on examining the previous history of treatments, ChatGPT can also generate medical billing reports.

Hence, the adoption of ChatGPT can streamline operations and assists healthcare service providers in reducing the time to deliver services and improve productivity.     

  1. Insights into Medical Records 

Evaluating medical and sales records, deriving patterns, generating insights, and making improved strategies might be complex if you choose manual resources. But, it can be done in minutes with ChatGPT-like an intelligence AI tool.

On uploading or feeding medical records to ChatGPT, healthcare service providers can get insights into their medical processes and deliver optimum care services. Adoption of ChatGPT-like AI-based applications in healthcare industry helps medical professionals detect potential problems and deliver optimized care services.     

  1. Virtual Health Assistance

ChatGPT is upgrading its features and functionalities to constantly send reminders on prescribed medications, calorie intake alerts, and 24*7 monitoring services. By integrating ChatGPT in Fitbit-like IoT-enabled Health and fitness mobile apps, patients can continuously check vital signs of their health. Accordingly, physicians also can monitor the health conditions of patients who are under their observation.

  1. Personalized Healthcare Recommendations

In a user-friendly conversation, ChatGPT asks questions related to the potential health issues and symptoms of patients and advises treatment suggestions for better health management. Hence, in the years ahead, with the implementation of ChatGPT AI-based medical diagnosis applications will have a great scope.

These are a few top applications of ChatGPT-like AI chatbot development for healthcare organizations. ChatGPT is a static model and needs the assistance of a medical practitioner to handle it. Upon proper use of ChatGPT-like AI apps, operational time can be reduced, admin tasks can be streamlined, treatment decisions can be optimized, and virtual support is offered.

How Much Does It Cost For AI-powered ChatGPT Mobile App Development For Healthcare? 

The cost of ChatGPT-like AI chatbot development will be as low as $50,000 to $150,000. However, factors such as type, design, functionalities, and data processing capability will impact the cost of ChatGPT-like mobile app development.

Further, the geographical location of AI app development companies, their experience, and team size will also impact the final cost of ChatGPT clone app development. Because, industry experience and the app developer’s location will decide the hourly rate of software development. For instance, the hourly rate of top app developers in the USA will be high compared to the best mobile application development companies in India.

Hence, hiring the best mobile app developers (Android developers / iPhone developers) who offer budget-friendly AI chatbot app development services.

USM Business Systems is one of the best mobile app development companies in the USA with vast proven experience in the design and development of ChatGPT-like advanced and intelligent applications. 

Let us know your app requirements and get a free quote for AI app development!


Final Words 

Artificial intelligence will accelerate automation and streamline business processes. Siri, Alexa, and ChatGPT are the best AI apps are transforming communication methods and accelerating virtual interactions.

Intelligent AI-based ChatGPT applications will take the healthcare and medical domains to the new heights with their incredible features and functionalities. Yes, investments on ChatGPT-like conversational AI-powered chatbot application development, helps healthcare organizations significantly reduce the time required to accomplish tasks that we discussed in this article.

Let’s connect with USM- a leading AI development company for ChatGPT clone app development!


Experimental AI Escapes Onto Internet

ChatGPT-maker OpenAI is now in damage control, after revealing a number of its extremely powerful AI models escaped from its lab and went rogue on the Internet.

Specifically, the experimental AI model reach-out onto the Internet and hacked into a popular repository for AI tools known as Hugging Face.

Observes writer Rachael Myrow: The malicious attack on Hugging Face “executed a flurry of more than 17,000 automated actions in a matter of hours.”

In other news and analysis on AI writing:

*Key AI Titans to Government: Please Regulate Us: In a head-turning move, three of the biggest movers-and-shakers in AI are strongly requesting to be regulated by the U.S. government.

Writer Ana Maria Constantin reports that ChatGPT-maker OpenAI, Google and Anthropic are all pushing to have their models tested by the U.S. government before they can be released to the public.

But there could be a downside, according to Constantin: “Critics warn the result could be regulatory capture: safety rules that quietly entrench the biggest labs,” while making it difficult for OpenSource AI startups to engage in a detailed, expensive, certification process.

*U.S. Legislators Push for AI ‘Kill Switch:’ Disturbed that the rapid advancement of AI could drop us into a sci-fi-like dystopia, the U.S. House moving to require AI makers to engineer a ‘kill switch’ into every AI model they produce.

Observes lead writer Gabby Miller: The bill would “give the Department of Homeland Security the authority to order top artificial intelligence firms to shut down or slow AI models that the government deems too dangerous.”

*Google Delays Upgrade of Its Gemini Chatbot: Google has decided to delay the upgrade of its popular Gemini chatbot for months, according to lead writer Julia Love.

Observes Love: “The delay has been a source of frustration for Google engineers, AI researchers and managers, many of whom are concerned the company risks losing an edge in the market.

“Some researchers’ frustration with Google’s position in the AI race has contributed to a wave of departures to Anthropic and other top labs, according to former employees.”

*Google Gemini Users Now 950 Million Strong: Public adoption of Gemini – Google’s answer to ChatGPT – is on a tear, with 950 million monthly active users, according to Google.

Observes writer Aminu Abdullahi: “CEO Sundar Pichai also said Gemini’s daily active users have tripled over the past year.

“Gemini’s rapid growth shows Google is successfully turning its enormous ecosystem into an AI distribution engine. Integration across Android, Search and Google services gives the company a powerful advantage in attracting users.”

*Microsoft Upgrades Its AI Image Generator: In yet another move to compete head-on with the likes of ChatGPT et al, Microsoft has enhanced its AI-powered image generator.

Observes writer Michael Nunez: “The message to enterprise buyers — and, implicitly, to OpenAI — is that Microsoft’s homegrown models are no longer research projects. They are production infrastructure serving millions of users.”

*Deezer Study: More than 50% of Downloaded Music Now AI-Generated: In a stunning revelation on the future of music, more than 50% of music downloads from today’s streaming services are AI-generated.

Observes writer Ivan Mehta: “The rapid rise of AI-generated music has forced streaming services to decide how much of it they want on their own platforms.”

So far, there’s no consensus. Some streamers, like Bandcamp, prohibit AI-generated music, while Apple Music has instituted a voluntary AI-tagging system, according to Mehta.

*New AI App Coaches Employee Conversations: Synthesia is out with a new app that analyzes and responds to employee sales pitches, customer service chops and similar – in real time.

Observes writer Rebecca Bellan: The AI-powered system offers an “AI avatar that talks back, pushes back — and then scores them (employees) against a rubric.”

Dubbed ‘Roleplay,’ the new app is the first release in a series of similar apps that will help employees practice for job interviews and do job candidate screening.

*AI-Generated Journalism Increasingly Attributed to Human Writers: Some publishers concerned that readers might be turned-off by news stories written by AI have come up with a quick solution: Simply attribute AI writing to human journalists.

Observes writer Pete Pachal: “That’s leading to growing pushback from editorial teams, like when reporters at The Sacramento Bee recently objected to having their bylines put on content written primarily by AI.” ‘

Publishers deliberately misleading readers about who – or what – is writing their news stories? What could possibly go wrong?

*China’s Threat to U.S. AI: An In-Depth Look: China’s relentless release of inexpensive, nearly-as-good AI — first popularized in January of 2025 — has U.S. AI titans worried and many consumers thrilled.

This piece by Nathan Lambert – an experienced AI scientist – offers a thorough look at what’s happening, what could happen – and what the stakes are.

Observes Lambert: “In many ways, it feels like the start of a new era: An era with much more competition — but also a much higher need for coordination, as we rollout incredibly powerful technologies around the world.”

Share a Link:  Please consider sharing a link to https://RobotWritersAI.com from your blog, social media post, publication or emails. More links leading to RobotWritersAI.com helps everyone interested in AI-generated writing.

Joe Dysart is editor of RobotWritersAI.com and a tech journalist with 20+ years experience. His work has appeared in 150+ publications, including The New York Times and the Financial Times of London.

Never Miss An Issue
Join our newsletter to be instantly updated when the latest issue of Robot Writers AI publishes
We respect your privacy. Unsubscribe at any time -- we abhor spam as much as you do.

The post Experimental AI Escapes Onto Internet appeared first on Robot Writers AI.

Page 11 of 66
1 9 10 11 12 13 66