AI-powered personas are becoming so realistic that they can infiltrate online communities and subtly steer public opinion. Unlike traditional bots, they adapt, coordinate, and refine their messaging at a massive scale, creating a false sense of consensus. Early warning signs—like deepfakes and fake news networks—have already appeared in global elections. Researchers warn that the next election could be the true test of this technology’s power.
The 5 Things It Does That Your Team Doesn’t Have Time For
The question we get most often in the first conversation with a supply chainleader is not ‘can AI do this?’ It is ‘what exactly does it do, and what does it replace?’
That is the right question. And the answer is specific.
A supply chain analyst agent does not replace supply chain judgment. It replaces the manual work that happens before the judgment. The reconciling, the assembling, the waiting-for-the-report work that consumes hours every week and still produces outputs that are already stale by the time anyone reads them.
USM Business Systems builds supply chain analyst agents for mid-market manufacturing, distribution, and logistics companies. Here is what those agents actually do.
1. Continuous Data Reconciliation
Most supply chain teams reconcile data manually. Lead times from supplier confirmations. Inventory positions from the WMS. Demand signals from the order management system. Purchase order status from the ERP. All of it coming in at different cadences, in different formats, from different systems.
The agent handles all of that continuously. Lead times update when supplier confirmations come in. Inventory positions update as transactions process. Demand signals update as orders come through. The team opens the dashboard and the picture is current.
Time recovered: 4-10 hours per analyst per week
Decision quality improvement: leadership briefs off data that is hours old, not days old
2. Automated Exception Surfacing
The most expensive supply chain problems are the ones nobody noticed until they became commitments. A supplier whose lead times have been drifting for three weeks. Inventory coverage that is thinning on a high-velocity SKU. A demand pattern that has shifted since the last forecast cycle.
The agent monitors the operation continuously and surfaces exceptions automatically. It does not wait for the weekly review. It flags the situation when the threshold is crossed.
Near-miss visibility window extends from hours before a problem to days before
The team shifts from reactive response to proactive resolution
3. Root Cause Analysis on Demand
When a supply chain problem does occur, the investigation typically takes longer than the resolution. Where did the breakdown start? Which supplier? Which lane? Which upstream signal was the leading indicator?
The agent traces disruptions backward through the data and presents the cause with supporting evidence. The supply chain leader does not spend Monday morning running the investigation. They receive the analysis and move to the response.
Mean time to root cause: reduced from days to hours
For manufacturers where downtime runs $10K-$50K per hour, this is direct margin protection
4. Plain-Language Scenario Modeling
Supply chain decisions under uncertainty require modeling. What happens to coverage if Supplier A delays by three weeks? What does re-sourcing to Supplier B do to landed cost and lead time? What is the inventory exposure if demand holds at the current pace through Q3?
Historically, running those scenarios required an analyst, a spreadsheet, and time that is usually not available before the decision needs to be made.
The agent accepts plain-language questions and returns modeled answers. The procurement leader or ops director asks the question and gets the output in minutes. The decision is made with the modeling, not in spite of the absence of it.
5. Automated Reporting and Narrative Generation
Weekly ops reviews, supplier scorecards, and executive summaries do not disappear when a supply chain agent is deployed. What changes is who builds them.
The agent generates those reports automatically, from the live data it is already reconciling. The narrative is written. The tables are populated. The anomalies are flagged.
The supply chain team does not spend Thursday building Friday’s report. Reporting becomes a byproduct of operations, not a project with a deadline.
4-8 senior team hours recovered per week on report assembly
Version control and manual error risk eliminated
The teams that get the most out of supply chain AI are not the ones with the biggest budgets. They are the ones who identified one specific problem and ran a contained build on it first.
What the First Deployment Looks Like?
USM scopes every supply chain agent engagement in two weeks. We identify the one or two problems with the clearest ROI and the fastest measurement cycle. We build to that scope. We measure from week one.
Most first deployments are live within 8-12 weeks. The team starts using the output before the quarter is out.
Request a 30-minute Supply Chain Agent walkthrough at usmsystems.com. See the live system, not the slide deck.
GRASP is a new gradient-based planner for learned dynamics (a “world model”) that makes long-horizon planning practical by (1) lifting the trajectory into virtual states so optimization is parallel across time, (2) adding stochasticity directly to the state iterates for exploration, and (3) reshaping gradients so actions get clean signals while we avoid brittle “state-input” gradients through high-dimensional vision models.
Large, learned world models are becoming increasingly capable. They can predict long sequences of future observations in high-dimensional visual spaces and generalize across tasks in ways that were difficult to imagine a few years ago. As these models scale, they start to look less like task-specific predictors and more like general-purpose simulators.
But having a powerful predictive model is not the same as being able to use it effectively for control/learning/planning. In practice, long-horizon planning with modern world models remains fragile: optimization becomes ill-conditioned, non-greedy structure creates bad local minima, and high-dimensional latent spaces introduce subtle failure modes.
In this blog post, I describe the problems that motivated this project and our approach to address them: why planning with modern world models can be surprisingly fragile, why long horizons are the real stress test, and what we changed to make gradient-based planning much more robust.
This blog post discusses work done with Mike Rabbat, Aditi Krishnapriyan, Yann LeCun, and Amir Bar (* denotes equal advisorship), where we propose GRASP.
What is a world model?
These days, the term “world model” is quite overloaded, and depending on the context can either mean an explicit dynamics model or some implicit, reliable internal state that a generative model relies on (e.g. when an LLM generates chess moves, whether there is some internal representation of the board). We give our loose working definition below.
Suppose you take actions and observe states (images, latent vectors, proprioception). A world model is a learned model that, given the current state and a sequence of future actions, predicts what will happen next. Formally, it defines a predictive distribution on a sequence of observed states and current action :
that approximates the environment’s true conditional . For this blog post, we’ll assume a Markovian model for simplicity (all results here can be extended to the more general case), and when the model is deterministic it reduces to a map over states:
In practice the state is often a learned latent representation (e.g., encoded from pixels), so the model operates in a (theoretically) compact, differentiable space. The key point is that a world model gives you a differentiable simulator; you can roll it forward under hypothetical action sequences and backpropagate through the predictions.
Planning: choosing actions by optimizing through the model
Given a start and a goal , the simplest planner chooses an action sequence by rolling out the model and minimizing terminal error:
Here we use as shorthand for the full rollout through the world model (dependence on model parameters is implicit):
In short horizons and low-dimensional systems, this can work reasonably well. But as horizons grow and models become larger and more expressive, its weaknesses become amplified.
So why doesn’t this just work at scale?
Why long-horizon planning is hard (even when everything is differentiable)
There are two separate pain points for the more general world model, plus a third that is specific to learned, deep learning-based models.
Those familiar with backprop through time (BPTT) may notice that we’re differentiating through a model applied to itself repeatedly, which will lead to the exploding/vanishing gradients problem. Namely, if we take derivatives (note we’re differentiating vector-valued functions, resulting in Jacobians that we denote with ) with respect to earlier actions (e.g. ):
We see that the Jacobian’s conditioning scales exponentially with time :
leading to exploding or vanishing gradients.
2) The landscape is non-greedy and full of traps
At short horizons, the greedy solution, where we move straight toward the goal at every step, is often good enough. If you only need to plan a few steps ahead, the optimal trajectory usually doesn’t deviate much from “head toward ” at each step.
As horizons grow, two things happen. First, longer tasks are more likely to require non-greedy behavior: going around a wall, repositioning before pushing, backing up to take a better path. And as horizons grow, more of these non-greedy steps are typically needed. Second, the optimization space itself scales with horizon: , further expanding the space of local minima for the optimization problem.
Distance to goal along the optimal path is non-monotonic, and the resulting loss landscape can be rough.
A long-horizon fix: lifting the dynamics constraint
Suppose we treat the dynamics constraint as a soft constraint, and we instead optimize the following penalty function over both actions and states :
This is also sometimes called collocation in planning/robotics literature. Note the lifted formulation shares the same global minimizers as the original rollout objective (both are zero exactly when the trajectory is dynamically feasible). But the optimization landscapes are very different, and we get two immediate benefits:
Each world model evaluation depends only on local variables, so all terms can be computed in parallel across time, resulting in a huge speed-up for longer horizons, and
You no longer backpropagate through a single deep -step composition to get a learning signal, since the previous product of Jacobians now splits into a sum, e.g.:
Being able to optimize states directly also helps with exploration, as we can temporarily navigate through unphysical domains to find the optimal plan:
Collocation-based planning allows us to directly perturb states and explore midpoints more effectively.
However, lunch is never free. And indeed, especially for deep learning-based world models, there is a critical issue that makes the above optimization quite difficult in practice.
An issue for deep learning-based world models: sensitivity of state-input gradients
The tl;dr of this section is: directly optimizing states through a deep learning-based is incredibly brittle, à la adversarial robustness. Even if you train your world model in a lower-dimensional state space, the training process for the world model makes unseen state landscapes very sharp, whether it be an unseen state itself or simply a normal/orthogonal direction to the data manifold.
Adversarial robustness and the “dimpled manifold” model
Adversarial robustness originally looked at classification models , and showed that by following the gradient of a particular logit from a base image (not of class ), you did not have to move far along to make classify as (Szegedy et al., 2014; Goodfellow et al., 2015):
Depiction of the classic example from (Goodfellow et al., 2015).
Later work has painted a geometric picture for what’s going on: for data near a low-dimensional manifold , the training process controls behavior in tangential directions, but does not regularize behavior in orthogonal directions, thus leading to sensitive behavior (Stutz et al., 2019). Another way stated: has a reasonable Lipschitz constant when considering only tangential directions to the data manifold , but can have very high Lipschitz constants in normal directions. In fact, it often benefits the model to be sharper in these normal directions, so it can fit more complicated functions more precisely.
As a result, such adversarial examples are incredibly common even for a single given model. Further, this is not just a computer vision phenomenon; adversarial examples also appear in LLMs (Wallace et al., 2019) and in RL (Gleave et al., 2019).
While there are methods to train for more adversarially robust models, there is a known trade-off between model performance and adversarial robustness (Tsipras et al., 2019): especially in the presence of many weakly-correlated variables, the model must be sharper to achieve higher performance. Indeed, most modern training algorithms, whether in computer vision or LLMs, do not train adversarial robustness out. Thus, at least until deep learning sees a major regime change, this is a problem we’re stuck with.
Why is adversarial robustness an issue for world model planning?
Consider a single component of the dynamics loss we’re optimizing in the lifted state approach:
Let’s further focus on just the base state:
Since world models are typically trained on state/action trajectories , the state-data manifold for has dimensionality bounded by the action space:
where is some optional space of augmentations (e.g. translations/rotations). Thus, we can typically expect to be much lower than , and thus: it is very easy to find adversarial examples that hack any state to any other desired state.
As a result, the dynamics optimization
feels incredibly “sticky,” as the base points can easily trick into thinking it’s already made its local goal.1
1. This adversarial robustness issue, while particularly bad for lifted-state approaches, is not unique to them. Even for serial optimization methods that optimize through the full rollout map , it is possible to get into unseen states, where it is very easy to have a normal component fed into the sensitive normal components of . The action Jacobian’s chain rule expansion is
See what happens if any stage of the product has any component normal to the data manifold.
Our fix
This is where our new planner GRASP comes in. The main observation: while is untrustworthy and adversarial, the action space is usually low-dimensional and exhaustively trained, so is actually reasonable to optimize through and doesn’t suffer from the adversarial robustness issue!
The action input is usually lower-dimensional and densely trained (the model has seen every action direction), so action gradients are much better behaved.
At its core, GRASP builds a first-order lifted state / collocation-based planner that is only dependent on action Jacobians through the world model. We thus exploit the differentiability of learned world models , while not falling victim to the inherent sensitivity of the state Jacobians .
GRASP: Gradient RelAxedStochastic Planner
As noted before, we start with the collocation planning objective, where we lift the states and relax dynamics into a penalty:
We then make two key additions.
Ingredient 1: Exploration by noising the state iterates
Even with a smoother objective, planning is nonconvex. We introduce exploration by injecting Gaussian noise into the virtual state updates during optimization.
A simple version:
Actions are still updated by non-stochastic descent:
The state noise helps you “hop” between basins in the lifted space, while the actions remain guided by gradients. We found that specifically noising states here (as opposed to actions) finds a good balance of exploration and the ability to find sharper minima.2
2. Because we only noise the states (and not the actions), the corresponding dynamics are not truly Langevin dynamics.
As discussed, the fragile pathway is the gradient that flows into the state input of the world model, . The most straightforward way to do this initially is to just stop state gradients into directly:
Let be the same value as , but with gradients stopped.
Define the stop-gradient dynamics loss:
This alone does not work. Notice now states only follow the previous state’s step, without anything forcing the base states to chase the next ones. As a result, there are trivial minima for just stopping at the origin, then only for the final action trying to get to the goal in one step.
Dense goal shaping
We can view the above issue as the goal’s signal being cut off entirely from previous states. One way to fix this is to simply add a dense goal term throughout prediction:
In normal settings this would over-bias towards the greedy solution of straight chasing the goal, but this is balanced in our setting by the stop-gradient dynamics loss’s bias towards feasible dynamics. The final objective is then as follows:
The result is a planning optimization objective that does not have dependence on state gradients.
Periodic “sync”: briefly return to true rollout gradients
The lifted stop-gradient objective is great for fast, guided exploration, but it’s still an approximation of the original serial rollout objective.
So every iterations, GRASP does a short refinement phase:
Roll out from using current actions , and take a few small gradient steps on the original serial loss:
The lifted-state optimization still provides the core of the optimization, while this refinement step adds some assistance to keep states and actions grounded towards real trajectories. This refinement step can of course be replaced with a serial planner of your choice (e.g. CEM); the core idea is to still get some of the benefit of the full-path synchronization of serial planners, while still mostly using the benefits of the lifted-state planning.
How GRASP addresses long-range planning
Collocation-based planners offer a natural fix for long-horizon planning, but this optimization is quite difficult through modern world models due to adversarial robustness issues. GRASP proposes a simple solution for a smoother collocation-based planner, alongside stable stochasticity for exploration. As a result, longer-horizon planning ends up not only succeeding more, but also finding such successes faster:
Push-T demo: longer-horizon planning with GRASP.
Horizon
CEM
GD
LatCo
GRASP
H=40
61.4% / 35.3s
51.0% / 18.0s
15.0% / 598.0s
59.0% / 8.5s
H=50
30.2% / 96.2s
37.6% / 76.3s
4.2% / 1114.7s
43.4% / 15.2s
H=60
7.2% / 83.1s
16.4% / 146.5s
2.0% / 231.5s
26.2% / 49.1s
H=70
7.8% / 156.1s
12.0% / 103.1s
0.0% / —
16.0% / 79.9s
H=80
2.8% / 132.2s
6.4% / 161.3s
0.0% / —
10.4% / 58.9s
Push-T results. Success rate (%) / median time to success. Bold = best in row. Note the median success time will bias higher with higher success rate; GRASP manages to be faster despite higher success rate.
What’s next?
There is still plenty of work to be done for modern world model planners. We want to exploit the gradient structure of learned world models, and collocation (lifted-state optimization) is a natural approach for long-horizon planning, but it’s crucial to understand typical gradient structure here: smooth and informative action gradients and brittle state gradients. We view GRASP as an initial iteration for such planners.
Extension to diffusion-based world models (deeper latent timesteps can be viewed as smoothed versions of the world model itself), more sophisticated optimizers and noising strategies, and integrating GRASP into either a closed-loop system or RL policy learning for adaptive long-horizon planning are all natural and interesting next steps.
I do genuinely think it’s an exciting time to be working on world model planners. It’s a funny sweet spot where the background literature (planning and control overall) is incredibly mature and well-developed, but the current setting (pure planning optimization over modern, large-scale world models) is still heavily underexplored. But, once we figure out all the right ideas, world model planners will likely become as commonplace as RL.
@article{psenka2026grasp,title={Parallel Stochastic Gradient-Based Planning for World Models},author={Michael Psenka and Michael Rabbat and Aditi Krishnapriyan and Yann LeCun and Amir Bar},year={2026},eprint={2602.00475},archivePrefix={arXiv},primaryClass={cs.LG},url={https://arxiv.org/abs/2602.00475}}
This article was initially published on the BAIR blog, and appears here with the authors’ permission.
Observes writer Taryn Plumb: “AI agents are now embedded in real enterprise workflows, and they’re still failing roughly one in three attempts on structured benchmarks.”
That reality is documented in the latest study on AI from Stanford: The 2026 AI Index Report.
The handy new feature is part of a new ‘Skills’ update rolled out in Chrome.
Observes writer Lance Whitney: “With Skills, you can save an AI prompt and then reuse it in the future just by selecting it from a list.
”To reuse a saved prompt in your chat window, just type the forward slash or click the plus button and select the Skill from the menu. That Skill then runs in your new chat.”
Observes writer Reece Rogers: “This update to AI Mode means that once you begin a search using that tool in Chrome, the search tool essentially becomes an always-on aspect of your user experience.”
Essentially, Canva has been redesigned with AI so that any user can build and publish work using everyday natural language commands – rather than clicking on individual tools.
Observes Cliff Obrecht, co-founder, Canva: “Until now, Canva has been a design platform with AI tools.
“Now, we become an AI platform with design tools.”
Creators looking for AI that creates prototypes, slides, wireframes, mockups, pitch decks, marketing content and similar will want to check-out the new tool.
Dubbed ‘Claude Design,’ the new AI is powered by Claude Opus 4.7.
*AI Search Optimization Tool Debuts: LovedByAI has released a new WordPress plugin that promises to auto-optimize the content you publish on your WordPress Web site for discovery by AI search tools.
Observes Jenny Beasley, head of GEO, LovedByAI: “Small businesses should not need a developer, a consultant — and weeks of testing — just to be visible in AI search.
“The goal with LovedByAI is simple: Give SMBs (small-and-medium-sized businesses) a practical way to help AI systems understand their site, without turning this into another complicated project.”
*New AI Writing Tool Released: Editors and writers looking for a new AI writing tool to test-drive may want to check-out TinyMCE AI.
Designed for content creators, the tool offers basic write, refine and review functionality – as well as conversational access, instant text transformation and automated quality checks.
Maker Tiugo Technologies promises the tool is the solution for editors and writers looking for a one-stop fusion of traditional digital writing with modern AI chops.
Anthropic promises that Opus 4.7 is able to handle complex, long-running tasks with rigor and consistency – while paying precise attention to instructions.
Also upgraded with the new version is Opus’ AI vision, which can see images in greater resolution, according to Anthropic.
*ChatGPT’s Latest Makeover: A Karen?: More than a few ChatGPT users are giving the AI the heave-ho after its most recent update began acting like a persnickety, nagging obsessive.
Observes writer Walter Schulze: “Perfectly routine requests are now being refused — or met with unsolicited lectures. The community has already given it a name: the Karen update.”
Even worse: Subscription cancellation rates for OpenAI’s Plus and Team tiers climbed 4% in the 24 hours following the update’s release, according to Schulze.
Share a Link: Please consider sharing a link to https://RobotWritersAI.com from your blog, social media post, publication or emails. More links leading to RobotWritersAI.com helps everyone interested in AI-generated writing.
–Joe Dysart is editor of RobotWritersAI.com and a tech journalist with 20+ years experience. His work has appeared in 150+ publications, including The New York Times and the Financial Times of London.
A humanoid robot that won a half-marathon race for robots in Beijing on Sunday ran faster than the human world record in a show of China's technological leaps.
How Much Does It Cost To Develop A Logistics and Supply Chain Management Application?
Warehouse management and streamlined logistics are core segments of product-based organizations. Starting from production and warehouse shipment to logistics and distribution, every phase needs to be monitored and better managed to ensure business effectiveness.
Unlike traditional manual tracking of logistics operations, organizations across manufacturing and retail are using advanced Artificial Intelligence (AI) based contemporary logistics and supply chain management applications.
Using the capabilities of automation technologies like AI, businesses are streamlining the value chain of logistics and supply-chain operations. Organizations can automatically monitor warehouses, inventories, shipments, and deliveries at the lowest operational costs. On top of all, the next-generation AI-based logistics and supply-chain apps make the entire process transparent and smooth.
Today, through this article, we would like to discuss the benefits of logistics and supply chain management solutions and how much it cost to develop AI-based supply chain management apps for Android/iOS/Windows.
Significant Benefits Of Logistics and Supply-Chain Management Apps
An intelligent, collaborative, and easy-to-use logistics app reshapes the company’s warehouse management and logistics operations. Here are a few top benefits of supply chain management software that you must know if you have plans to develop AI-based logistics and supply-chain applications.
Streamlined Process & Cost Saving
It is one of the top benefits of implementing the logistics management software solution for better-organizing inventory and managing warehouse & distribution operations. Such an automated process will reduce the overall expenses on resources and warehouse maintenance.
Order Processing & Delivery Status Tracking
It is another top benefit of implementing customized AI-based supply-chain management solutions. Innovative AI apps automate client-to-brand interactions and make order processing virtual.
The order management feature of the logistics apps will mainly involve automating the order fulfillment process. Starting from product loading and shipment to temporary storage in a warehouse, order packaging and deliveries to logistics, intelligent supply chain management apps will handle smartly with high accuracy.
Further, order management functionality also plays a key role in properly maintaining inventory databases and order information. This information would be further processed to predict sales opportunities and improve business efficiency.
AI Inventory Management
Here is another significant feature of an enterprise-centric supply-chain management Solution. Using machine learning and deep learning technologies, supply chain management apps with inventory tracking features allow organizations to better organize and manage their inventories as per the market demand. It helps the companies monitor stock levels and always stay on top of the demand.
Geolocation Tracking Of The Fleet or Vehicle Management
Internet-of-Things (IoT) plays a key role in tracking the fleets. Yes, AI, coupled with IoT technology will continuously monitor the live location of the fleet or goods carriers. Hence, by using intelligent supply-chain management solutions, companies can benefit from reliable logistics and deliveries on time.
Besides, by connecting multiple IoT sensors to the vehicle, organizations can monitor the fuel levels, and tire pressure, and get notifications on overall carrier performance reporting instantly. It will help companies to improve vehicle performance and ensure reliable deliveries to the distribution centers on scheduled time.
Scheduling Goods Delivery
Implementation of AI-based logistics and supply chain management solutions will help manufacturing and retail companies automatically process purchase orders from clients and schedule goods delivery rights from the app. It will help the logistics department to access the delivery information from anywhere at any time.
Orders History Management
By adopting supply chain and logistics management applications, organizations can completely reduce the burden of paperwork. Every order will be automatically stored in the application. Hence, using AI-based supply-chain management applications, businesses can maintain clean data records of order details and make accounting and auditing processes smooth.
Risk Analysis and Management
Risk analysis is one of the core and must-have functionality of a logistics application. The logistics software solutions can predict the risks by determining the data received from the IoT sensors located in the different parts of the fleet. For instance, suppliers will get instant notifications about freight accidents if any, and helps in taking immediate actions with no delay.
Centralize Customer Support Functions
By integrating AI-based customer support chatbots or virtual assistants in supply-chain management apps, businesses can seamlessly interact with clients and resolve their issues in order taking, deliveries, or any other service-related concerns.
How Much does Logistics App Development Cost
Logistics app development costs in 2026 typically range from $20,000 to over $600,000 . The final price depends heavily on the complexity of features, the technology stack, and the geographic location of your development team.
Cost Breakdown by App Complexity
The more advanced the functionality—such as AI-driven route optimization or IoT integration—the higher the investment
Basic App (MVP): $20,000 – $30,000
Includes essential features like user registration, simple real-time tracking, and basic delivery scheduling .
Timeline: 3–4 months
Medium Complexity: $30,000 – $40,000
Adds automated scheduling, route optimization, barcode scanning, and multi-user access
Timeline: 5–7 months
Enterprise/Advanced Solution: $40,000 – $80,000+
Features cutting-edge tech like AI for predictive analytics, 5G-ready architecture, and deep integrations with existing ERP/WMS systems
Timeline: 8+ months
Development Stage Estimates
A typical project budget is often distributed across these core phases:
Planning & Discovery: $5,000 – $10,000 (Research and prototypes)
UI/UX Design: $10,000 – $30,000 (Wireframes and user flows)
Core Development: $40,000 – $60,000 (Frontend and backend coding)
Testing & Launch: $10,000 – $15,000 (QA and app store submission)
Conclusion
Intelligent supply chain and logistics management software streamlines the value chain of operations, including warehouse shipping, inventory management, order management, logistics management, and many more. Such an automated process improves business efficiency and optimizes the overall supply-chain operations.
Calling AI things like “smart” or saying it “knows” something might sound harmless, but it can quietly mislead people about what AI actually does. A new study shows that news writers are more careful than expected, rarely using strongly human-like language. When they do, it often falls on a spectrum—sometimes describing simple requirements, other times hinting at human traits.
Engineers at Northwestern University have taken a striking leap toward merging machines with the human brain by printing artificial neurons that can actually communicate with real ones. These flexible, low-cost devices generate lifelike electrical signals capable of activating living brain cells, a breakthrough demonstrated in mouse brain tissue.
Researchers have shown that blending quantum computing with AI can dramatically improve predictions of complex, chaotic systems. By letting a quantum computer identify hidden patterns in data, the AI becomes more accurate and stable over time. The method outperformed standard models while using far less memory. This could have big implications for fields like climate science, energy, and medicine.
Breaking away from conventional robots that perform only predefined functions once fabricated, researchers have developed a next-generation artificial muscle that can change its shape in real time, recover from damage, and even be reused. The study is published in Science Advances.
When it comes to teamwork, we could all learn something from ants. These relatively simple, small-brained animals are famous for their ability to collectively build massive, intricate, climate-controlled structures, despite having neither a blueprint nor a worksite foreman.
Claire chatted to Rich Walker from Shadow Robot Company about their advanced robotic hands for research and industry.
Rich Walker has been at Shadow Robot since long before it was a company, working initially on software and systems engineering before “jumping the fence” into management. He led Shadow Robot’s engagement with a number of R&D initiatives in UK and across Europe, as well as developing proof-of-concept projects for dexterous robotics with a number of commercial organisations. Rich represents robotics SMEs at the European level as one of the Directors of euRobotics, as well as maintaining Shadow Robot’s research engagements and policy programme.


 and observe states
 (images, latent vectors, proprioception). A world model is a learned model that, given the current state and a sequence of future actions, predicts what will happen next. Formally, it defines a predictive distribution on a sequence of observed states
 and current action
 :

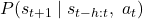 . For this blog post, we’ll assume a Markovian model

 is often a learned latent representation (e.g., encoded from pixels), so the model operates in a (theoretically) compact, differentiable space. The key point is that a world model gives you a differentiable simulator; you can roll it forward under hypothetical action sequences and backpropagate through the predictions.
 and a goal
 , the simplest planner chooses an action sequence
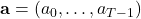 by rolling out the model and minimizing terminal error:

 as shorthand for the full rollout through the world model (dependence on model parameters
 is implicit):

 ) with respect to earlier actions (e.g.
 ):

 :

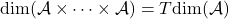 , further expanding the space of local minima for the optimization problem.

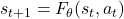 as a soft constraint, and we instead optimize the following penalty function over both actions
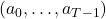 and states
 :

 depends only on local variables, so all

 is incredibly brittle, à la adversarial robustness. Even if you train your world model in a lower-dimensional state space, the training process for the world model makes unseen state landscapes very sharp, whether it be an unseen state itself or simply a normal/orthogonal direction to the data manifold.
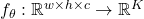 , and showed that by following the gradient of a particular logit
 from a base image
 (not of class
 ), you did not have to move far along
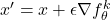 to make
 classify
 as

 , the training process controls behavior in tangential directions, but does not regularize behavior in orthogonal directions, thus leading to sensitive behavior (


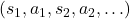 , the state-data manifold for

 is some optional space of augmentations (e.g. translations/rotations). Thus, we can typically expect
 to be much lower than
 , and thus: it is very easy to find adversarial examples that hack any state to any other desired state.


 . The action Jacobian’s chain rule expansion is


 is actually reasonable to optimize through and doesn’t suffer from the adversarial robustness issue!


 be the same value as


 iterations, GRASP does a short refinement phase:
 , and take a few small gradient steps on the original serial loss: