Archive 23.04.2026

Page 37 of 66
1 35 36 37 38 39 66

Supply Chain AI Roadmap for Mid-Market Ops Leaders

From Reactive to Ready: A 90-Day Supply Chain AI Roadmap for Mid-Market Ops Leaders

Most supply chain AI conversations stall in the same place. The ops leader knows the problem. The case for doing something is clear. The question that does not have a clean answer is: what does the first 90 days actually look like?

This is the roadmap USM Business Systems uses with mid-market manufacturing and logistics clients who are moving from interest to implementation. It is designed for organizations that do not have 18 months or a seven-figure platform budget. It is designed for teams that want to start, measure, and expand.

Before You Start: The Three Inputs That Determine Your Roadmap

A 90-day AI roadmap for supply chain is only as good as the three inputs that shape it. Get these clear before any build decision is made.

Input 1: The Problem With the Clearest Cost

Every mid-market supply chain operation has multiple AI opportunities. The teams that move fastest pick one. The one with the most direct and measurable cost attached.

Supplier lead time visibility. Inventory coverage calculation speed. Demand signal latency. Pick the one where someone can tell you what a miss costs in dollars, hours, or margin. That is where you start.

Input 2: Your Current Data Access Points

The roadmap is shaped by what you can connect the agent to. ERP API access. WMS data exports. Supplier EDI feeds. Order management integrations. You do not need all of these to start. You need the ones relevant to the problem you are solving.

A two-week scoping engagement with USM maps your data access reality and builds the agent architecture around what exists, not what would be ideal.

Input 3: The Success Metric

Before build begins, define what success looks like at 90 days. A number. Coverage calculation time reduced from 6 hours to 45 minutes. Near-misses surfaced with 72 hours of lead time instead of 24. Report generation recovered from Thursday manual build to automated Monday delivery.

That metric drives scope. It also drives the conversation about whether to expand.

Days 1-14: Scoping and Architecture

This is not a sales process. It is a working session.

  • Data environment mapping: what systems exist, what APIs are accessible, what exports are available
  • Problem prioritization: identify the one or two problems with the clearest ROI and the fastest measurement cycle
  • Agent architecture design: what the agent will connect to, what it will monitor, what it will surface
  • Success metric definition: specific, measurable, and agreed upon before build begins

At the end of day 14, you have an architecture document, a build scope, a timeline, and a defined metric.

Days 15-60: Build and Integration

The build phase runs in two tracks simultaneously.

Track one is data integration. The agent connects to your existing systems and begins ingesting live data. This phase surfaces the data quality issues that need to be addressed before the agent can produce reliable outputs. Those issues are resolved here, not discovered after go-live.

Track two is agent logic development. The monitoring rules, the exception thresholds, the scenario modeling logic, and the reporting templates are built and tested against real data from your operation.

By day 45, a test version of the agent is running against your data. The supply chain team begins evaluating outputs. Feedback shapes the final configuration before go-live.

Days 61-90: Go-Live and Measurement

Go-live is not a launch event. It is a transition. The agent moves from test to production. The team begins using it as the primary source for the problem it was built to solve.

The measurement cycle starts at day one of production. The success metric defined in scoping is tracked weekly. By the end of day 90, you have six weeks of live data showing the impact on decision time, report generation, near-miss visibility, or whatever metric was set.

That six weeks of measurement data is what drives the conversation about what to build next.

The Expansion Path

The teams that get the most out of supply chain AI do not deploy a platform across the entire operation on day one. They solve one problem, measure it, and expand.

After a successful first deployment, the common expansion paths are:

  • Adding supplier performance monitoring to an inventory visibility agent
  • Expanding from lead time tracking to landed cost scenario modeling
  • Connecting demand signal inputs from a second channel or geography
  • Integrating logistics lane performance data into coverage calculations

Each expansion is scoped and built with the same 8-12 week discipline. The architecture from the first deployment is designed to support expansion from the start.

The supply chain leaders who move fastest on AI do not have bigger budgets or cleaner data than their peers. They pick one problem, run a contained build, and measure it. That is the entire edge.


USM’s POC Commitment

For qualified supply chain and logistics engagements, USM fronts the proof-of-concept cost. You identify the problem. We scope and build the initial deployment. You measure the output before making a larger commitment.

The engagement starts with a scoping conversation. If the architecture is sound and the ROI case is clear, we move to build within two weeks.

Ready to scope your first supply chain AI deployment? Start with a 30-minute conversation at usmsystems.com. No pitch deck. Just the architecture conversation.

[contact-form-7]

This new brain-like chip could slash AI energy use by 70%

A breakthrough in brain-inspired computing could make today’s energy-hungry AI systems far more efficient. Researchers have engineered a new nanoelectronic device using a modified form of hafnium oxide that mimics how neurons process and store information at the same time. Unlike conventional chips that waste energy moving data back and forth, this device operates with ultra-low power—potentially slashing energy use by up to 70%.

AI-powered table tennis robot now challenges human pros and hints at faster, more adaptive machines

A paddle-wielding robot is so adept at playing table tennis that it is posing a tough challenge to elite human players and sometimes defeating them, according to a new study that shows how advances in artificial intelligence are making robots more agile.

Sony AI table tennis robot outplays elite human players

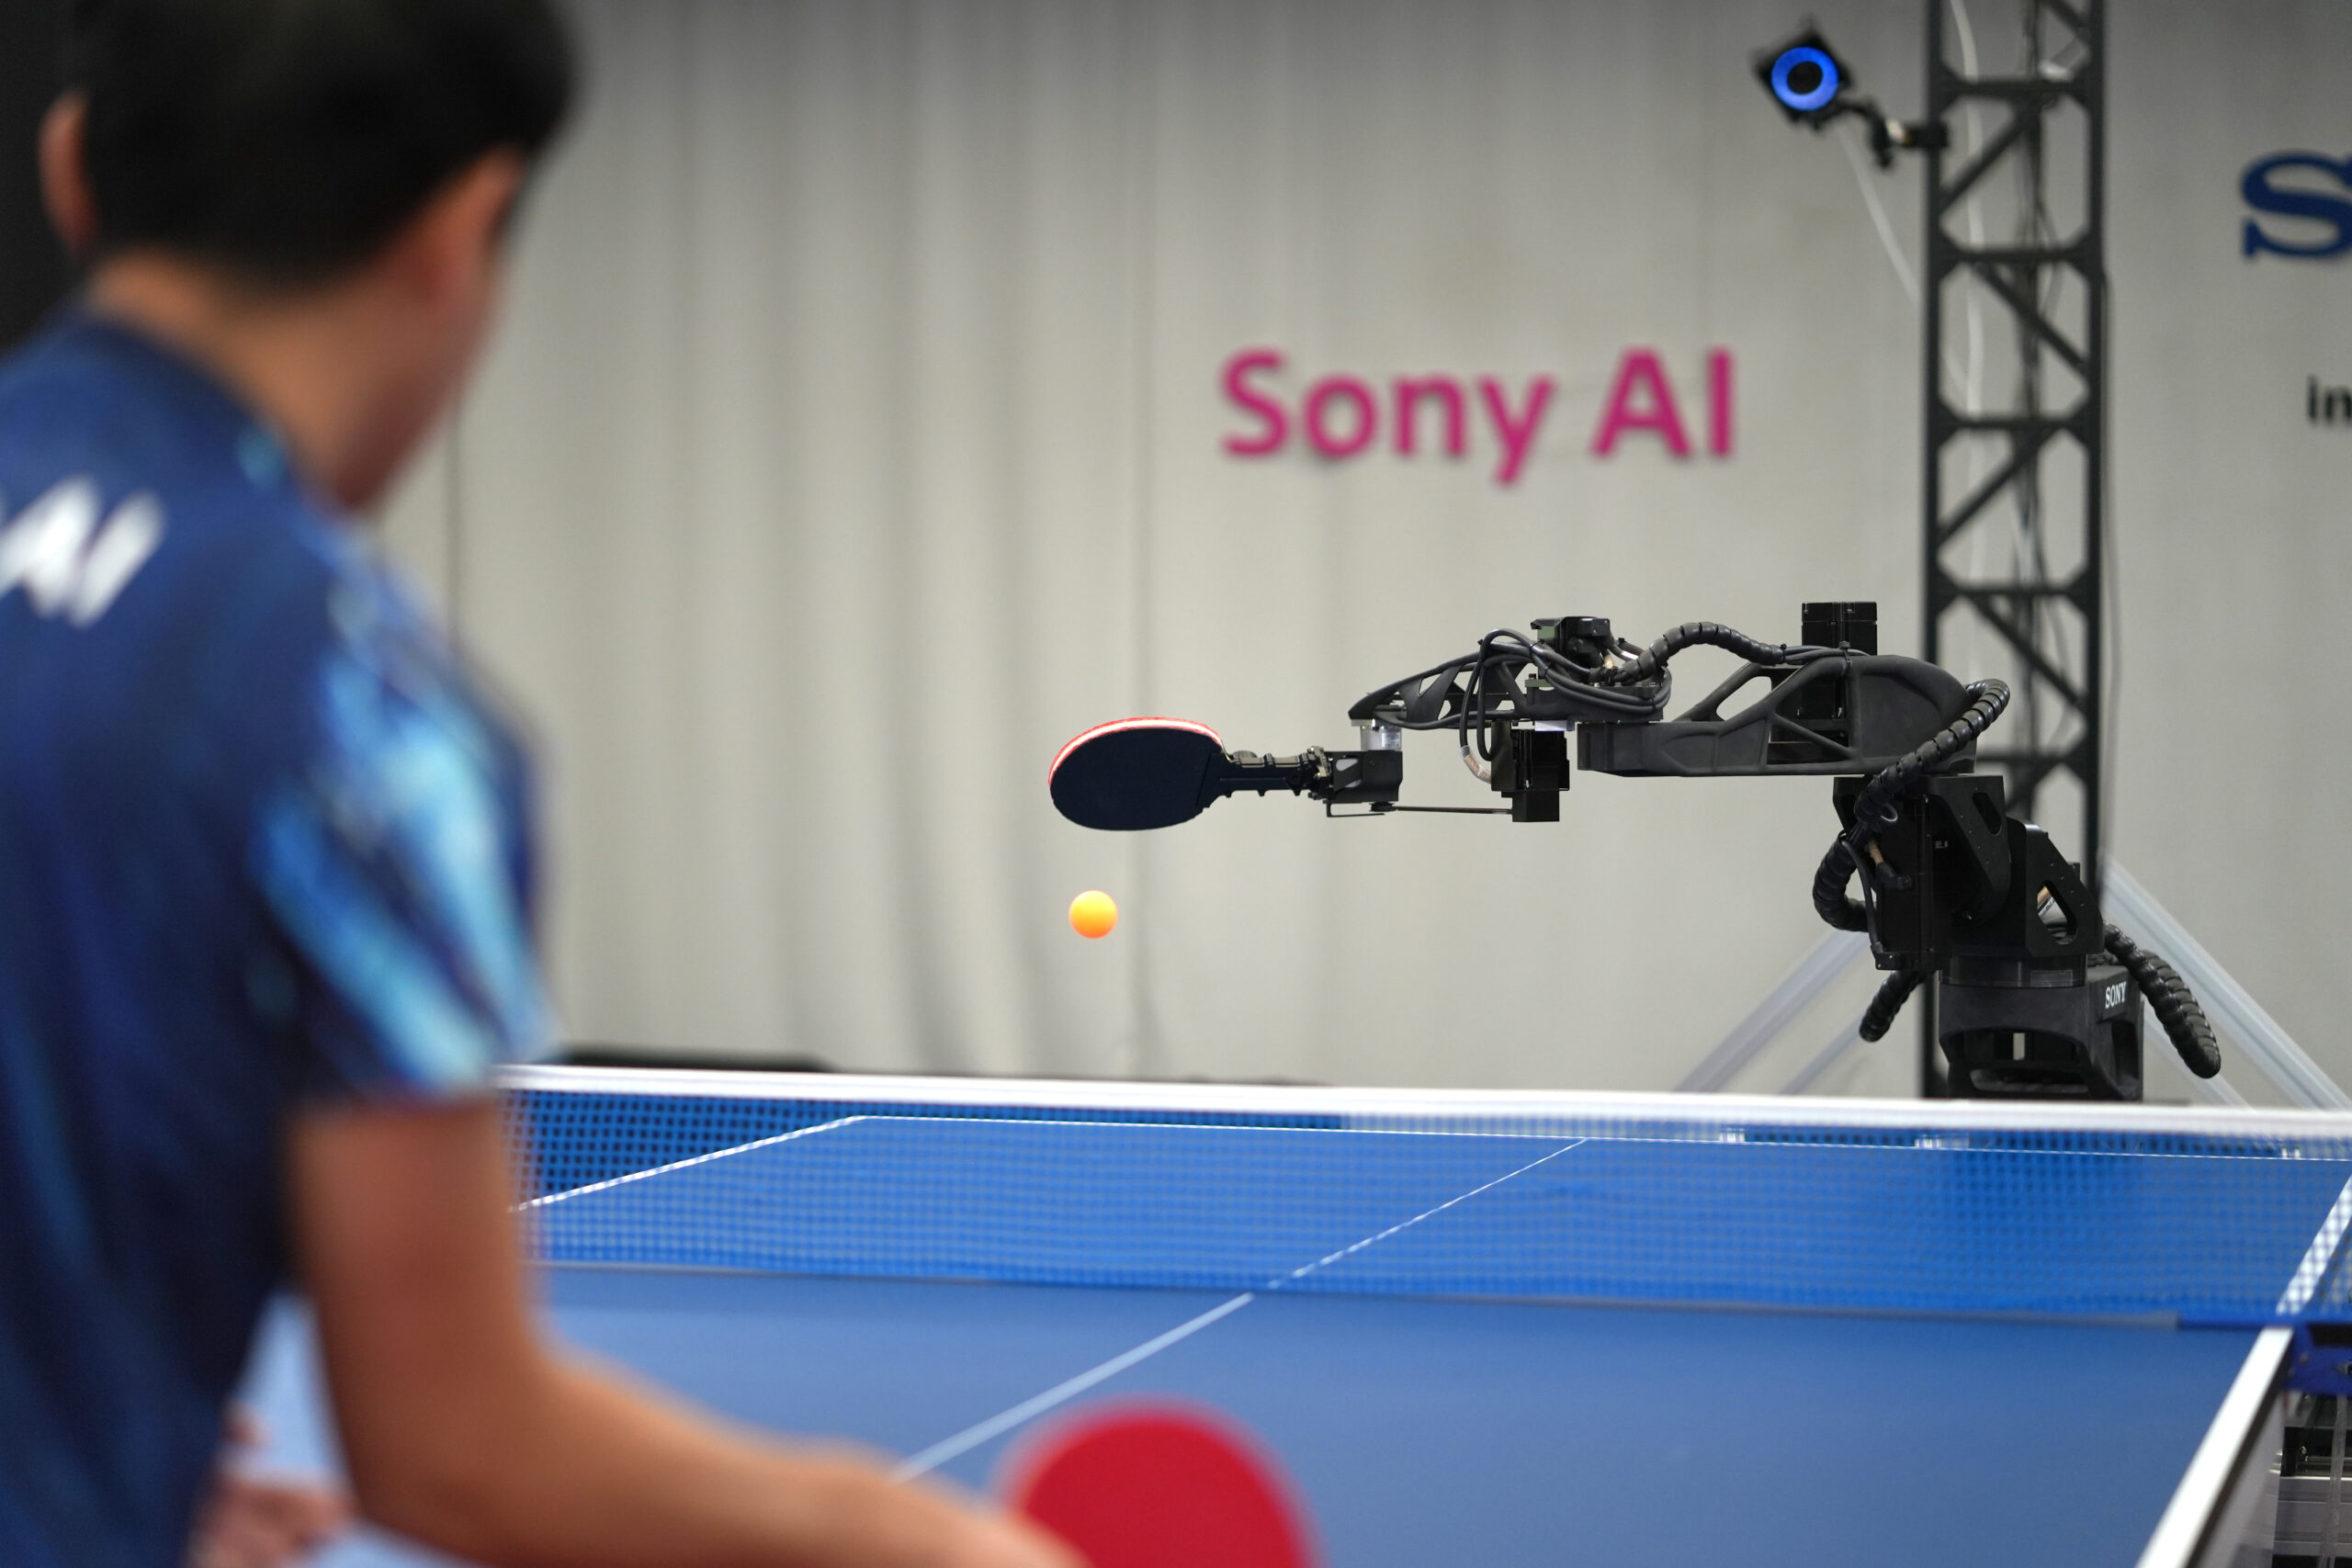
Ace rotates its paddle as it prepares to return the ball back to its human opponent, Yamato Kawamata, during a match in December 2025. Credit: Sony AI.

In an article published today in Nature, Sony AI introduce Ace, the first robot to beat elite human players in competitive physical sport.

Although AI systems have shown advanced performance in digital domains and board games (such as complex video games, chess and Go), translating this to physical performance has remained a significant challenge. Such a feat requires perception, planning, and control to work in a high-speed domain on the scale of milliseconds. Table tennis is a demanding and complex real-world test for robotics, requiring rapid decision-making, precise physical execution, and continuous adaptation to an unpredictable opponent. The ball’s high speed, spin, and complex trajectories are central to competitive play.

Director of Sony AI in Zürich, and project lead for Ace, Peter Dürr said “this research has shown that an autonomous robot can, in fact, win at a competitive sport, matching or exceeding the reaction time and decision making of humans in a physical space. Table tennis is a game of enormous complexity that requires split-second decisions as well as speed and power. This research breakthrough highlights the potential of physical AI agents to perform real-time interactive tasks, and represents a significant step toward creating robots with broader applications in fast, precise, and real-time human interactions.”

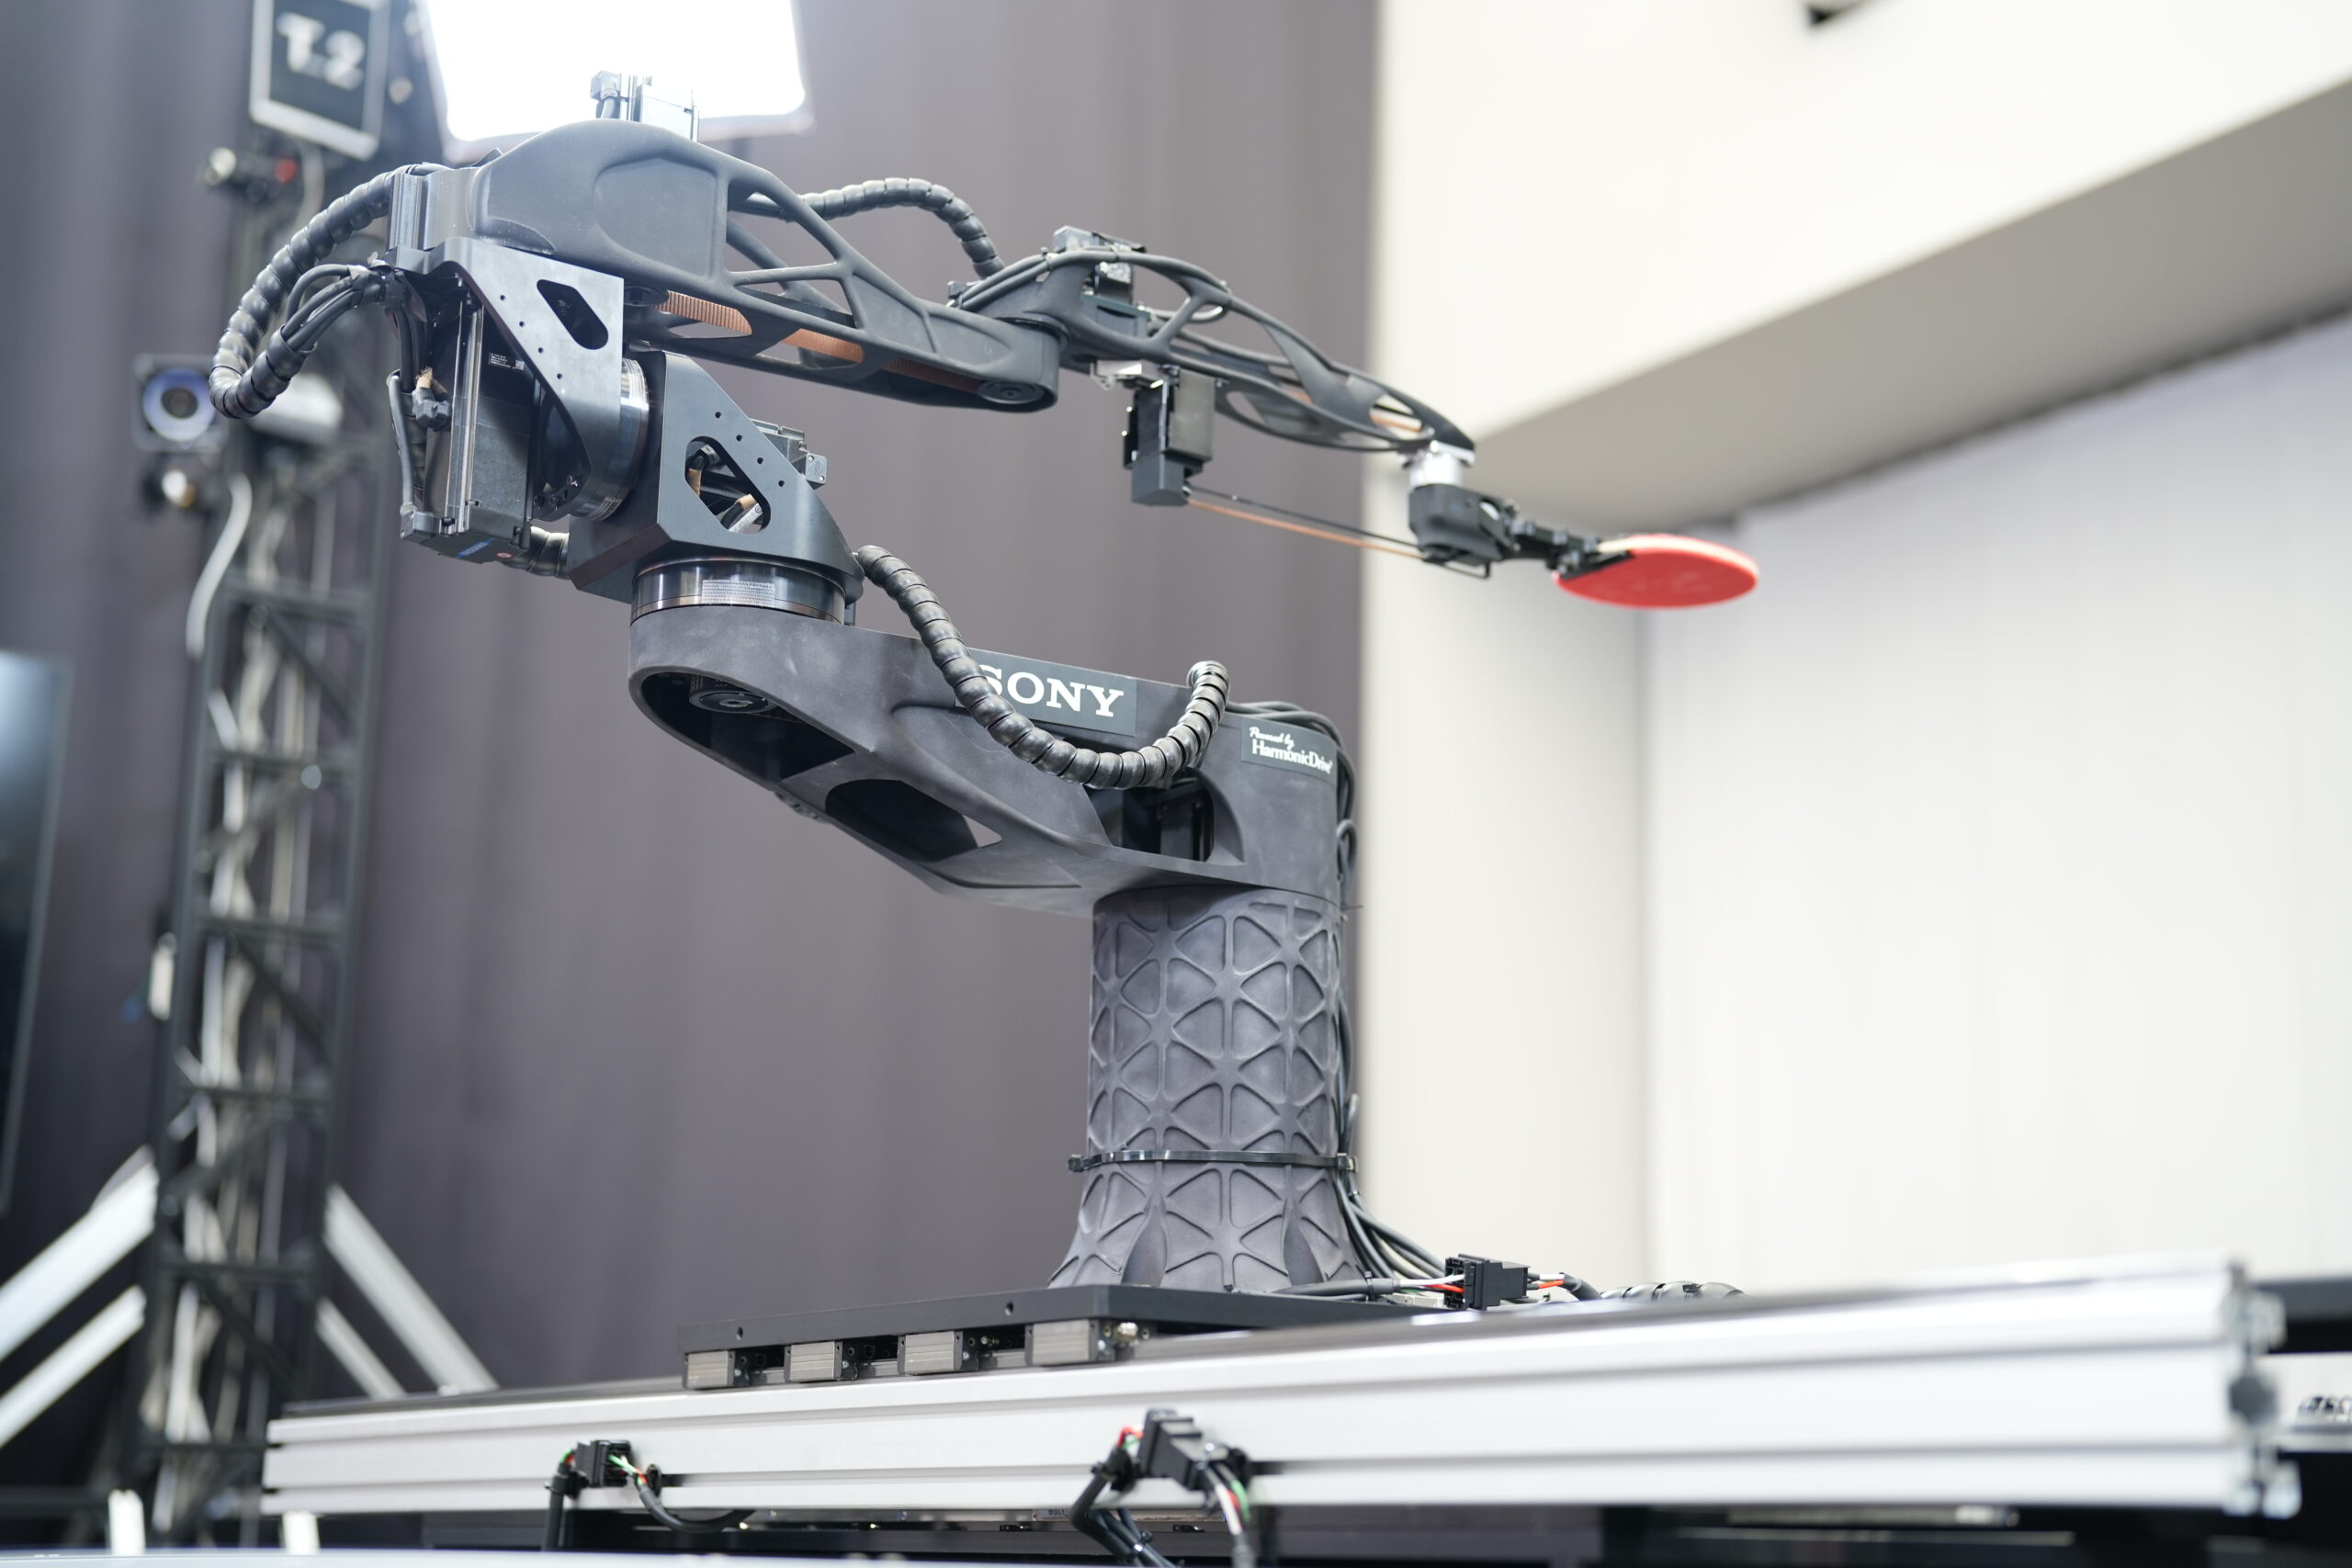
A complete view of table tennis robot, Ace, including arm and track. Credit: Sony AI.

What new components does Ace incorporate?

Ace combines event-based vision sensors and a control system based on model-free reinforcement learning, as well as state-of-the-art high-speed robot hardware. Ace was designed with three novel components:

  • A high speed perception system composed of nine active pixel sensor cameras to determine the ball’s precise 3D position, combined with three gaze control systems that use event-based vision sensor cameras, pan/tilt mirrors, and telephoto tunable lens to measure the ball’s angular velocity and spin in real time.
  • A novel control system based on model-free reinforcement learning to enable rapid adaptation and decision-making without reliance on pre-programmed models.
  • High-speed robotic hardware capable of executing precise, high-speed control for agile physical interaction.

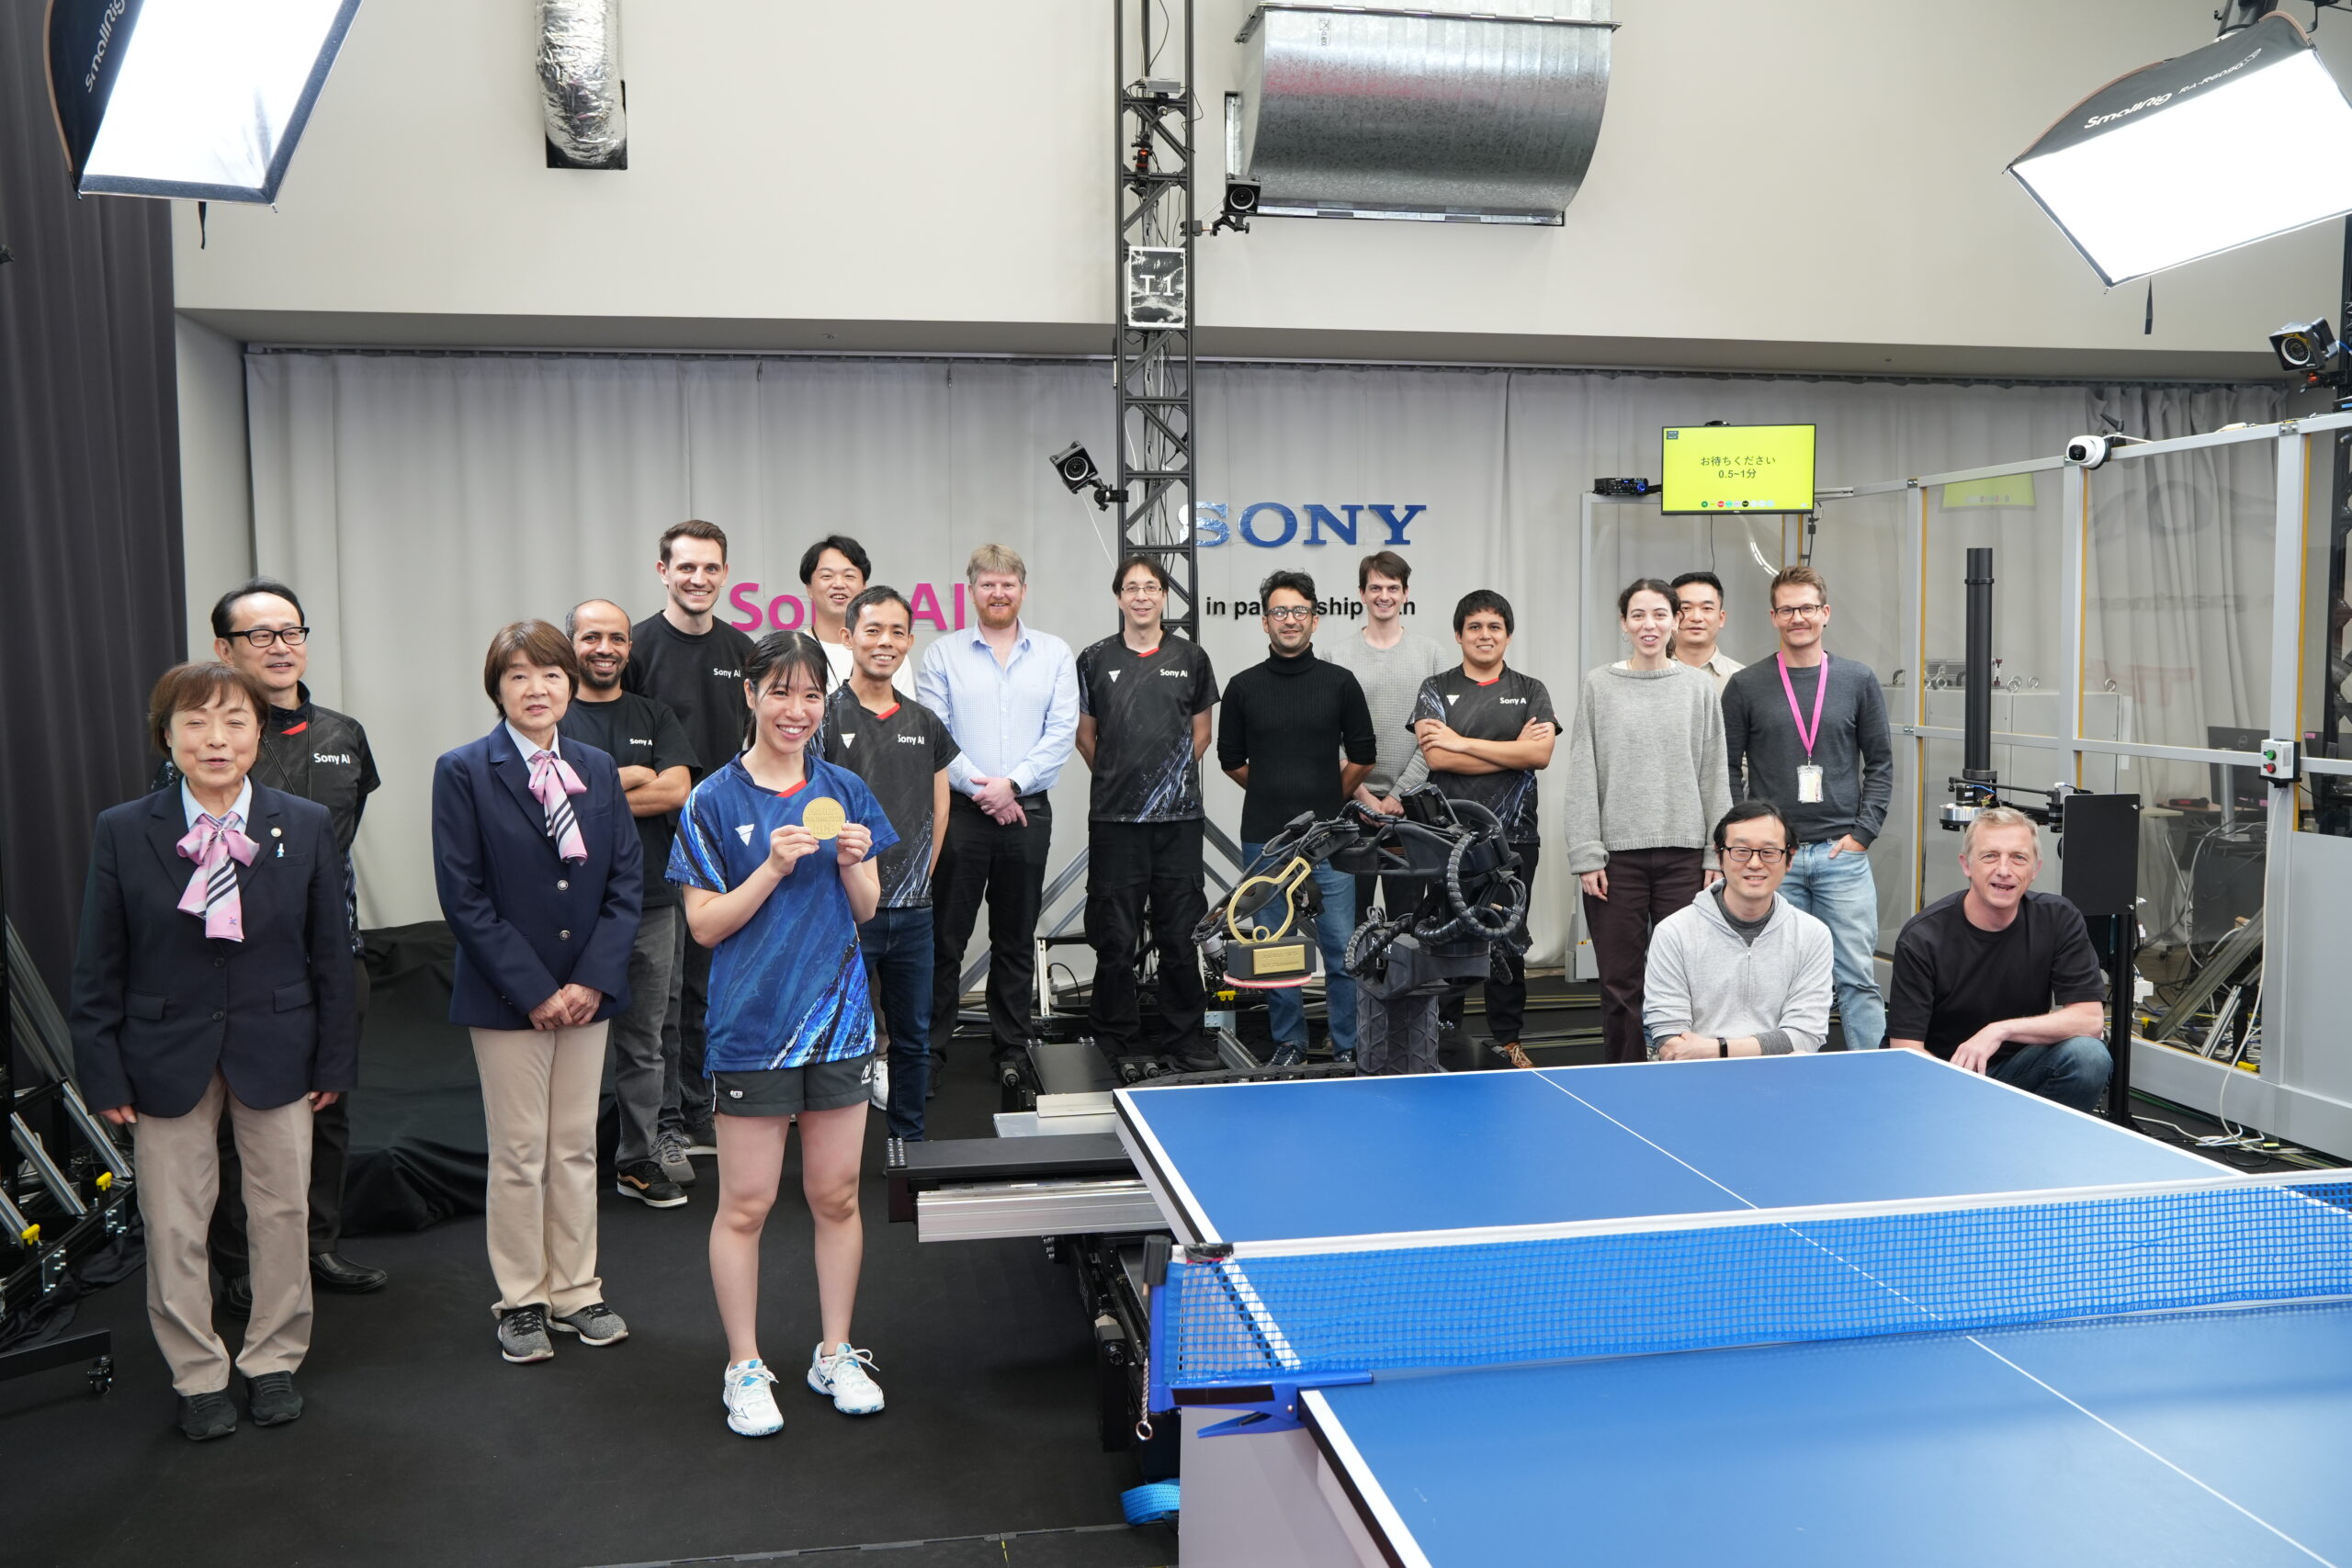
Members of the Ace research team and table tennis officials pose with the robot and its human opponent, Mayuka Taira, following an official match in December 2025.

From Figure 4 in the Nature manuscript “Outplaying elite table tennis players with an autonomous robot” this film shows the robot making a split section change to its trajectory when the ball hits the net. Credit: Sony AI and Nature.

Testing Ace against elite players

For the results reported in the Nature publication, Ace was evaluated in matches against five elite players and two professional table tennis players, under International Table Tennis Federation (ITTF) regulations. Ace achieved three victories in five matches against the elite players, along with competitive performances in the remaining matches.

There were some interesting results from the evaluations, including the fact that Ace was able to return a wide range of spins, consistently achieving over 75% return rate up to spins of 450 rad/s. The control systems behind Ace also allowed for quick reaction to unusual shots, such as balls bouncing off the net. This behavior illustrates the ability of the approach to generalize to situations that are both rare and hard to model in simulation.

Following submission of the Nature manuscript, the team conducted additional competitive matches in December 2025 and March 2026, beating professional players in the process. Compared with earlier evaluations, Ace demonstrated higher shot speeds, more aggressive placement closer to the table edge, and faster-paced rallies, reflecting continued performance gains under competitive conditions.

Find out more about the project in this video from Sony AI.

Your AI agents will run everywhere. Is your architecture ready for that? 

You bet on a hyperscaler to power your AI ambitions. One provider, one ecosystem, one set of tools. What nobody said out loud is that you just walked into a walled garden.

The walls are the point. AWS, GCP, and Azure can all be connected to other environments, but none of them is built to serve as a neutral control layer across the rest. And none of them extends that control cleanly across your on-premise systems, edge environments, and business applications by default.

So most enterprises end up with one of two bad options: consolidate more of the stack into one cloud and accept the lock-in, or hand-build brittle integrations across environments and accept the operational risk.

This isn’t about where your AI platform runs. It’s about where your agents execute, and whether your architecture can govern them consistently everywhere they do. 

Agents don’t stay inside walls. They need to operate across business applications, clouds, on-premise systems, and edge environments, consistently, securely, and under unified governance. No single hyperscaler is designed to provide that across a heterogeneous enterprise estate. And while patchwork integrations can bridge the gaps temporarily, they rarely provide the consistency, control, or durability that enterprise-scale agent deployment requires.

Key takeaways

  • Agentic AI requires infrastructure-agnostic deployment so agents can run consistently across cloud, on-premise, and edge environments.
  • Every major cloud provider operates as a walled garden. Without a vendor-neutral control plane, multi-cloud agentic AI becomes far harder to govern, scale, and keep consistent across environments.
  • Governance must follow the agent everywhere, ensuring consistent security, lineage, and behavior across every environment it touches.
  • Infrastructure-agnostic deployment is a strategic cost lever, enabling smarter workload placement, avoiding vendor lock-in, and improving performance. 
  • Build-once, deploy-anywhere execution is achievable today, but only with a platform that separates governance from compute and orchestrates across all environments.

The hybrid and multi-cloud trap most enterprises are already in 

Most enterprise AI workloads don’t live in one place. They’re scattered across business applications, multiple clouds, on-premise systems, and edge environments. That distribution looks like flexibility. In practice, it’s fragmentation.

Each environment runs its own security model, configuration logic, and identity controls. What enterprises usually lack is a native, cross-environment way to coordinate those differences under one operating model. So they end up making one of two bad choices.

  1. Consolidation: Move everything into one cloud, accept the data gravity, navigate the sovereignty constraints, and pay for the migrations. And once you’re all in, you’re all in. Switching costs make the lock-in permanent in everything but name.
  2. Integration: Hand-build the connectors, the IAM mappings, the data pipelines, and the monitoring hooks across every environment. This works until it doesn’t. Policies drift. Tools fall out of sync. 

When an agent calls a tool in one environment using assumptions baked in from another, behavior becomes unpredictable and failures are hard to trace. Security gaps appear not because anyone made a bad decision, but because no one had visibility across the whole system.

Without a coordination layer above all environments, tracking assets, enforcing governance, and monitoring performance consistently become fragmented and hard to sustain. For traditional AI workloads, that’s already a serious problem. For agentic AI, it becomes a critical failure point.

Agentic AI doesn’t just expose your infrastructure gaps. It amplifies them

Traditional AI workloads are relatively forgiving of infrastructure fragmentation. A model running in one cloud, returning predictions to one application, can tolerate some environmental inconsistency. Agents can’t.

Agentic AI systems make decisions, trigger actions, and execute multi-step workflows autonomously. They call tools, query data, and interact with business applications across whatever environments those resources live in. 

That means infrastructure inconsistency doesn’t just create operational friction. It changes the conditions under which agents reason, call tools, and execute workflows, which can lead to inconsistent behavior across environments.

To operate safely and reliably, agents require consistency across five dimensions:

  • Consistent reasoning behavior. Agents plan and make decisions based on context. When the tools, data, or APIs available to an agent change between environments, its reasoning changes too — producing different outputs for the same inputs. At enterprise scale, that inconsistency is ungovernable.
  • Consistent tool access. Agents need to call the same APIs and reach the same resources regardless of where they’re running. Environment-specific rewrites don’t scale and introduce failure points that are difficult to detect and nearly impossible to audit.
  • Consistent governance and lineage. Every decision, data interaction, and action an agent takes must be tracked, logged, and compliant — across all environments, not just the ones your security team can see.
  • Consistent performance. Latency and throughput differences across cloud and on-premise hardware affect how agents execute time-sensitive workflows. Performance variability isn’t just an engineering problem. It’s a business reliability problem.
  • Consistent safety and auditability. Guardrails, identity controls, and access policies must follow the agent wherever it runs. An agent that operates under strict governance in one environment and loose controls in another isn’t governed at all.

What a vendor-neutral control plane actually gives you

The consistency that enterprise agentic AI requires usually does not come from any single cloud provider. It comes from a layer above the infrastructure: a vendor-neutral control plane that governs how agents behave regardless of where they run.

This isn’t about where your AI platform is deployed. It’s about where your agents execute, and ensuring that wherever that is, governance, security, and behavior travel with them.

That control plane does three things hyperscaler ecosystems struggle to do consistently on their own:

  • Enables agents to execute where data lives. Cross-environment data movement is expensive, slow, and often non-compliant. A vendor-neutral control plane lets agents operate where the data already resides, eliminating the cost and compliance risk of moving sensitive data across environments to meet compute requirements.
  • Unifies identity and access across every environment. Without a central identity layer, every cloud and on-premise environment maintains its own access controls, creating gaps where agent permissions are inconsistent or unaudited. A vendor-neutral control plane enforces the same identity, RBAC, and approval workflows everywhere, so there’s no environment where an agent operates outside policy.
  • Centralizes policy without limiting deployment flexibility. Security and governance rules are written once and propagated automatically across every environment. Policies don’t drift. Compliance doesn’t require per-environment validation. And when requirements change, updates apply everywhere simultaneously.

This is what a multi-cloud orchestration layer like Covalent makes operationally real: reducing environment-specific infrastructure differences behind a common control layer so agents can be governed and executed more consistently whether they run in a public cloud, on-premise, at the edge, or alongside business platforms like SAP, Salesforce, or Snowflake.

The architectural requirements for infrastructure-agnostic agentic AI 

Building for infrastructure agnosticism isn’t a single decision. It’s a set of architectural commitments that work together to ensure agents behave consistently, securely, and governably across every environment they touch. Here’s what that foundation looks like. 

Separation of control plane and compute plane

Two distinct functions. Two distinct layers.

  • Control plane. Where governance lives. Security policies, identity controls, compliance rules, and audit logging are defined once and applied everywhere.
  • Compute plane. Where execution happens. Clouds, on-premise systems, edge environments, GPU clusters — wherever agents need to run.

Separating them means governance follows the agent automatically rather than being rebuilt for each new environment. When requirements change, updates propagate everywhere. When a new environment is added, it inherits existing controls immediately.

This is what makes build-once, deploy-anywhere operationally real rather than aspirationally true.

Containerization and standardized interfaces

Separating control from compute sets the architectural principle. Containerization and standardized interfaces are what make it executable at the agent level.

  • Containerization. Agents are packaged with everything they need to run: runtime, dependencies, configuration. What works in AWS works on-premise. What works on-premise works at the edge. No rebuilding per environment.
  • Standardized interfaces. Agents interact with tools, data, and other agents the same way regardless of where compute lives. No environment-specific rewrites. No workflow rebuilding. No behavioral drift.

Without both, every new deployment is effectively a new build.

Policy inheritance and governance consistency

Separating control from compute only delivers value if governance actually travels with the agent. Policy inheritance is how that happens.

When security and governance rules are defined centrally, every agent automatically inherits and applies enterprise-compliant behavior wherever it runs. No manual reconfiguration per environment. No gaps between what policy says and what agents do.

What this means in practice:

  • No policy drift. Changes propagate automatically across every environment simultaneously.
  • No compliance blind spots. Every environment operates under the same rules, whether it’s a public cloud, on-premise system, or edge deployment.
  • Faster audit cycles. Compliance teams validate one operating model instead of assessing each environment independently.

Lineage, versioning, and reproducibility

Observability tells you what agents are doing right now. Lineage tells you what they did, why, and with what version of which tools and models.

In enterprise environments where agents are making consequential decisions at scale, that distinction matters. Every agent action, tool call, and model version needs to be traceable and reproducible. When something goes wrong — and at scale, something always does — you need to reconstruct exactly what happened, in which environment, under which conditions.

Lineage also makes agent updates safer. When you can version tools, models, and agent definitions independently and trace their interactions, you can roll back selectively rather than broadly. That’s the difference between a controlled update and an enterprise-wide incident.

Without lineage, you don’t have governance. You have hope.

Unified observability and auditability

Governance and policy consistency mean nothing without visibility. When agents are making decisions and triggering actions autonomously across multiple environments, you need a single, unified view of what they’re doing, where they’re doing it, and whether it’s working as intended.

That means one consolidated view across:

  • Performance: Latency, throughput, and task-quality signals across every environment.
  • Drift: Detecting when agent behavior deviates from expected patterns before it becomes a business problem.
  • Security events: Identity anomalies, access violations, and guardrail triggers surfaced in one place regardless of where they occur.
  • Audit trails: Every agent action, tool call, and workflow step logged and traceable across all environments.

Without unified observability, you’re not governing a distributed agentic system. You’re hoping it’s working.

How infrastructure-agnostic deployment simplifies compliance and eliminates vendor lock-in

When each cloud and on-premise environment runs its own security model, audit process, and configuration standards, the gaps between them become the risk. Policies fall out of sync. Audit trails fragment. Security teams lose visibility precisely where agents are most active. For regulated industries, that exposure isn’t theoretical. It’s an audit finding waiting to happen.

Infrastructure-agnostic deployment gives compliance teams a single entry point to govern, monitor, and secure every agentic workload regardless of where it runs.

  • Consistent security controls. Identity, RBAC, guardrails, and access permissions are defined once and enforced everywhere. No rebuilding configurations for AWS, then Azure, then GCP, then on-premise.
  • No policy drift. In multi-cloud environments, policies maintained separately per environment will diverge over time. A single infrastructure-agnostic control plane propagates changes automatically, keeping every environment aligned without manual correction.
  • Simplified governance reviews. Compliance teams validate one operating model instead of auditing each environment independently, accelerating alignment with SOC 2, ISO 27001, FedRAMP, GDPR, and internal risk frameworks.
  • Unified audit logging. Every agent action, tool call, and workflow step is captured in one place. End-to-end traceability is the default, not something reconstructed after the fact.

When governance and orchestration live above the cloud layer rather than inside it, workloads are far easier to move between environments without large-scale rewrites, duplicated security rework, or full compliance revalidation from scratch.

Infrastructure agnosticism is also a cost strategy 

Vendor lock-in doesn’t just constrain your architecture. It constrains your leverage. When all your agentic AI workloads run inside one hyperscaler’s ecosystem, you pay their prices, on their terms, with no practical alternative.

Infrastructure-agnostic deployment changes that calculus. When workloads can move with less friction, cost becomes more of a controllable variable rather than a fixed amount you simply absorb.

  • Burst to lower-cost GPU providers when demand spikes. Rather than over-provisioning expensive reserved capacity, workloads shift automatically to alternative GPU clouds when needed and scale back when demand drops.
  • Use purpose-built clouds for training. Not all clouds handle AI training equally. Infrastructure-agnostic deployment lets you route training workloads to providers optimized for that task and avoid paying general-purpose compute rates for specialized work.
  • Run inference on-premise or in cheaper regions. Steady-state and latency-tolerant inference workloads don’t need to run in expensive primary cloud regions. Routing them to lower-cost environments is a straightforward cost lever that’s only accessible when your architecture isn’t locked to one provider.
  • Preserve negotiating leverage. When you can move workloads with far less friction, you are less captive to a single provider’s pricing and capacity constraints. That optionality has real financial value, even when you do not exercise it often.

Deploy anywhere, govern everywhere

Infrastructure-agnostic deployment isn’t an architectural preference. It’s the prerequisite for enterprise agentic AI that actually works, consistently, securely, and at scale across every environment your business runs on.

Where to run your AI platform is only half the question. The harder half is whether your agents can execute anywhere your business needs them to, under governance that travels with them.

The walled garden was never a foundation. It was a starting point. The enterprises that will lead on agentic AI are the ones building above it.

See the Agent Workforce Platform in action.

FAQs

Why do enterprises need infrastructure-agnostic deployment for agentic AI?

Agentic AI relies on consistent tool access, reasoning behavior, memory, governance, and auditability. These requirements break down when agents run in environments that enforce different security models, APIs, networking patterns, or hardware assumptions.

Infrastructure-agnostic deployment provides a unified control plane that sits above all clouds, on-premise systems, and edge environments. This ensures that agents operate the same way everywhere, using the same policies, lineage, access controls, and orchestration logic, regardless of where the compute actually runs.

What makes multi-cloud and hybrid AI deployments so challenging today?

Cloud providers operate as walled gardens. AWS, GCP, and Azure can all be connected to other environments, but none is designed to act as a neutral control layer across the rest, and none extends governance cleanly across on-premise or edge environments by default. Without a neutral control layer, enterprises face two bad options: centralize all workloads into one cloud, which is unrealistic for sovereignty, cost, and data-gravity reasons, or hand-build brittle integrations across environments.

These manual integrations often drift, introduce security gaps, and create inconsistent agent behavior. Infrastructure-agnostic deployment solves this by providing a single orchestration and governance layer across all environments.

How does infrastructure-agnostic deployment support compliance?

Compliance becomes significantly easier when all agent activity flows through a single entry point. Infrastructure-agnostic deployment enables unified audit logging, consistent RBAC and identity controls, and standardized policy enforcement across every environment.

Instead of evaluating each cloud independently, compliance teams can validate one operating model for SOC 2, ISO 27001, GDPR, FedRAMP, or internal risk frameworks. It also reduces policy drift, as changes propagate everywhere automatically, allowing security and governance standards to remain stable over time.

Does this approach help reduce vendor lock-in?

Yes. When governance, orchestration, policy controls, and agent behavior are defined at the control-plane level rather than inside a specific cloud, enterprises can move or scale workloads freely.

This makes it possible to burst to alternative GPU providers, keep sensitive workloads on-premise, or switch clouds for cost or availability reasons without rewriting code or rebuilding configurations. The result is more leverage, lower long-term cost, and the ability to adapt as infrastructure needs change.

What’s the biggest misconception about hybrid or cross-environment agent deployment?

Many organizations assume they can deploy agents the same way they deploy traditional applications, by running identical containers in multiple clouds. But agents are not simple services. They depend on reasoning, multi-step workflows, tool use, memory, and safety constraints that must behave identically across environments.

Hardware differences, networking assumptions, inconsistent security models, and cloud-specific APIs can cause agents to behave unpredictably if not managed centrally. A vendor-neutral control plane is required to preserve consistent behavior and governance across all environments.

How does DataRobot enable “build once, deploy anywhere” execution?

DataRobot provides a centralized control plane for agent governance, lineage, and security, with one critical distinction: governance is enforced at Day 0, meaning it’s baked into the agent’s definition at build time, not added after deployment. 

Workloads run wherever the customer needs them, whether in a public cloud, on-premise, at the edge, in specialized GPU clouds, or directly inside business applications like SAP, Salesforce, and Snowflake, through Covalent-powered multi-cloud orchestration. Standardized agent templates and tool interfaces ensure consistent behavior across every environment, while the Unified Workload API allows models, tools, containers, and NIMs to run without environment-specific rewrites. The result is agentic AI that doesn’t just run everywhere. It runs safely everywhere.

The post Your AI agents will run everywhere. Is your architecture ready for that?  appeared first on DataRobot.
AI latency is a business risk. Here’s how to manage it

When a major insurer’s AI system takes months to settle a claim that should be resolved in hours, the problem usually isn’t the model in isolation. It’s the system around the model and the latency that system introduces at every step.

Speed in enterprise AI isn’t about impressive benchmark numbers. It’s about whether AI can keep pace with the decisions, workflows, and customer interactions the business depends on. And in production, many systems can’t. Not under real load, not across distributed infrastructure, and not when every delay affects cost, conversion, risk, or customer trust.

The danger is that latency rarely appears alone. It is tightly coupled with cost, accuracy, infrastructure placement, retrieval design, orchestration logic, and governance controls. Push for speed without understanding those dependencies, and you do one of two things: overspend to brute-force performance, or simplify the system until it is faster but less useful.

That is why latency is not just an engineering metric. It is an operating constraint with direct business consequences. This guide explains where latency comes from, why it compounds in production, and how enterprise teams can design AI systems that perform when the stakes are real.

Key takeaways

  • Latency is a system-level business issue, not a model-level tuning problem. Faster performance depends on infrastructure, retrieval, orchestration, and deployment design as much as model choice.
  • Where workloads run often determines whether SLAs are realistic. Data locality, cross-region traffic, and hybrid or multi-cloud placement can add more delay than inference itself.
  • Predictive, generative, and agentic AI create different latency patterns. Each requires a different operating strategy, different optimization levers, and different business expectations.
  • Sustainable performance requires automation. Manual tuning does not scale across enterprise AI portfolios with changing demand, changing workloads, and changing cost constraints.
  • Deployment flexibility matters because AI has to run where the business operates. That may mean containers, scoring code, embedded equations, or workloads distributed across cloud, hybrid, and on-premises environments.

The business cost of AI that can’t keep up

Every second your AI lags, there’s a business consequence. A fraud charge that goes through instead of getting flagged. A customer who abandons a conversation before the response arrives. A workflow that grinds for 30 seconds when it should resolve in two.

In predictive AI, this means meeting strict operational response windows inside live business systems. When a customer swipes their credit card, your fraud detection model has roughly 200 milliseconds to flag suspicious activity. Miss that window and the model may still be accurate, but operationally it has already failed.

Generative AI introduces a different dynamic. Responses are generated incrementally, retrieval steps may happen before generation begins, and longer outputs increase total wait time. Your customer service chatbot might craft the perfect response, but if it takes 10 seconds to appear, your customer is already gone.

Agentic AI raises the stakes further. A single request may trigger retrieval, planning, multiple tool calls, approval logic, and one or more model invocations. Latency accumulates across every dependency in the chain. One slow API call, one overloaded tool, or one approval checkpoint in the wrong place can turn a fast workflow into a visibly broken one. 

Each AI type carries different latency expectations, but all three are constrained by the same underlying realities: infrastructure placement, data access patterns, model execution time, and the cost of moving information across systems.​​

Speed has a price. So does falling behind.

Most AI initiatives go sideways when teams optimize for speed, then act surprised when their costs explode or their accuracy drops. Latency optimization is always a trade-off decision, not a free improvement.

  • Faster is more expensive. Higher-performance compute can reduce inference time dramatically, but it raises infrastructure costs. Warm capacity improves responsiveness, but idle capacity costs money. Running closer to data may reduce latency, but it may also require more complex deployment patterns. The real question is not whether faster infrastructure costs more. It is whether the business cost of slower AI is greater.
  • Faster can reduce quality if teams use the wrong shortcuts. Techniques such as model compression, smaller context windows, aggressive retrieval limits, or simplified workflows can improve response time, but they can also reduce relevance, reasoning quality, or output precision. A fast answer that causes escalation, rework, or user abandonment is not operationally efficient.
  • Faster usually increases architectural complexity. Parallel execution, dynamic routing, request classification, caching layers, and differentiated treatment for simple versus complex requests can all improve performance. But they also require tighter orchestration, stronger observability, and more disciplined operations.

That is why speed is not something enterprises “unlock.” It is something they engineer deliberately, based on the business value of the use case, the tolerance for delay, and the cost of getting it wrong.

Three things that determine whether your AI performs in production 

Three patterns show up consistently across enterprise AI deployments. Get these right and your AI performs. Get them wrong and you have an expensive project that never delivers.

Where your AI runs matters as much as how it runs 

Location is the first law of enterprise AI performance.

In many AI systems, the biggest latency bottleneck is not the model. It is the distance between where compute runs and where data lives. If inference happens in one region, retrieval happens in another, and business systems sit somewhere else entirely, you are paying a latency penalty before the model has even started useful work.

That penalty compounds quickly. A few extra network hops across regions, cloud boundaries, or enterprise systems can add hundreds of milliseconds or more to a request. Multiply that across retrieval steps, orchestration calls, and downstream actions, and latency becomes structural, not incidental.

“Centralize everything” has been the default hyperscaler posture for years, and it starts to break down under real-time AI requirements. Pulling data into a preferred platform may be acceptable for offline analytics or batch processing. It is much less acceptable when the use case depends on real-time scoring, low-latency retrieval, or live customer interaction.

The better approach is to run AI where the data and business process already live: inside the data warehouse, close to existing transactional systems, within on-premises environments, or across hybrid infrastructure designed around performance requirements instead of platform convenience.

Automation matters here too. Manually deciding where to place workloads, when to burst, when to shut down idle capacity, or how to route inference across environments does not scale. Enterprise teams that manage latency well use orchestration systems that can dynamically allocate resources against real-time cost and performance targets rather than relying on static placement assumptions.

Your AI type determines your latency strategy 

Not all AI behaves the same way under pressure, and your latency strategy needs to reflect that.

Predictive AI is the least forgiving. It often has to score in milliseconds, integrate directly into operational systems, and return a result fast enough for the next system to act. In these environments, unnecessary middleware, slow network paths, or rigid deployment models can destroy value even when the model itself is strong.

Generative AI is more variable. Latency depends on prompt size, context size, retrieval design, token generation speed, and concurrency. Two requests that look similar at a business level may have very different response times because the underlying workload is not uniform. Stable performance requires more than model hosting. It requires careful control over retrieval, context assembly, compute allocation, and output length.

Agentic AI compounds both problems. A single workflow may include planning, branching, multiple tool invocations, safety checks, and fallback logic. The performance question is no longer “How fast is the model?” It becomes “How many dependent steps does this system execute before the user sees value?” In agentic systems, one slow component can hold up the entire chain.

What matters across all three is closing the gap between how a system is designed and how it actually behaves in production. Models that are built in one environment, deployed in another, and operated through disconnected tooling usually lose performance in the handoff. The strongest enterprise programs minimize that gap by running AI as close as possible to the systems, data, and decisions that matter.

Why automation is the only way to scale AI performance 

Manual performance tuning does not scale. No engineering team is large enough to continuously rebalance compute, manage concurrency, control spend, watch for drift, and optimize latency across an entire enterprise AI portfolio by hand.

That approach usually leads to one of two outcomes: over-provisioned infrastructure that wastes budget, or under-optimized systems that miss performance targets when demand changes.

The answer is automation that treats cost, speed, and quality as linked operational targets. Dynamic resource allocation can adjust compute based on live demand, scale capacity up during bursts, and shut down unused resources when demand drops. That matters because enterprise workloads are rarely static. They spike, stall, shift by geography, and change by use case.

But speed without quality is just expensive noise. If latency tuning improves response time while quietly degrading answer quality, decision quality, or business outcomes, the system is not improving. It is becoming harder to trust. Sustainable optimization requires continuous accuracy evaluation running alongside performance monitoring so teams can see not just whether the system is faster, but whether it is still working.

Together, automated resource management and continuous quality evaluation are what make AI performance sustainable at enterprise scale without requiring constant manual intervention.

Know where latency hides before you try to fix it 

Optimization without diagnosis is just guessing. Before your teams change infrastructure, model settings, or workflow design, they need to know exactly where time is being lost.

  • Inference is the obvious suspect, but rarely the only one, and often not the biggest one. In many enterprise systems, latency comes from the layers around the model more than the model itself. Optimizing inference while ignoring everything else is like upgrading an engine while leaving the rest of the vehicle unchanged.
  • Data access and retrieval often dominate total response time, especially in generative and agentic systems. Finding the right data, retrieving it across systems, filtering it, and assembling useful context can take longer than the model call itself. That is why retrieval strategy is a performance decision, not just a relevance decision.
  • More data is not always better. Pulling too much context increases processing time, expands prompts, raises cost, and can reduce answer quality. Faster systems often improve because they retrieve less, but retrieve more precisely.
  • Network distance compounds quickly. A 50-millisecond delay across one hop becomes much more expensive when requests touch multiple services, regions, or external tools. At enterprise scale, those increments are not trivial. They determine whether the system can support real-time use cases or not.
  • Orchestration overhead accumulates in agentic systems. Every tool handoff, policy check, branch decision, and state transition adds time. When teams treat orchestration as invisible glue, they miss one of the biggest sources of avoidable delay.
  • Idle infrastructure creates hidden penalties too. Cold starts, spin-up time, and restart delays often show up most visibly on the first request after quiet periods. These penalties matter in customer-facing systems because users experience them directly.

The goal is not to make every component as fast as possible. It is to assign performance targets based on where latency actually affects business outcomes. If retrieval consumes two seconds and inference takes a fraction of that, tuning the model first is the wrong investment.

Governance doesn’t have to slow you down 

Enterprise AI needs governance that enforces auditability, compliance, and safety without making performance unacceptable.

Most governance functions do not need to sit directly in the critical path. Audit logging, trace capture, model monitoring, drift detection, and many compliance workflows can run alongside inference rather than blocking it. That allows enterprises to preserve visibility and control without adding unnecessary user-facing delay.

Some controls do need real-time execution, and those should be designed with performance in mind from the start. Content moderation, policy enforcement, permission checks, and certain safety filters may need to execute inline. When that happens, they need to be lightweight, targeted, and intentionally placed. Retrofitting them later usually creates avoidable latency.

Too many organizations assume governance and performance are naturally in tension. They are not. Poorly implemented governance slows systems down. Well-designed governance makes them more trustworthy without forcing the business to choose between compliance and responsiveness.

It is also worth remembering that perceived speed matters as much as measured speed. A system that communicates progress, handles waiting intelligently, and makes delays visible can outperform a technically faster system that leaves users guessing. In enterprise AI, usability and trust are part of performance.

Building AI that performs when it counts 

Latency is not a technical detail to hand off to engineering after the strategy is set. It is a constraint that shapes what AI can actually deliver, at what cost, with what level of reliability, and in which business workflows it can be trusted.

The enterprises getting this right are not chasing speed for its own sake. They are making explicit operating decisions about workload placement, retrieval design, orchestration complexity, automation, and the trade-offs they are willing to accept between speed, cost, and quality.

Performance techniques that work in a controlled environment rarely survive real traffic unchanged. The gap between a promising proof of concept and a production-grade system is where latency becomes visible, expensive, and politically important inside the business.

And latency is only one part of the broader operating challenge. In a survey of nearly 700 AI leaders, only a third said they had the right tools to get models into production. It takes an average of 7.5 months to move from idea to production, regardless of AI maturity. Those numbers are a reminder that enterprise AI performance problems usually start well before inference. They start in the operating model.

That is the real issue AI leaders have to solve. Not just how to make models faster, but how to build systems that can perform reliably under real business conditions. Download the Unmet AI Needs survey to see the full picture of what is preventing enterprise AI from performing at scale.

Want to see what that looks like in practice? Explore how other AI leaders are building production-grade systems that balance latency, cost, and reliability in real environments.

FAQs

Why is latency such a critical factor in enterprise AI systems?

Latency determines whether AI can operate in real time, support decision-making, and integrate cleanly into downstream workflows. For predictive systems, even small delays can break operational SLAs. For generative and agentic systems, latency compounds across retrieval, token generation, orchestration, tool calls, and policy checks. That is why latency should be treated as a system-level operating issue, not just a model-tuning exercise.

What causes latency in modern predictive, generative, and agentic systems?

Latency usually comes from a mix of factors: inference delays, retrieval and data access, network distance, cold starts, and orchestration overhead. Agentic systems add further complexity because delays accumulate across tools, branches, context passing, and approval logic. The most effective teams identify which layers contribute most to total response time and optimize there first.

How does DataRobot reduce latency without sacrificing accuracy?

DataRobot uses Covalent and syftr to automate resource allocation, GPU and CPU optimization, parallelism, and workflow tuning. Covalent helps manage scaling, bursting, warm pools, and resource shifting so workloads can run on the right infrastructure at the right time. syftr helps teams evaluate accuracy, performance, and drift so they do not improve speed by quietly degrading model quality. Together, they support lower-latency AI that remains accurate and cost-aware.

How do infrastructure placement and deployment flexibility impact latency?

Where compute runs matters as much as the model itself. Long network paths between cloud regions, cross-cloud traffic, and distant data access can inflate latency before useful work begins. DataRobot addresses this by allowing AI to run directly where data lives, including Snowflake, Databricks, on-premises environments, and hybrid clouds. Teams can deploy models in multiple formats and place them in the environments that best support operational performance, rather than forcing workloads into one preferred architecture.

The post AI latency is a business risk. Here’s how to manage it appeared first on DataRobot.

Handle with care: Soft robot gripper picks ripe fruit without bruising

When assessing the ripeness of fruit, sight and smell can tell you a lot, but the best indicator is often how the fruit feels. Cornell researchers used stretchable fiber-optic sensors to create a soft robot gripper that can predict the ripeness of strawberries by touch, then gently twist them off their branch or vine without causing any damage.

AI system learns to keep warehouse robot traffic running smoothly

By Adam Zewe

Inside a giant autonomous warehouse, hundreds of robots dart down aisles as they collect and distribute items to fulfill a steady stream of customer orders. In this busy environment, even small traffic jams or minor collisions can snowball into massive slowdowns.

To avoid such an avalanche of inefficiencies, researchers from MIT and the tech firm Symbotic developed a new method that automatically keeps a fleet of robots moving smoothly. Their method learns which robots should go first at each moment, based on how congestion is forming, and adapts to prioritize robots that are about to get stuck. In this way, the system can reroute robots in advance to avoid bottlenecks.

The hybrid system utilizes deep reinforcement learning, a powerful artificial intelligence method for solving complex problems, to figure out which robots should be prioritized. Then, a fast and reliable planning algorithm feeds instructions to the robots, enabling them to respond rapidly in constantly changing conditions.

In simulations inspired by actual e-commerce warehouse layouts, this new approach achieved about a 25 percent gain in throughput over other methods. Importantly, the system can quickly adapt to new environments with different quantities of robots or varied warehouse layouts.

“There are a lot of decision-making problems in manufacturing and logistics where companies rely on algorithms designed by human experts. But we have shown that, with the power of deep reinforcement learning, we can achieve super-human performance. This is a very promising approach, because in these giant warehouses even a two or three percent increase in throughput can have a huge impact,” says Han Zheng, a graduate student in the Laboratory for Information and Decision Systems (LIDS) at MIT and lead author of a paper on this new approach.

Zheng is joined on the paper by Yining Ma, a LIDS postdoc; Brandon Araki and Jingkai Chen of Symbotic; and senior author Cathy Wu, the Class of 1954 Career Development Associate Professor in Civil and Environmental Engineering (CEE) and the Institute for Data, Systems, and Society (IDSS) at MIT, and a member of LIDS. The research appears today in the Journal of Artificial Intelligence Research.

Rerouting robots

Coordinating hundreds of robots in an e-commerce warehouse simultaneously is no easy task.

The problem is especially complicated because the warehouse is a dynamic environment, and robots continually receive new tasks after reaching their goals. They need to be rapidly redirected as they leave and enter the warehouse floor.

Companies often leverage algorithms written by human experts to determine where and when robots should move to maximize the number of packages they can handle.

But if there is congestion or a collision, a firm may have no choice but to shut down the entire warehouse for hours to manually sort the problem out.

“In this setting, we don’t have an exact prediction of the future. We only know what the future might hold, in terms of the packages that come in or the distribution of future orders. The planning system needs to be adaptive to these changes as the warehouse operations go on,” Zheng says.

The MIT researchers achieved this adaptability using machine learning. They began by designing a neural network model to take observations of the warehouse environment and decide how to prioritize the robots. They train this model using deep reinforcement learning, a trial-and-error method in which the model learns to control robots in simulations that mimic actual warehouses. The model is rewarded for making decisions that increase overall throughput while avoiding conflicts.

Over time, the neural network learns to coordinate many robots efficiently.

“By interacting with simulations inspired by real warehouse layouts, our system receives feedback that we use to make its decision-making more intelligent. The trained neural network can then adapt to warehouses with different layouts,” Zheng explains.

It is designed to capture the long-term constraints and obstacles in each robot’s path, while also considering dynamic interactions between robots as they move through the warehouse.

By predicting current and future robot interactions, the model plans to avoid congestion before it happens.

After the neural network decides which robots should receive priority, the system employs a tried-and-true planning algorithm to tell each robot how to move from one point to another. This efficient algorithm helps the robots react quickly in the changing warehouse environment.

This combination of methods is key.

“This hybrid approach builds on my group’s work on how to achieve the best of both worlds between machine learning and classical optimization methods. Pure machine-learning methods still struggle to solve complex optimization problems, and yet it is extremely time- and labor-intensive for human experts to design effective methods. But together, using expert-designed methods the right way can tremendously simplify the machine learning task,” says Wu.

Overcoming complexity

Once the researchers trained the neural network, they tested the system in simulated warehouses that were different than those it had seen during training. Since industrial simulations were too inefficient for this complex problem, the researchers designed their own environments to mimic what happens in actual warehouses.

On average, their hybrid learning-based approach achieved 25 percent greater throughput than traditional algorithms as well as a random search method, in terms of number of packages delivered per robot. Their approach could also generate feasible robot path plans that overcame congestion caused by traditional methods.

“Especially when the density of robots in the warehouse goes up, the complexity scales exponentially, and these traditional methods quickly start to break down. In these environments, our method is much more efficient,” Zheng says.

While their system is still far away from real-world deployment, these demonstrations highlight the feasibility and benefits of using a machine learning-guided approach in warehouse automation.

In the future, the researchers want to include task assignments in the problem formulation, since determining which robot will complete each task impacts congestion. They also plan to scale up their system to larger warehouses with thousands of robots.

AI swarms could hijack democracy without anyone noticing

AI-powered personas are becoming so realistic that they can infiltrate online communities and subtly steer public opinion. Unlike traditional bots, they adapt, coordinate, and refine their messaging at a massive scale, creating a false sense of consensus. Early warning signs—like deepfakes and fake news networks—have already appeared in global elections. Researchers warn that the next election could be the true test of this technology’s power.
Page 37 of 66
1 35 36 37 38 39 66