News

Page 76 of 718
1 … 74 75 76 77 78 … 718

Small Team, Big Output: The Wine Bottler Bulles Création Automates Its End-of-Line with Robotiq Cobot Palletizing

Bulles Création built its business on flexibility, bottling for local winemakers while developing its own effervescent drinks. But as demand grew, the company's production tools couldn't keep up. Its packaging line was capped at 1,500 bottles an hour.

Simple robot design exceeds human hand in some core motions

The human hand is a dexterous and versatile machine. Scientists have conventionally tried to replicate these traits in robots by copying the biological mechanics of the hand, resulting in complex and difficult-to-control structures. An alternative solution to these challenges was proposed in a new study published in Advanced Science: the BioflexBot, a novel robot that mimics and even exceeds core motions of the hand with a simple design.

Local tracing in the DataRobot CLI: catch issues before production

Building an agentic application is a loop: ask the agent a question, see how it responds, and when something’s off, investigate why. Most of the time it works, but when it doesn’t, it’s rarely caught in your local environment. It’s after you’ve deployed, on a request that behaved fine right up until it didn’t.

That’s the part that costs you: push a change, wait for it to land, run the request, then go hunting for the answer in a different tool, minutes removed from the moment you cared about it. DataRobot local tracing closes that gap, whether you’re working in an agentic application template directly, or using Agent Assist to do the scaffolding for you.

What runs on your local host

dr xp, the DataRobot experimentation CLI plugin, runs a local OpenTelemetry dashboard while you develop. Same open standard, same tracing model the platform uses post-deploy. What you see locally is what your agent actually did, live, with no deploy required.

Open the tracing page on localhost and see every request: which tools were called, in what order, latency, token counts, error logs. Filter by attribute, status, date range, or search.

How you get dr xp: the Agent Assist skill

Every DataRobot agent template ships with dr xp pre-installed and configured, so you don’t set it up separately. You can get to that template through the Agent Assist skill, which runs inside your coding agent: OpenCode, Claude Code, Cursor, or VS Code Copilot.

Install with:

npx ai-agent-skills install datarobot-oss/datarobot-agent-skills

Then start it with datarobot-agent-assist or a slash command.

From there, Agent Assist:

  • Turns your natural-language description into a structured agent_spec.md (YAML)
  • Can simulate agent behavior from that spec before any code exists, using mock tool calls
  • Scaffolds code from a DataRobot agent template, which is where AGENTS.md and dr xp come from, pre-configured, every time (not something Agent Assist generates from scratch per project)
  • Walks you through deployment (you run the deploy commands yourself)

The one case where you don’t automatically get this local dev experience: pointing Agent Assist at your own existing repo (the “Code an AI agent” or brownfield path) that wasn’t built from the DataRobot template. There, AGENTS.md may be minimal or absent, and dr xp isn’t there until you add the template’s tooling yourself.

Why it matters

The value isn’t just speed, though the loop does get shorter. It’s that you stop treating production as the place where you find out what your agent actually does. Every trace you watch locally, whether a clean run, a slow tool call, or an edge case that breaks a prompt, is something you caught while it was still cheap to fix, in the same window you’re already working in.

That changes what “ready to deploy” means. You’re not shipping on faith that a demo run generalizes; you’re shipping something you watched hold up across real requests, with a full record of why it behaved the way it did at every step. And because it comes bundled into the same Agent Assist skill you’re already using to scaffold and build the agent, none of this is a separate tool to learn or a separate habit to build. It’s just what’s there, from the first line of code.

Get started

To go deeper on dr xp commands, configuration, and the local tracing dashboard, see the experimentation plugin documentation.

Agentic AI capabilities are a premium feature. Enablement requires contacting a DataRobot representative.

The post Local tracing in the DataRobot CLI: catch issues before production appeared first on DataRobot.

Butterfly-inspired ceramic microscrolls unroll with magnets to power tiny robots

Researchers at the University of Stuttgart and the Max Planck Institute for Solid State Research have developed tiny rolls that can be unrolled and rolled up in a controlled manner using a magnet. The model for this was the proboscis of butterflies. These smart materials enable the development of more efficient drive technologies for micro- and soft robotics, a field of research of great economic importance. The results have been published in the journal Advanced Materials.

Scientists develop ‘RoboDojo,’ a unified platform to evaluate embodied AI

The Multimedia Laboratory (MMLab) at The University of Hong Kong (HKU) has spearheaded the development of "RoboDojo," a unified benchmarking platform designed to evaluate robotic manipulation across simulated and physical environments. Co-initiated by Professor Ping Luo, associate director (AI Research and Tech Transfer) of the HKU School of Computing and Data Science (CDS), and his Ph.D. student Tianxing Chen, the project was developed in collaboration with researchers from nearly 20 leading global universities, including the University of California, Berkeley, and Tsinghua University. The paper is posted to the arXiv preprint server.

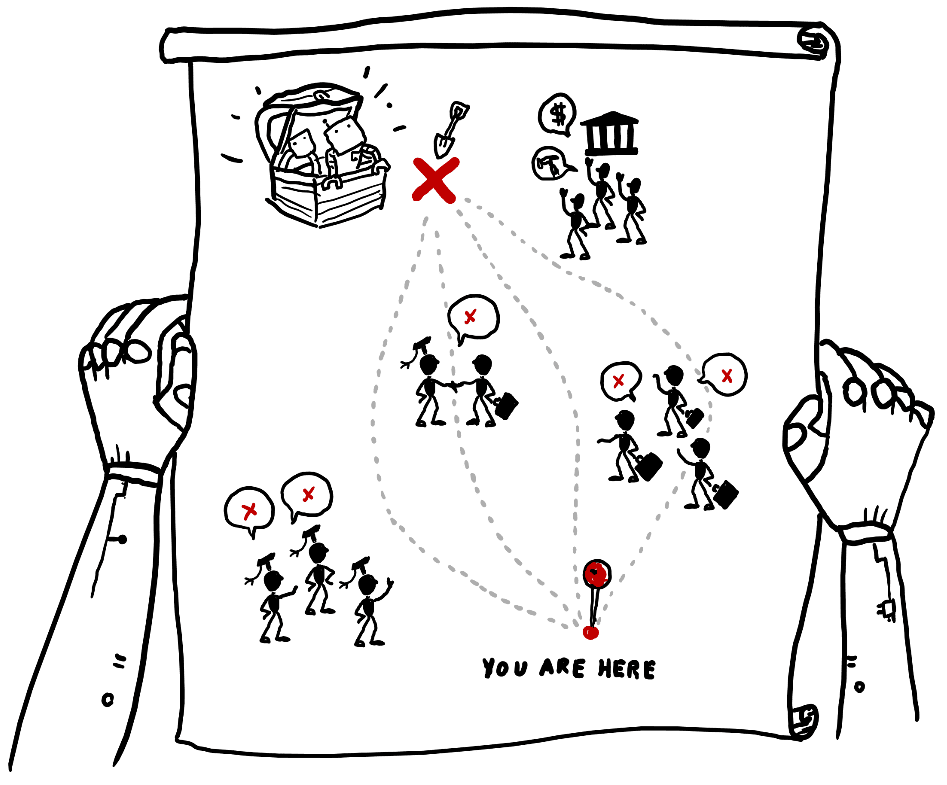
Robotics roadmaps from around the world

What’s a robotics roadmap, and why should we care?

Machines with pre-defined capabilities will soon be old-school. Future machines are expected to learn and adapt to unpredictability and to interact with the physical world with the ableness of our own bodies. Welcome to Industry 4.0 (1).

The reliance of modern societies on robots, from manufacturing to healthcare to agriculture to transportation (2), already suggests the magnitude of impact that recent innovations in robotic hardware could have once transferred from the laboratory to the market. Investment in robotics is a national priority in many countries (3). We are in fact in the midst of a global race to advance robots for physically embodying artificial intelligence, which is expected to have a dominating influence in global labor markets, immigration, military, commerce, and education (4).

Gaining familiarity with relevant stakeholders helps roboticists to understand their role in influencing the trajectory of their innovation. Roboticists can advise policymakers, for example, on the viability of their field and its potential to transform specific sectors. Government support in these areas enables academic institutes and industries to advance their technology, which can also reassure private investors to bet their money on related businesses. Done well, this process will expedite innovation where society needs it most.

We have a responsibility as a robotics community to discuss the collective milestones that we envision for a better society. What do we want robots to do in 10 years? Who should be the end users? And what resources do we need to transfer our technology into the real world? Though it feels removed from our typical day-to-day work as roboticists, grappling with these questions and reaching the right people could have far-reaching impact.

Roadmaps are an effective tool, especially for the interdisciplinary robotics community, to consolidate ideas and define a shared trajectory. They take many forms, depending on the target audience; a federal action plan can serve as a directive for research institutions while incentivizing investors to support an industry, an academic paper drafted by a coalition of robotics experts can serve as a beacon for innovators and ignite a common vision.

Influential robotics roadmaps have been authored by members of academia, industry, and government alike, often involving a combination of these entities to reflect their diverse perspectives and to propose objectives within realistic constraints. Some examples of these roadmaps include: The US National Robotics Roadmap–a bottom-up, academic-led roadmap that incentivizes major government investment towards innovations in collaborative robots (5,6); the industry-led ADRA Strategic Research, Innovation and Deployment Agenda–which successfully championed a ‘Physical AI’ funding track across the EU through the Horizon Europe innovation funding program (7); and Made in China 2025–a major government-driven plan including robotics development goals which helped transition China from low-cost workshops into a global high-tech leader over the course of a decade (8).

While internationally collaborative robotics roadmaps do exist (9), the majority of robotics roadmaps are highly country-specific, each having a set of unique priorities steeped in economics, geopolitics, and cultural values. A streamlined robotics agenda can help one country rise in the global value chain, while for another it may kickstart innovation needed for achieving technological sovereignty, particularly critical in an era where disruptive digital transformation can dictate shifts in global order.

In this monthly bite-size article series, we will untangle some of the latest information on roadmaps from leading robotics countries around the world. Each month will highlight one country and its robotics agenda.

Some topics we will delve into include:

  • the outstanding priorities and strategies of various country’s robotics roadmaps.
  • the potential target audiences and intended outcomes of their readership.
  • the influence of geopolitical tensions on roadmap strategies.

Thank you for reading this introductory article. Stay tuned for future additions. We would appreciate your opinions and feedback in the meantime, which you can send us at ras@ieee.org.


Robotics Roadmap Issue #1

Ellen H. Rumley – Policy Analyst
Allison Okamura – Vice President

IEEE RAS Science & Technology Watch Board


References

[1] Saurabh Vaidya, Prashant Ambad, Santosh Bhosle, Industry 4.0 – A Glimpse, Procedia Manufacturing, Volume 20, 2018, Pages 233-238, ISSN 2351-9789.
[2] International Federation of Robotics (2025). World Robotics 2025 – Service Robots.
[3] International Federation of Robotics. (2024). Executive summary: World robotics R&D programs (Version 4).
[4] Special Competitive Studies Project (SCSP). (2025). “Who’s Ahead, Who’s Behind, and Where We Are Headed Next in the U.S.-China Technology Competition?”
[5] D. J. Hicks and R. Simmons, “The National Robotics Initiative: A Five-Year Retrospective,” in IEEE Robotics & Automation Magazine, vol. 26, no. 3, pp. 70-77, Sept. 2019.
[6] Christensen, Henrik, et al. A Roadmap for US Robotics – Robotics for a Better Tomorrow. UC San Diego, Computing Community Consortium and Engineering Research Visioning Alliance, Apr. 2024.
[7] Fredrik Heintz, Nabil Belbachir, and Edward Curry, “Strategic Research, Innovation, and Deployment Agenda 2025-2027”, February 2024, Brussels, ADRA.
[8] State Council of the People’s Republic of China. (2015). Made in China 2025. Beijing: State Council.
[9] D. Araiza-Illan et al., “A Road Map for Responsible Robotics: Promoting Human Agency and Collaborative Efforts,” in IEEE Robotics & Automation Magazine, vol. 32, no. 4, pp. 12-24, Dec. 2025.

Stop Rate-Limiting Requests. Start Scheduling Tokens: Introducing DataRobot TokenGrid

Authors: Sudeeptha Jothiprakash, Venkat Bala, Tushar Pandey, Romi Datta

The real bottleneck in the modern AI stack

Enterprise IT has a strange problem: token spend and third-party model subscription costs keep climbing, while the GPU clusters running these workloads sit at just 20% utilization. That gap comes down to one thing: the tools managing access were never built to see the workload itself.

Traditional application orchestrators, Kubernetes frameworks, and API gateways like Tyk or Envoy manage static hardware: CPU, GPU count, memory, network traffic. They have no visibility into token counts, prompt length, or the KV cache pressure that actually drives LLM inference cost, and that blind spot hits both sides of the AI stack. It can’t optimize self-hosted GPU infrastructure, and it can’t govern quota, rate limits, or cost across third-party model APIs either.

To manage access today, platform teams lean on stateless proxies like LiteLLM: static configuration maps, hardcoded bandwidth rules, and count-based rate limits, say, a flat ceiling of 100 requests per minute. That works fine for simple traffic. It breaks down fast in multi-turn generative AI and agentic systems. A token-blind gateway sees two requests as identical if their metadata matches, even if one is a 10-token query and the other passes a 200K-token context file. The actual cost inside the cluster is orders of magnitude apart. Without a way to isolate these workloads, that 200K-token request locks up the model server’s KV cache, drives up P95 tail latency for every other tenant on that hardware, and can cascade into failures across the cluster, triggering a wave of 429 rejections across unrelated, mission-critical applications. The gateway admits it either way: a single rogue user or an unmanaged agent loop can trigger an uncontrolled surge that saturates model bandwidth for everyone else, because the gateway was never built to look for it.

Platform teams run into this friction in three places.

Model proliferation and silos. Token management is scattered across local infrastructure and third-party cloud APIs like AWS Bedrock, Azure OpenAI, and Anthropic. Business units spin up model endpoints independently or plug into third-party APIs on their own, so admins have no single place to track, audit, or enforce quota rules across the organization.

Bandwidth hijacking. Static quotas only check compliance at admission. A multi-turn prompt or agent request can look fine going in, then expand its context size and execution intensity well past that checkpoint mid-run. A single unmanaged agent loop can monopolize shared cluster bandwidth, lock up memory, starve neighboring applications, and blow through production SLAs, all without ever tripping the admission check that was supposed to catch it.

Runtime demand volatility. Enterprise AI architectures now mix third-party cloud APIs with self-hosted open-source models. Hosting those OSS models yourself means managing token-level resource surges directly, and static hardware management can’t keep up. Legacy infrastructure can’t align container scaling with actual request behavior, so platform teams end up choosing between slow response times during traffic spikes or expensive over-provisioning that leaves millions of dollars of enterprise compute sitting idle.

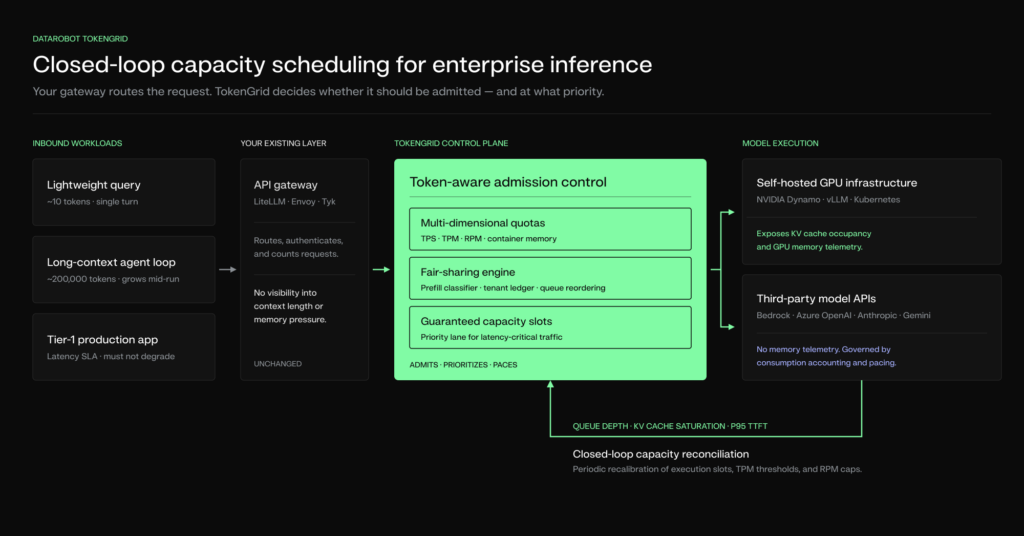
DataRobot TokenGrid works alongside your existing gateways and proxies rather than replacing them. It’s a stateful, token-aware capacity scheduler that sits directly in the admission path, bridging the gap between what the gateway lets in and what the underlying compute can actually handle.

DataRobot TokenGrid: scheduling by token physics, not hardware count

TokenGrid replaces static hardware partitions with a shared, work-conserving capacity pool. It’s a software scheduling layer that sits between your LLM gateways and wherever your models run: self-hosted clusters, hyperscaler-hosted models, or third-party models accessed directly from vendors like Anthropic and Google. Three capabilities make that possible.

1. Dynamic rate limiting

Instead of a fixed requests-per-minute ceiling, TokenGrid enforces unified, multi-dimensional quotas that map directly to physical cluster and API constraints. By tracking live metrics, tokens per second, monthly token budgets (TPM), and container-level memory, it turns raw telemetry into policy-based quotas that platform teams can apply consistently across business units, without piling heavy reasoning workloads onto already-saturated nodes.

2. The fair-sharing engine

TokenGrid runs every inbound request through a multi-stage fairness check that weighs workload shape, a tenant’s quota history, and current hardware constraints before a prompt ever reaches a model.

  • Stage 1, workload classification. TokenGrid estimates prefill demand at the gateway layer, separating heavy context requests from lightweight queries and routing large contexts to dedicated or chunked prefill paths instead of letting them block the queue.
  • Stage 2, quota enforcement. TokenGrid keeps a running ledger of token consumption across self-hosted clusters and third-party APIs. When a tenant exceeds its fair share, the scheduler lowers its priority. On self-hosted clusters, that means deprioritizing the request and pulling its prefix-cache affinity bonus, so compliant tenants keep access to fast KV cache nodes. On third-party APIs, it means applying backpressure and pacing so one high-volume tenant doesn’t exhaust the shared TPM/RPM ceiling or trigger provider rate limits (429s) for everyone else.
  • Stage 3, memory-based backpressure. For self-hosted and managed deployments where container telemetry is visible, since third-party APIs don’t expose KV cache state, TokenGrid watches GPU memory and cache occupancy directly. When a model server pool crosses a configurable KV cache threshold, TokenGrid applies backpressure (HTTP 429) to low-priority background threads, shifts interactive streams to available nodes, and reorders the execution queue from first-come-first-served to shortest-job-first.

3. Automated capacity reconciliation

TokenGrid feeds container performance signals into a centralized Token Admin Service, then cross-references that data against real-time traffic patterns on a regular interval. That closes the loop between what’s happening at the infrastructure layer and what’s happening at the traffic layer, so the system can recommend and recalibrate execution slots, TPM thresholds, and RPM caps across your model fleet automatically. Platform teams no longer need to over-provision for spiky traffic. TokenGrid learns from real usage patterns and resizes allocations accordingly, freeing GPU capacity for other models or training workloads.

Built for on-prem and hybrid, built for what’s next

We hear this problem most from platform teams running predominantly on-premises. These organizations have invested millions of dollars in dedicated, bare-metal GPU clusters, where every percentage point of wasted capacity is a real cost. On-prem admins are the ones managing rigid compute boundaries with no native way to isolate a sudden developer burst from a core business application.

TokenGrid gives these environments an immediate answer to traffic surges that static proxy configs can’t handle. As a lightweight, container-aware scheduling layer, it lets platform teams reclaim GPU margin, enforce multi-dimensional quotas, and keep one noisy tenant from taking down the rest, directly in the admission path.

LLM inference rate limiting

That’s the immediate value. The longer-term shift matters more: moving from fixed hardware placement to an ongoing, automated capacity-scheduling loop opens up new ways to think about enterprise inference orchestration altogether, not just how to contain a runaway agent loop today.

As enterprise AI moves from simple chat interfaces to multi-turn agentic systems, the teams that win won’t be the ones over-provisioning GPUs or bolting static rate limits onto their API proxies. They’ll be the ones who understand how tokens actually move through their infrastructure. TokenGrid turns unmanaged model consumption from a source of chaos into something predictable and efficient.

DataRobot TokenGrid is currently in Private Preview for select co-engineering and enterprise accounts. Reach out to our product team to explore the architecture and request early access.

The post Stop Rate-Limiting Requests. Start Scheduling Tokens: Introducing DataRobot TokenGrid appeared first on DataRobot.

Electronic skin enables tunable touch and proximity sensing for robots and prosthetics

Recent advances in miniaturized and portable electronics, particularly wearable and flexible devices, have increased the demand for self-powered sensing technologies. Among these, triboelectric nanogenerators (TENGs) have received considerable attention for developing highly sensitive tactile sensors.

A ‘5-in-1’ seed-sized surgical robot

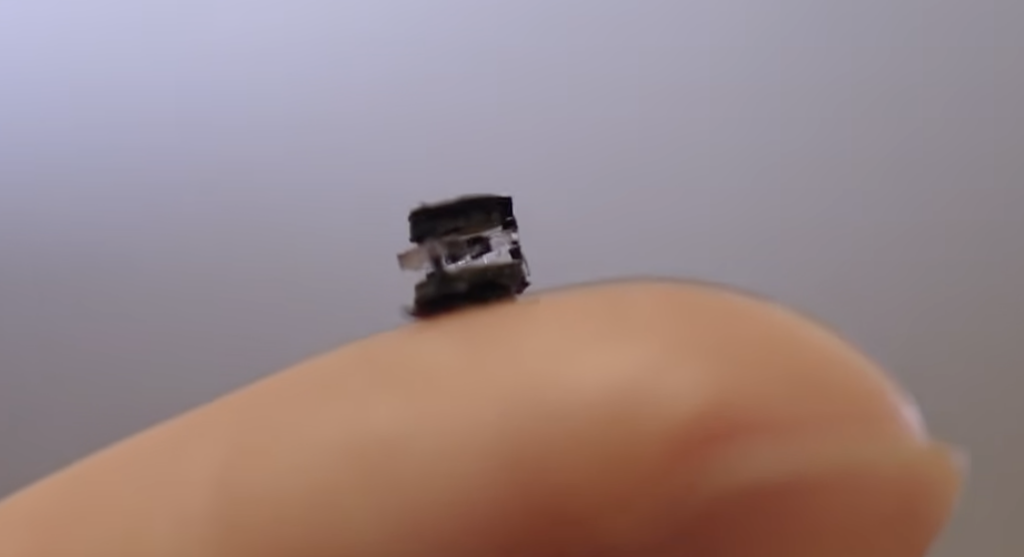
Scientists from Nanyang Technological University, Singapore (NTU Singapore) have developed a tiny seed-sized robot that can navigate across soft and uneven surfaces to perform five surgical functions wirelessly, paving the way for developing robots to make surgeries and medical treatments more precise.

The miniature robot, measuring just 4.4 mm in length and controlled by weak magnetic fields, can move, cut biological tissues, release drugs, grip and store tissue samples, or generate heat remotely at any one time. It takes under a second to switch between these functions.

Led by Associate Professor Lum Guo Zhan from NTU’s School of Mechanical and Aerospace Engineering (MAE), the work was recently published in the academic journal Advanced Materials.

Using magnetic coils in the laboratory to remotely control the robot, the team was able to make the robot deploy different tools and perform different functions, such as activating a tiny blade to cut through tissue, or emitting heat to a targeted area, which could be relevant for approaches being studied that use heat for cancer treatment.

“Most magnetic robots like this can perform only one or two functions. Our latest invention can now do five, and our long-term goal is for doctors to use these mini robots in the body, navigate them to a targeted location, and use them to perform treatments,” said Assoc Prof Lum, who is a pioneer in miniature robots made from soft, flexible materials.

Mini robots are being studied worldwide as a possible way to make minimally invasive surgical and medical procedures safer, less painful and more precise.

Such devices could one day allow doctors to carry out targeted surgeries deep inside the body without large cuts or bulky surgical instruments.

Overcoming a key robotics challenge

To fit multiple functions into a robot only a few millimetres long, the NTU team developed a device for controlling movements that is activated by magnetic fields and which can be reprogrammed in under a second.

The robot is made from soft magnetic materials, including PDMS and Ecoflex, which are silicone-based materials commonly used in soft robotics as they are flexible and can be shaped into small structures.

These materials are embedded with magnetic microparticles measuring 5 micrometres each, allowing different parts of the robot to respond to magnetic fields.

At the centre of the device is a magnetic module that can be magnetised, demagnetised and remagnetised in different directions.

Each magnetic orientation activates a different function of the robot, allowing the same mobile robot to perform five different functions, including cutting and grasping tissues.

The researchers also engineered different regions of the robot to ensure that only one part, but not the rest, responds to the same magnetic field.

This means that only one part of the robot reacts to a magnetic field to change its shape to activate a tool or function, while other parts remain still and unchanged in their current forms, addressing a major limitation in miniature magnetic robots.

At small scales, magnetic fields often affect the entire device at once, causing it to behave like a single magnet, with all parts reacting to a magnetic field, thus limiting how precisely it can move or activate different tools.

Most miniature magnetic robots are also limited to five degrees of freedom. They can only move along three axes and rotate in two directions.

The NTU robot adds a sixth movement, rolling, which allows it to spin around its own long axis. This gives the robot finer control over how it can be positioned, which is important for navigating narrow, soft and irregular spaces, such as those inside the body.

Unlike slime-like mini robots, the NTU robot has a solid but flexible body, making it sturdier and easier to retrieve after use.

Tested on biological tissues

The NTU team tested the robot’s surgical functions using biological tissue models, including chicken liver, as well as gelatin-based materials that simulate soft tissue.

In laboratory tests, the robot cut through biological tissues, dispensing particles simulating drug particles, gripped and stored tissue samples, and generated localised heat after being induced by magnetic fields.

To produce heat, the researchers exposed the robot to a high-frequency alternating magnetic field. This caused magnetic materials inside the device to generate heat remotely, in an approach relevant to magnetic hyperthermia methods being explored in cancer treatment.

The team also evaluated the biocompatibility of the robot’s materials by exposing them to human skin cells under laboratory conditions.

More than 99 per cent of the cells remained viable after exposure to the robot’s materials, similar to the control group, suggesting that the materials were largely non-toxic under the experimental conditions.

The team – including NTU’s MAE alumnae Dr Chelsea Shan Xian Ng and Yu Xuan Yeoh, and current PhD student Nicholas Yong Wei Foo, who are co-authors of the research – is now exploring how future versions could be combined with imaging technologies, sensing systems and clinically realistic artificial organ models that better mimic the physical behaviour of human tissues.

Assoc Prof Lum is also working with surgeons to understand how mini robotic systems could eventually fit into real clinical workflows.

“For these robots to move closer to practical use, we need to understand not just how they work in the lab, but how they could be guided, monitored and controlled in realistic medical settings,” he added.

Giving independent comments, Dr Yeo Leong Litt, Leonard, Senior Consultant from the Division of Neurology at the National University Hospital, said: “These millimetre-scale magnetically guided robots are truly remarkable in their ability to traverse complicated environments and then perform a variety of tasks such as deliver medication to a location, perform biopsies and administer therapeutic heat remotely. I can envision that they have the potential to replace many aspects of interventional radiological surgery and become a new mode of therapy in medicine.”

Read the work in full

Miniature Soft Robot With Magnetically Reprogrammable Surgical Functions, Chelsea Shan Xian Ng, Yu Xuan Yeoh, Nicholas Yong Wei Foo, Keerthana Radhakrishnan, Guo Zhan Lum.
How Much Does It Cost to Develop a Chatbot Like ChatGPT?

How Much Does It Cost to Develop A Chatbot Like ChatGPT? 

What is ChatGPT and How It Is Useful?

ChatGPT (Chat Generative Pre-Trained Transformer) is a breakthrough in the field of Artificial Intelligence (AI) and Generative AI. Since its introduction into the tech world in 2022 by OpenAI, ChatGPT has been a buzz in the tech world and across social media. Leveraging Natural Language Processing (NLP) and Machine Learning like major subfields of AI technology, ChatGPT is well-trained to interpret user queries and generate accurate content that the users look for. Initially, OpenAI launched ChatGPT in Noven 2022 for the Android mobile app version in the USA and witnessed great attention soon.

Later, upgrading the version and adding the latest advanced tech features like GPT4 integration, OpenAI released the newest version of GPT on March 2023 and made it available for iOS users. Surprisingly, with its first month of launch, the app has generated approximately four million downloads in the USA in its first month itself. This newest language model-based AI Chatbot has its applications in many areas. From supporting students in preparing essays and other materials to assisting software developers in writing code, ChatGPT has its significance. 

Additionally, ChatGPT is also popularizing in the field of Marketing and sales, where it is supporting marketing people to create compelling digital campaign content and also giving suggestions to write SEO-friendly website content. Further, for sales teams, ChatGPT’s contributions are incredible. It is helping sales personnel to write crispy introductions and follow-up emails faster. Likewise, the ChatGPT use cases are enormous. On top of all top applications, AI-powered ChatGPT is a great assistant tool for graphic designers, where it accurately interprets user queries and recommends ideas for video or image designs. 

Since the hype of ChatGPT is incredible, why don’t come up with an app like GPT? USM Business Systems has best practices in designing and developing of ChatGPT-like similar AI chatbot. In this article, with our experts’ input, we have given the estimated cost to develop an app like ChatGPT. Our app development consultants have also given insights into cost optimization strategies and how to create an AI Chatbot within your budget.

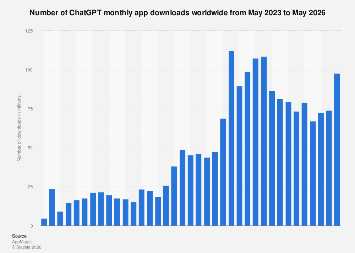
AI ChatGPT Chatbot Downloads Per Month from May 2023 to 2026

chatgpt downloads

Since the renowned ChatGPT mobile app launch into the U.S. iOS market on May 2023, the application generated approximately four million downloads within one month. When expanded to other global markets, the app reported total downloads of 12.5 million in July. Additionally, the Android version release propelled total downloads to almost 16 million in August. These numbers indicate the rapid growth and quick evolution of ChatGPT AI and GenAI’s implementation. This is the right time to invest and attract user attention towards ChatGPT-like AI innovations. Let’s look at how much it costs to create a ChatGPT clone app for Android and iOS.  

The Cost to Make an AI Chatbot Like ChatGPT App

The ChatGPT app development costs will depend on multiple technical factors, such as the language learning model it deploys (Either GPT 3 or GPT 4), the database which is used to train the algorithm, and agile methodology implementation will all take an essential part of the development cost of ChatGPT AI app. 

Further, the cost of developing a ChatGPT-like AI app will also be impacted by the complexity of the User interface and the other computational and analytical potentialities of this innovative software solution. Accordingly, the expertise, location, and team size of the AI development company will also be significant cost-impacting factors in ChatGPT clone mobile app development. The hourly rate of mobile app development agencies will vary based on their industry experience and team capabilities. 

For instance, a top AI app development company in the USA will cost much more than the cost of hiring AI developers from India. Considering all these factors, we estimate that the cost to build an app like ChatGPT will fall between $90,000 to $450,000. The cost might increase beyond the estimated range because ChatGPT is purely a novel and advanced revolution of AI.

Recommend To Read: The Best 13 AI App Development Companies List

Tips To Reduce the Cost Burden of ChatGPT App Development

By seeing the above-estimated cost figure, you might be concerned about the budget to kick start the development process of ChatGPT AI Chatbot. Being one of the biggest AI mobile app development companies in the USA, we would like to share a few tips to optimize the cost of ChatGPT clone app development.

  • Hire The Top AI App Developers 

This is one of the most significant cost-cutting strategies when stepping ahead of ChatGPT like AI app development. An expert AI app development company will deliver fully advanced software solutions like ChatGPT on-demand. Top mobile app development companies with their vast industry expertise and required skill sets in their development team, will ensure quick development without compromising on quality. A faster development process will consume less time for app developers and help you save costs.

  • Partnership With Cloud Service Providers

According to the research analysts, training a large language model such as GPT-3 and GPT-4 will cost millions of dollars. ChatGPT-like AI chatbot requires huge data to train the algorithm. Hence, to reduce the burden of ChatGPT-like chatbot mobile app development expenses, partnership with cloud companies is a good strategy to access the information legally and train GPT.

  • Go-To-Market with MVP Approach

Here is another best strategy to lower mobile app development costs. Minimum Viable Product (MVP) development with primary features and user-friendly UI design will help you reduce the development costs. The release of MVP will also help you get the user feedback about the application performance and how your app is fulfilling their desired requirements. Hence, eliminating the development of advanced features does not add any value to the application, organizations can reduce AI-based app development costs. Top mobile app development companies perform extensive research to match your application requirements with the ChatGPT trends, release MVP faster, make the application qualitative, and test GPT modules multiple times to ensure efficiency.

Recommend To Read: How Can Startups Reduce the Mobile App Development Costs?


Conclusion

Technology developments continue to emerge with the innovations in AI, such as the evolution of GenAI. Hence, GPT-like applications will need to be customized according to the business objectives. Currently, the ChatGPT Enterprise version using advanced GPT4 and GenAI capabilities is a hot topic now. Businesses across the industries are in plans of integrating GPT 4 like complex LLM and GenAI to create accurate images, videos, and content in response to user prompts. Such advanced Enterprise ChatGPT development cost might go beyond $500,000 as it needs more development time, a huge database, and fully generative capabilities. Hire the best AI developers and get expert guidance to Introduce your new version of an AI Chatbot app like ChatGPT.


Let’s discuss your AI app idea and get a free quote!

[contact-form-7]
Page 76 of 718
1 … 74 75 76 77 78 … 718